# AnotherAI CLI Tool (Not released)
URL: /cli.private
undefined
***
## title: AnotherAI CLI Tool (Not released)
## AnotherAI CLI Tool
For testing high-token content that exceeds the Read tool limit, use the `cli.py` script with input variables:
### Setup
```bash
# Create virtual environment (one-time setup)
python3 -m venv anotherai_env
source anotherai_env/bin/activate
pip install openai requests
```
### Input Variables Workflow
For high-token content with multiple variables, use input IDs:
**Step 1: Create input with variables**
```bash
source anotherai_env/bin/activate
# Create input with structured variables and metadata (no file size limits)
python cli.py add_input \
--content '{"email_content": "Large email content here...", "user_name": "Alice", "department": "Sales", "priority": "urgent"}' \s
--metadata '{"title": "Sales Analysis Data", "category": "quarterly-review", "source": "sales-team", "experiment": "v1"}'
# Returns: Input ID: input_20250707_143337
# Minimal example without metadata
python cli.py add_input \
--content '{"email_content": "Large email content here...", "user_name": "Alice"}'
```
**Step 2: Use input IDs in testing**
```bash
# Test with input variables using input IDs
python cli.py playground \
--agent-id "your-agent-name" \
--models "gpt-4o-mini,claude-3-5-sonnet-20241022" \
--messages '[{"role": "system", "content": "You are a helpful assistant"}, {"role": "user", "content": "Analyze {{email_content}} from {{user_name}} in {{department}} with {{priority}} priority"}]' \
--input-ids "input_20250707_143337" \
--api-key "aai-your-api-key" \
--output "results.json"
```
### Key Benefits
* **No token limits**: Handle any size content via IDs instead of embedding
* **Structured data**: Input variables support complex multi-field templates
* **Flexible metadata**: Add custom metadata fields for categorization, tracking, and organization
* **Reusable**: Same input IDs work across multiple experiments
* **Multiple models**: Test same input across different models
* **Performance metrics**: Cost and duration tracking for each test
* **Clean output**: Optimized JSON structure for input variables
### Metadata Examples
```bash
# Simple metadata
--metadata '{"title": "Customer Support", "description": "Email analysis"}'
# Rich metadata with multiple fields
--metadata '{
"title": "Customer Support Analysis",
"category": "support",
"source": "zendesk",
"experiment_id": "exp_001",
"user_id": "analyst_123",
"tags": "urgent,billing,complaint",
"priority": "high",
"version": "v2.1"
}'
# No metadata (optional)
# Just use --content without --metadata
```
### Example Results Format
```json
[
{
"model": "gpt-4o-mini",
"input_id": "input_20250707_143337",
"response": "Analysis of sales email...",
"cost": 0.000064,
"duration": 2.47
}
]
```
Use this CLI for high-token testing, then create experiments with the best performing prompts/models.
# Observability FAQ
URL: /faq
undefined
***
title: Observability FAQ
summary: Frequently asked questions about observability features
----------------------------------------------------------------
## Frequently Asked Questions
### Why can't I select a completion from a dashboard view?
If you're unable to select a completion from a view in your dashboard, it's likely because the `SELECT` statement in your query is missing the `id` field.
The `id` field is required for the UI to create clickable links to individual completions. Make sure your query includes the completion ID:
```sql
-- ❌ Bad: Missing id field
SELECT agent_id, cost_usd, duration_seconds
FROM completions
WHERE created_at >= now() - INTERVAL 30 DAY
-- � Good: Includes id field
SELECT id, agent_id, cost_usd, duration_seconds
FROM completions
WHERE created_at >= now() - INTERVAL 30 DAY
```
When the `id` field is included, each row in your view will be clickable, allowing you to navigate to the detailed completion view.
# Foundations
URL: /foundations
undefined
***
title: Foundations
summary: Essential concepts and architecture of AnotherAI to get you started with agents, models, deployments, and core features.
---------------------------------------------------------------------------------------------------------------------------------
## What is AnotherAI?
Think of AnotherAI as a drop-in replacement for OpenAI API, with primitives added to make it easier to build AI agents.
AnotherAI works with all programming languages, we provide specific examples for Python, Javascript, Typescript, Go, Ruby, Rust, Java, C#.
### Cost
By using AnotherAI, you won't pay more than your current inference costs. We price match the providers and make our margin through volume discounts. [Learn more about our pricing](/pricing).
## Primitives
### Inference
AnotherAI exposes a compatible OpenAI API endpoint to `/v1/chat/completions`, which means that all SDKs that support OpenAI API will work with AnotherAI by simply changing the base URL and the API key.
> The API Key is usually stored in an environment variable (e-g `ANOTHERAI_API_KEY`). AnotherAI API keys start with `aai-...`. API Keys can be created in the UI or using the `create_api_key` MCP tool.
```python
import openai
client = openai.OpenAI(
base_url="{{API_URL}}/v1",
api_key="aai-***",
)
```
```typescript
import OpenAI from 'openai';
const client = new OpenAI({
baseURL: '{{API_URL}}/v1',
apiKey: 'aai-***',
})
```
```go
import (
"github.com/openai/openai-go/v2"
"github.com/openai/openai-go/v2/option"
)
var client = openai.NewClient(
option.WithBaseURL("{{API_URL}}/v1"),
option.WithAPIKey("aai-***"),
)
```
The primary benefit of using AnotherAI's API is gaining access to a unified interface for all AI models across the market. The list of models supported can be listed by calling the `list_models` MCP tool, or `curl {{API_URL}}/v1/models`. This eliminates the complexity of managing multiple API keys and switching between different provider SDKs - you can seamlessly use any model through a single, consistent API.
Technical details:
* all requests are proxied by AnotherAI, then sent to an AI provider.
### API
You can interact with the API directly, read the [OpenAPI spec](\{\{API_URL}}/openapi.json)
### Observability
By default, AnotherAI saves all LLM completions. Observability is critical for building reliable AI agents. LLM observability helps teams improve reliability, reduce costs, debug failures faster, ensure safety, and optimize prompts and models by providing end-to-end visibility into how queries are processed and where issues arise.
#### Viewing Completions in the Web App
To view your completions in the AnotherAI web app, use the `query_completions` MCP tool. This tool validates your SQL query and returns a URL to view the results in the web interface.
Learn more about by reading the [Observability](/observability) section.
### Experiments
Experiments are containers for testing and comparing different model configurations, prompts, and parameters. They enable systematic evaluation and iteration of AI agents.
> **Important:** The experiment tools (`create_experiment`, `add_inputs_to_experiment`, `add_versions_to_experiment`, etc.) work independently of the AnotherAI inference endpoint. You can use these tools to create and manage experiments without changing your existing code or base\_url.
**Key concepts:**
* Experiments group related completions for analysis
* Each experiment has a unique ID and can be annotated with feedback
* Results are documented for future reference and learning
**Creating experiments:**
AnotherAI provides a collection of tools (`create_experiment`, `add_inputs_to_experiment`, `add_versions_to_experiment`, get\_experiment) that allowing experimenting with different parameters and inputs for a given agent:
* Test multiple models in parallel (e.g., "gpt-4o-mini,claude-3-5-sonnet-20241022")
* Compare different prompt variations and temperatures
* Test with structured inputs using template variables
* Automatically track cost and performance metrics
* Allows retrying existing inputs through SQL queries
The tool creates a matrix of completions testing all combinations of models, prompts, inputs, and temperatures.
**Agent workflow:**
1. **Create experiments** with `create_experiment`.
2. **Add inputs** with `add_inputs_to_experiment`. Here you can create new inputs if needed using the `inputs` parameter, or re-use existing inputs if needed using the `query` parameter. Always use the `query` parameter when re-using existing inputs, this will ensure that the inputs are identical.
3. **Add versions** with `add_versions_to_experiment`. If versions already exist, in most cases you should start with an existing version as a baseline (`version` parameter). Sometimes, like when the input variables are different, it can be good to start with a completely new version.
4. **Wait for the results** with `get_experiment`. You can ask the tool to include the full version and inputs if needed, and filter via version or input ids. The `get_experiment` tool will return a query that you can use to fetch the results.
5. **Get the results** via the `query_completions` tool. Remember that you can paginate the results to avoid context overflows.
6. **Add results/conclusions** using `add_experiment_result` with:
* Performance metrics (speed, cost, accuracy)
* Key findings and insights
* Recommendations for next steps
* Model comparisons and winners
7. **Provide experiment URL** immediately for user review: `{{WEB_APP_URL}}/experiments/{experiment_id}`
8. **Check for user feedback** using `get_annotations`
9. **Iterate** based on feedback. You can use `add_versions_to_experiment` to add new versions or the `add_inputs_to_experiment` to add new inputs to the same experiment.
Always add experiment results using `add_experiment_result` after completing any testing or analysis. This tool documents findings, performance metrics, and recommendations for future reference.
**Model selection for experiment creation:**
When creating experiments for agents with complex structured output schemas, asking **Claude Opus** to create the experiment is recommended. Less intelligent models have been known to modify or simplify schemas despite explicit instructions not to. Claude Opus consistently preserves the exact schema specifications as intended.
### Deployments
Deployments allow you to update an agent's prompt or model without changing the code. Learn more about deployments by reading the [Deployments](/deployments) page.
## `/v1/chat/completions`
### Parameters
Building an AI agent is the process of picking the right value for each parameter of the `/v1/chat/completions` API. Let's go through each parameter one by one.
```python
completion = client.chat.completions.create( # or client.chat.completions.parse for structured outputs
model="..",
messages=[...],
metadata={
"agent_id": "...",
"key": "value", # user provided metadata
},
extra_body={
# AnotherAI specific parameters
"input": {
"variable_name": "variable_value"
},
},
max_tokens=1000,
)
print(completion.choices[0].message.content)
print(completion.choices[0].cost_usd)
print(completion.choices[0].duration_seconds)
```
```typescript
const completion = await openai.chat.completions.create({
model="..",
messages=[...],
metadata={
"agent_id": "...",
"key": "value", // user provided metadata
},
input: { // AnotherAI specific parameter. Might need to silence a TS error
"variable_name": "variable_value"
},
})
console.log(completion.choices[0].message.content)
console.log(completion.choices[0].cost_usd)
console.log(completion.choices[0].duration_seconds)
```
```go
params := openai.ChatCompletionNewParams{
model: "..",
metadata: map[string]string{
"agent_id": "...",
"key": "value", // user provided metadata
},
}
params.SetExtraFields(map[string]any{
"input": map[string]any{
...
},
})
completion, err := client.Chat.Completions.New(context.TODO(), params)
fmt.Printf("Cost USD: %s", completion.choices[0].JSON.ExtraFields["cost_usd"].Raw())
fmt.Printf("Duration Seconds: %s", completion.choices[0].JSON.ExtraFields["duration_seconds"].Raw())
```
#### model
One of the model.id from the `list_models` MCP tool, or `curl {{API_URL}}/v1/models`
AnotherAI allows non-OpenAI models to be used via a OpenAI SDK.
each model listed by AnotherAI includes information about its price, its intelligence (quality\_index), its capabilities, its context window.
#### messages
`messages`: The messages to send to the model. The messages are a list of dictionaries, each dictionary containing a role and content. The role can be "user", "assistant", or "system". The content can be a string, or a list of strings.
```json
messages = [
{"role": "user", "content": "Hello, how are you?"}
]
```
There are a few differences between the OpenAI API and AnotherAI API:
* **[Input variables](/observability/input-variables) (strongly recommended)**: Use Jinja2 template syntax to separate static instructions from dynamic data. This is a best practice that significantly improves observability, debugging, and prompt management.
```
messages=[{
"role": "user",
"content": "Analyze this email: {{email_content}}"
}]
```
See the `input` parameter below on how to pass variables to the LLM. Note that the template rendering is done server-side by AnotherAI, so the client does not need to render the template.
Learn more about input variables by reading the [Input Variables](/observability/input-variables) section.
* [Deployments](/deployments): When using deployments, the `messages` parameter can be empty because the messages are stored on AnotherAI directly, and added automatically to the request. `messages = []` is valid. Note that the `messages` parameter is required by OpenAI SDKs, so `messages = None` is not valid.
Learn more about deployments by reading the [Deployments](/deployments) section.
#### metadata
Any key-value pair can be passed to the `metadata` parameter. Runs are searchable by metadata keys (list all the metadata keys for a given agent using the `query_completions` MCP tool). For example, "customer\_id": "1234567890", "user\_email": "[john.doe@example.com](mailto:john.doe@example.com)".
> **Recommended**: Include `agent_id` in the `metadata` parameter to identify your agent and organize observability data. This is the preferred method for agent identification.
#### max\_tokens
`max_tokens`: (optional) The maximum number of tokens to generate. If not provided, the model will generate as many tokens as needed. Make sure that `max_tokens` is high enough to generate a complete response.
#### input
`input`: (strongly recommended for most use cases) provides variables to the LLM when using [input variables](/observability/input-variables). **Always use input variables instead of string concatenation** when you have dynamic content - it dramatically improves debugging, observability, and prompt management.
```python
completion = client.chat.completions.create(
messages=[{"role": "user", "content": "Analyze this email: {{email_content}}"}],
extra_body={ # input must be wrapped in extra_body because the OpenAI SDK doesn't recognize 'input' as a valid parameter. extra_body passes custom fields directly to the request body.
"input": {
"email_content": "Dear team, please review the quarterly report..."
}
}
)
```
```typescript
const completion = await openai.chat.completions.create({
messages=[{"role": "user", "content": "Analyze this email: {{email_content}}"}],
input: { // AnotherAI specific parameter. Might need to silence a TS error
email_content: "Dear team, please review the quarterly report...",
},
})
```
```go
params := openai.ChatCompletionNewParams{
// OpenAI supported fields
}
// AnotherAI specific fields
params.SetExtraFields(map[string]any{
"input": map[string]any{
"email_content": "Dear team, please review the quarterly report...",
},
})
```
**Best practice:** Use input variables for any dynamic content rather than concatenating strings in your code. This separates your prompt logic from your application logic and makes debugging much easier.
#### response\_format
`response_format`: (optional) ensures AI models generate responses that perfectly match your defined JSON Schema. Instead of hoping the model follows formatting instructions, you get guaranteed compliance with your data structure. Use structured outputs when you need reliable data extraction, classification, or any scenario requiring consistent JSON format.
```python
from pydantic import BaseModel
class UserInfo(BaseModel):
name: str
age: int
email: str
# `client.beta.chat` before OpenAI v2
completion = client.chat.completions.parse(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Extract user info: John Doe, 30, john@example.com"}],
response_format=UserInfo # Guarantees valid UserInfo object
)
user = completion.choices[0].message.parsed # Direct access to typed object
```
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const UserInfo = z.object({
name: z.string(),
age: z.number(),
email: z.string()
})
const completion = await openai.beta.chat.completions.parse({
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Extract user info: John Doe, 30, john@example.com"}],
response_format: zodResponseFormat(UserInfo, "UserInfo"),
})
user = completion.output_parsed
```
```go
import "github.com/invopop/jsonschema"
type UserInfo struct {
Name string `json:"name"`
Age int `json:"age"`
Email string `json:"email"`
}
UserInfoSchema := jsonschema.Reflect(&UserInfo{})
chatCompletion, err := client.Chat.Completions.New(context.TODO(), openai.ChatCompletionNewParams{
Model: "autopilot-openai-beta-parse/" + model,
Messages: ...,
ResponseFormat: openai.ChatCompletionNewParamsResponseFormatUnion{
OfJSONSchema: &openai.ResponseFormatJSONSchemaParam{
JSONSchema: openai.ResponseFormatJSONSchemaJSONSchemaParam{
Name: "user_info",
Schema: UserInfo,
},
},
},
})
```
Learn more about structured outputs in the [Structured Outputs](/inference/structured-outputs) section.
### Response
AnotherAI returns the same response format as the OpenAI API, ensuring full compatibility with existing code while adding additional fields for enhanced functionality.
```python
completion = client.chat.completions.create(...)
content = completion.choices[0].message.content
# for structured outputs
# `client.beta.chat` in older versions of the SDK
completion = client.chat.completions.parse(..., response_format=...)
parsed_output = completion.choices[0].message.parsed
```
```typescript
const completion = await openai.chat.completions.create(...)
const content = completion.choices[0].message.content
```
```go
completion, err := client.Chat.Completions.New(context.TODO(), openai.ChatCompletionNewParams{...})
if err != nil {
...
}
content := completion.Choices[0].Message.Content
```
#### cost and latency
AnotherAI adds cost and latency to the response. Learn more about cost and latency in the [Cost Metadata](/inference/cost) section.
```python
cost = getattr(completion.choices[0], 'cost_usd', None)
latency = getattr(completion.choices[0], 'duration_seconds', None)
print(f"Latency (s): {latency:.2f}")
print(f"Cost ($): ${cost:.6f}")
```
```typescript
const cost = completion.choices[0].cost_usd
const latency = completion.choices[0].duration_seconds
console.log(`Cost: $${cost.toFixed(6)}`)
console.log(`Latency: ${latency.toFixed(2)}s`)
```
```go
completion, _ := client.Chat.Completions.New(context.TODO(), openai.ChatCompletionNewParams{...})
cost := strconv.ParseFloat(completion.Choices[0].JSON.ExtraFields["cost_usd"].Raw(), 32)
latency := strconv.ParseFloat(completion.Choices[0].JSON.ExtraFields["duration_seconds"].Raw(), 32)
fmt.Printf("Cost: $%f", cost)
fmt.Printf("Latency: %fs", latency)
```
## Contact Us
Need help or have questions about AnotherAI? We're here to support you through multiple channels:
* **Email**: [team@workflowai.support](mailto:team@workflowai.support)
* **Slack Community**: [Join our Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA)
* **GitHub**: [github.com/anotherai-dev/anotherai](https://github.com/anotherai-dev/anotherai) - Feel free to create issues for bug reports, feature requests, or questions
Whether you're getting started, troubleshooting an issue, or looking to discuss advanced use cases, our team and community are ready to help.
## URLs
AnotherAI provides direct URLs to view completions and experiments in the web app:
### Completion URL
To view a specific completion in the web app:
```
{{WEB_APP_URL}}/completions/{completion_id}
```
### Experiment URL
To view a specific experiment and its results:
```
{{WEB_APP_URL}}/experiments/{experiment_id}
```
### View URL
To view a specific saved view in the web app:
```
{{WEB_APP_URL}}/views/{view_id}
```
### Query Results URL
When using the `query_completions` MCP tool, it returns a URL in this format:
```
{{WEB_APP_URL}}/completions?query={encoded_query}
```
This URL displays filtered completion results based on your SQL query.
# Getting Started
URL: /getting-started
undefined
***
title: Getting Started
summary: How to get set up to use AnotherAI.
--------------------------------------------
## Set Up
To use AnotherAI's hosted service: go to [https://anotherai.dev/](https://anotherai.dev/) and sign up to create a free account.
Are you interested in a self-hosted, [open-source](https://github.com/anotherai-dev/anotherai) set up? We have that too! You can learn how to get set up [here](/self-hosted).
Need an extra hand with the setup? We're happy to help. Reach us at [team@workflowai.support](mailto:team@workflowai.support) or on [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
### MCP
AnotherAI is available as an MCP server in the IDEs below.
Quick setup (recommended):
1. Complete the [set up](#set-up) steps above
2. Tap on the button below
 Manual installation:
1. Open Cursor
2. Go to `Settings...`
3. Navigate to `Cursor Settings`
4. Select `Tools and Integrations`
5. Select `+ New MCP Server`
6. Choose your authentication method:
**OAuth Authentication (Recommended)**
Add the following configuration to your MCP servers config:
```json
{
"mcpServers": {
"AnotherAI": {
"url": "{{API_URL}}/mcp"
}
}
}
```
7. Return to the MCP Tools settings screen and enable the MCP, the indicator should be yellow with the message "Needs login".
8. Tap "Need login", open the link and select "Allow" in your browser when prompted.
9. Return to Cursor and the MCP should show as Connected (see screenshot below)
**API Key Authentication**
7. Get your API key on [anotherai.dev/](https://anotherai.dev/completions?showManageKeysModal=true) and add the following configuration:
```json
{
"mcpServers": {
"anotherai": {
"url": "{{API_URL}}/mcp",
"headers": {
"Authorization": "Bearer "
}
}
}
}
```
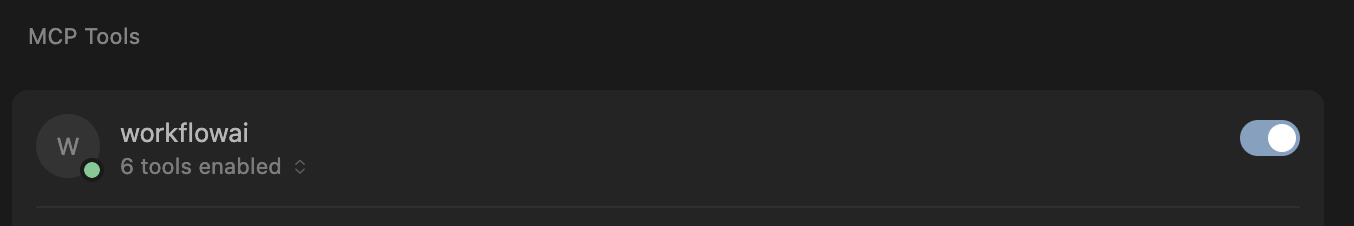
8. Return to the MCP Tools settings screen. The Cursor UI should now look like this (note the green indicator and the number of tools enabled displayed):
1. Complete the set up above
2. Choose your authentication method:
**OAuth Authentication (Recommended)**
3. Open Claude Code in your preferred terminal (standalone or within your IDE)
4. Type the following to install:
```bash
claude mcp add --scope user --transport http anotherai {{API_URL}}/mcp
```
5. Check that the server was added:
```bash
claude mcp list
```
6. Start Claude and authenticate:
```bash
claude
```
Then type:
```bash
/mcp
```
Navigate to `anotherai` and press Enter. You should automatically be redirected to a browser to authenticate.
**API Key Authentication**
3. Get your API key on [anotherai.dev/](https://anotherai.dev/completions?showManageKeysModal=true)
4. Open Claude Code in your preferred terminal (standalone or within your IDE)
5. Type the following to install:
```bash
claude mcp add --scope user anotherai {{API_URL}}/mcp --transport http --header "Authorization: Bearer YOUR_API_KEY_HERE"
```
**Installation Scopes**: The `--scope user` flag installs AnotherAI for your personal use across all projects. For team projects, you can use `--scope project` instead to create a shared `.mcp.json` file that can be committed to version control and shared with your team members. Learn more about MCP scopes in the [Anthropic documentation](https://docs.anthropic.com/en/docs/claude-code/mcp#user-scope).
6. Type the following to verify the server is properly connected:
```bash
claude
```
Then type:
```bash
/mcp
```
You should see the AnotherAI server listed as "connected".
If you're testing an agent that has a large system prompt and/or very long inputs, you may encounter token limit issues with the `get_experiment` MCP tool that impacts Claude Code's ability to provide accurate insights on your agent.

In this case, you can manually increase Claude Code's output token limit.
**To set up permanently for all terminal sessions:**
For zsh (default on macOS):
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.zshrc && source ~/.zshrc
```
For bash:
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.bashrc && source ~/.bashrc
```
**For temporary use in current session only:**
```bash
export MAX_MCP_OUTPUT_TOKENS=150000
```
Notes:
* If you forget or don't realize you need to set a higher limit, you can quit your existing session, run the command to increase the limit, and then use `claude --resume` to continue your previous session with the increased limit applied.
You can learn more about tool output limits for Claude Code in their [documentation](https://docs.claude.com/en/docs/claude-code/mcp#mcp-output-limits-and-warnings).
**Currently only available in beta to Pro and Plus accounts on the web. Refer to [ChatGPT's documentation](https://platform.openai.com/docs/guides/developer-mode) for more information.**
1. Enable Developer Mode in ChatGPT:
* Go to [ChatGPT](https://chatgpt.com/)
* Click on the user icon in the bottom left corner
* Select `Settings` -> `Connectors` -> `Advanced Settings`
* Toggle the `Developer Mode` switch ON
2. Add the AnotherAI MCP server:
* Go back to the main Connectors page
* Select `Create`
* Name the connector `AnotherAI`
* In `MCP Server URL`, enter `{{API_URL}}/mcp`
* In `Authentication`, make sure OAuth is selected
* Select `Create` to save the configuration
3. Using the AnotherAI MCP: you will need to manually enable the MCP server in a new chat to use it
* In the chat text box, select the `+` -> `More` -> `Developer Mode`
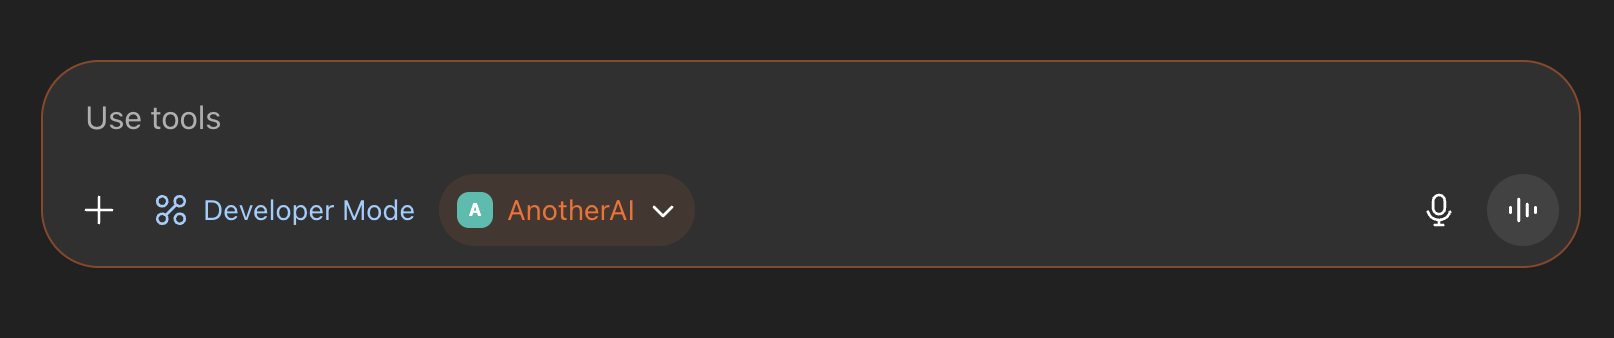
* You should see `Developer Mode` and `Add sources` appear at the bottom of the text box
* Select `Add sources` and toggle on AnotherAI
Once you've added the MCP server, it should look like this:
1. Open Windsurf
2. Go to `Settings...`
3. Select `Windsurf Settings`
4. Navigate to `Cascade`
5. Select `Manage MCPs`
6. Select `View Raw Config`
Add the following configuration to your MCP servers config:
```json
{
"mcpServers": {
"anotherai": {
"url": "{{API_URL}}/mcp",
"headers": {
"Authorization": "Bearer "
}
}
}
}
```
Navigate back to Manage MCPs and refresh the page. The AnotherAI MCP should appear and show as enabled.
Cursor CLI can access MCPs configured in your IDE's `mcp.json` configuration file, enabling the same MCP servers and tools that you've configured for the IDE.
Setup steps:
1. Complete the [set up](#set-up) steps described above and ensure the AnotherAI MCP server is running
2. Configure the AnotherAI MCP in your IDE's `mcp.json` file, as described in the `Cursor` tab.
3. Once the MCP is enabled and active, you can ask the Cursor CLI to interact with it
**Additional Configuration**: If you find that the CLI claims it can't find or use the AnotherAI MCP, you may need to give it the specific file path to use to look for the mcp.json file.
Codex stores the MCP configuration in a user scoped file located at \~/.codex/config.toml.
> Remote MCP support is currently experimental so `experimental_use_rmcp_client` must be set to `true` in the config.toml file. For now, the config file must be edited manually.
Then to add the MCP:
```sh
# Add the MCP to the config file
codex mcp add anotherai --url https://api.anotherai.dev/mcp
# Authenticate the MCP using OAuth
codex mcp login anotherai
```
The config file should look like:
```toml
experimental_use_rmcp_client = true
[mcp_servers.anotherai]
url = "https://api.anotherai.dev/mcp"
```
## Try it out
After you have the above set up completed, AnotherAI is ready to use!
* If you have agents already created, check out how to [migrate them to AnotherAI](/agents/migrating).
* If you don't have any agents built yet, check out [building a new agent](/agents/building) to learn about building a new AnotherAI-compatible agent.
# Overview
URL: /
undefined
***
title: Overview
summary: Introduction to the AnotherAI documentation. Provides information on what AnotherAI is and how to get started with building, deploying, and improving AI agents.
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Code2, BookOpen, Wand2, Eye, Network, FileCode, Shield } from 'lucide-react';
## What is AnotherAI?
**AnotherAI turns your AI assistant into your AI engineer.**
Let Claude Code, Cursor, ChatGPT, Windsurf, etc... operate your AI agents through MCP. Compatible with any programming language and OpenAI's SDK, access every LLM model from: OpenAI, Anthropic, Google, Meta, DeepSeek, Mistral, and more. Fully [open-source](https://github.com/anotherai-dev/anotherai).
**With AnotherAI, your AI assistant becomes an AI engineer that can:**
* **[Build new agents](/use-cases/fundamentals/building):** Tests [100+ models](/features/models) from OpenAI, Anthropic, Google & more, optimizes prompts, compares quality vs. cost vs. speed
* **[Debug production issues](/use-cases/fundamentals/debugging):** `Why is the email parser failing?` → Queries logs, identifies patterns, deploys fix
* **[Run experiments](/use-cases/checking-new-models):** `Compare GPT-4o vs Claude vs Gemini on quality, cost and latency` → Compare models and prompts with synthetic or production data
* **[Deploy without code changes](/use-cases/fundamentals/deployments):** Updates prompts and models instantly, without a deployment.
* **[Optimize costs](/use-cases/lowering-costs):** "Reduce AI spend by 30%" → Analyzes usage, switches to cheaper models where quality permits
* **[Improve from feedback](/use-cases/user-feedback):** Collect users's feedback, automated AI review of feedbacks, identifies issues, suggests improvements
* **[Analyze performance](/use-cases/fundamentals/metrics):** `Show response times by model this week` → Generates custom metrics and visualizations
* **[Evaluate quality](/use-cases/fundamentals/evaluating):** `Test if the new prompt maintains accuracy` → Runs evaluation suites, compares against baselines
{/* Watch Claude Code debug an issue with an agent and deploy a fix without changing the codebase:
[video] */}
By using AnotherAI, you won't pay more than your current inference costs. We price match the providers and make our margin through volume discounts. [Learn more about our pricing](/pricing).
## Join the community
If you have questions about AnotherAI, reach out to our team and community on our community [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
# Pricing
URL: /pricing
undefined
***
title: Pricing
summary: Documentation on the pay-as-you-go pricing model. Explains the price-match guarantee, what you pay for, and answers common questions about billing and costs.
----------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
AnotherAI offers a pay-as-you-go model, like AWS. There are no fixed costs, minimum spends, or annual commitments. You can start without talking to sales.
## Simple pricing promise
AnotherAI matches the per-token price of all LLM providers, so AnotherAI **costs the same as using providers directly**.
{/* ### Price per model
[TODO: component with @guillaume]
model | price per 1M input | price per 1M output
--- | --- | ---
gpt-4o | $75 | $75
claude-3-5-sonnet | $75 | $75
gemini-2.0-flash-exp | $75 | $75
llama-3.1-8b-instruct | $75 | $75
mistral-7b-instruct | $75 | $75 */}
| **What we charge for** | **What's included for free** |
| -------------------------- | ---------------------------- |
| Tokens used by your agents | Data storage |
| | Number of agents |
| | Users in your organization |
| | Bandwidth or CPU usage |
## How we make money
Behind every AI model, there are two ways to pay for inference: buy tokens from providers, or rent GPU capacity directly to run models yourself.
Individual customers typically buy tokens because their usage is sporadic: they can't justify renting GPUs that sit idle most of the time. Even when GPUs aren't processing requests, you're still paying for them.
AnotherAI pools demand from many customers, creating consistent 24/7 throughput that maximizes GPU utilization. This allows us to rent GPU capacity directly instead of buying tokens, securing much better rates.
We pass the standard token pricing to you while capturing the cost savings from efficient GPU utilization. That's how we match provider prices while staying profitable.
## FAQ
We monitor provider pricing in real-time and automatically match their per-token rates. If you ever find a discrepancy, we'll refund the difference and update our pricing immediately.
Yes, you can connect your own API keys from OpenAI, Anthropic, Google, and other providers to use your existing credits while still benefiting from AnotherAI's tools and infrastructure.
When using your own API keys, AnotherAI doesn't charge for inference tokens - you pay your provider directly. We only charge for [built-in tools](/agents/tools) that your agents use (like web search, browser, etc.).
You're only charged for tokens actually consumed by your agents and any tools they use. We provide detailed [usage analytics](/observability/costs) so you can see exactly what you're paying for. Billing is monthly with no minimums.
Our pricing scales linearly with no minimums or commitments. For most customers, our pooled model provides better economics than going direct.
If you're spending over $25,000/month on LLM usage, you have two options: use your own API keys with AnotherAI to get your negotiated rates, or contact us to apply volume discounts to your account.
Unless you can maintain 24/7 GPU utilization (which requires significant scale), our pooled model will be more cost-effective than renting your own GPUs while providing better reliability and no infrastructure management overhead.
Data storage, unlimited agents, team collaboration, and bandwidth are completely free. You only pay for the AI inference tokens your agents actually use.
# Security
URL: /security
Learn about the security measures implemented in AnotherAI's SQL query tool
***
title: Security
summary: Security measures for the SQL query tool
description: Learn about the security measures implemented in AnotherAI's SQL query tool
----------------------------------------------------------------------------------------
## SQL Query Tool Security
The SQL query tool in AnotherAI provides powerful observability capabilities while maintaining strict security boundaries to protect your data.
### Technical Implementation
Our SQL query security is built on [ClickHouse's robust access control system](https://clickhouse.com/docs/operations/access-rights):
* **Read-only access**: All SQL queries are executed with [read-only permissions](https://clickhouse.com/docs/operations/settings/permissions-for-queries), preventing any data modification, deletion, or schema changes
* **Tenant Isolation**: Each customer operates within isolated security contexts using a dedicated ClickHouse's user with strict role-based permissions
* **Resource limitations**: Each query is limited in CPU and memory usage to prevent starvation of resources
* **Query validation**: All queries are validated before execution to ensure they comply with security policies
### Security Guarantees
**What you CAN do:**
* Execute SELECT queries to analyze your completions data
* Use aggregations, filters, and joins within your data scope
* Export query results for further analysis
* Create complex analytical queries for insights
**What you CANNOT do:**
* Modify, delete, or insert data
* Access other customers' data
* Alter database schemas or tables
* Execute system-level commands
* Bypass row-level security policies
* Execute queries that would require too much resources
### Data Isolation
* **Customer segregation**: Each customer's data is logically isolated using row-level security
* **Query scope**: Queries are automatically scoped to your organization's data only
For security concerns or questions, contact [team@workflowai.support](mailto:team@workflowai.support)
# Self-Hosted Setup Guide
URL: /self-hosted
undefined
***
title: Self-Hosted Setup Guide
summary: Guide for setting up and using AnotherAI on your own infrastructure
----------------------------------------------------------------------------
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Code2, BookOpen, Wand2, Eye, Network, FileCode, Shield } from 'lucide-react';
### Self Host Set Up
To self-host your own instance of AnotherAI, ask Claude Code to do the setup for you by sending the following prompt:
```
claude "Please follow instructions in https://raw.githubusercontent.com/anotherai-dev/anotherai/refs/heads/main/examples/quickstart/INSTRUCTIONS.md"
```
### MCP Configuration
AnotherAI is available as an MCP server in the IDEs below.
Quick setup (recommended):
1. Complete the [Self Host Set Up](#self-host-set-up) steps above.
2. Tap on this button below
Manual installation:
1. Open Cursor
2. Go to `Settings...`
3. Navigate to `Cursor Settings`
4. Select `Tools and Integrations`
5. Select `+ New MCP Server`
Add the following configuration to your MCP servers config:
```json
{
"mcpServers": {
"anotherai": {
"url": "http://127.0.0.1:8000/mcp/"
}
}
}
```
Cursor UI should now look like this (note the green indicator and the number of tools enabled displayed):

1. Open Claude Code in your preferred terminal (standalone or within your IDE).
2. Type the following to install:
```bash
claude mcp add --scope user --transport http anotherai http://127.0.0.1:8000/mcp/
```
**Installation Scopes**: The `--scope user` flag installs AnotherAI for your personal use across all projects. For team projects, you can use `--scope project` instead to create a shared `.mcp.json` file that can be committed to version control and shared with your team members. Learn more about MCP scopes in the [Anthropic documentation](https://docs.anthropic.com/en/docs/claude-code/mcp#user-scope).
3. Type the following to verify the server is properly connected:
```bash
claude
```
Then type:
```bash
/mcp
```
You should see the AnotherAI server listed as "connected".
1. Open Windsurf
2. Go to `Settings...`
3. Select `Windsurf Settings`
4. Navigate to `Cascade`
5. Select `Manage MCPs`
6. Select `View Raw Config`
Add the following configuration to your MCP servers config:
```json
{
"mcpServers": {
"anotherai": {
"url": "http://127.0.0.1:8000/mcp/"
}
}
}
```
Navigate back to Manage MCPs and refresh the page. The AnotherAI MCP should appear and show as enabled.
Cursor CLI can access MCPs configured in your IDE's `mcp.json` configuration file, enabling the same MCP servers and tools that you've configured for the IDE.
Setup steps:
1. Complete the [Self Host Set Up](#self-host-set-up) steps above and ensure the AnotherAI MCP server is running
2. Configure the AnotherAI MCP in your IDE's `mcp.json` file, as described in the `Cursor` tab
3. Once the MCP is enabled and active, you can ask the Cursor CLI to interact with it
**Additional Configuration**: If you find that the CLI claims it can't find or use the AnotherAI MCP, you may need to give it the specific file path to use to look for the mcp.json file.
### Configuring Authentication
The default configuration disables authentication all together using `NO_AUTHORIZATION_ALLOWED=true` in the `.env` file.
If that variable is not present, the backend expects means to validate a JWT token in environment variables, either:
* `JWKS_URL`: the URL to a valid JSON Web Key Set
* `JWK`: a stringified JSON of a valid JSON Web Key
> You can check [signature\_verifier](/backend//core/utils/signature_verifier.py) for the implementation of the signature verification and the [lifecycle.py](/backend/protocol/_common/lifecycle.py) for how the verifier is selected.
The Web Client currently only supports Clerk based authentication, which is also disabled by default. It can be activated by providing the `NEXT_PUBLIC_CLERK_PUBLISHABLE_KEY` and `CLERK_SECRET_KEY` environment variables (note that the `NEXT_PUBLIC_...` key must be available at build time).
### Setting up Provider Keys
Provider keys determine which AI provider credentials AnotherAI uses to make requests to models.
**For self-hosted users**: Provider keys are required and must be configured via environment variables:
```bash
# .env file
OPENAI_API_KEY=sk-...
ANTHROPIC_API_KEY=sk-ant-...
GOOGLE_API_KEY=...
```
**For cloud users**: AnotherAI provides provider access automatically.
### Try it out
After you have the above set up completed, AnotherAI is ready to use!
* If you have agents already created, check out how to [migrate them to AnotherAI](/use-cases/fundamentals/migrating).
* If you don't have any agents built yet, check out [building a new agent](/use-cases/fundamentals/building) to learn about building a new AnotherAI-compatible agent.
Once you have an agent built or migrated, here are some examples of prompts you can send to your AI assistant to test how AnotherAI works:
## Join the community
If you have questions about AnotherAI, reach out to our team and community on our community [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
# API Keys
URL: /features/api-keys
Managing API keys for authentication
***
title: API Keys
description: Managing API keys for authentication
-------------------------------------------------
## What are AnotherAI API keys used for?
AnotherAI API key enable you to:
* Connect your IDE to AnotherAI via MCP (Model Context Protocol)
* Run your agents using AnotherAI's API
* Give your AI coding agent access to 100+ different models from providers like OpenAI, Anthropic, DeepSeek, and more without managing individual API keys
## Creating API Keys
### Via Web App
If you're just setting up AnotherAI and don't have the MCP connected yet, you'll need to create your first API key through the web app.
1. Log in to AnotherAI (or sign up if you haven't already)
2. Select **API Keys** in the left sidebar
3. Select the **+ New API Key** button
4. Copy and save the generated API key
You can learn more about setting up AnotherAI [here](/#get-started)
API keys are only displayed once. Store your key securely as you won't be able to view it again after leaving the
page.
### Via MCP
Once you have the AnotherAI MCP set up, you can simply ask your preferred AI assistant to create an API key for you using the AnotherAI MCP.
This method is particularly useful when developing agents, as it eliminates the need to switch to the web app to create a new API key manually.
## Deleting API Keys
API keys can only be deleted through the web app:
1. Log in to AnotherAI
2. Navigate to **API Keys** in the left sidebar
3. Select the API key you want to delete
4. Click **Delete**
Before deleting an API key, ensure it's not being used by any active agents or integrations. Deletion will immediately
break any services using that key.
# Caching
URL: /features/caching
Learn how to enable and configure caching in the AnotherAI API.
***
title: Caching
summary: Documentation for caching API requests. Covers caching mechanisms, configuration options, and best practices for both text and image-based requests.
description: Learn how to enable and configure caching in the AnotherAI API.
----------------------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
**Think of caching as free key-value storage**: The LLM input acts as the "key" and the generated output becomes the "value". Once cached, identical requests return the stored result instantly at no cost, effectively giving you a free key-value storage system backed by your LLM interactions.
AnotherAI offers caching capabilities that allow you to reuse the results of identical requests, saving both time and cost. When enabled, the system will return stored results for matching requests for free, instead of making redundant calls to the LLM.
## How caching works
### Input Hash
A unique hash is calculated based on the input provided to the model. This can be:
* The list of `messages` if no specific input variables are used.
* A combination of defined `input` variables (passed via `extra_body`) and the list of `messages` (relevant for replies or when messages supplement templated prompts).
### Version Hash
A hash representing the agent's configuration is computed. This typically includes:
* The model identifier (e.g., `gpt-4o`).
* The `temperature` setting.
* Other version parameters (such as `top_p`, `max_tokens`, etc.).
* For calls using input variables: the message templates are also factored in.
### Cache Check
Before calling the LLM provider and depending on the caching option (see below), AnotherAI checks if a previous run exists with the exact same **Input Hash** and **Version Hash**.
### Cache Hit
If a matching run is found, its saved output is returned immediately, bypassing the actual model call.
## Caching options
The behavior is controlled by the `use_cache` parameter, which can be passed in the `extra_body` of your API request. It accepts the following values:
| Option | Description | Conditions |
| -------------------- | --------------------------------------------------- | -------------------------------------------------------------------- |
| `"auto"` **Default** | The cache is checked only under specific conditions | `temperature` must be `0` and no `tools` are provided in the request |
| `"always"` | The cache is always checked | Regardless of `temperature` setting or use of `tools` |
| `"never"` | The cache is never checked | No caching occurs |
### When does AnotherAI look up the cache?
Caching behaviour depends on three things:
1. `use_cache` (`"auto"`, `"always"`, `"never"`)
2. `temperature`
3. Whether you include `tools` in the request body
The table below shows whether a cache lookup occurs for every combination that matters:
| `use_cache` value | `temperature` | `tools` present? | Cache lookup |
| ------------------ | ------------- | ---------------- | ------------ |
| `"auto"` (default) | `0` | No | ✅ **Yes** |
| `"auto"` | `0` | Yes | ❌ No |
| `"auto"` | > `0` | Any | ❌ No |
| `"always"` | Any | Any | ✅ **Yes** |
| `"never"` | Any | Any | ❌ No |
#### Why the cache is OFF by default when using the OpenAI-compatible endpoint
The OpenAI `chat/completions` endpoint defaults to `temperature = 1`, and AnotherAI inherits that default. Combined with `use_cache = "auto"`, the first row that matches in the table is the third one (`temperature > 0 → ❌ No`).
Therefore, a request will **not** use the cache unless you either:
* set `temperature = 0` **and** omit `tools`, or
* set `use_cache = "always"`.
**Examples:**
```python
import openai
# Configure the OpenAI client to use AnotherAI
client = openai.OpenAI(
api_key="YOUR_ANOTHERAI_API_KEY",
base_url="{{API_URL}}/v1"
)
# Example 1: Cache is NEVER hit (Default behavior)
# Reason: temperature defaults to 1, and use_cache defaults to "auto"
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Describe the meaning of life"}],
metadata={"agent_id": "my-chatbot"}
)
# Example 2: Cache CAN be hit
# Reason: temperature is explicitly 0, meeting the "auto" cache condition.
# A subsequent identical request will hit the cache.
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Describe the meaning of life"}],
temperature=0,
metadata={"agent_id": "my-chatbot"}
)
# Example 3: Cache CAN be hit (using Deployment and "always")
# Reason: use_cache="always" forces a cache check regardless of temperature.
completion = client.chat.completions.create(
model="anotherai/deployment/travel-assistant:production#1", # Using an AnotherAI deployment
# messages might be empty if the prompt is fully server-side
messages=[], # required by SDK so pass an empty array
extra_body={
"input": {
"destination": "Paris",
"traveler_type": "business"
},
"use_cache": "always" # Force cache check
}
# response_format=MyPydanticModel # If expecting structured output
)
# Example 4: Caching with structured outputs
from pydantic import BaseModel
class TravelAdvice(BaseModel):
destination: str
tips: list[str]
warnings: list[str]
completion = client.chat.completions.parse(
model="gpt-4o-mini",
messages=[
{"role": "user", "content": "Give me travel advice for Tokyo"}
],
response_format=TravelAdvice,
temperature=0, # Required for auto caching
extra_body={
"metadata": {"agent_id": "travel-advisor"}
}
)
```
## Caching with AnotherAI features
### Caching and Deployments
When using [deployments](/deployments), the version hash automatically includes all deployment parameters:
```python
# Both requests will use the same cache if inputs match
# The deployment version determines model, temperature, and prompt
completion1 = client.chat.completions.create(
model="anotherai/deployment/customer-support:production#1",
messages=[{"role": "user", "content": "How do I reset my password?"}],
extra_body={
"use_cache": "always"
}
)
# Subsequent identical request hits the cache
completion2 = client.chat.completions.create(
model="anotherai/deployment/customer-support:production#1",
messages=[{"role": "user", "content": "How do I reset my password?"}],
extra_body={
"use_cache": "always"
}
)
```
### Monitoring cache performance
Track cache hit rates using AnotherAI's observability tools.
Ask questions in natural language using your preferred AI assistant:
```
Show me the cache hit rate for each of my agents over the last 7 days
```
```
What's the total requests, cache hits, and cache hit rate percentage for all agents this week?
```
## Caching with images
When using images as input to your models, it's important to understand how the caching mechanism handles different image formats:
### Image input formats and cache behavior
The cache hash is computed based on the **exact input provided**, not the actual content of the image. This means:
* If you provide an image as **base64-encoded data**, the cache hash will be calculated from that base64 string.
* If you provide an image as a **URL** (e.g., S3 URL), the cache hash will be calculated from the URL string itself.
**Important:** Even if both inputs represent the same image content, they will produce **different cache hashes** because the input format differs. The system does not download and compare image contents when computing cache hashes, as this would defeat the performance benefits of caching.
### Examples
```python
# These two requests will have DIFFERENT cache hashes, even if the image is the same
# Request 1: Using base64
completion1 = client.chat.completions.create(
model="gpt-4o",
messages=[{
"role": "user",
"content": [
{"type": "text", "text": "What's in this image?"},
{"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,/9j/4AAQ..."}}
]
}],
temperature=0,
metadata={"agent_id": "image-analyzer"}
)
# Request 2: Using S3 URL for the same image
completion2 = client.chat.completions.create(
model="gpt-4o",
messages=[{
"role": "user",
"content": [
{"type": "text", "text": "What's in this image?"},
{"type": "image_url", "image_url": {"url": "https://s3.amazonaws.com/bucket/image.jpg"}}
]
}],
temperature=0,
metadata={"agent_id": "image-analyzer"}
)
# These will NOT hit the same cache entry
```
### Best practices for image caching
To maximize cache hits when working with images:
1. **Be consistent with your image format**: Choose either base64 or URL format and stick to it across your application.
2. **Use stable URLs**: If using URLs, ensure they don't contain changing parameters (like timestamps or signatures) that would alter the cache hash.
3. **Consider preprocessing**: If you need flexibility in image sources, consider standardizing to one format before making API calls.
# Cost Metadata
URL: /features/cost
undefined
***
title: Cost Metadata
summary: Documentation on the cost metadata returned by the API. Explains how estimated costs are provided for each request and how to access this data programmatically.
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
While most standard LLM APIs return usage metrics (like input and output token counts), they typically don't provide the actual monetary cost of the request. Developers are often left to calculate this themselves, requiring them to maintain and apply up-to-date pricing information for each model.
AnotherAI simplifies cost tracking by automatically calculating the estimated cost for each LLM request based on the specific model used and AnotherAI's current pricing data.
### Programmatically
The cost and latency information are added to each choice in the response:
```python
import openai
client = openai.OpenAI(
api_key="YOUR_ANOTHERAI_API_KEY",
base_url="{{API_URL}}/v1"
)
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Hello!"}],
metadata={"agent_id": "my-agent"}
)
# Access cost and latency from the first choice
cost = getattr(completion.choices[0], 'cost_usd', None)
latency = getattr(completion.choices[0], 'duration_seconds', None)
print(f"Cost: ${cost:.6f}")
print(f"Latency: {latency:.2f}s")
```
```javascript
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: 'YOUR_ANOTHERAI_API_KEY',
baseURL: '{{API_URL}}/v1',
});
const completion = await client.chat.completions.create({
model: 'gpt-4o-mini',
messages: [{ role: 'user', content: 'Hello!' }],
metadata: { agent_id: 'my-agent' }
});
// Access cost and latency from the first choice
const cost = completion.choices[0].cost_usd;
const latency = completion.choices[0].duration_seconds;
console.log(`Cost: $${cost.toFixed(6)}`);
console.log(`Latency: ${latency.toFixed(2)}s`);
```
```bash
curl {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer YOUR_ANOTHERAI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "user", "content": "Hello!"}],
"metadata": {"agent_id": "my-agent"}
}'
# Response includes cost_usd and duration_seconds in each choice:
# {
# "choices": [{
# "message": {...},
# "cost_usd": 0.000015,
# "duration_seconds": 1.23
# }],
# ...
# }
```
```python
from pydantic import BaseModel
import instructor
client = instructor.from_openai(
openai.OpenAI(
api_key="YOUR_ANOTHERAI_API_KEY",
base_url="{{API_URL}}/v1"
)
)
class Answer(BaseModel):
sentiment: str
score: float
answer, completion = client.chat.completions.create_with_completion(
model="gpt-4o-mini",
response_model=Answer,
messages=[{"role": "user", "content": "I love AnotherAI!"}],
metadata={"agent_id": "sentiment-analysis-agent"}
)
# Access cost and latency from the completion
cost = getattr(completion.choices[0], 'cost_usd', None)
latency = getattr(completion.choices[0], 'duration_seconds', None)
print(f"Sentiment: {answer.sentiment}, Score: {answer.score}")
print(f"Cost: ${cost:.6f}, Latency: {latency:.2f}s")
```
## Tracking Costs
### Via MCP
Ask questions about costs in natural language using your preferred AI assistant:
```
What's the total cost for my-agent since January 1st, 2024?
```
```
Show me the sum of all costs for my-agent completions created after 2024-01-01
```
### Creating Cost Views in AnotherAI
Track spending across agents with custom views:
`Create a view in AnotherAI that shows daily costs for calendar_event_extractor.py`
`Create a view showing total monthly spend across all agents, by agent_id, with a line chart`
`Create a cost breakdown view showing spend by model across all agents`
# Overview
URL: /features
Discover how AnotherAI simplifies AI agent development.
***
title: Overview
summary: Explore the powerful features that make AnotherAI the ideal platform for building and deploying AI agents.
description: Discover how AnotherAI simplifies AI agent development.
--------------------------------------------------------------------
import { Card, Cards } from "fumadocs-ui/components/card";
import { BrainCircuit, Cpu, DollarSign, FileJson, HardDrive, Image, Key, Variable } from "lucide-react";
We built AnotherAI with two main goals in mind:
1. Provide all the tools needed for your AI agents to build high-quality, reliable agents for you.
2. Provide you the observability tools to effectively monitor the agents that have been built.
## Explore Features
}>
Get instant access to over 100+ of the latest AI models from all major providers. All with just a single API key.
}>
Unlock clearer versioning and code-free updates by separating static agent content from dynamic data using Jinja2
templates.
}>
Ensure your agents always generate the output format you want by utilizing structured outputs with Pydantic, Zod, or
JSON Schema.
}>
Enable step-by-step reasoning for complex problem solving and configure reasoning effort levels to balance quality
and cost.
}>
Save time and money with intelligent request caching.
}>
Access agent costs with detailed metadata, and create customized cost views for easy visualization and monitoring of
trends.
}>
Create diverse agents that process text, images, and audio inputs across compatible models.
}>
Access everything AnotherAI has to offer with a single API key: connect your IDE via MCP and unlock access to 100+
models.
# Input Variables
URL: /features/input-variables
Separate your agent instructions from dynamic data to improve debugging, enable deployments, and make your agents more maintainable and testable.
***
title: Input Variables
description: Separate your agent instructions from dynamic data to improve debugging, enable deployments, and make your agents more maintainable and testable.
summary: Documentation on using input variables with agents for better observability and debugging. Covers Jinja2 template syntax, common errors, and best practices.
---------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Tabs, Tab } from "fumadocs-ui/components/tabs"
import { Callout } from "fumadocs-ui/components/callout"
## Overview
Input variables allow you to separate static agent instructions from dynamic data, making your agents more maintainable and observable. They use **Jinja2 template syntax** with double braces `{{variable_name}}` to inject variables into your prompts at runtime.
**Benefits of Input Variables:**
* **Better Observability**: Clear separation between static instructions and dynamic data.
* **Easier Debugging**: Variables are displayed separately in run details.
* **Deployment Support**: Required for [deployments](/deployments) to be able to edit prompts without a code change.
## Basic usage
### Providing input variables
Input variables are provided via the `extra_body` parameter in your completion request:
```python
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{
"role": "user",
"content": "Analyze this email: {{email_content}}"
}],
extra_body={
"input": {
"email_content": "Dear team, please review the quarterly report..."
}
},
metadata={"agent_id": "email-analyzer"}
)
```
```typescript
// @ts-expect-error input is specific to the AnotherAI implementation
const completion = await openai.chat.completions.create({
model: "gpt-4o-mini",
messages: [{
role: "user",
content: "Analyze this email: {{email_content}}"
}],
input: {
email_content: "Dear team, please review the quarterly report..."
},
metadata: { agentId: "email-analyzer" }
});
```
```sh
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer $ANOTHERAI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{
"role": "user",
"content": "Analyze this email: {{email_content}}"
}],
"extra_body": {
"input": {
"email_content": "Dear team, please review the quarterly report..."
}
},
"metadata": {"agent_id": "email-analyzer"}
}'
```
### Template syntax
AnotherAI uses **Jinja2** templating with these key patterns:
| Pattern | Usage | Example |
| ------------------------ | ---------------------------- | ------------------------------------------ |
| `{{variable}}` | Simple variable substitution | `{{user_name}}` |
| `{{object.property}}` | Nested object access | `{{user.email}}` |
| `{{list[0]}}` | Array element access | `{{messages[0]}}` |
| `{% if condition %}` | Conditional logic | `{% if is_premium %}...{% endif %}` |
| `{% for item in list %}` | Loop over arrays | `{% for msg in messages %}...{% endfor %}` |
## Examples
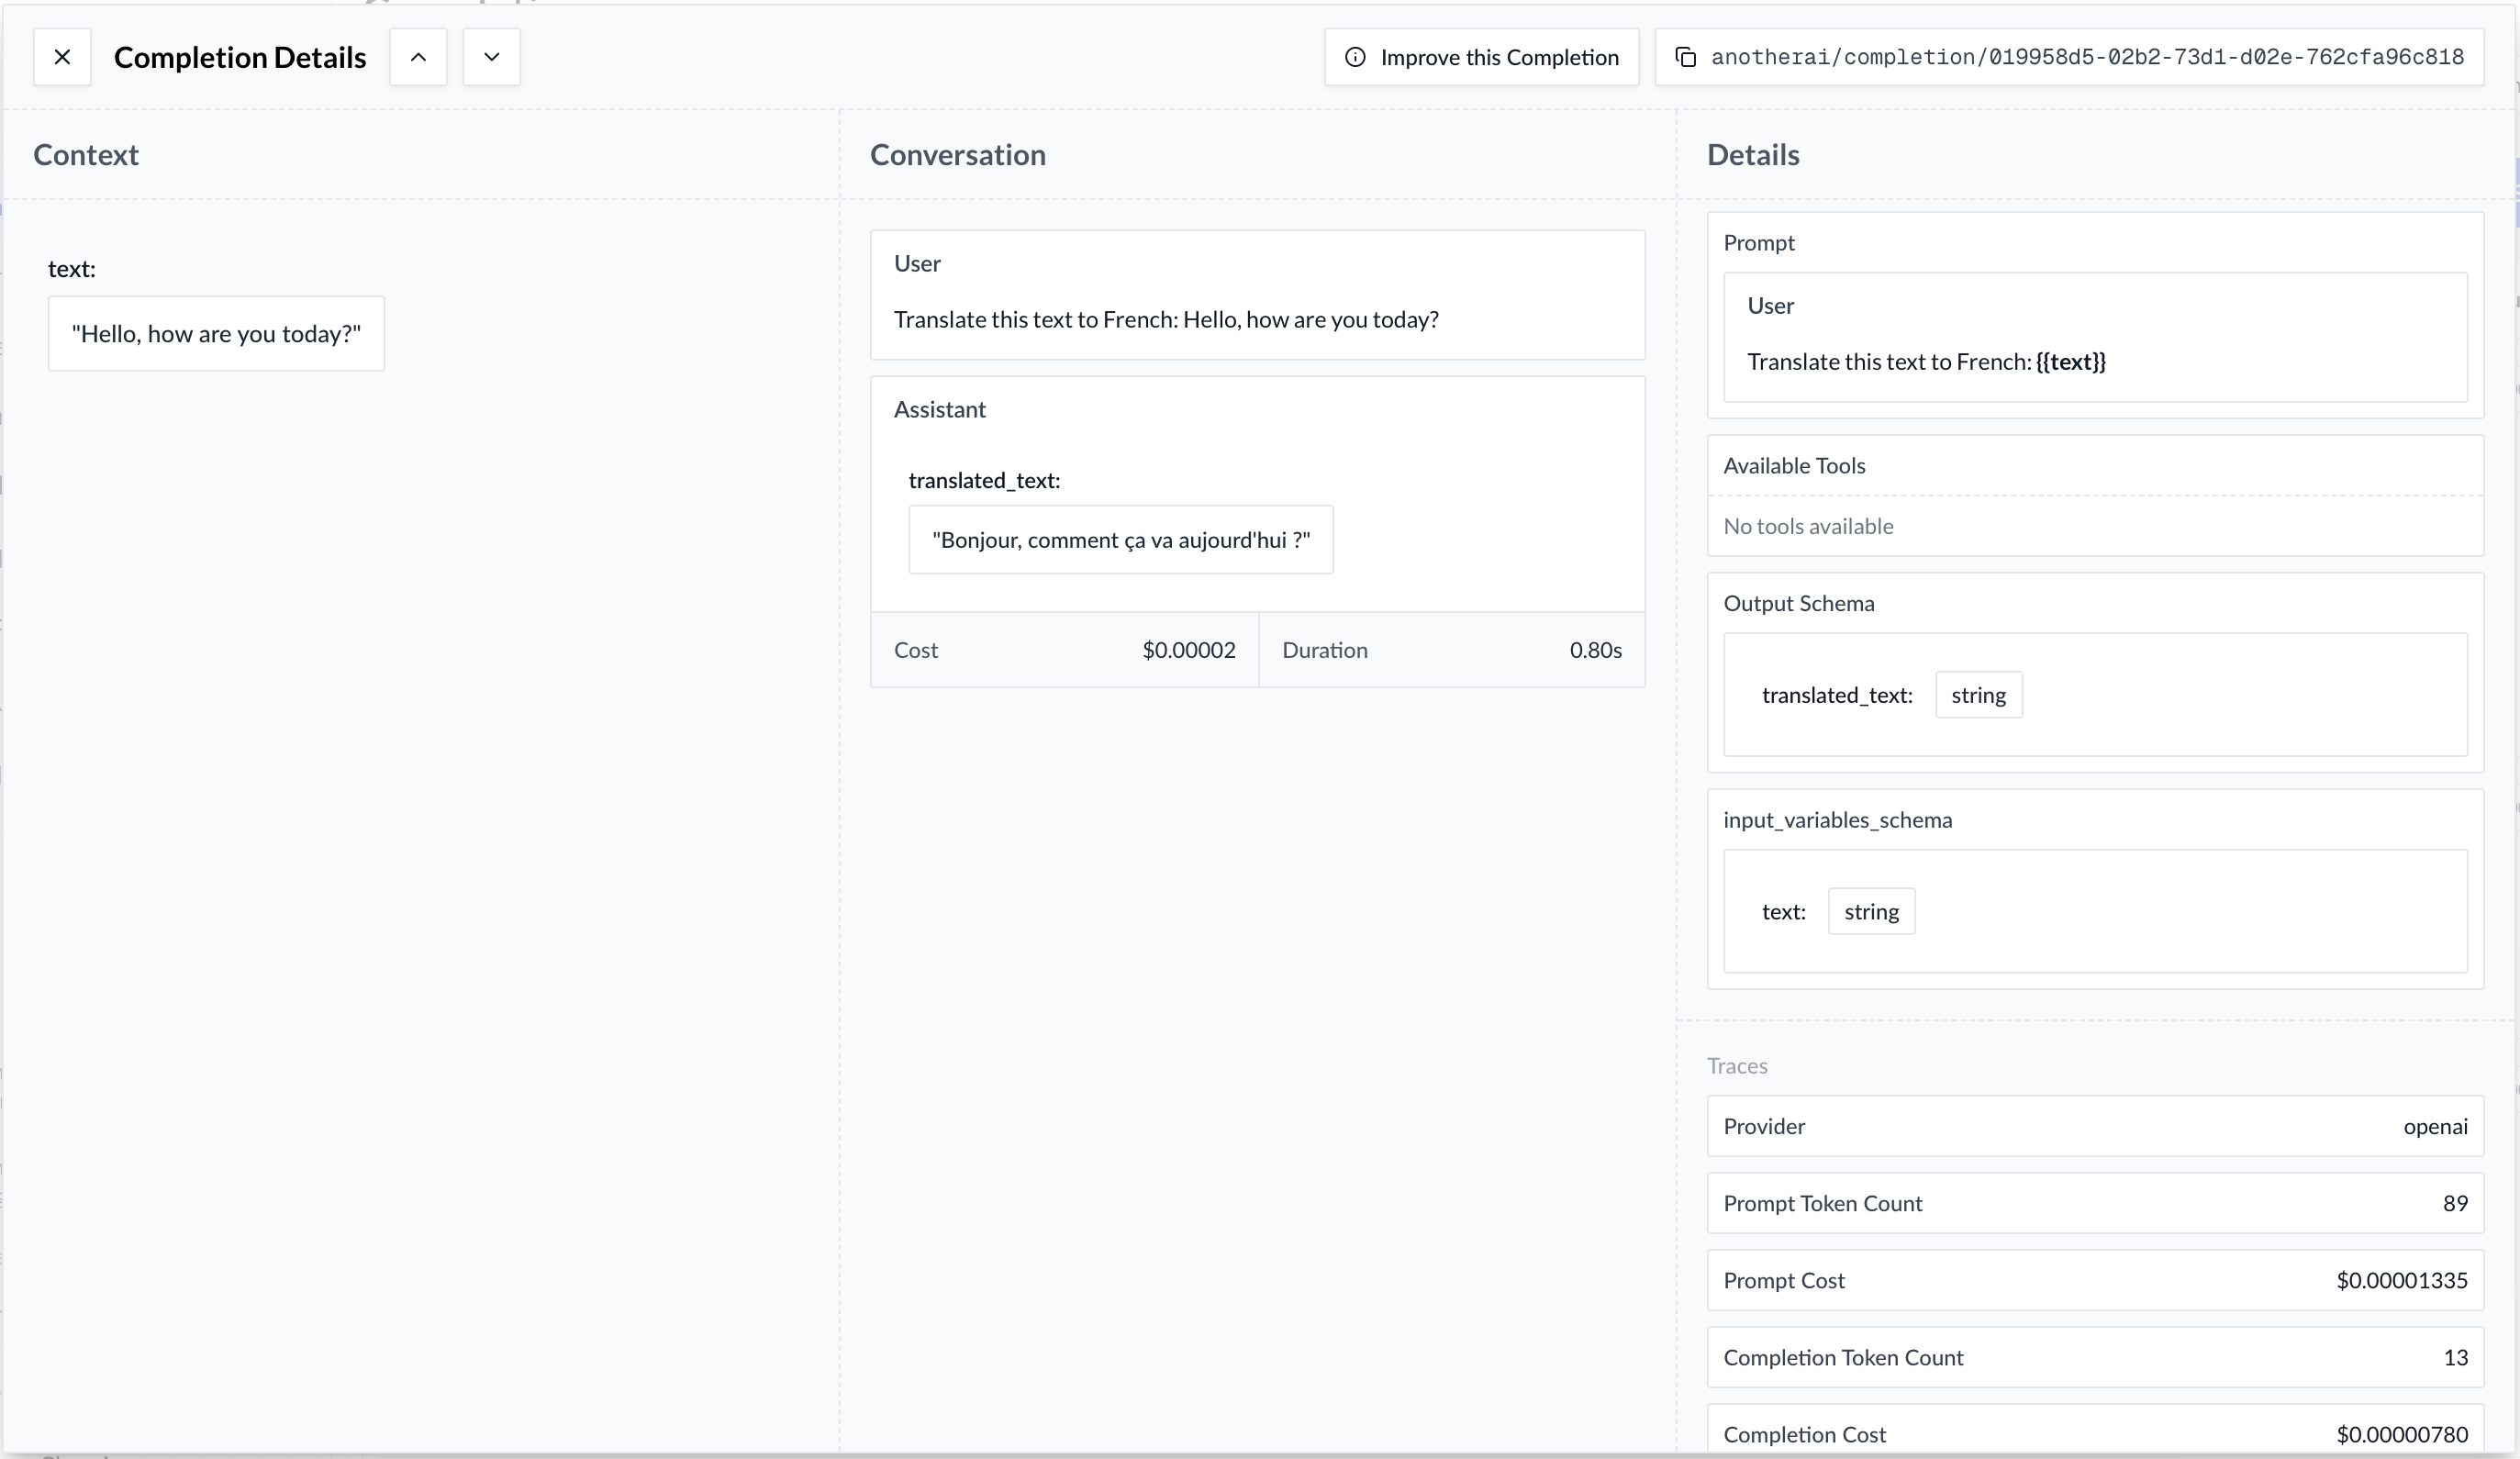
```python
messages = [{
"role": "user",
"content": "Translate this text to French: {{text}}"
}]
extra_body = {
"input": {
"text": "Hello, how are you today?"
}
}
```
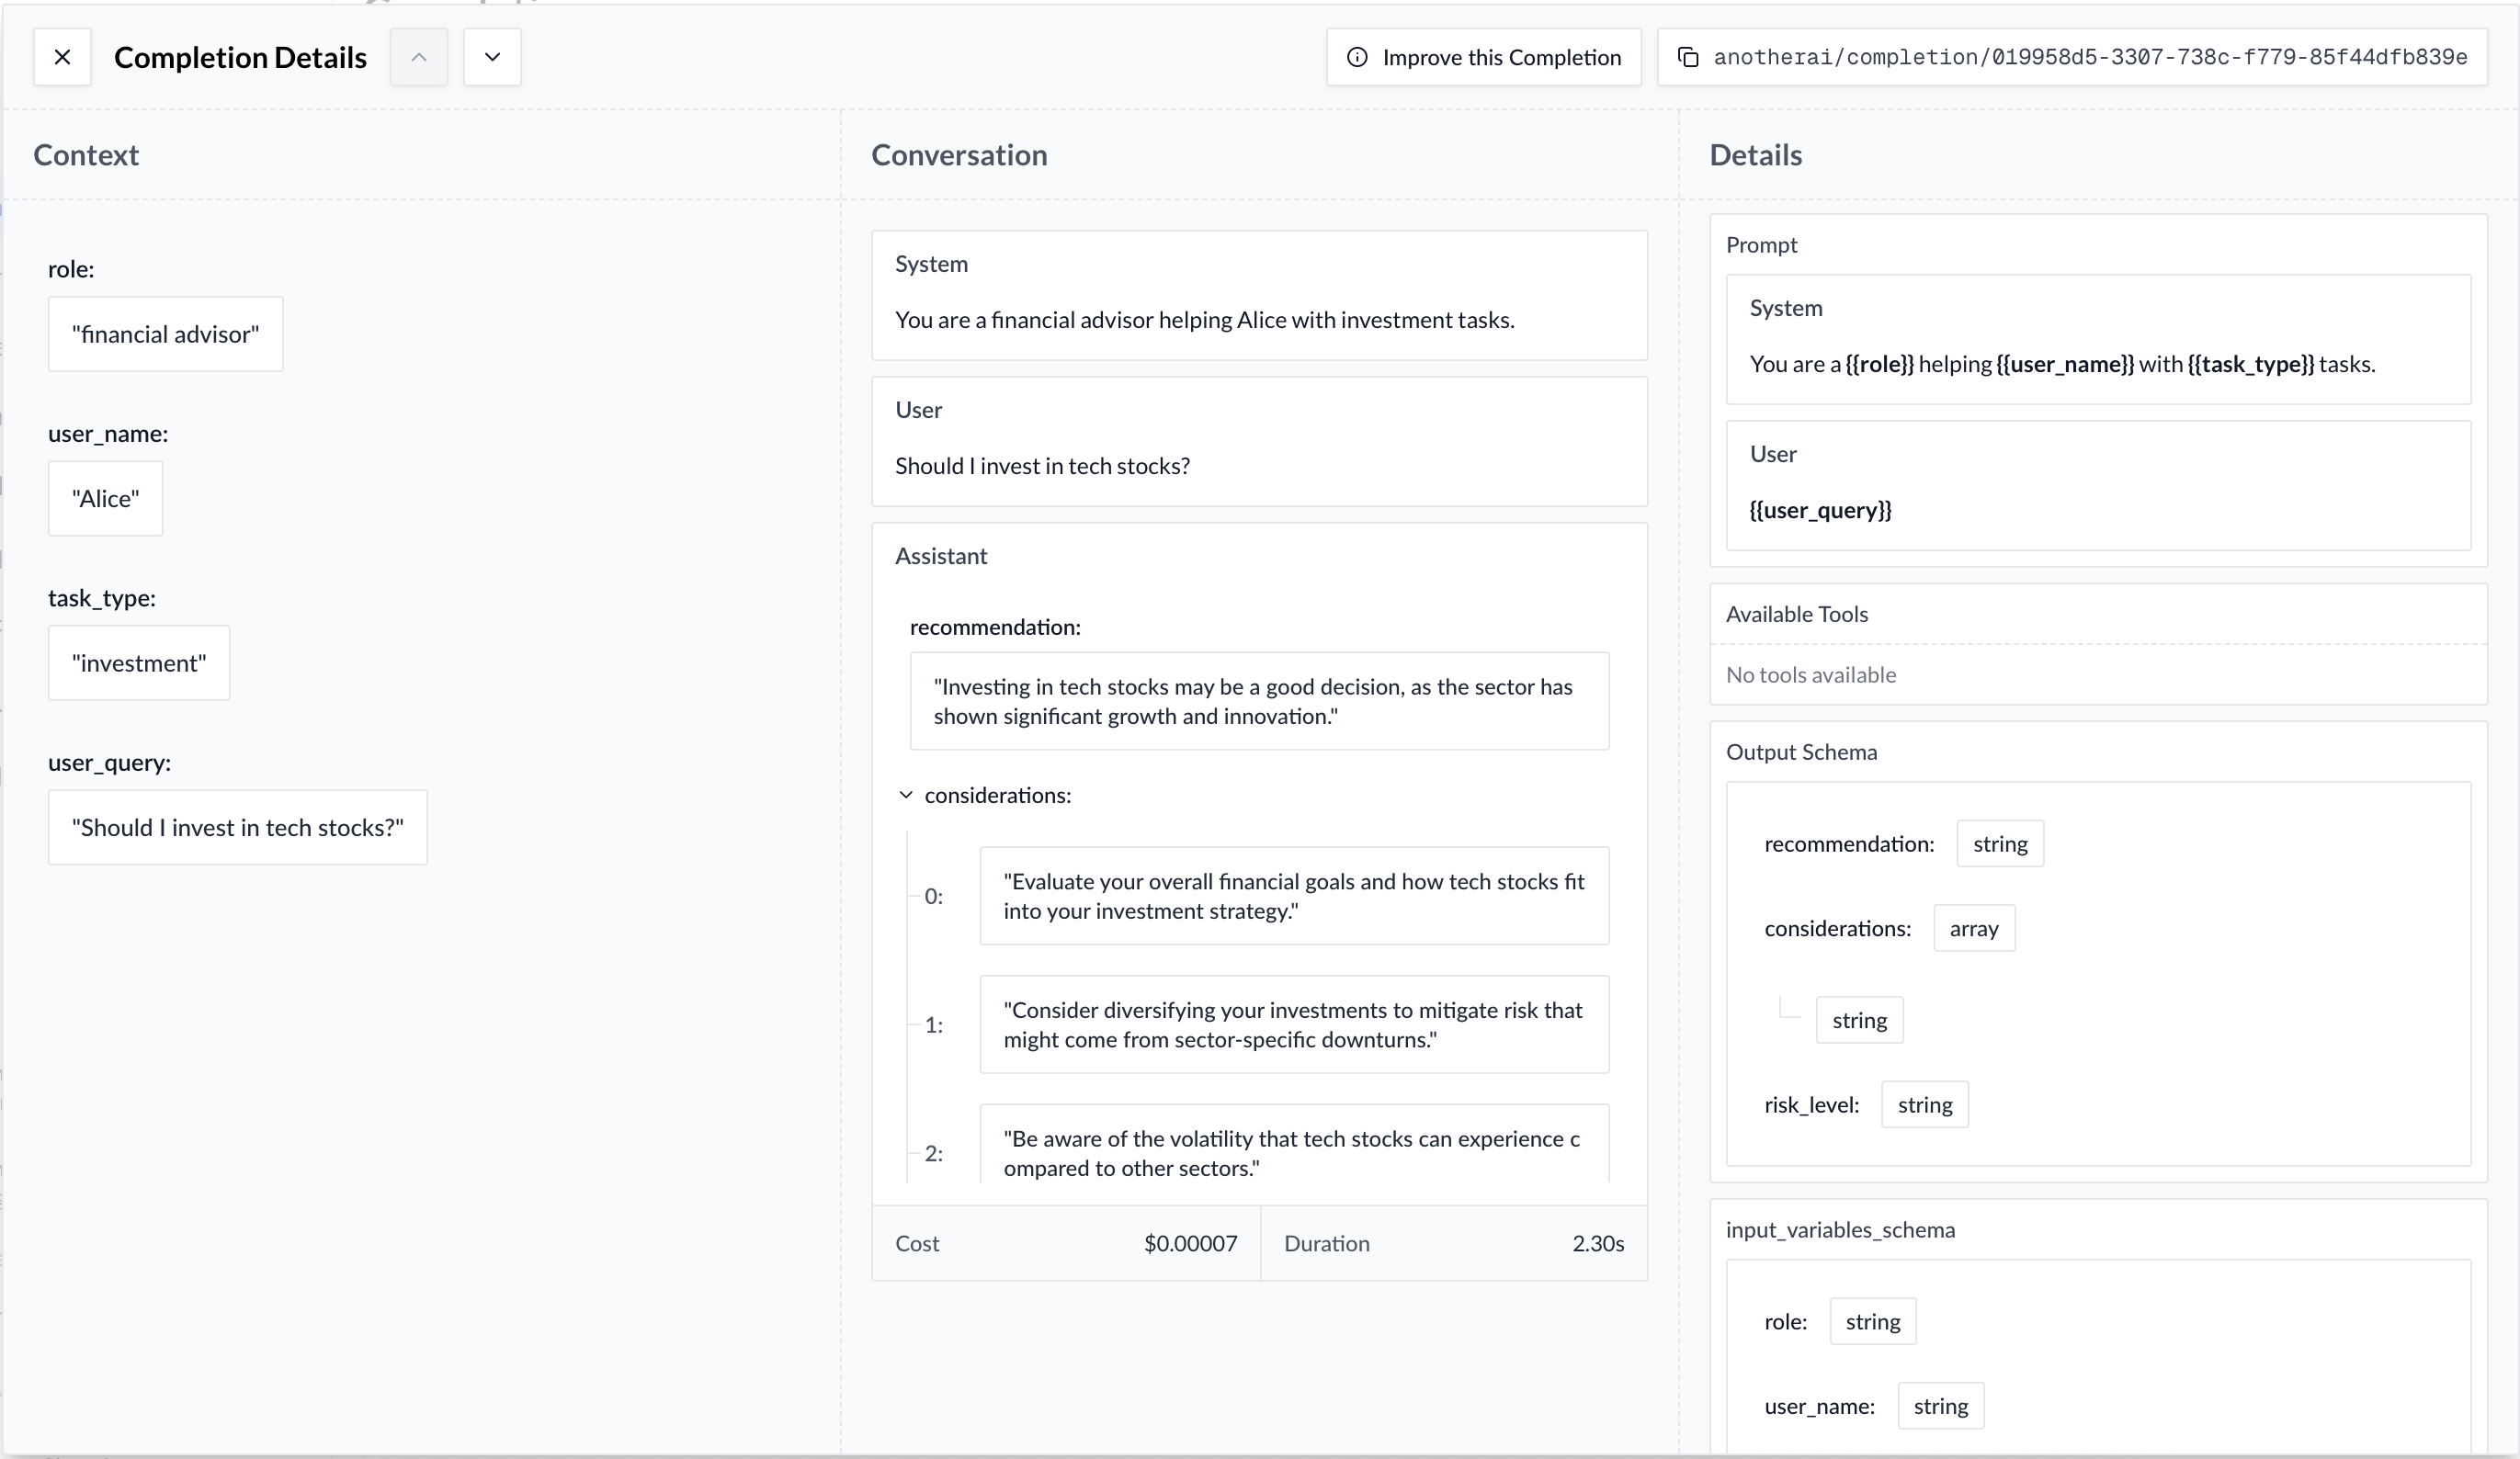
```python
messages = [{
"role": "system",
"content": "You are a {{role}} helping {{user_name}} with {{task_type}} tasks."
}, {
"role": "user",
"content": "{{user_query}}"
}]
extra_body = {
"input": {
"role": "financial advisor",
"user_name": "Alice",
"task_type": "investment",
"user_query": "Should I invest in tech stocks?"
}
}
```
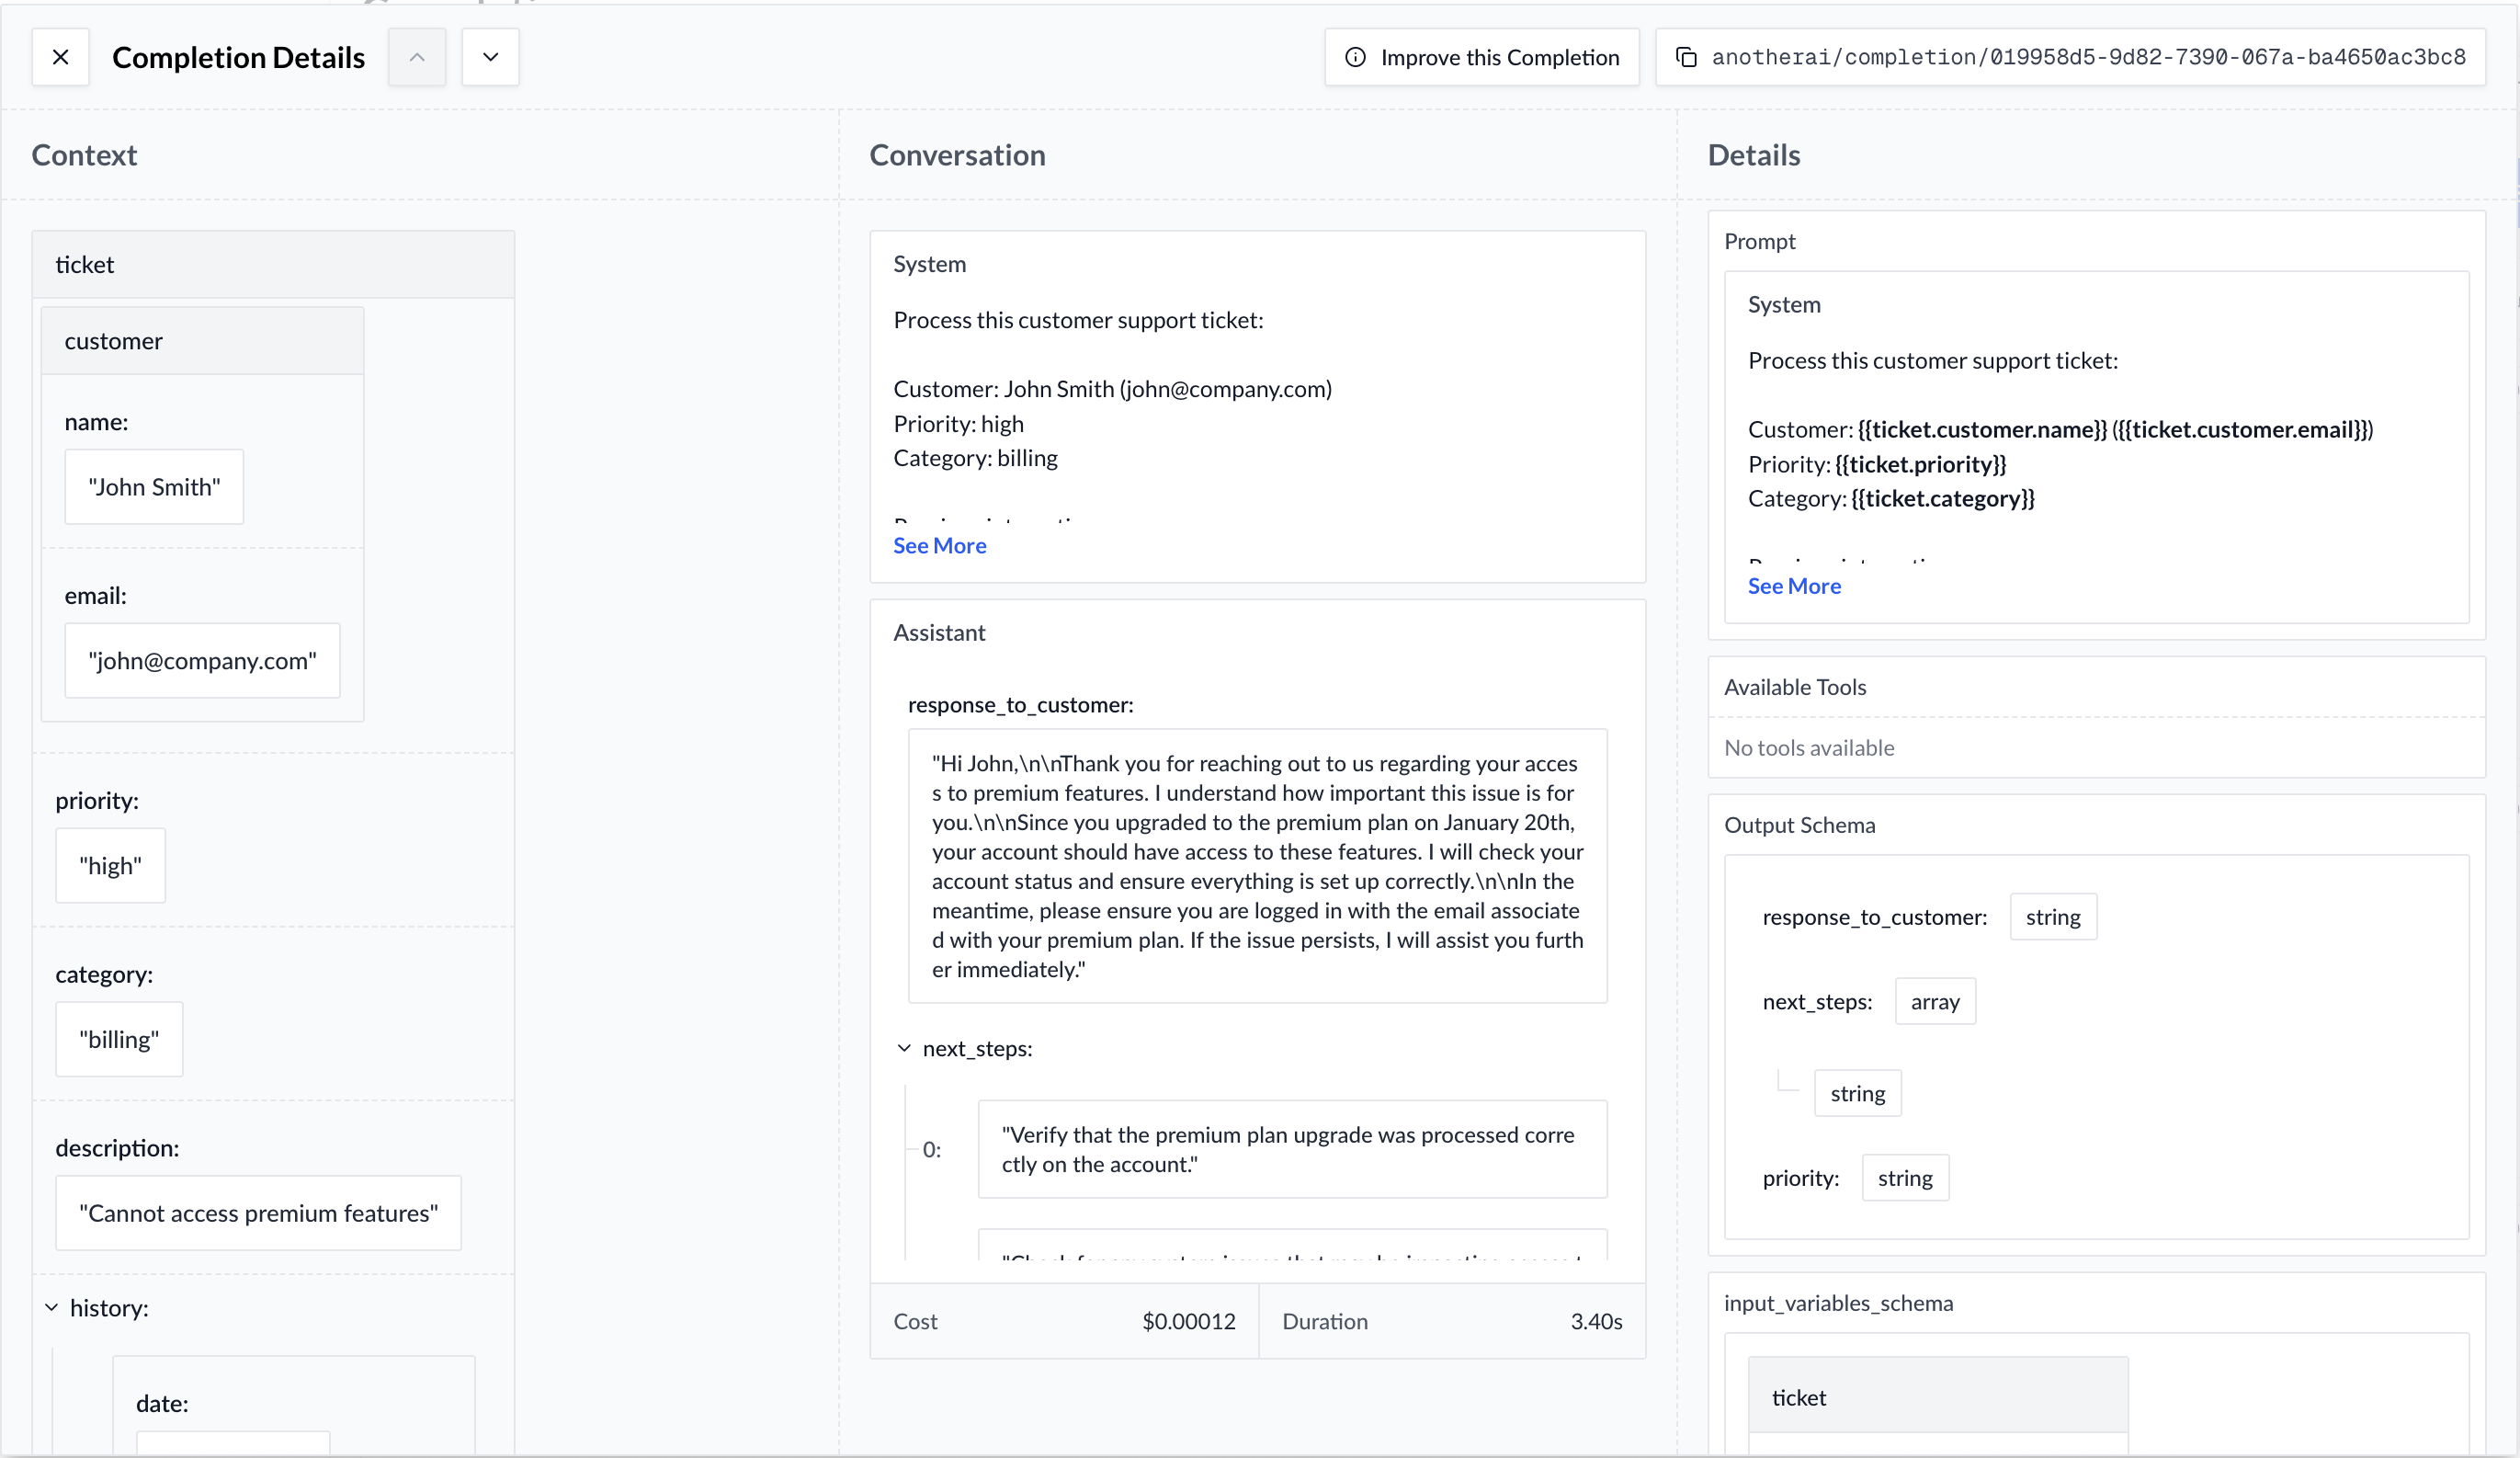
```python
messages = [{
"role": "system",
"content": """Process this customer support ticket:
Customer: {{ticket.customer.name}} ({{ticket.customer.email}})
Priority: {{ticket.priority}}
Category: {{ticket.category}}
Previous interactions:
{% for interaction in ticket.history %}
- {{interaction.date}}: {{interaction.summary}}
{% endfor %}
Current issue: {{ticket.description}}"""
}]
extra_body = {
"input": {
"ticket": {
"customer": {
"name": "John Smith",
"email": "john@company.com"
},
"priority": "high",
"category": "billing",
"description": "Cannot access premium features",
"history": [
{
"date": "2024-01-15",
"summary": "Initial signup completed"
},
{
"date": "2024-01-20",
"summary": "Upgraded to premium plan"
}
]
}
}
}
```
In the AnotherAI web app, these examples would appear like:
## Observability benefits
### Viewing variables in run details
When you use input variables, AnotherAI automatically separates them in the run view:
* **Agent Input**: Shows the variables you provided
* **Agent Output**: Shows the agent's response
* **Prompt View**: Shows the final rendered prompt with variables substituted
{/*
**TODO for Anya**: Add screenshot showing the run details view with input variables separated from output, highlighting the Agent Input, Agent Output, and Prompt View sections.
*/}
**Run View**: In the run details, you'll see a clear separation between your input variables and the agent's output, making debugging much easier.
This separation makes it much easier to:
* Debug issues with specific input data
* Understand what changed between runs
* Test different variable values while keeping instructions constant
### Searching by variables
You can search for runs using input variable values:
1. Go to the **Runs** section in AnotherAI
2. Use the search filters to find runs by:
* Specific variable values (e.g., `input.user_id = "12345"`)
* Variable existence (e.g., runs that have `input.priority`)
* Variable ranges (e.g., `input.score > 0.8`)
{/*
**TODO for Anya**: Add screenshot of the Runs section showing the search filters interface with examples of searching by input variable values.
*/}
Learn more about advanced run searching, including using the MCP tool and API, in the [Search documentation](/observability/runs#search-runs).
## Error handling and debugging
### Common template errors
**Error message:**
```
Template variable 'user_name' is not defined in input variables
```
**Solution:** Ensure all variables used in templates are provided in `extra_body.input`:
```python
# ❌ Missing variable
messages = [{"role": "user", "content": "Hello {{user_name}}"}]
extra_body = {"input": {}} # user_name not provided
# ✅ Correct
messages = [{"role": "user", "content": "Hello {{user_name}}"}]
extra_body = {"input": {"user_name": "Alice"}}
```
**Error message:**
```
Template syntax error: unexpected character '{' at line 1
```
**Common causes:**
* Single braces instead of double: `{variable}` → `{{variable}}`
* Unmatched braces: `{{variable}` → `{{variable}}`
# Supported Models
URL: /features/models
A unified API for 100+ models from leading AI providers including OpenAI, Anthropic, Google, Meta, DeepSeek, Mistral, and more.
***
title: Supported Models
summary: Documentation for using and switching between different AI models. Covers how to list available models and manage versions for agents.
description: A unified API for 100+ models from leading AI providers including OpenAI, Anthropic, Google, Meta, DeepSeek, Mistral, and more.
--------------------------------------------------------------------------------------------------------------------------------------------
import { WorkflowModelsWrapper } from '@/components/workflow-models-wrapper';
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { WorkflowModelCount } from '@/components/workflow-model-count';
## Switching between models
To use a specific model, simply change the `model` parameter in your API call.
```python
import openai
client = openai.OpenAI(
api_key="YOUR_ANOTHERAI_API_KEY",
base_url="{{API_URL}}/v1"
)
# Using GPT-4
response = client.chat.completions.create(
model="gpt-4o", # [!code highlight]
messages=[{"role": "user", "content": "Hello!"}],
metadata={"agent_id": "my-agent"}
)
# Switching to Claude
response = client.chat.completions.create(
model="claude-3-7-sonnet-latest", # [!code highlight]
messages=[{"role": "user", "content": "Hello!"}],
metadata={"agent_id": "my-agent"}
)
# Using Llama
response = client.chat.completions.create(
model="llama4-maverick-instruct-fast", # [!code highlight]
messages=[{"role": "user", "content": "Hello!"}],
metadata={"agent_id": "my-agent"}
)
```
```javascript
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: 'YOUR_ANOTHERAI_API_KEY',
baseURL: '{{API_URL}}/v1',
});
// Using GPT-4
let response = await client.chat.completions.create({
model: 'gpt-4o', // [!code highlight]
messages: [{ role: 'user', content: 'Hello!' }],
metadata: { agent_id: 'my-agent' }
});
// Switching to Claude
response = await client.chat.completions.create({
model: 'claude-3-7-sonnet-latest', // [!code highlight]
messages: [{ role: 'user', content: 'Hello!' }],
metadata: { agent_id: 'my-agent' }
});
// Using Llama
response = await client.chat.completions.create({
model: 'llama4-maverick-instruct-fast', // [!code highlight]
messages: [{ role: 'user', content: 'Hello!' }],
metadata: { agent_id: 'my-agent' }
});
```
```bash
# Using GPT-4
curl {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer YOUR_ANOTHERAI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o", // [!code highlight]
"messages": [{"role": "user", "content": "Hello!"}],
"metadata": {"agent_id": "my-agent"}
}'
# Switching to Claude
curl {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer YOUR_ANOTHERAI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "claude-3-7-sonnet-latest", // [!code highlight]
"messages": [{"role": "user", "content": "Hello!"}],
"metadata": {"agent_id": "my-agent"}
}'
```
## Supported models
### Using the MCP
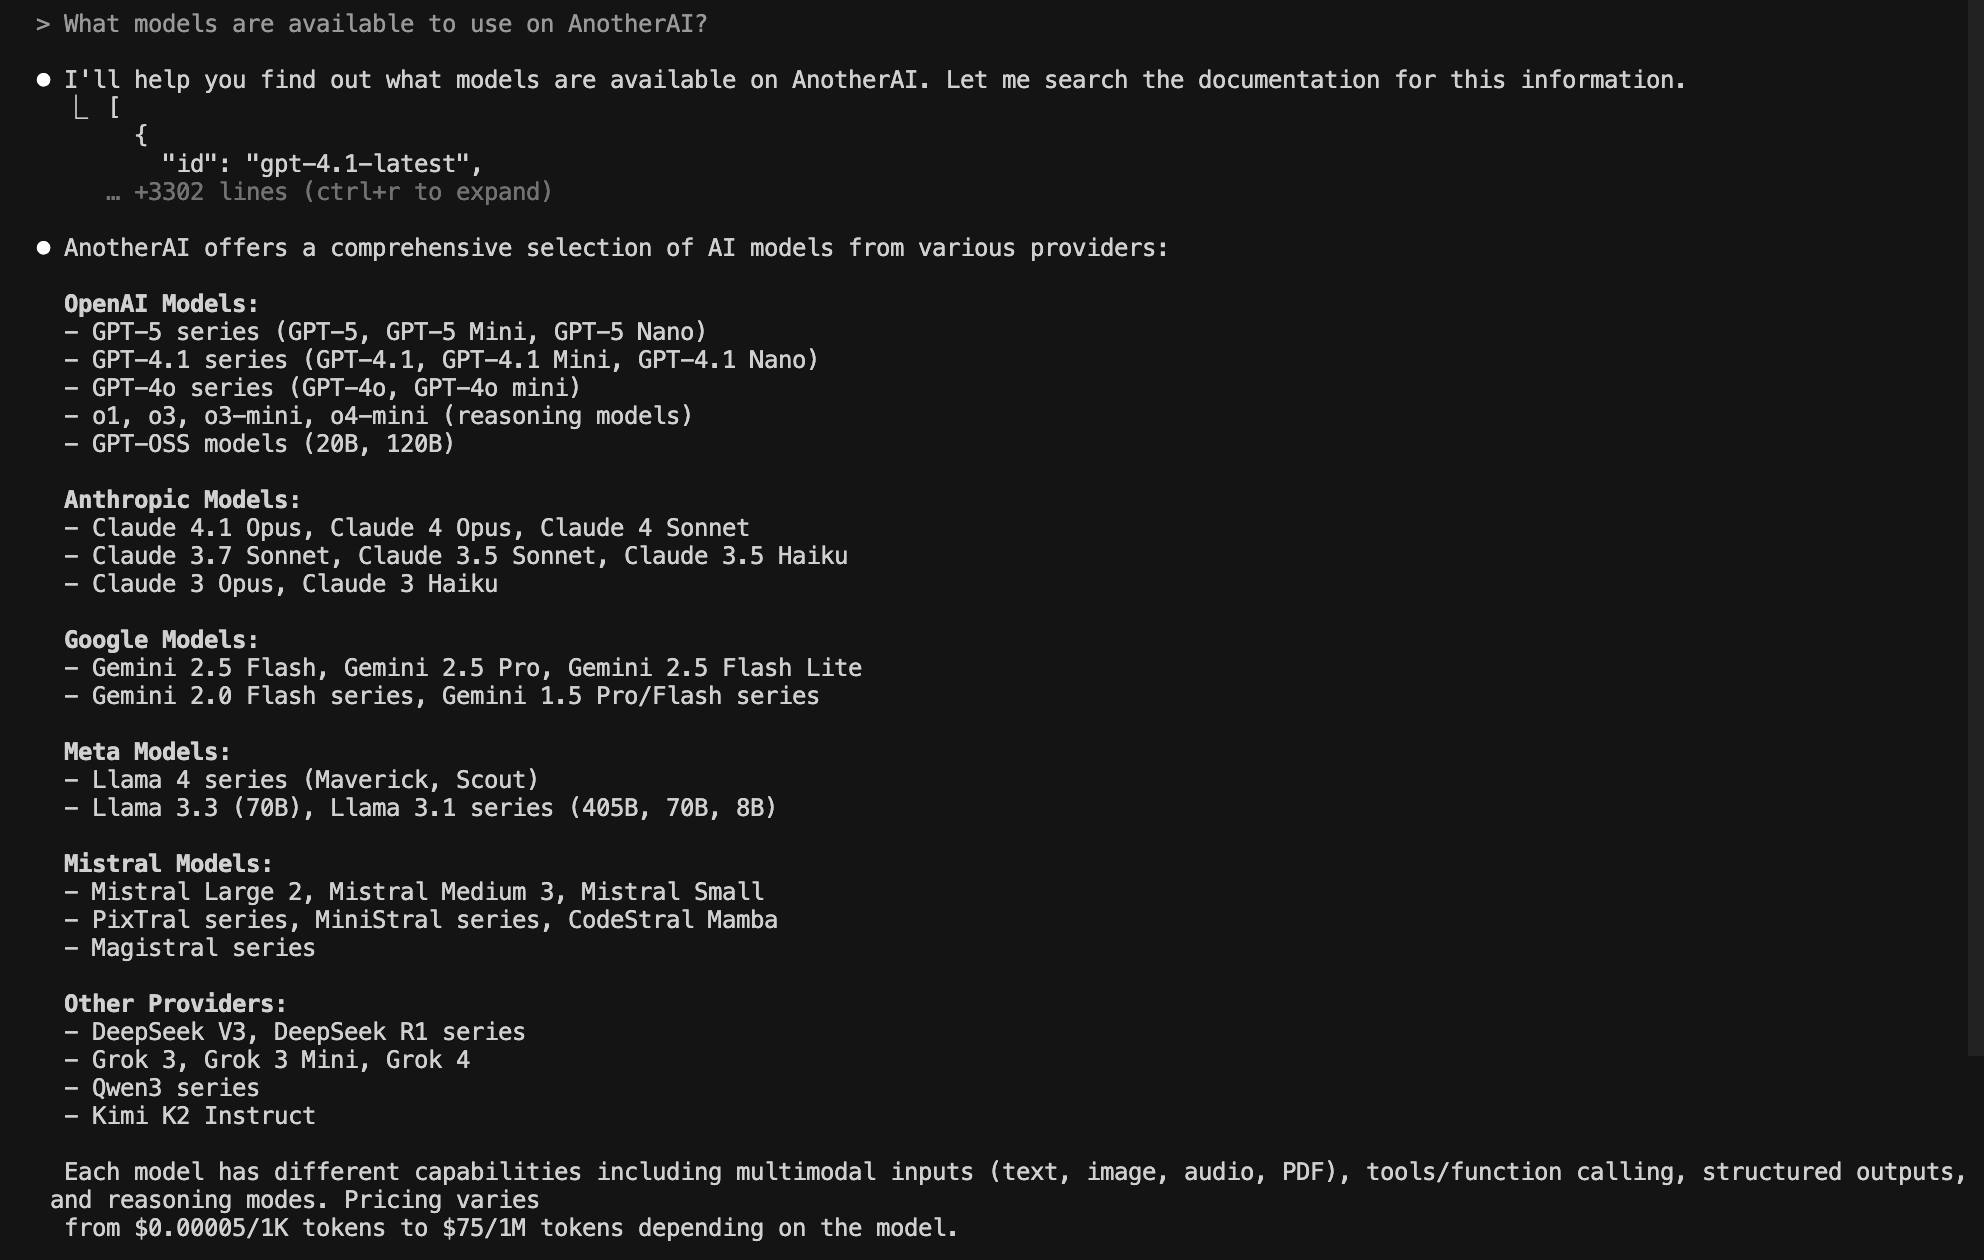
You can list the models available to you via MCP, by asking your preferred AI assistant to list the models:
```bash
What models are available to use on AnotherAI?
```
### Using the API
You can access the [list of models](\{\{API_URL}}/v1/models) and their `id` via our API:
* without any authentication
* in a format compatible with the OpenAI API.
```bash
curl -X GET "{{API_URL}}/v1/models"
```
```python
import openai
client = openai.OpenAI(api_key="YOUR_API_KEY", base_url="{{API_URL}}/v1")
models = client.models.list()
for model in models:
print(model.id)
```
```typescript
import OpenAI from 'openai';
const client = new OpenAI({
apiKey: 'YOUR_API_KEY',
baseURL: '{{API_URL}}/v1',
});
const models = await client.models.list();
models.data.forEach((model) => {
console.log(model.id);
});
```
### List
{/*
TODO:
- Add pricing information.
- Show "price match info"
- ✅ Removed support columns for image, audio, PDF to save space
Add an image ?
*/}
{/*  */}
## Requesting a new model
If you don't see the model you are looking for, you can request it by [contacting us](mailto:team@workflowai.support).
# Non-Text Inputs (Images, PDFs, Audio)
URL: /features/non-text-inputs
undefined
***
title: Non-Text Inputs (Images, PDFs, Audio)
summary: Explanation on how different modalities are supported by AnotherAI
---------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
Just like OpenAI, AnotherAI supports passing images and audio to the completion endpoint. AnotherAI also supports passing PDFs (although OpenAI models do not support processing PDFs, other models including ones from Gemini, Claude, and Mistral do).
### Handling Images
Images can be passed using the `image_url` field, which accepts both public URLs and base64-encoded data.
```js
const response = await openai.chat.completions.create({
model: "gpt-4o-mini",
messages: [
{
role: "user",
content: [
{ type: "text", text: "What's in this image?" },
{ type: "image_url", image_url: { url: "https://example.com/image.png" } }
]
}
]
});
```
```python
response = openai.chat.completions.create(
model="gpt-4o-mini",
messages=[
{
"role": "user",
"content": [
{"type": "text", "text": "What's in this image?"},
{"type": "image_url", "image_url": {"url": "https://example.com/image.png"}}
]
}
]
)
```
### Handling Audio Files
Audio can be passed using the `input_audio` field, which accepts both public URLs and base64-encoded data. When using a URL, simply pass it in the data field and the format parameter will be ignored.
```js
const response = await openai.chat.completions.create({
model: "gpt-4o-mini",
messages: [
{
role: "user",
content: [{ type: "input_audio", input_audio: {
data: "https://example.com/audio.mp3", // just pass a URL in the data field
format: "mp3" // when the data field is a URL, the format is ignored
} }]
}
]
});
```
### Non-Text Inputs Usage in Templates
As described in the [Input Variables](/observability/input-variables) section, it is possible to separate static instructions from dynamic data by using Jinja2 variables in the text content of messages.
**For non-text inputs (images, audio, PDFs), template variables must be passed as their specific content type in a separate content field, not embedded in text strings.** For example, for images, the template variable goes in the `image_url` field of the image content object:
```python
completion = openai.chat.completions.create(
model="gpt-4o-mini",
messages=[
{
"role": "user",
"content": [
{"type": "text", "text": "Please describe this image:"},
{"type": "image_url", "image_url": {"url": "{{image_url}}"}}
]
}
],
extra_body={
"input": {
"image_url": "https://example.com/image.png"
}
}
)
```
```js
const response = await openai.chat.completions.create({
model: "gpt-4o-mini",
messages: [
{
role: "user",
content: [
{ type: "text", text: "Please describe this image:" },
{ type: "image_url", image_url: { url: "{{image_url}}" } }
]
}
],
extra_body: {
input: {
image_url: "https://example.com/image.png",
},
},
});
```
**Important Note:** Attempting to use template variables for modalities directly in text strings will not work. The following approach is incorrect and will result in your AI Agent being unable to access the content properly.
```python
# INCORRECT - Will not work for image inputs
completion = openai.chat.completions.create(
model="gpt-4o-mini",
messages=[
{
"role": "user",
"content": "Please describe {{image_url}}" # Wrong - treats as text
}
],
extra_body={
"input": {
"image_url": "https://example.com/image.png"
}
}
)
```
```js
// INCORRECT - Will not work for image inputs
const response = await openai.chat.completions.create({
model: "gpt-4o-mini",
messages: [
{
role: "user",
content: "Please describe {{image_url}}" // Wrong - treats as text
}
],
extra_body: {
input: {
image_url: "https://example.com/image.png"
}
}
});
```
# Reasoning Models
URL: /features/reasoning
Enable reasoning on capable models and retrieve the reasoning content.
***
title: Reasoning Models
summary: Documentation on using reasoning models. Explains how to enable and configure reasoning mode to get step-by-step thought processes from supported AI models.
description: Enable reasoning on capable models and retrieve the reasoning content.
-----------------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Callout } from 'fumadocs-ui/components/callout';
## What is reasoning?
Reasoning mode is a capability available in certain AI models that allows them to engage in explicit step-by-step reasoning before providing their final answer. When reasoning mode is enabled, the model generates internal "thoughts" that show its reasoning process, problem-solving steps, and decision-making logic.
Reasoning mode can unlock better inference capabilities in complex use cases; however, it can add extra cost and latency, since the **reasoning content** is generated prior to the response and count towards the used tokens. It is important to consider the trade-off when enabling reasoning mode.
## Configuration
All providers have a different way of configuring reasoning mode or returning the reasoning content:
* [OpenAI](https://platform.openai.com/docs/guides/reasoning) and [xAI](https://docs.x.ai/docs/guides/reasoning) expose a **reasoning effort** parameter (`low`, `medium`, `high`).
* [Anthropic](https://docs.anthropic.com/en/docs/build-with-claude/extended-thinking) and [Google](https://ai.google.dev/gemini-api/docs/thinking) allow providing a thinking budget, limiting the number of tokens used for thinking.
* Fireworks does not support configuring reasoning mode
To reconcile differences between providers, AnotherAI converts back and forth between a reasoning effort and a reasoning budget (also called thinking budget).
Each reasoning effort level corresponds to a reasoning budget that allocates a specific percentage of the model's maximum output tokens.
| Reasoning Effort | Maximum Token Budget |
| ---------------- | -------------------------------- |
| `disabled` | Disables reasoning when possible |
| `low` | **20%** of maximum output tokens |
| `medium` | **50%** of maximum output tokens |
| `high` | **80%** of maximum output tokens |
In the inverse, the reasoning budget is converted to a reasoning effort:
| Token Budget Range | Converted to Effort |
| ------------------------------- | --------------------------------------------- |
| `0`% | `disabled` (disables reasoning when possible) |
| Up to **20%** of max tokens | `low` |
| **20%** - **50%** of max tokens | `medium` |
| Above **50%** of max tokens | `high` |
Reasoning can be configured via the `reasoning` request parameter which is an object with the following fields:
* `budget`: integer, the reasoning budget in tokens
* `effort`: string, the reasoning effort, one of `disabled`, `low`, `medium`, `high`
```json
{
"reasoning": {
"budget": 10000
}
}
```
```json
{
"reasoning": {
"effort": "medium"
}
}
```
Either `budget` or `effort` can be provided, but not both.
{/*
TODO: add table about reasoning effort and budget for each provider by calling the /v1/models endpoint
*/}
As explained above, the way providers allow configuring reasoning is different. The same value can be sent differently to each provider. For example, given a reasoning budget of `50k tokens`, AnotherAI will send:
* a reasoning effort of `medium` if using o3, since o3 has max output tokens of 100k
* a thinking budget of `50k` if using claude 4 sonnet
* nothing if using deepseek r1, since fireworks does not support configuring reasoning
OpenAI completion API exposes a `reasoning_effort` (`low`, `medium`, `high`) parameter. It is also supported by AnotherAI but does not allow configuring a granular thinking budget or disabling reasoning.
## Usage
### Completion API
As explained above, the reasoning effort can be passed as a parameter to the completion API. Thoughts can then be retrieved from the choice object via a AnotherAI specific field `reasoning_content`.
As the `reasoning_content` field is not part of the OpenAI API response, it will likely throw a typing issue when accessed.
For now, since AnotherAI relies on the OpenAI completion API which does not return the reasoning content, the reasoning content will not be available on OpenAI models.
```python
res = openai.chat.completions.create(
model="claude-4-sonnet",
messages=[{"role": "user", "content": "What is the meaning of life?"}],
extra_body={
"reasoning": {
"budget": 10000,
# or "effort": "low",
}
}
)
# Access the reasoning content
print(res.choices[0].message.reasoning_content) # type: ignore
# Access the reasoning tokens
print(res.usage.completion_tokens_details.reasoning_tokens)
```
```typescript
const res = await openai.chat.completions.create({
model: "claude-4-sonnet",
messages: [{ role: "user", content: "What is the meaning of life?" }],
extra_body: {
reasoning: {
budget: 10000,
// or "effort": "low",
}
}
});
// Access the reasoning content
// @ts-expect-error - reasoning_content is not part of the OpenAI API
console.log(res.choices[0].message.reasoning_content);
// Access the reasoning tokens usage
console.log(res.usage.completion_tokens_details.reasoning_tokens);
```
```json
{
"model": "claude-4-sonnet",
"messages": [
{
"role": "user",
"content": "What is the meaning of life?"
}
],
"reasoning": {
"budget": 10000,
// or "effort": "low",
}
}
```
When streaming, the reasoning content deltas are also returned at the same level as the content field.
```python
print(res.choices[0].delta.reasoning_content)
print(res.choices[0].delta.content)
```
```typescript
console.log(res.choices[0].delta.reasoning_content);
console.log(res.choices[0].delta.content);
```
### Viewing reasoning models
The [AnotherAI models endpoint](\{\{API_URL}}/v1/models) exposes the parameter `supports.reasoning`.
```json
{
"data": [
{
"id": "claude-4-sonnet",
...,
"supports": {
"reasoning": true
}
},
...
]
}
```
It is also possible to filter for reasoning models via the `reasoning` query parameter.
```python
models = openai.models.list(extra_query={"reasoning": True})
# The supports field is ignored by the OpenAI SDK so it is not accessible
print(models.data)
```
```sh
curl {{API_URL}}/v1/models?reasoning=true
```
# Streaming
URL: /features/streaming.private
Learn how to stream model responses from the AnotherAI API using server-sent events.
***
title: Streaming
summary: Documentation on streaming responses from the API. Covers enabling streaming, processing response chunks, and handling complete JSON outputs.
description: Learn how to stream model responses from the AnotherAI API using server-sent events.
-------------------------------------------------------------------------------------------------
import { Tab, Tabs } from 'fumadocs-ui/components/tabs';
By default, when you make a request to the AnotherAI API, the model generates the entire output before returning it in a single HTTP response. For longer outputs, this can mean waiting until the full response is ready. With streaming, you can start receiving and processing the model's output as it is generated, allowing you to display or use partial results in real time.
## Enable streaming
Streaming is available exactly like in the OpenAI API. If you are already streaming from the OpenAI API, no code change is required.
To stream completions, set `stream=True` in the request.
The response is sent back incrementally in chunks with an event stream. You can iterate over the event stream with a for loop, like this:
```python
from openai import OpenAI
client = OpenAI(
base_url="{{API_URL}}/v1",
api_key="aai--***",
)
stream = client.chat.completions.create(
model="gpt-4.1",
messages=[
{
"role": "user",
"content": "Say 'double bubble bath' ten times fast.",
},
],
stream=True, # [!code highlight]
)
for chunk in stream:
print(chunk)
print(chunk.choices[0].delta)
print("****************")
```
## Read the responses
When you stream a chat completion, the responses have a `delta` field rather than a `message` field. The `delta` field can hold a role token, content token, or nothing.
```
{ role: 'assistant', content: '', refusal: null }
****************
{ content: 'Why' }
****************
{ content: " don't" }
****************
{ content: ' scientists' }
****************
{ content: ' trust' }
****************
{ content: ' atoms' }
****************
{ content: '?\n\n' }
****************
{ content: 'Because' }
****************
{ content: ' they' }
****************
{ content: ' make' }
****************
{ content: ' up' }
****************
{ content: ' everything' }
****************
{ content: '!' }
****************
{}
****************
```
To stream only the text response of your chat completion, your code would look like this:
```python
from openai import OpenAI
client = OpenAI(
base_url="{{API_URL}}/v1",
api_key="aai--***",
)
stream = client.chat.completions.create(
model="gpt-4.1",
messages=[
{
"role": "user",
"content": "Say 'double bubble bath' ten times fast.",
},
],
stream=True,
)
for chunk in stream:
if chunk.choices[0].delta.content is not None:
print(chunk.choices[0].delta.content, end="")
```
## Streaming complete JSON outputs
When using JSON outputs, it can be quite complicated to piece together the deltas in order to get a usable partial JSON object. The final payload is split into multiple chunks that only amount to a valid JSON object at the very end.
For example, when trying to extract a user with a name, age and email in JSON form:
```json
{
"name": "John Doe",
"age": 30,
"email": "john.doe@example.com"
}
```
The chunks can have the following content deltas:
```sh
{"name
":"
"John
Doe
",
...
```
By setting the `stream_options.valid_json_chunks` parameter to `true`, AnotherAI can aggregate the deltas into valid partial JSON objects, transforming the above deltas into:
```sh
# Chunks that do not represent an update of the JSON object are ignored
# Each chunk is a valid JSON object
{"name": "John"}
{"name": "John Doe"}
...
```
```python
streamer = await openai_client.chat.completions.create(
model="gpt-4o",
metadata={"agent_id": "my-agent"},
messages=...,
stream=True,
# The following can break typing since `valid_json_chunks` is not supported by OpenAI,
# one solution is to cast to ChatCompletionStreamOptionsParam
stream_options={"valid_json_chunks": True},
response_format={"type": "json_object"}, # or "json_schema"
)
async for chunk in streamer: # Every content delta is a valid JSON object
print(json.loads(chunk.choices[0].delta.content))
```
```typescript
const completion = await openai.chat.completions.create({
model: 'gpt-4o',
metadata: { agent_id: 'my-agent' },
messages: ...,
response_format: { type: 'json_object' }, // or "json_schema"
stream: true,
stream_options: {
//@ts-expect-error - valid_json_chunks is not supported by OpenAI
valid_json_chunks: true,
},
})
for await (const chunk of completion) {
if (chunk.choices[0].delta.content) {
console.log(JSON.parse(chunk.choices[0].delta.content));
}
}
```
```sh
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer aai--***" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o",
"messages": [],
"stream": true,
"stream_options": {
"valid_json_chunks": true
},
"response_format": {
"type": "json_object"
},
"metadata": {
"agent_id": "my-agent"
}
}'
```
# Structured Outputs
URL: /features/structured-outputs
Generate type-safe, structured responses from AI models
***
title: Structured Outputs
summary: Documentation on generating structured JSON responses. Covers using Pydantic, Zod, and JSON Schema to ensure type-safe, validated data from AI models.
description: Generate type-safe, structured responses from AI models
--------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
## Introduction
When building AI applications, you often need responses in a specific format—whether that's extracting data fields, classifying into different categories, or generating different fields. JSON has become the universal language for data exchange between applications, but getting AI models to consistently produce valid, well-structured JSON can be challenging.
Structured Outputs solves this problem by ensuring AI models always generate responses that perfectly match your defined JSON Schema. Instead of hoping the model follows your formatting instructions or writing complex validation logic, you get guaranteed compliance with your data structure requirements.
For example: imagine you want to extract the name, age, and email of a user from a text.
```python
from pydantic import BaseModel
class User(BaseModel):
name: str
age: int
email: str
```
```typescript
import { z } from "zod";
const User = z.object({
name: z.string(),
age: z.number(),
email: z.string()
});
```
```json
{
"type": "json_schema",
"json_schema": {
"name": "User",
"strict": true,
"schema": {
"type": "object",
"properties": {
"name": {
"type": "string"
},
"age": {
"type": "integer"
},
"email": {
"type": "string"
}
},
"required": ["name", "age", "email"],
"additionalProperties": false
}
}
}
```
**Key benefits of Structured Outputs:**
1. **Reliable type-safety**: No need to validate or retry incorrectly formatted responses
2. **Explicit refusals**: Safety-based model refusals are now programmatically detectable
3. **Simpler prompting**: No need for strongly worded prompts to achieve consistent formatting
## Supported models
A key benefit of using AnotherAI's inference API is that structured outputs are supported across all available models. While some providers only support structured outputs on specific models, AnotherAI ensures you get properly formatted data from any model you choose to use. This means you can reliably extract structured data regardless of which underlying model powers your application.
## How to use
The `openai` Python library offers a highly convenient way to achieve this by directly providing a [Pydantic](https://docs.pydantic.dev/latest/) model definition.
To get structured output using the `openai` Python library with AnotherAI:
1. Define your desired output structure as a Pydantic `BaseModel`.
2. Use the `client.chat.completions.parse()` method (note the `.parse()` instead of `.create()`).
3. Pass your Pydantic class directly to the `response_format` parameter.
4. Access the parsed Pydantic object directly from `response.choices[0].message.parsed`.
**Example: Basic Usage with Deployments**
Let's redefine the `get_country` example using a Pydantic model:
```python
from pydantic import BaseModel
# Assuming `openai` client is configured as `client`
class CountryInfo(BaseModel): # [!code highlight]
country: str # [!code highlight]
population: int # [!code highlight]
def get_country(city: str):
# Use the `.parse()` method for structured output with Pydantic
# `client.beta.chat` in older versions of the SDK
completion = client.chat.completions.parse( # [!code highlight]
model="gpt-4o",
messages=[
{"role": "system", "content": "You are a helpful assistant that extracts geographical information."},
{"role": "user", "content": f"What is the country and population of {{city}}?"}
],
# Pass the Pydantic class directly as the response format
response_format=CountryInfo, # [!code highlight]
extra_body={
"input": {
"city": city
}
},
metadata={
"agent_id": "country-extractor",
}
)
parsed_output: CountryInfo = completion.choices[0].message.parsed # [!code highlight]
return parsed_output
```
This approach leverages the `openai` library's integration with Pydantic to abstract away the manual JSON schema definition and response parsing, providing a cleaner developer experience.
The `openai` TypeScript library provides structured output support using [Zod](https://zod.dev/) schemas for type-safe validation.
To get structured output using the `openai` TypeScript library with AnotherAI:
1. Define your desired output structure using Zod schema.
2. Use the `client.chat.completions.parse()` method.
3. Pass your Zod schema using `zodResponseFormat()` helper to the `response_format` parameter.
4. Access the parsed object directly from `response.choices[0].message.parsed`.
**Example: Basic Usage with Deployments**
Let's redefine the `get_country` example using a Zod schema:
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
// Assuming `openai` client is configured as `client`
const CountryInfo = z.object({ // [!code highlight]
country: z.string(), // [!code highlight]
population: z.number().int() // [!code highlight]
}); // [!code highlight]
async function getCountry(city: string) {
// Use the `.parse()` method for structured output with Zod
// `client.beta.chat` in older versions of the SDK
const completion = await client.chat.completions.parse({ // [!code highlight]
model: "gpt-4o",
messages: [
{role: "system", content: "You are a helpful assistant that extracts geographical information."},
{role: "user", content: `What is the country and population of {{city}}?`}
],
// Pass the Zod schema using zodResponseFormat helper
response_format: zodResponseFormat(CountryInfo, "CountryInfo"), // [!code highlight]
input: {
city: city
},
metadata: {
agent_id: "country-extractor",
}
});
const parsedOutput = completion.choices[0].message.parsed; // [!code highlight]
return parsedOutput;
}
```
This approach leverages the `openai` library's integration with Zod to provide type-safe structured outputs with TypeScript.
For direct API integration, you can use CURL with raw JSON Schema definitions.
To get structured output using CURL with AnotherAI:
1. Define your desired output structure using JSON Schema format.
2. Use the `/v1/chat/completions` endpoint.
3. Pass your JSON schema in the `response_format` parameter with `type: "json_schema"`.
4. Access the parsed JSON from the response.
**Example: Basic Usage with Deployments**
Let's redefine the `get_country` example using raw JSON Schema:
```bash
curl {{API_URL}}/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer YOUR_API_KEY" \
-d '{
"model": "gpt-4o",
"messages": [
{
"role": "system",
"content": "You are a helpful assistant that extracts geographical information."
},
{
"role": "user",
"content": "What is the country and population of {{city}}?"
}
],
"response_format": {
"type": "json_schema",
"json_schema": {
"name": "CountryInfo",
"strict": true,
"schema": {
"type": "object",
"properties": {
"country": {
"type": "string"
},
"population": {
"type": "integer"
}
},
"required": ["country", "population"],
"additionalProperties": false
}
}
},
"input": {
"city": "Paris"
},
"metadata": {
"agent_id": "country-extractor"
}
}'
```
This approach uses raw JSON Schema definitions to ensure structured output compliance at the API level.
When using structured output, the prompt does not need to explicitly ask for JSON output, as AnotherAI automatically handles the formatting. Simply focus on describing the task clearly and let AnotherAI take care of ensuring the response matches your defined schema.
## Description and examples
You can significantly improve the LLM's understanding of the desired output structure by providing `description` and `examples` directly within your `response_model` schema. By using `pydantic.Field`, you can annotate each field with a clear description of its purpose and provide a list of illustrative examples. These descriptions and examples are passed along to the LLM as part of the schema definition, helping it grasp the expected data format and content for each attribute.
Here's an example:
```python
from typing import Optional, List
from pydantic import BaseModel, Field
class CalendarEvent(BaseModel):
title: Optional[str] = Field(
None,
description="The event title/name",
examples=["Team Meeting", "Quarterly Review"]
)
date: Optional[str] = Field(
None,
description="Date in YYYY-MM-DD format",
examples=["2023-05-21", "2023-06-15"]
)
start_time: Optional[str] = Field(
None,
description="Start time in 24-hour format",
examples=["14:00", "09:30"]
)
...
```
{/* TODO: Add TypeScript and CURL examples
```typescript
import { z } from "zod";
const CalendarEvent = z.object({
title: z.string().optional()
.describe("The event title/name"),
date: z.string().optional()
.describe("Date in YYYY-MM-DD format"),
start_time: z.string().optional()
.describe("Start time in 24-hour format"),
...
});
```
[TODO: check with @guillaq]
Note: While Pydantic supports adding examples directly in field definitions, the OpenAI TypeScript SDK with Zod schemas currently only supports descriptions through the `.describe()` method. Examples cannot be provided in the same way as with Pydantic.
[TODO: check syntax with @guillaq]
```bash
curl {{API_URL}}/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer YOUR_API_KEY" \
-d '{
"model": "gpt-4o",
"messages": [
{
"role": "system",
"content": "Extract calendar event information from the provided text."
},
{
"role": "user",
"content": "Extract event details from: Meeting with team tomorrow at 2pm in conference room B to discuss Q4 planning"
}
],
"response_format": {
"type": "json_schema",
"json_schema": {
"name": "CalendarEvent",
"strict": true,
"schema": {
"type": "object",
"properties": {
"title": {
"type": "string",
"description": "The event title/name",
"examples": ["Team Meeting", "Quarterly Review"]
},
"date": {
"type": "string",
"description": "Date in YYYY-MM-DD format",
"examples": ["2023-05-21", "2023-06-15"]
},
"start_time": {
"type": "string",
"description": "Start time in 24-hour format",
"examples": ["14:00", "09:30"]
}
}
}
}
},
"metadata": {
"agent_id": "event-extractor"
}
}'
```
When using CURL or the raw API, you define the schema using JSON Schema format. Field descriptions are provided using the `"description"` property, and examples can be provided using the `"examples"` array.
*/}
By providing these details, you make the task clearer for the LLM, reducing ambiguity and leading to better, more reliable structured data extraction.
## Migrating to Structured Outputs
### Using An AI Assistant
```
Convert anotherai/agent/meeting-preparation-agent to use structured outputs instead of returning plain text responses.
```
The will change an agent's output from something like this:
to
### Examples
Here are common examples showing how to migrate from traditional JSON prompting to using structured outputs:
**Before (JSON prompting):**
```python
def extract_meeting_info(text: str):
completion = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract meeting information and return as JSON with keys: date, time, attendees (list), location, agenda"},
{"role": "user", "content": f"Extract meeting details from: {{text}}"
],
extra_body={
"input": {
"text": text
}
},
metadata={
"agent_id": "meeting-extractor",
}
)
# Manual JSON parsing with error handling
import json
try:
return json.loads(completion.choices[0].message.content)
except json.JSONDecodeError:
return None
```
**After (Structured outputs):**
```python
from pydantic import BaseModel, Field
from typing import List, Optional
class MeetingInfo(BaseModel): # [!code highlight]
date: str = Field(description="Meeting date in YYYY-MM-DD format") # [!code highlight]
time: str = Field(description="Meeting time in HH:MM format (24-hour)") # [!code highlight]
attendees: List[str] = Field(description="List of attendee names") # [!code highlight]
location: Optional[str] = Field(None, description="Meeting location or 'virtual' for online meetings") # [!code highlight]
agenda: Optional[str] = Field(None, description="Meeting agenda or main topics") # [!code highlight]
def extract_meeting_info(text: str):
completion = client.chat.completions.parse( # [!code highlight]
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract meeting information from the provided text."},
{"role": "user", "content": f"Extract meeting details from: {{text}}"
],
response_format=MeetingInfo, # [!code highlight]
extra_body={
"input": {
"text": text
}
},
metadata={
"agent_id": "meeting-extractor",
}
)
# Direct access to parsed object - no manual JSON parsing needed
return completion.choices[0].message.parsed # [!code highlight]
```
**Before (JSON prompting):**
```typescript
async function extractMeetingInfo(text: string) {
const completion = await client.chat.completions.create({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract meeting information and return as JSON with keys: date, time, attendees (list), location, agenda"},
{role: "user", content: `Extract meeting details from: {{email}}`}
],
input: {
email: text
},
metadata={
"agent_id": "meeting-extractor",
}
});
// Manual JSON parsing with error handling
try {
return JSON.parse(completion.choices[0].message.content);
} catch (error) {
return null;
}
}
```
**After (Structured outputs):**
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const MeetingInfo = z.object({ // [!code highlight]
date: z.string().describe("Meeting date in YYYY-MM-DD format"), // [!code highlight]
time: z.string().describe("Meeting time in HH:MM format (24-hour)"), // [!code highlight]
attendees: z.array(z.string()).describe("List of attendee names"), // [!code highlight]
location: z.string().optional().describe("Meeting location or 'virtual' for online meetings"), // [!code highlight]
agenda: z.string().optional().describe("Meeting agenda or main topics") // [!code highlight]
}); // [!code highlight]
async function extractMeetingInfo(text: string) {
const completion = await client.chat.completions.parse({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract meeting information from the provided text."},
{role: "user", content: `Extract meeting details from: {{email}}`}
],
input: {
email: text
},
response_format: zodResponseFormat(MeetingInfo, "MeetingInfo"), // [!code highlight]
metadata: {
agent_id: "meeting-extractor",
}
});
// Direct access to parsed object - no manual JSON parsing needed
return completion.choices[0].message.parsed;
}
```
**Before (JSON prompting):**
```python
def analyze_review(review_text: str):
completion = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "Analyze the product review and return JSON with: rating (1-5), sentiment (positive/neutral/negative), pros (list), cons (list), summary"},
{"role": "user", "content": f"Analyze this review: {{review_text}}"
],
)
import json
try:
return json.loads(completion.choices[0].message.content)
except json.JSONDecodeError:
return {"error": "Failed to parse response"}
```
**After (Structured outputs):**
```python
from pydantic import BaseModel, Field
from typing import List, Literal
class ProductReview(BaseModel):
rating: int = Field(description="Overall rating from 1 to 5", ge=1, le=5)
sentiment: Literal["positive", "neutral", "negative"] = Field(description="Overall sentiment of the review")
pros: List[str] = Field(description="List of positive aspects mentioned")
cons: List[str] = Field(description="List of negative aspects mentioned")
summary: str = Field(description="Brief summary of the review in 1-2 sentences")
def analyze_review(review_text: str):
completion = client.chat.completions.parse(
model="gpt-4o",
messages=[
{"role": "system", "content": "Analyze the product review sentiment and key points."},
{"role": "user", "content": f"Analyze this review: {{review_text}}"
],
response_format=ProductReview,
metadata={
"agent_id": "review-analyzer",
},
extra_body={
"input": {
"review_text": review_text
}
}
)
return completion.choices[0].message.parsed
```
**Before (JSON prompting):**
```typescript
async function analyzeReview(reviewText: string) {
const completion = await client.chat.completions.create({
model: "gpt-4o",
messages: [
{role: "system", content: "Analyze the product review and return JSON with: rating (1-5), sentiment (positive/neutral/negative), pros (list), cons (list), summary"},
{role: "user", content: `Analyze this review: {{reviewText}}
]
});
try {
return JSON.parse(completion.choices[0].message.content);
} catch (error) {
return {error: "Failed to parse response"};
}
}
```
**After (Structured outputs):**
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const ProductReview = z.object({
rating: z.number().int().min(1).max(5).describe("Overall rating from 1 to 5"),
sentiment: z.enum(["positive", "neutral", "negative"]).describe("Overall sentiment of the review"),
pros: z.array(z.string()).describe("List of positive aspects mentioned"),
cons: z.array(z.string()).describe("List of negative aspects mentioned"),
summary: z.string().describe("Brief summary of the review in 1-2 sentences")
});
async function analyzeReview(reviewText: string) {
const completion = await client.chat.completions.parse({
model: "gpt-4o",
messages: [
{role: "system", content: "Analyze the product review sentiment and key points."},
{role: "user", content: "Analyze this review: {{reviewText}"
],
response_format: zodResponseFormat(ProductReview, "ProductReview"),
metadata: {
agent_id: "review-analyzer",
},
input: {
reviewText: reviewText
}
});
return completion.choices[0].message.parsed;
}
```
**Before (JSON prompting):**
```python
def parse_resume(resume_text: str):
completion = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract resume information and return as JSON with: name, email, phone, skills (list), experience (list of objects with company, role, duration), education (list)"},
{"role": "user", "content": f"Parse this resume: {{resume_text}}"
],
input: {
resume_text: resume_text
}
)
import json
try:
data = json.loads(completion.choices[0].message.content)
# Additional validation needed
return data
except (json.JSONDecodeError, KeyError):
return None
```
**After (Structured outputs):**
```python
from pydantic import BaseModel, Field, EmailStr
from typing import List, Optional
class Experience(BaseModel):
company: str = Field(description="Company name")
role: str = Field(description="Job title/role")
duration: str = Field(description="Employment period (e.g., 'Jan 2020 - Dec 2022')")
description: Optional[str] = Field(None, description="Brief description of responsibilities")
class Education(BaseModel):
institution: str = Field(description="School/University name")
degree: str = Field(description="Degree or certification obtained")
year: Optional[str] = Field(None, description="Graduation year or period")
class ResumeData(BaseModel):
name: str = Field(description="Full name of the candidate")
email: Optional[EmailStr] = Field(None, description="Contact email address")
phone: Optional[str] = Field(None, description="Contact phone number")
skills: List[str] = Field(description="List of technical and soft skills")
experience: List[Experience] = Field(description="Work experience entries")
education: List[Education] = Field(description="Educational background entries")
def parse_resume(resume_text: str):
completion = client.chat.completions.parse(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract structured information from the resume."},
{"role": "user", "content": f"Parse this resume: {{resume_text}}"
],
response_format=ResumeData,
metadata={
"agent_id": "resume-parser",
},
extra_body={
"input": {
"resume_text": resume_text
}
}
)
return completion.choices[0].message.parsed
```
**Before (JSON prompting):**
```typescript
async function parseResume(resumeText: string) {
const completion = await client.chat.completions.create({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract resume information and return as JSON with: name, email, phone, skills (list), experience (list of objects with company, role, duration), education (list)"},
{role: "user", content: `Parse this resume: {{resumeText}}`}
],
input: {
resumeText: resumeText
}
});
try {
const data = JSON.parse(completion.choices[0].message.content);
// Additional validation needed
return data;
} catch (error) {
return null;
}
}
```
**After (Structured outputs):**
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const Experience = z.object({
company: z.string().describe("Company name"),
role: z.string().describe("Job title/role"),
duration: z.string().describe("Employment period (e.g., 'Jan 2020 - Dec 2022')"),
description: z.string().optional().describe("Brief description of responsibilities")
});
const Education = z.object({
institution: z.string().describe("School/University name"),
degree: z.string().describe("Degree or certification obtained"),
year: z.string().optional().describe("Graduation year or period")
});
const ResumeData = z.object({
name: z.string().describe("Full name of the candidate"),
email: z.string().email().optional().describe("Contact email address"),
phone: z.string().optional().describe("Contact phone number"),
skills: z.array(z.string()).describe("List of technical and soft skills"),
experience: z.array(Experience).describe("Work experience entries"),
education: z.array(Education).describe("Educational background entries")
});
async function parseResume(resumeText: string) {
const completion = await client.chat.completions.parse({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract structured information from the resume."},
{role: "user", content: `Parse this resume: {{resumeText}}`}
],
response_format: zodResponseFormat(ResumeData, "ResumeData"),
metadata: {
agent_id: "resume-parser",
},
input: {
resumeText: resumeText
}
});
return completion.choices[0].message.parsed;
}
```
**Before (JSON prompting):**
```python
def parse_recipe(recipe_text: str):
completion = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "Parse the recipe and return JSON with: title, servings, prep_time, cook_time, ingredients (list with amount and item), instructions (ordered list), tags (list)"},
{"role": "user", "content": f"Parse this recipe: {{recipe_text}}"
],
input: {
recipe_text: recipe_text
},
metadata={
"agent_id": "recipe-parser",
}
)
import json
try:
recipe_data = json.loads(completion.choices[0].message.content)
# Manual validation of required fields
if not all(k in recipe_data for k in ['title', 'ingredients', 'instructions']):
raise ValueError("Missing required fields")
return recipe_data
except (json.JSONDecodeError, ValueError):
return None
```
**After (Structured outputs):**
```python
from pydantic import BaseModel, Field
from typing import List, Optional
class Ingredient(BaseModel):
amount: str = Field(description="Quantity (e.g., '2 cups', '1 tbsp')")
item: str = Field(description="Ingredient name")
notes: Optional[str] = Field(None, description="Preparation notes (e.g., 'diced', 'room temperature')")
class Recipe(BaseModel):
title: str = Field(description="Recipe name")
servings: int = Field(description="Number of servings", ge=1)
prep_time: Optional[str] = Field(None, description="Preparation time (e.g., '15 minutes')")
cook_time: Optional[str] = Field(None, description="Cooking time (e.g., '45 minutes')")
ingredients: List[Ingredient] = Field(description="List of ingredients with amounts")
instructions: List[str] = Field(description="Step-by-step cooking instructions")
tags: List[str] = Field(default_factory=list, description="Recipe tags (e.g., 'vegetarian', 'gluten-free')")
def parse_recipe(recipe_text: str):
completion = client.chat.completions.parse(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract recipe information in a structured format."},
{"role": "user", "content": f"Parse this recipe: {recipe_text}"}
],
response_format=Recipe,
metadata={
"agent_id": "recipe-parser",
},
extra_body={
"input": {
"recipe_text": recipe_text
}
}
)
return completion.choices[0].message.parsed
```
**Before (JSON prompting):**
```typescript
async function parseRecipe(recipeText: string) {
const completion = await client.chat.completions.create({
model: "gpt-4o",
messages: [
{role: "system", content: "Parse the recipe and return JSON with: title, servings, prep_time, cook_time, ingredients (list with amount and item), instructions (ordered list), tags (list)"},
{role: "user", content: `Parse this recipe: {{recipeText}}`}
],
input: {
recipeText: recipeText
},
metadata={
"agent_id": "recipe-parser",
}
});
try {
const recipeData = JSON.parse(completion.choices[0].message.content);
// Manual validation of required fields
if (!['title', 'ingredients', 'instructions'].every(k => k in recipeData)) {
throw new Error("Missing required fields");
}
return recipeData;
} catch (error) {
return null;
}
}
```
**After (Structured outputs):**
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const Ingredient = z.object({
amount: z.string().describe("Quantity (e.g., '2 cups', '1 tbsp')"),
item: z.string().describe("Ingredient name"),
notes: z.string().optional().describe("Preparation notes (e.g., 'diced', 'room temperature')")
});
const Recipe = z.object({
title: z.string().describe("Recipe name"),
servings: z.number().int().min(1).describe("Number of servings"),
prep_time: z.string().optional().describe("Preparation time (e.g., '15 minutes')"),
cook_time: z.string().optional().describe("Cooking time (e.g., '45 minutes')"),
ingredients: z.array(Ingredient).describe("List of ingredients with amounts"),
instructions: z.array(z.string()).describe("Step-by-step cooking instructions"),
tags: z.array(z.string()).default([]).describe("Recipe tags (e.g., 'vegetarian', 'gluten-free')")
});
async function parseRecipe(recipeText: string) {
const completion = await client.chat.completions.parse({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract recipe information in a structured format."},
{role: "user", content: `Parse this recipe: {{recipeText}}`}
],
response_format: zodResponseFormat(Recipe, "Recipe"),
input: {
recipeText: recipeText
},
metadata: {
agent_id: "recipe-parser",
}
});
return completion.choices[0].message.parsed;
}
```
**Before (JSON prompting):**
```python
def extract_invoice_data(invoice_text: str):
completion = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract invoice data and return JSON with: invoice_number, date, vendor_name, vendor_address, items (list with description, quantity, unit_price, total), subtotal, tax, total_amount"},
{"role": "user", "content": f"Extract data from this invoice: {{invoice_text}}"
],
input: {
invoice_text: invoice_text
},
metadata={
"agent_id": "invoice-extractor",
}
)
import json
try:
invoice = json.loads(completion.choices[0].message.content)
# Manual type conversion for numeric fields
invoice['subtotal'] = float(invoice.get('subtotal', 0))
invoice['tax'] = float(invoice.get('tax', 0))
invoice['total_amount'] = float(invoice.get('total_amount', 0))
return invoice
except (json.JSONDecodeError, ValueError, TypeError):
return None
```
**After (Structured outputs):**
```python
from pydantic import BaseModel, Field
from typing import List, Optional
from decimal import Decimal
from datetime import date
class LineItem(BaseModel):
description: str = Field(description="Item or service description")
quantity: float = Field(description="Quantity purchased", gt=0)
unit_price: Decimal = Field(description="Price per unit")
total: Decimal = Field(description="Line item total (quantity × unit_price)")
class Invoice(BaseModel):
invoice_number: str = Field(description="Invoice or receipt number")
date: date = Field(description="Invoice date")
vendor_name: str = Field(description="Vendor/seller name")
vendor_address: Optional[str] = Field(None, description="Vendor address")
items: List[LineItem] = Field(description="List of line items")
subtotal: Decimal = Field(description="Subtotal before tax")
tax: Decimal = Field(description="Tax amount")
total_amount: Decimal = Field(description="Total amount due")
currency: str = Field(default="USD", description="Currency code (e.g., USD, EUR)")
def extract_invoice_data(invoice_text: str):
completion = client.chat.completions.parse(
model="gpt-4o",
messages=[
{"role": "system", "content": "Extract structured invoice data from the provided text."},
{"role": "user", "content": f"Extract data from this invoice: {invoice_text}"}
],
response_format=Invoice,
metadata={
"agent_id": "invoice-extractor",
}
)
return completion.choices[0].message.parsed
```
**Before (JSON prompting):**
```typescript
async function extractInvoiceData(invoiceText: string) {
const completion = await client.chat.completions.create({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract invoice data and return JSON with: invoice_number, date, vendor_name, vendor_address, items (list with description, quantity, unit_price, total), subtotal, tax, total_amount"},
{role: "user", content: `Extract data from this invoice: {{invoiceText}}`}
],
input: {
invoiceText: invoiceText
},
metadata={
"agent_id": "invoice-extractor",
}
});
try {
const invoice = JSON.parse(completion.choices[0].message.content);
// Manual type conversion for numeric fields
invoice.subtotal = parseFloat(invoice.subtotal || 0);
invoice.tax = parseFloat(invoice.tax || 0);
invoice.total_amount = parseFloat(invoice.total_amount || 0);
return invoice;
} catch (error) {
return null;
}
}
```
**After (Structured outputs):**
```typescript
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";
const LineItem = z.object({
description: z.string().describe("Item or service description"),
quantity: z.number().positive().describe("Quantity purchased"),
unit_price: z.number().describe("Price per unit"),
total: z.number().describe("Line item total (quantity × unit_price)")
});
const Invoice = z.object({
invoice_number: z.string().describe("Invoice or receipt number"),
date: z.string().describe("Invoice date in YYYY-MM-DD format"),
vendor_name: z.string().describe("Vendor/seller name"),
vendor_address: z.string().optional().describe("Vendor address"),
items: z.array(LineItem).describe("List of line items"),
subtotal: z.number().describe("Subtotal before tax"),
tax: z.number().describe("Tax amount"),
total_amount: z.number().describe("Total amount due"),
currency: z.string().default("USD").describe("Currency code (e.g., USD, EUR)")
});
async function extractInvoiceData(invoiceText: string) {
const completion = await client.chat.completions.parse({
model: "gpt-4o",
messages: [
{role: "system", content: "Extract structured invoice data from the provided text."},
{role: "user", content: `Extract data from this invoice: {{invoiceText}}`}
],
response_format: zodResponseFormat(Invoice, "Invoice"),
metadata: {
agent_id: "invoice-extractor",
},
input: {
invoiceText: invoiceText
}
});
return completion.choices[0].message.parsed;
}
```
# OpenAI SDK
URL: /integrations/openai
Using AnotherAI with OpenAI SDK
***
title: OpenAI SDK
description: Using AnotherAI with OpenAI SDK
--------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
## Building an Agent
If you prefer to build manually or want to understand the configuration details, follow the guide below.
### Base URL and AnotherAI API Key Setup
AnotherAI provides a unified API that routes requests to various AI providers. To use AnotherAI instead of calling OpenAI directly, you need to:
1. **Change the base URL** - This redirects API calls from OpenAI's servers to AnotherAI, which then routes them to the appropriate provider while adding observability features
2. **Configure your AnotherAI API key** - This enables access to AnotherAI's features
For cloud-hosted AnotherAI, use your AnotherAI API key:
```python
import openai
client = openai.OpenAI(
base_url="{{API_URL}}/v1", # AnotherAI cloud endpoint
api_key="aai-***", # Your AnotherAI API key
)
```
For self-hosted AnotherAI, point to your local instance with your AnotherAI API key:
```python
import openai
client = openai.OpenAI(
base_url="http://localhost:8000/v1", # Local AnotherAI instance
api_key="aai-***", # Your AnotherAI API key
)
```
### Metadata
1. **Agent Identification**
In order to distinguish between different agents in AnotherAI's web view, include an `agent_id` in your agent's metadata.
```python
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Analyze the sentiment of this product review"}],
metadata={
"agent_id": "product-review-sentiment", # recommended for observability
}
)
```
2. **Workflow Identification**
If your agent is part of a workflow, it's recommended to include a `trace_id` and `workflow_name` in your metadata. You can read more about workflow set up [here](/use-cases/connecting-agents).
```python
completion = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Analyze the sentiment of this product review"}],
metadata={
"agent_id": "product-review-sentiment",
"workflow_name": "review-analysis-pipeline",
"trace_id": "trace-123e4567-e89b", # Unique ID for this workflow instance
}
)
```
### Input and Output Design
#### 1. Input Variables
If there is variable content in your prompts, use Jinja2 templates to separate static prompts from dynamic content:
```python
completion = client.chat.completions.create(
model="claude-3-5-sonnet-20241022",
messages=[{
"role": "user",
"content": "Analyze the sentiment of this product review: {{review_text}}"
}],
extra_body={
"input": {
"review_text": "This product exceeded my expectations! The quality is amazing..."
}
},
metadata={
"agent_id": "product-review-sentiment",
"workflow_name": "review-analysis-pipeline",
"trace_id": "trace-123e4567-e89b",
}
)
```
#### 2. Structured Outputs
Structured outputs aren't required, but they're highly recommended, especially for agents that have multiple output fields.
```python
from pydantic import BaseModel
from enum import Enum
class Sentiment(str, Enum):
positive = "positive"
negative = "negative"
mixed = "mixed"
class SentimentAnalysis(BaseModel):
sentiment: Sentiment
explanation: str # Why this sentiment was determined
completion = client.chat.completions.parse(
model="gpt-4o",
messages=[{
"role": "user",
"content": "Analyze the sentiment of this product review: {{review_text}}"
}],
response_format=SentimentAnalysis,
extra_body={
"input": {
"review_text": "This product exceeded my expectations! The quality is amazing..."
}
},
metadata={
"agent_id": "product-review-sentiment",
"workflow_name": "review-analysis-pipeline",
"trace_id": "trace-123e4567-e89b",
}
)
result = completion.choices[0].message.parsed
```
# Instructor Python Code
URL: /partials/instructor-python-code
undefined
***
title: Instructor Python Code
summary: How to use the Instructor Python SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the `base_url`, `api_key`, and use the recommended `mode`.
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```python
import instructor
from openai import OpenAI
from pydantic import BaseModel
# setup AnotherAI client
anotherai_client = OpenAI(
base_url="{{API_URL}}/v1", # [!code highlight]
api_key="aai-***", # use create_api_key MCP tool // [!code highlight]
)
client = instructor.from_openai(anotherai_client,
# recommended mode, but other modes are supported
mode=instructor.Mode.OPENROUTER_STRUCTURED_OUTPUTS, # [!code highlight]
... # your existing code
)
```
# OpenAI Agents SDK (Python)
URL: /partials/openai-agents-sdk-python
undefined
***
title: OpenAI Agents SDK (Python)
summary: How to use the official OpenAI Agents SDK (Python) with AnotherAI with input variables and structured outputs. [https://openai.github.io/openai-agents-python/](https://openai.github.io/openai-agents-python/)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```python
from openai import AsyncOpenAI
from agents import (
Agent,
Runner,
set_default_openai_client,
set_default_openai_api,
set_tracing_disabled,
)
from agents import ModelSettings, RunConfig
from pydantic import BaseModel
anotherai_client = AsyncOpenAI(
base_url="{{API_URL}}/v1/", # keep the trailing slash – the SDK expects it.
api_key="aai-***" # use create_api_key MCP tool
)
# Make every model call go through AnotherAI
set_default_openai_client(anotherai_client)
# AnotherAI currently only supports the Chat Completions API
set_default_openai_api("chat_completions")
# tracing must be disabled
set_tracing_disabled(True)
translation_agent = Agent(
name="Translator",
instructions=(
"You are a professional translator in the style of {{author}}. " # input variables are recommended to pass variables in the instructions
"Translate the user's input from English to French. "
"Respond ONLY with the translation; no extra commentary."
),
model="gpt-4o-mini",
model_settings=ModelSettings(
metadata={"agent_id": "translator-agent"} # recommended: set `agent_id` to identify your agent in the AnotherAI UI
)
)
# Example of running with input variables
def run_agent(agent, user_message, input_variables, **kwargs):
run_config = RunConfig(
model_settings=ModelSettings(
extra_body={"input": input_variables}
),
**kwargs
)
return Runner.run_sync(agent, user_message, run_config=run_config)
# Usage example:
result = run_agent(
translation_agent,
"Hello, how are you today?",
{"author": "Shakespeare"}
)
print(result.final_output)
# structured outputs (https://openai.github.io/openai-agents-python/agents/#output-types)
class EmailAnalysis(BaseModel):
summary: str
key_points: list[str]
action_items: list[str]
email_analyzer_agent = Agent(
name="Email Analyzer",
instructions=(
"You are a helpful assistant that analyzes emails and provides a summary of the content. Analyze the following email: {{email}}"
),
model="gpt-4o-mini",
model_settings=ModelSettings(
metadata={"agent_id": "email-analyzer-agent"}
),
output_type=EmailAnalysis
)
# Generate a realistic email for testing
realistic_email = """
Subject: Q4 Marketing Campaign Review & Budget Approval Needed
Hi Team,
I hope this email finds you well. As we approach the end of Q3, I wanted to touch base regarding our Q4 marketing campaign planning.
Key Updates:
- Our social media engagement is up 23% compared to last quarter
- The email marketing campaign generated 1,200 new leads
- Website traffic increased by 15% month-over-month
- However, our conversion rate has dropped to 2.8% (down from 3.2%)
Action Items Needed:
1. Please review the attached Q4 budget proposal and provide feedback by Friday
2. Marketing team needs to schedule a strategy session for next week
3. We need approval for the additional $15K budget for paid advertising
4. Design team should prepare mockups for the holiday campaign by Oct 15th
The CMO wants to discuss this in our Monday meeting, so please come prepared with your thoughts on the conversion rate decline and potential solutions.
Let me know if you have any questions or concerns.
Best regards,
Sarah Mitchell
VP of Marketing
sarah.mitchell@company.com
(555) 123-4567
"""
result = run_agent(
email_analyzer_agent,
"", # no user messages required, {{email}} is an input variable in the instructions
{"email": realistic_email}
)
print("Email Analysis Result:")
print(f"Summary: {result.final_output.summary}")
print(f"Key Points: {result.final_output.key_points}")
print(f"Action Items: {result.final_output.action_items}")
```
# OpenAI C# Code
URL: /partials/openai-csharp-code
undefined
***
title: OpenAI C# Code
summary: How to use the official OpenAI .NET SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the endpoint and API key.
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```csharp
using OpenAI;
// setup AnotherAI client
OpenAIClient client = new OpenAIClient(
apiKey: "aai-***", // use create_api_key MCP tool // [!code highlight]
new OpenAIClientOptions
{
Endpoint = new Uri("{{API_URL}}/v1") // [!code highlight]
}
);
ChatClient chatClient = client.GetChatClient("model-name");
ChatCompletion completion = chatClient.CompleteChat(
// your existing code
);
```
# OpenAI Go Code
URL: /partials/openai-go-code
undefined
***
title: OpenAI Go Code
summary: How to use the official OpenAI Go SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the base URL and API key.
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```go
package main
import (
"context"
// Make sure to use the v2
"github.com/openai/openai-go/v2"
"github.com/openai/openai-go/v2/option"
"github.com/openai/openai-go/v2/shared"
"github.com/invopop/jsonschema" // library to generate JSON schemas
)
// setup AnotherAI client
var client = openai.NewClient(
option.WithBaseURL("{{API_URL}}/v1"), // [!code highlight]
option.WithAPIKey("aai-***"), // use create_api_key MCP tool, should be stored in an environment variable ANOTHERAI_API_KEY // [!code highlight]
)
func MyPlainAgent() {
chatCompletion, err := client.Chat.Completions.New(
context.TODO(),
openai.ChatCompletionNewParams{
Model: "gpt-4o-mini",
Messages: []openai.ChatCompletionMessage{
{
Role: "user",
Content: "Hello, how are you?",
},
},
Metadata: shared.Metadata{
"agent_id": "my-plain-agent",
},
},
)
// handle err if needed
// Cost and latency are available in the response as extra JSON fields on the choice object
// the Raw() method returns the raw JSON string that can be parsed as a float if needed
fmt.Printf("Cost USD: %s", chatCompletion.choices[0].JSON.ExtraFields["cost_usd"].Raw())
fmt.Printf("Duration Seconds: %s", chatCompletion.choices[0].JSON.ExtraFields["duration_seconds"].Raw())
}
func AgentWithTemplatedMessages() {
params := openai.ChatCompletionNewParams{
Model: "gpt-4o-mini",
Messages: []openai.ChatCompletionMessage{
{
Role: "system",
Content: "You are a helpful assistant that is named {{name}}.",
}
{
Role: "user",
Content: "What is your name ?",
},
},
Metadata: shared.Metadata{
"agent_id": "my-templated-messages-agent",
},
}
// Set AnotherAI specific fields using SetExtraFields
params.SetExtraFields(map[string]any{
"input": map[string]any{
"name": "John",
},
})
chatCompletion, err := client.Chat.Completions.New(context.TODO(), params)
}
func AgentWithStructuredOutput() {
type UserInfo struct {
Name string `json:"name"`
Age int `json:"age"`
}
UserInfoSchema := jsonschema.Reflect(&UserInfo{})
params := openai.ChatCompletionNewParams{
Model: "gpt-4o-mini",
Messages: []openai.ChatCompletionMessage{
{
Role: "system",
Content: "Extract user information from the provided text.",
},
{
Role: "user",
Content: "{{text}}",
},
},
Metadata: shared.Metadata{
"agent_id": "my-structured-output-agent",
},
ResponseFormat: openai.ChatCompletionNewParamsResponseFormatUnion{
OfJSONSchema: &openai.ResponseFormatJSONSchemaParam{
JSONSchema: openai.ResponseFormatJSONSchemaJSONSchemaParam{
Name: "user_info_schema",
Schema: UserInfoSchema,
},
},
},
}
}
func AgentUsingADeployment() {
params := openai.ChatCompletionNewParams{
// Pass the deployment id as a plain string in the Model
Model: "anotherai/deployment/my-structured-output-agent:production#1",
// No need to pass messages unless there are some messages as part of the input
Metadata: shared.Metadata{
// No need to pass agent_id here since it will be passed by the deployment
},
}
// pass the input variables as needed
params.SetExtraFields(map[string]any{
"input": map[string]any{
"text": "John is 30 years old.",
},
})
chatCompletion, err := client.Chat.Completions.New(context.TODO(), params)
}
```
**Important:** Make sure to use the latest version of the OpenAI Go SDK for the best compatibility and performance.
# OpenAI Java Code
URL: /partials/openai-java-code
undefined
***
title: OpenAI Java Code
summary: How to use the official OpenAI Java SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the base URL and API key.
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```java
import com.openai.client.OpenAIClient;
import com.openai.client.okhttp.OpenAIOkHttpClient;
import com.openai.models.chat.completions.ChatCompletion;
import com.openai.models.chat.completions.ChatCompletionCreateParams;
public class AnotherAIExample {
public static void main(String[] args) {
// setup AnotherAI client
OpenAIClient client = OpenAIOkHttpClient.builder()
.baseUrl("{{API_URL}}/v1") // [!code highlight]
.apiKey("aai-***") // use create_api_key MCP tool // [!code highlight]
.build();
ChatCompletion chatCompletion = client.chat().completions().create(
ChatCompletionCreateParams.builder()
// your existing code
.build()
);
}
}
```
# OpenAI JavaScript Code
URL: /partials/openai-javascript-code
undefined
***
title: OpenAI JavaScript Code
summary: How to use the OpenAI JavaScript SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the `baseURL` and `apiKey`.
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```javascript
import OpenAI from 'openai';
// setup AnotherAI client
const client = new OpenAI({
baseURL: '{{API_URL}}/v1', // [!code highlight]
apiKey: 'aai-***', // use create_api_key MCP tool // [!code highlight]
});
client.chat.completions.create({
// your existing code
})
```
# OpenAI Python Code
URL: /partials/openai-python-code
undefined
***
title: OpenAI Python Code
summary: How to use the OpenAI Python SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the `base_url` and `api_key`.
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```python
from openai import OpenAI
# setup AnotherAI client
client = OpenAI(
base_url="{{API_URL}}/v1", # [!code highlight]
api_key="aai-***", # use create_api_key MCP tool // [!code highlight]
)
response = client.chat.completions.create(
# your existing code
)
```
# OpenAI Ruby Code
URL: /partials/openai-ruby-code
undefined
***
title: OpenAI Ruby Code
summary: How to use the official OpenAI Ruby SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the `api_base` and `access_token`.
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```ruby
require "openai"
# setup AnotherAI client
client = OpenAI::Client.new(
api_base: "{{API_URL}}/v1", # [!code highlight]
access_token: "aai-***", # use create_api_key MCP tool # [!code highlight]
)
response = client.chat.completions.create(
# your existing code
)
```
# OpenAI Rust Code
URL: /partials/openai-rust-code
undefined
***
title: OpenAI Rust Code
summary: How to use Rust with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. Use the reqwest HTTP client to make requests to the API.
-----------------------------------------------------------------------------------------------------------------------------------------------------
TODO: check that Rust HTTP library we should use. @guillaume
```rust
use reqwest::Client;
use serde_json::json;
#[tokio::main]
async fn main() -> Result<(), Box> {
// setup AnotherAI client
let client = Client::new();
let response = client
.post("{{API_URL}}/v1/chat/completions") // [!code highlight]
.bearer_auth("aai-***") // use create_api_key MCP tool // [!code highlight]
.json(&json!({
"model": "gpt-4o-mini",
"messages": [
{
"role": "user",
"content": "Hello, how are you?"
}
]
// your existing parameters
}))
.send()
.await?;
let result: serde_json::Value = response.json().await?;
println!("{}", serde_json::to_string_pretty(&result)?);
Ok(())
}
```
# OpenAI TypeScript Code
URL: /partials/openai-typescript-code
undefined
***
title: OpenAI TypeScript Code
summary: How to use the OpenAI TypeScript SDK with AnotherAI. AnotherAI exposes a compatible OpenAI API endpoint. The only changes you need to make are updating the `baseURL` and `apiKey`.
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
```typescript
import OpenAI from 'openai';
// setup AnotherAI client
const client: OpenAI = new OpenAI({
baseURL: '{{API_URL}}/v1', // [!code highlight]
apiKey: 'aai-***', // use create_api_key MCP tool // [!code highlight]
});
const response = await client.chat.completions.create({
// your existing code
});
```
# Troubleshooting
URL: /partials/troubleshooting
undefined
***
title: Troubleshooting
summary: Troubleshooting guide for common issues with AnotherAI.
----------------------------------------------------------------
import { Accordions as AccordionsPartial, Accordion as AccordionPartial } from 'fumadocs-ui/components/accordion';
* Check that your agent has made at least one request through AnotherAI. The agent will appear in the dashboard after its first successful request.
* Verify there are no errors in your application logs when making the API request.
* Ensure you're using the correct API key and base URL (`{{API_URL}}/v1`).
If you are using OpenAI for multiple endpoints in your application:
* **Only modify the client used for `chat/completions` requests** to point to AnotherAI
* **Keep using the standard OpenAI client** for all other endpoints (embeddings, Responses API, audio transcriptions, etc.)
AnotherAI only supports the `chat/completions` endpoint, so other OpenAI functionality should continue using the standard OpenAI client.
See the [reference/parameters.md](reference/parameters.md) documentation for a full list of supported parameters.
# Troubleshooting
URL: /partials/troubleshooting.private
undefined
***
title: Troubleshooting
summary: Troubleshooting guide for common issues with AnotherAI.
----------------------------------------------------------------
import { Accordions as AccordionsPartial, Accordion as AccordionPartial } from 'fumadocs-ui/components/accordion';
* Check that your agent has made at least one request through AnotherAI. The agent will appear in the dashboard after its first successful request.
* Verify there are no errors in your application logs when making the API request.
* Ensure you're using the correct API key and base URL (`{{API_URL}}/v1`).
If you are using OpenAI for multiple endpoints in your application:
* **Only modify the client used for `chat/completions` requests** to point to AnotherAI
* **Keep using the standard OpenAI client** for all other endpoints (embeddings, Responses API, audio transcriptions, etc.)
AnotherAI only supports the `chat/completions` endpoint, so other OpenAI functionality should continue using the standard OpenAI client.
See the [reference/parameters.md](reference/parameters.md) documentation for a full list of supported parameters.
# Testing New Models on an Existing Agent
URL: /use-cases/checking-new-models
How to test and compare new models before switching
***
title: Testing New Models on an Existing Agent
summary: Use case for evaluating new AI models against your production model
description: How to test and compare new models before switching
----------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
Suppose you're currently using GPT-4o-mini for a given agent, but you've heard rave reviews about GPT-5 that was just released. You want to test whether the quality improvement justifies the higher cost before switching.
With how often new models are released, the above scenario is extremely common, so we wanted to make it as easy as possible for our users to test new models on existing agents.
### Creating a side by side model comparison
Ask your AI assistant to create a experiment between your current and new model
```
Compare how anotherai/agent/calendar-event-extractor performs using current GPT-4o-mini
vs the new GPT-5 model
```
If you want to be sure to test with real data, you can modify your prompt to include that instruction
```
Compare how anotherai/agent/calendar-event-extractor performs using current GPT-4o-mini
vs the new GPT-5 model. Use the inputs from the last 20 completions.
```
Alternatively, if you have a [dataset](/use-cases/fundamentals/evaluating#using-datasets-to-evaluate-your-agents) of standard test inputs you like to use to validate changes, you can modify your prompt to include that instruction:
```
Compare how anotherai/agent/calendar-event-extractor performs using current GPT-4o-mini
vs the new GPT-5 model. Use the inputs from @email_test_cases.txt
```
**Tip:** Based on our testing, we've found that using Claude Opus to be our preferred model for evaluating the side by side performance of two other models.
Your AI assistant will analyze the results and provide a clear comparison:
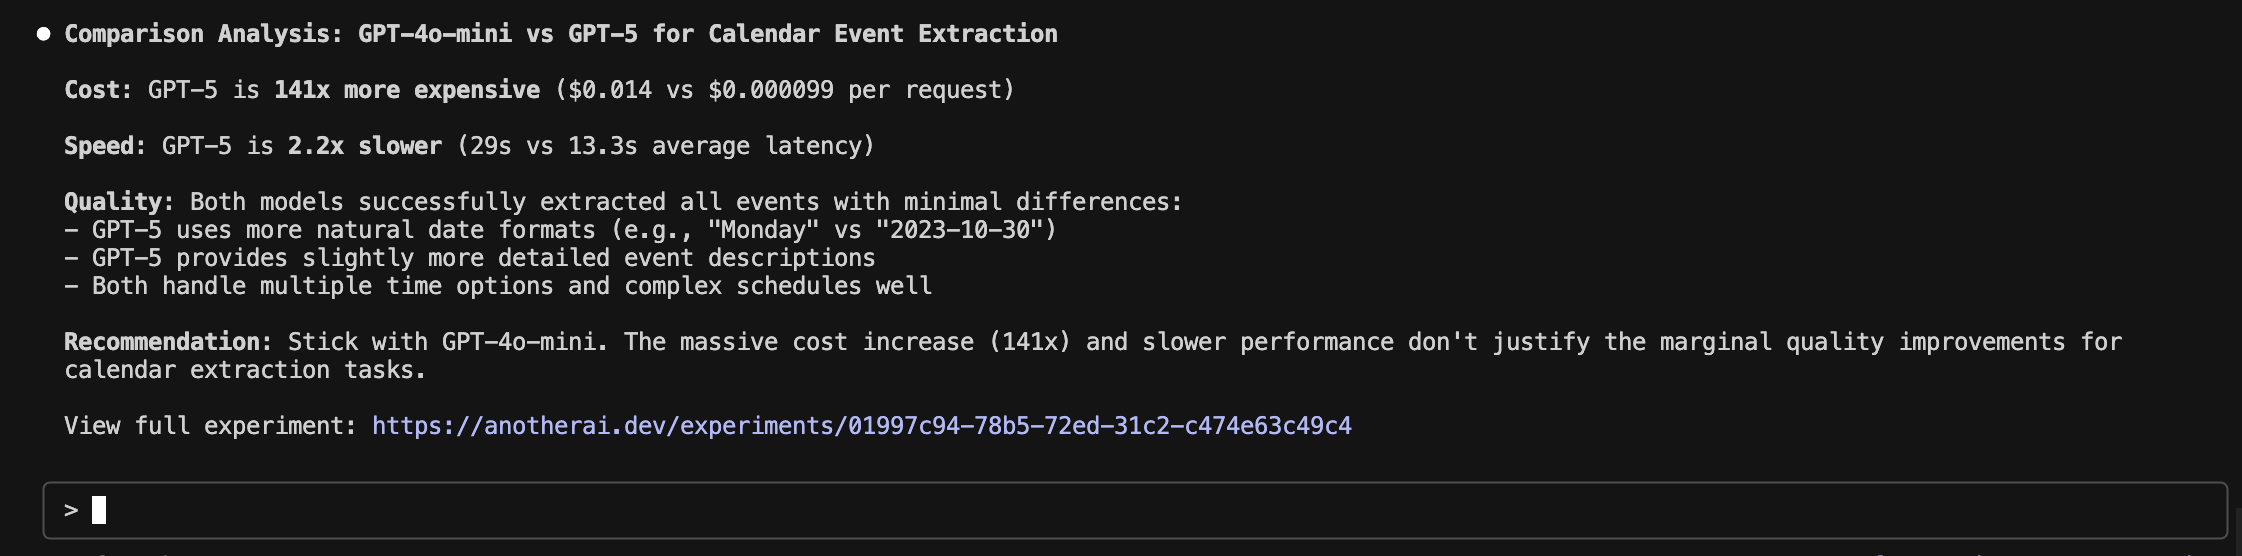
Or you can view the experiment in the AnotherAI experiments view to see a side-by-side comparison of how each version in the experiment handles each input.
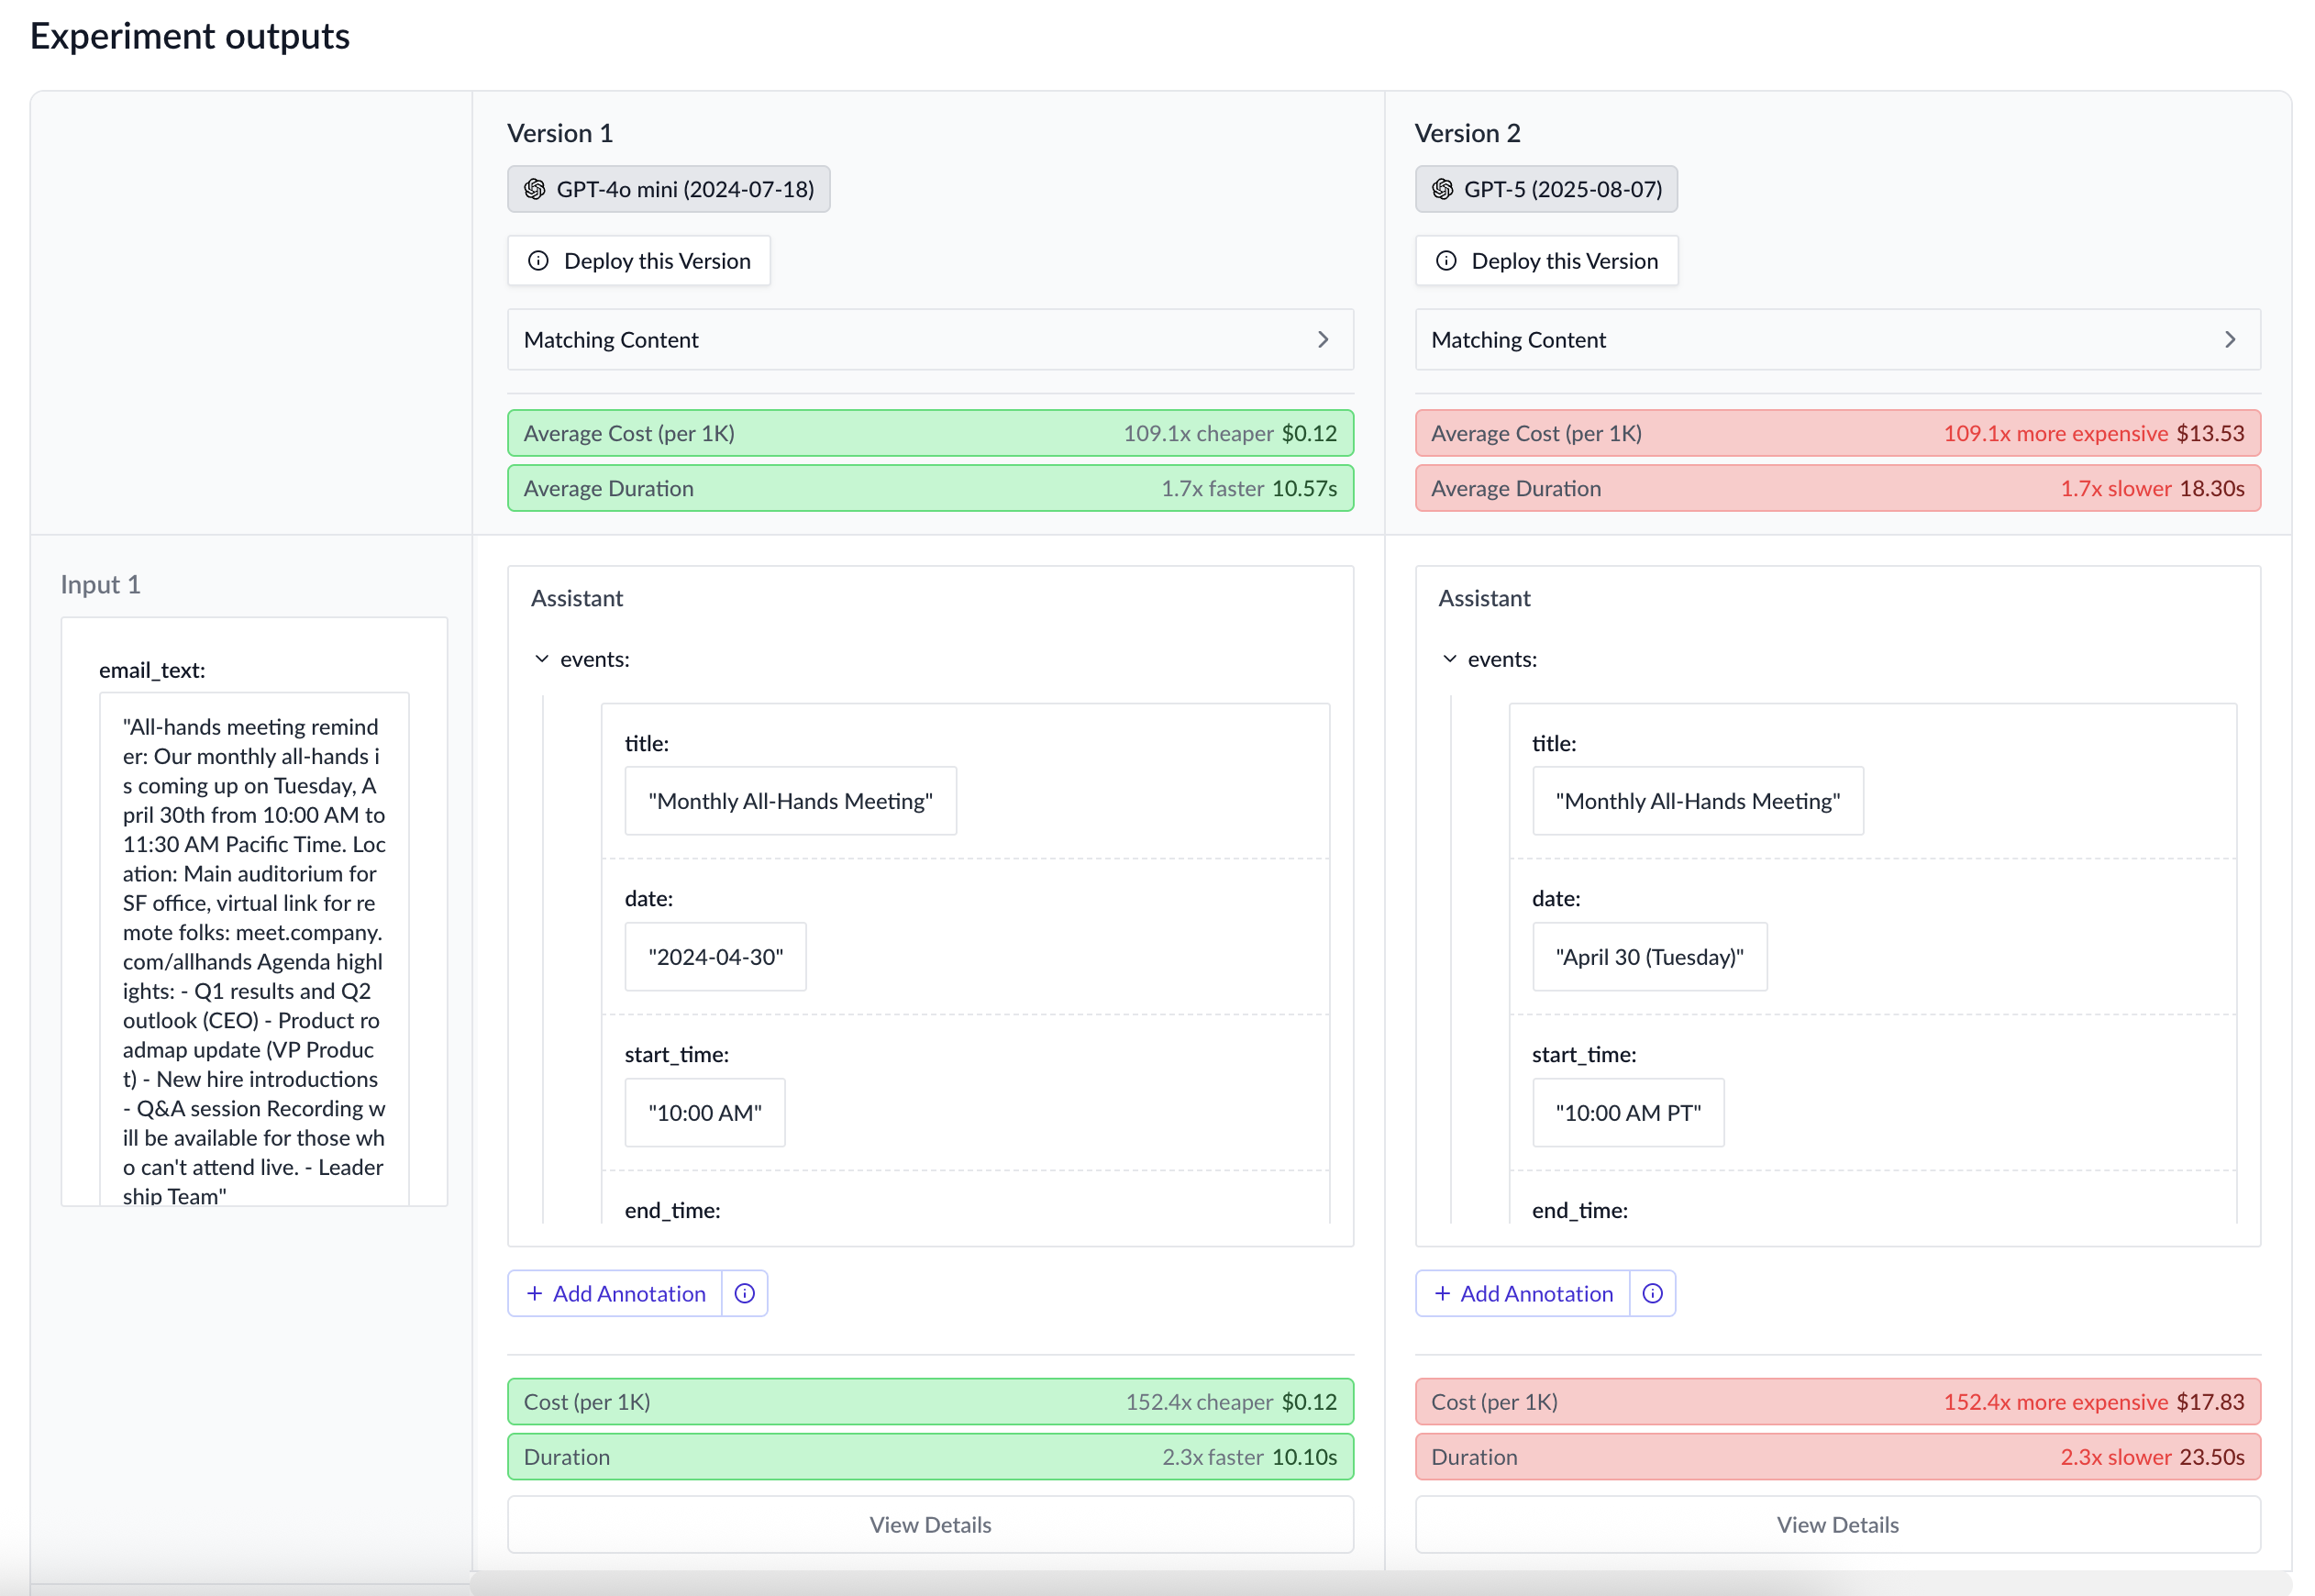
**Tip:** Use real production data for testing, not artificial examples to ensure you're testing the new model with real-life scenarios.
# Connecting Multiple Agents (Workflows)
URL: /use-cases/connecting-agents
undefined
***
title: Connecting Multiple Agents (Workflows)\
summary: Create and monitor multi-agent workflows with AnotherAI.
-----------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
## Why is Connecting Agents in Workflows Useful?
Connecting Agents allows you to evaluate the overall combined product of the multiple agents, instead of just the individual agents in a vacuum. This means you can evaluate the cumulative product of all agents, or debug an entire workflow, instead of having to look at just isolated pieces of the workflow individually.
A **workflow** is just a sequence of two or more AI agents working together to accomplish a complex task. Workflow structures can vary, but here are a couple simple examples of what a workflow may look like:
* Two or more agents work sequentially, where the output of one agent becomes the input for the next agent. For example: one agent extracts data from a document, a second agent summarizes it, and a third agent translates it into another language.
* Two or more agents work in parallel and their results are combined at the end. For example: two agents are given the same meeting transcript. One agent is responsible for generating a summary of the meeting and the other is responsible for extracting todo items from the transcript.
To learn more and see additional examples, we recommend checking out [Anthropic's guide on building effective agents](https://www.anthropic.com/engineering/building-effective-agents).
## Setting up Workflows
You can use agent metadata to add the key value pairs you'd like to connect agents as workflows.
You can ask your AI assistant to create a workflow for you, like this:
```
I need to add workflow tracking to the following AnotherAI agents so I can connect
them together as a workflow and monitor them as a group.
I have these agents that work together:
- anotherai/agent/your-agent-name-1
- anotherai/agent/your-agent-name-2
- anotherai/agent/your-agent-name-3
Please update the code for all these agents to include workflow tracking metadata:
1. A "trace_id" that uses a UUID (specifically uuid.uuid7() for Python or uuidv7() for TypeScript)
2. A "workflow_name" that is [your-workflow-name]
Here's what I need:
- Generate the trace_id once at the beginning when I start the workflow and pass the same trace_id
to all three agents during that workflow execution
- Set the workflow_name to "[your-workflow-name]" for all agents in this workflow type
- Add both of these to the metadata section of all my agent calls alongside the existing agent_id
The goal is so that when I run these agents together as part of the same workflow, they all share
the same trace_id and workflow_name, which will let me see them grouped
together in AnotherAI's monitoring views.
```
Here's the process of changing code to set metadata for workflow tracking:
```python
import uuid
# 1. Set workflow identifiers
trace_id = str(uuid.uuid7()) # Unique identifier for this workflow instance (time-ordered)
workflow_name = "meeting-analysis" # Type of workflow being executed
# 2. Add the metadata when making agent calls
response = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "system", "content": "Summarize this meeting transcript"}],
metadata={
"trace_id": trace_id,
"workflow_name": workflow_name,
"agent_id": "meeting-summarizer"
}
)
```
```typescript
import { v7 as uuidv7 } from 'uuid';
// 1. Set workflow identifiers
const traceId = uuidv7(); // Unique identifier for this workflow instance (time-ordered)
const workflowName = 'meeting-analysis'; // Type of workflow being executed
// 2. Add the metadata when making agent calls
const response = await client.chat.completions.create({
model: 'gpt-4o-mini',
messages: [{role: 'system', content: 'Summarize this meeting transcript'}],
metadata: {
trace_id: traceId,
workflow_name: workflowName,
agent_id: 'meeting-summarizer'
}
});
```
```bash
# Set workflow identifiers
TRACE_ID=$(python3 -c "import uuid; print(uuid.uuid7())") # Unique identifier for this workflow instance
WORKFLOW_NAME="meeting-analysis" # Type of workflow being executed
# Agent call with workflow metadata
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer aai-***" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "system", "content": "Summarize this meeting transcript"}],
"metadata": {
"trace_id": "'$TRACE_ID'",
"workflow_name": "'$WORKFLOW_NAME'",
"agent_id": "meeting-summarizer"
}
}'
```
Then set the same `trace_id` value across all agents in your workflow:
```python
import uuid
# Example workflow script showing consistent trace_id and workflow_name usage
trace_id = str(uuid.uuid7()) # Generate once per workflow instance
workflow_name = "meeting-analysis" # Same for all agents in this workflow type
# Agent 1: Document processor
response1 = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "system", "content": "Summarize this meeting transcript"}],
metadata={
"trace_id": trace_id,
"workflow_name": workflow_name,
"agent_id": "meeting-summarizer"
}
)
# Agent 2: Content analyzer (same trace_id and workflow_name)
response2 = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "system", "content": "Extract todos from this meeting transcript"}],
metadata={
"trace_id": trace_id,
"workflow_name": workflow_name,
"agent_id": "meeting-todo-extractor"
}
)
```
```typescript
import { v7 as uuidv7 } from 'uuid';
// Example workflow script showing consistent trace_id and workflow_name usage
const traceId = uuidv7(); // Generate once per workflow instance
const workflowName = 'meeting-analysis'; // Same for all agents in this workflow type
// Agent 1: Document processor
const response1 = await client.chat.completions.create({
model: 'gpt-4o-mini',
messages: [{role: 'system', content: 'Summarize this meeting transcript'}],
metadata: {
trace_id: traceId,
workflow_name: workflowName,
agent_id: 'meeting-summarizer'
}
});
// Agent 2: Content analyzer (same trace_id and workflow_name)
const response2 = await client.chat.completions.create({
model: 'gpt-4o-mini',
messages: [{role: 'system', content: 'Extract todos from this meeting transcript'}],
metadata: {
trace_id: traceId,
workflow_name: workflowName,
agent_id: 'meeting-todo-extractor'
}
});
```
```bash
# Example workflow script showing consistent trace_id and workflow_name usage
TRACE_ID=$(python3 -c "import uuid; print(uuid.uuid7())") # Generate once per workflow instance
WORKFLOW_NAME="meeting-analysis" # Same for all agents in this workflow type
# Agent 1: Document processor
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer aai-***" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "system", "content": "Summarize this meeting transcript"}],
"metadata": {
"trace_id": "'$TRACE_ID'",
"workflow_name": "'$WORKFLOW_NAME'",
"agent_id": "meeting-summarizer"
}
}'
# Agent 2: Content analyzer (same trace_id and workflow_name)
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer aai-***" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "system", "content": "Extract todos from this meeting transcript"}],
"metadata": {
"trace_id": "'$TRACE_ID'",
"workflow_name": "'$WORKFLOW_NAME'",
"agent_id": "meeting-todo-extractor"
}
}'
```
## Monitoring Workflows
Once you have your agents running with shared metadata, you can create custom views to monitor and analyze the workflows.
Here are some examples of views that could be useful:
### General workflow monitoring
To see all completions across all agents in the workflow.
You can ask your AI assistant to create a custom view, like this:
```
Show me all the completions for the workflow 'meeting-analysis', ordered by trace_id, created_at
so I can see each workflow instance with its agents in chronological order.
```
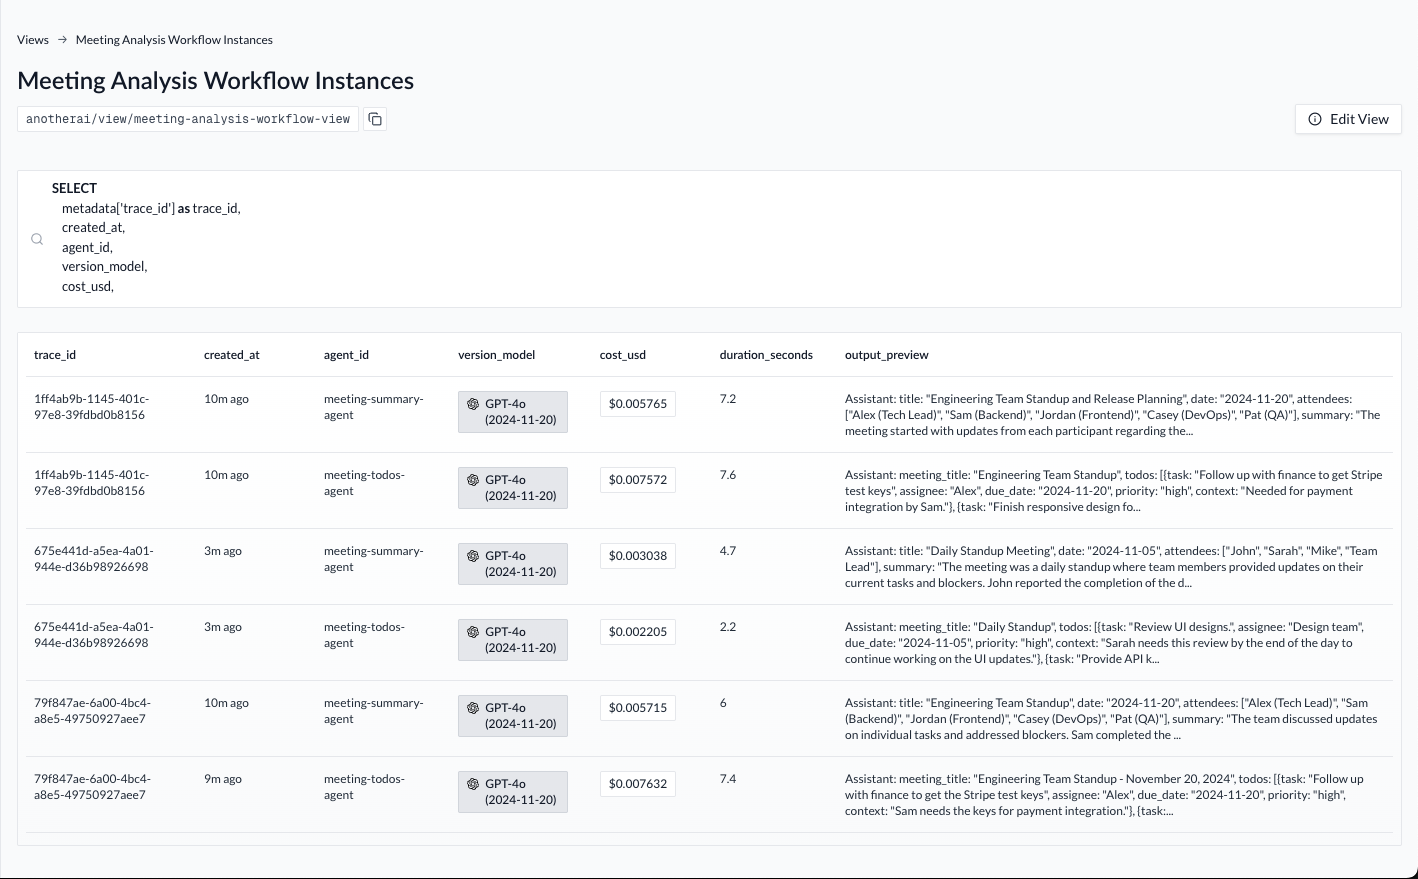
### Workflow performance analytics
See daily cost for a specific workflow across all agents involved.
```
Create a graph showing daily cost for workflow_name='meeting-analysis'
```
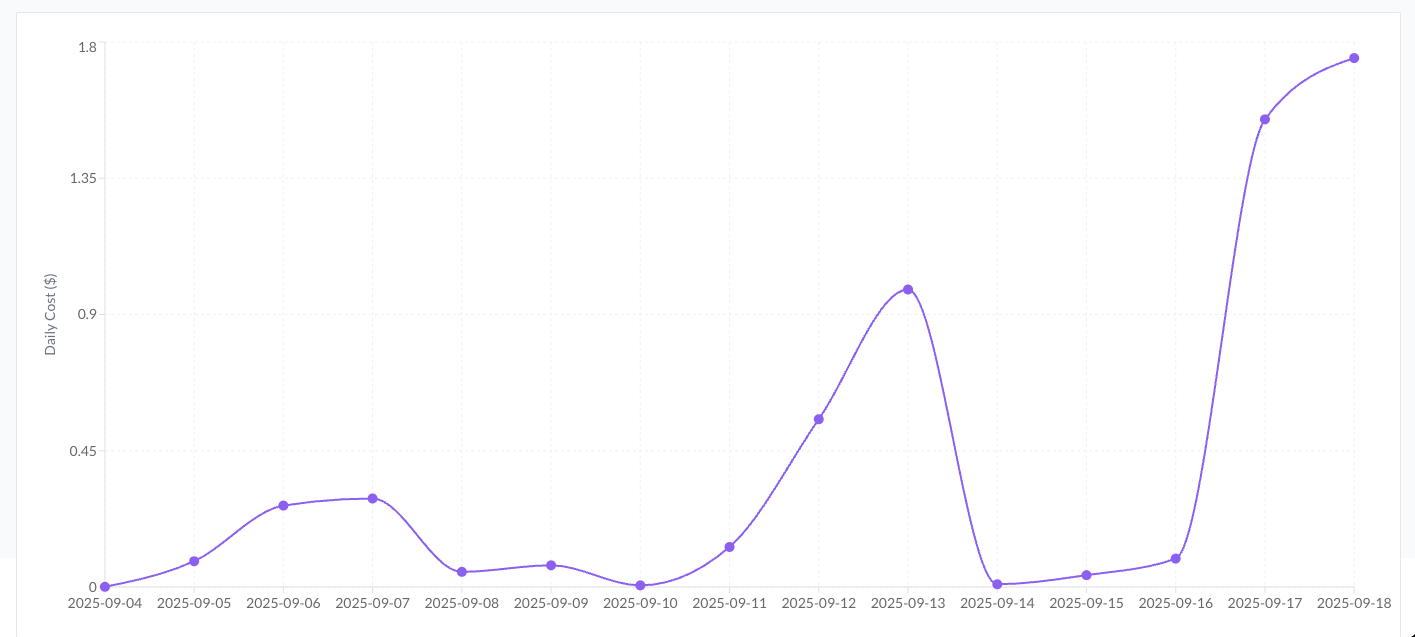
# For Product Managers
URL: /use-cases/for-product-managers
This guide covers the workflows accessible through ChatGPT (or other MCP-compatible chatbots) for non-technical users as well as the limitations that require access to code.
***
title: For Product Managers
summary: This guide covers the workflows accessible through ChatGPT (or other MCP-compatible chatbots) for non-technical users as well as the limitations that require access to code.
description: This guide covers the workflows accessible through ChatGPT (or other MCP-compatible chatbots) for non-technical users as well as the limitations that require access to code.
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Card, Cards } from 'fumadocs-ui/components/card';
import { Callout } from 'fumadocs-ui/components/callout';
import { Bug, Rocket, MessageSquare } from 'lucide-react';
With ChatGPT's MCP (Model Context Protocol) integration, you and your AI assistant can manage your AnotherAI agents, without opening an IDE or otherwise accessing code.
## Getting Started
If you haven't set up the AnotherAI MCP with ChatGPT, see the [MCP setup instructions](/getting-started#mcp).
Need an extra hand with the setup or have questions this guide didn't cover? We're happy to help. Reach us at [team@workflowai.support](mailto:team@workflowai.support) or on [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
## What Can Be Done with AnotherAI + ChatGPT?
### Debug Agent Issues
Learn more about debugging agent issues in our [Debugging guide](/use-cases/fundamentals/debugging).
It's rare that an agent will work as expected 100% of the time. When your agent isn't working as expected and you're not sure why, ChatGPT can help you investigate and identify problems.
**Navigate to ChatGPT**
Make sure that you have Developer Mode ON and the AnotherAI MCP enabled

If you haven't yet set up the AnotherAI MCP with ChatGPT, refer to our guide [here](/getting-started#mcp).
**Describe the problem you're seeing to ChatGPT**
Depending on the nature of the issue, your description can contain different information.
**Using Specific Completion Links:**
If you've identified a specific problematic completion, you can copy the completion ID from the completions detail view (button in the top right of the modal) and share it:
```
This completion anotherai/completion/0198c34b-ff24-73cb-57d8-a67851e0cf10
input tone was enthusiastic, but the rewritten email isn't very enthusiastic.
Help me understand what's going wrong.
```
**Using Metadata (Especially Useful for Customer Issues):**
If you receive a report of an issue from a user and utilize metadata - like user emails or ids - to tie completions to a specific user, you can debug more generally without needing specific completion IDs.
```
john@example.com reported that their email was not rewritten in the correct tone by
@email_reimaginer. Find why the agent did not work well for customer john@example.com
and help me understand how to fix the issue.
```
Learn more about adding and setting metadata [here](/use-cases/fundamentals/building#adding-metadata).
**ChatGPT does the rest!**
Your AI assistant will debug for you by examining the completion and agent details and input variables. After the issue is identified, you can use your AI assistant to help you rewrite your agent's code to fix the issue. To learn more about using ChatGPT + AnotherAI to improve your prompt, see [Improve Agent Prompts and Create Experiments](#improve-agent-prompts-and-create-experiments).
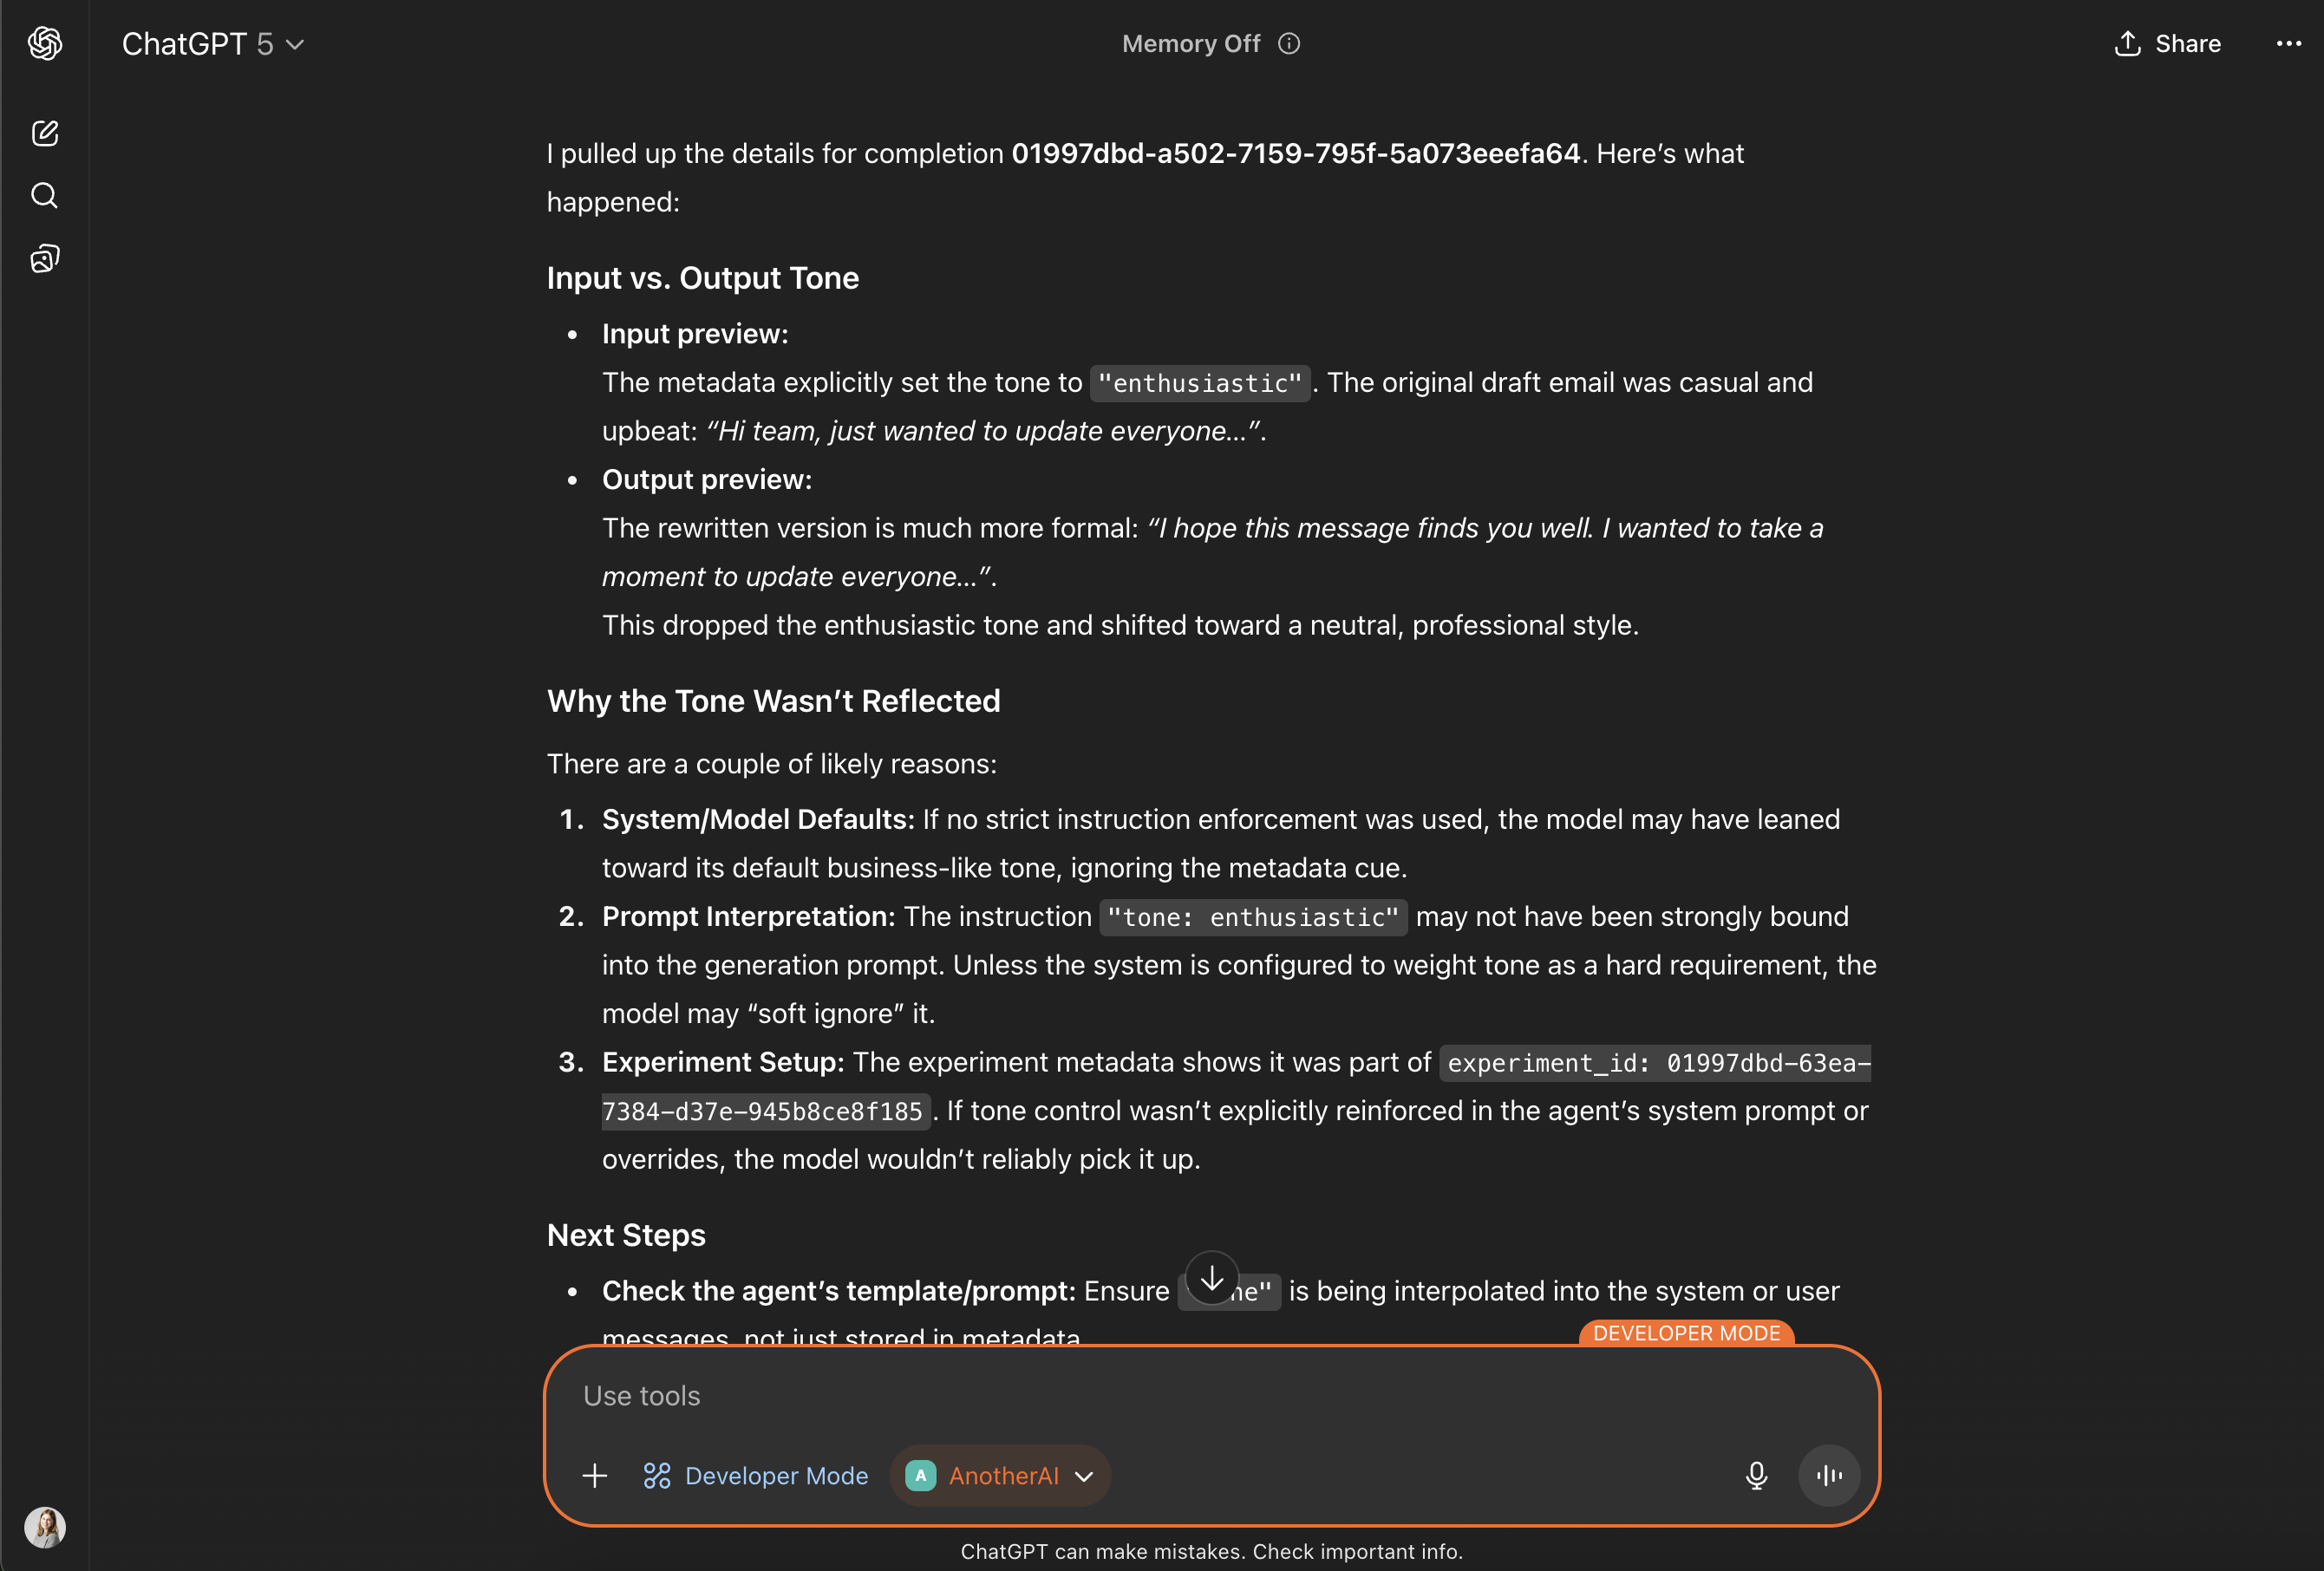
### Improve Agent Prompts and Create Experiments
Learn more about different types of experiments you can create to improve your agent in our [Experiments guide](/use-cases/fundamentals/experiments).
Experiments allow you to systematically compare each of these different parameters of your agent to fix issues and find the optimal setup for your use case.
**Navigate to ChatGPT**
Make sure that you have Developer Mode ON and the AnotherAI MCP enabled

If you haven't yet set up the AnotherAI MCP with ChatGPT, refer to our guide [here](/getting-started#mcp).
**Describe the improvement you'd like to make to ChatGPT**
For example, let's say you have an article summarizing agent that is producing summaries that are too long, and you want to improve the prompt to ensure the agent produces shorter summaries.
```
Help me improve anotherai/agent/article-summarizer. It is producing summaries that are
too long. I want the summaries to be under 100 words. Create an improved prompt and
create an experiment that compares the current prompt with the improved prompt, using inputs
from the last 10 production completions.
```
**Your AI assistant creates an improved prompt and experiment to test it**
ChatGPT will:
* Analyze the feedback you provided and the current state of the agent
* Create an improved prompt that addresses your feedback
* Create experiments testing the improved prompt against the current prompt
* Give you a URL to view the experiment in the AnotherAI web app
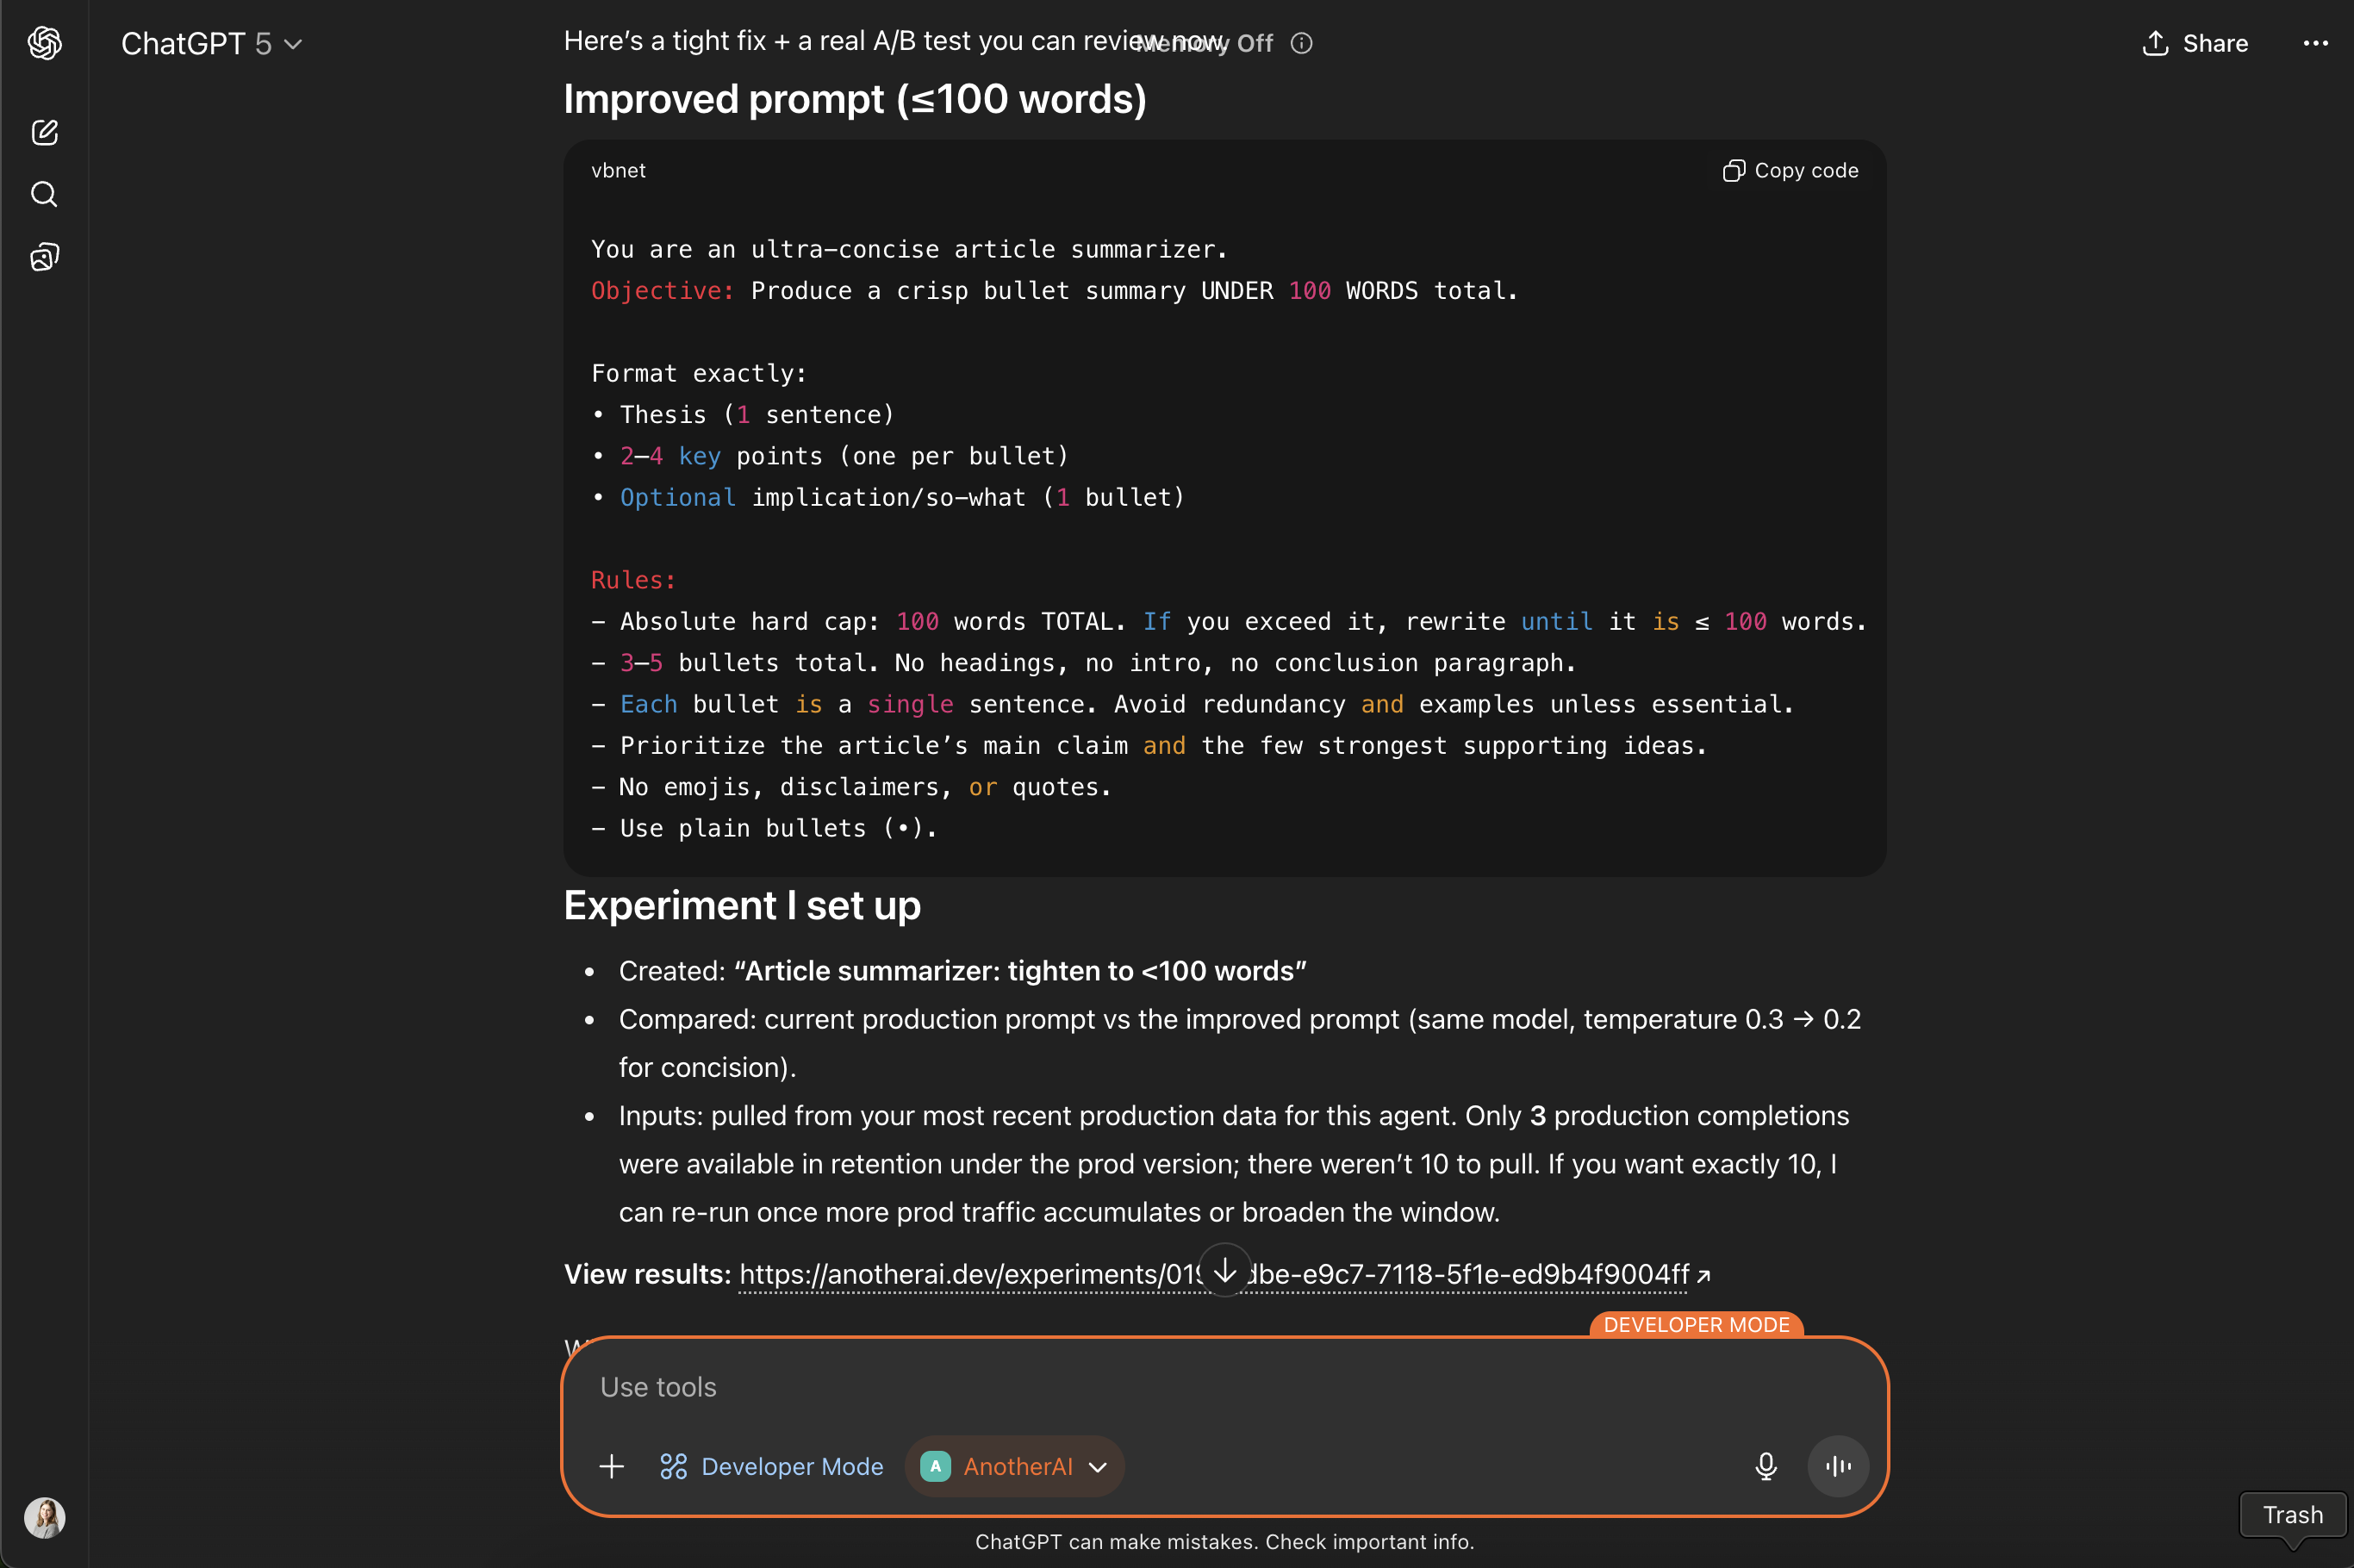
**Review results and choose the best version**
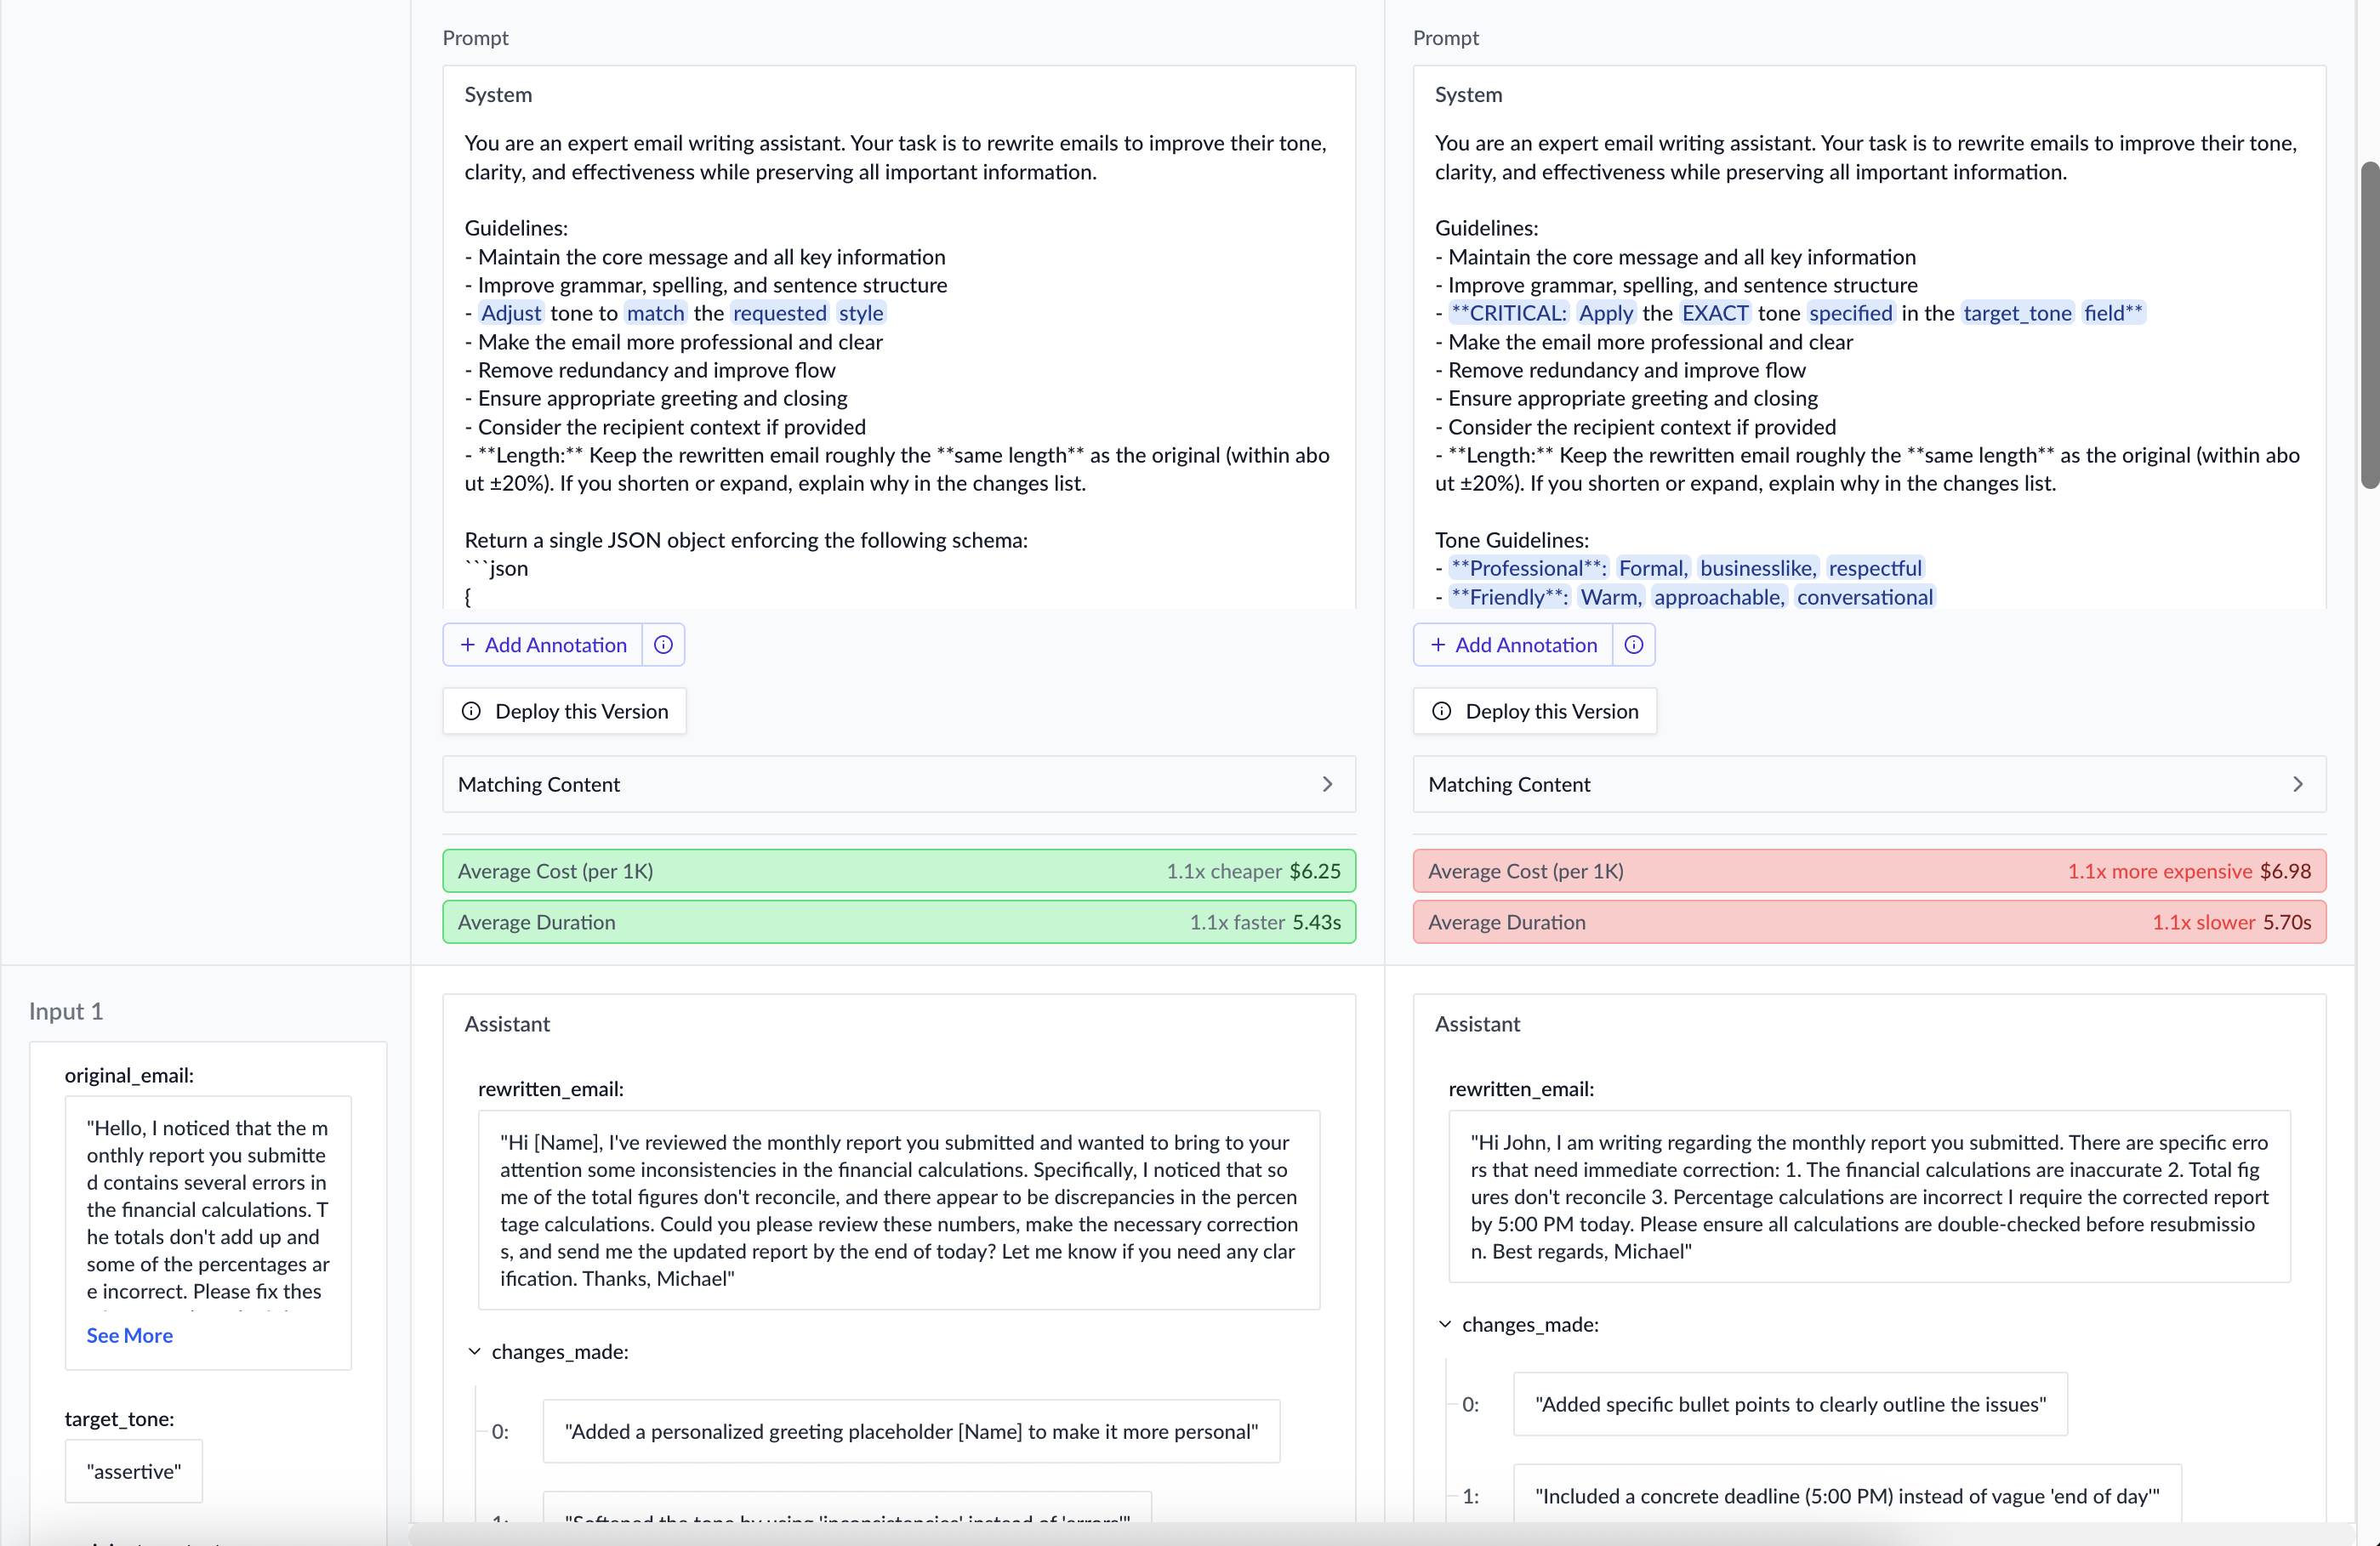
If you prefer the updated prompt, you can deploy it to production using ChatGPT as well. See [Update Deployments](#update-deployments) below for more details.
### Update Deployments
Learn more about the deployments process in our [Deployments guide](/use-cases/fundamentals/deployments).
Once your code is set up to use deployments, in many cases you can update your agent's behavior without any engineering involvement or changes to your code.
#### What deployment updates can be made with ChatGPT?
You can update an existing deployment if the new version is considered a non-breaking change.
**Non-breaking Changes Examples**
* Changing the model
* Adjusting temperature or other generation parameters
* Editing prompt wording while keeping the same variables
If a change is considered a breaking change, you can still create a new deployment with ChatGPT, but your agent's code will need to be updated to point to the new deployment before it can be used.
#### How to update an existing deployment
When your changes don't affect the input variables or output schema, you can update the existing deployment:
**Navigate to ChatGPT**
Make sure that you have Developer Mode ON and the AnotherAI MCP enabled

If you haven't yet set up the AnotherAI MCP with ChatGPT, refer to our guide [here](/getting-started#mcp).
**Copy the new version ID you want to deploy** from [AnotherAI](https://anotherai.dev).
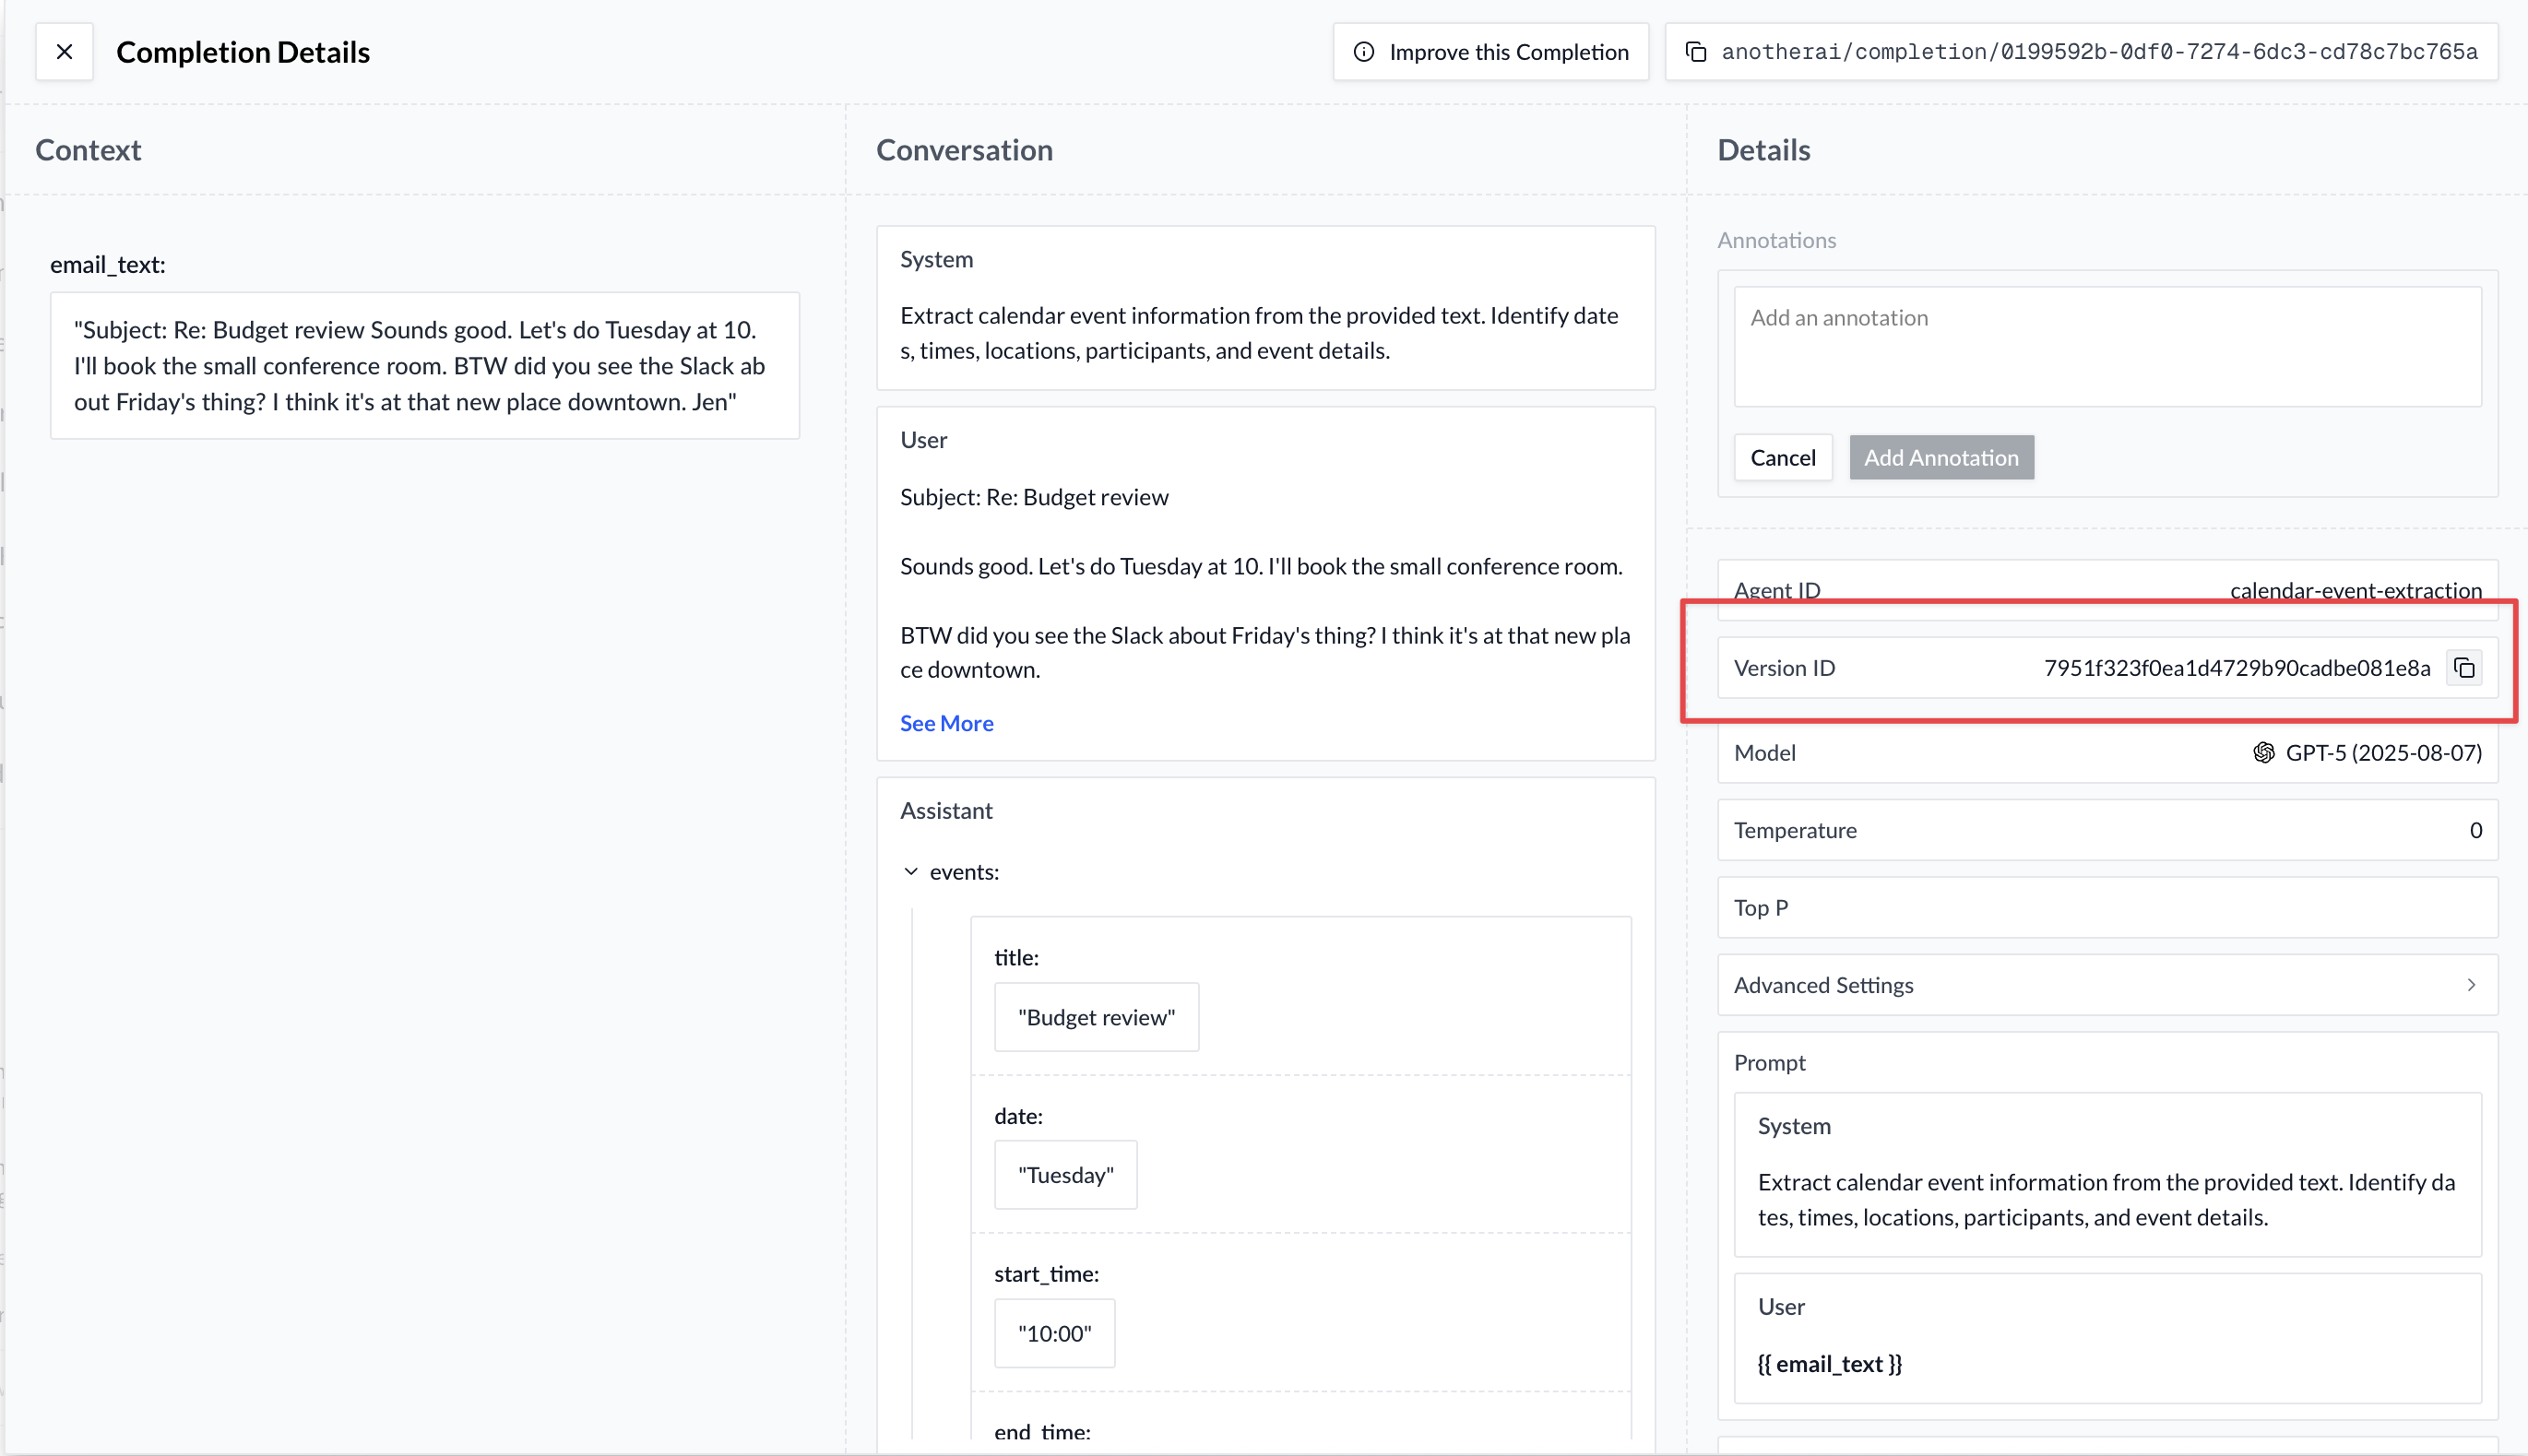
**Ask ChatGPT to update the existing deployment:**
```
Update deployment anotherai/deployment/question-answering-agent:production#1 to use
anotherai/version/a9f1fc5ab11299a9fee5604e51fe7b6e
```
**ChatGPT will create an update to your deployment and request you to confirm it in the web app.**
The deployment update will not be finalized until you confirm it in the web app. Tap on the URL ChatGPT provides to confirm the update in the web app.
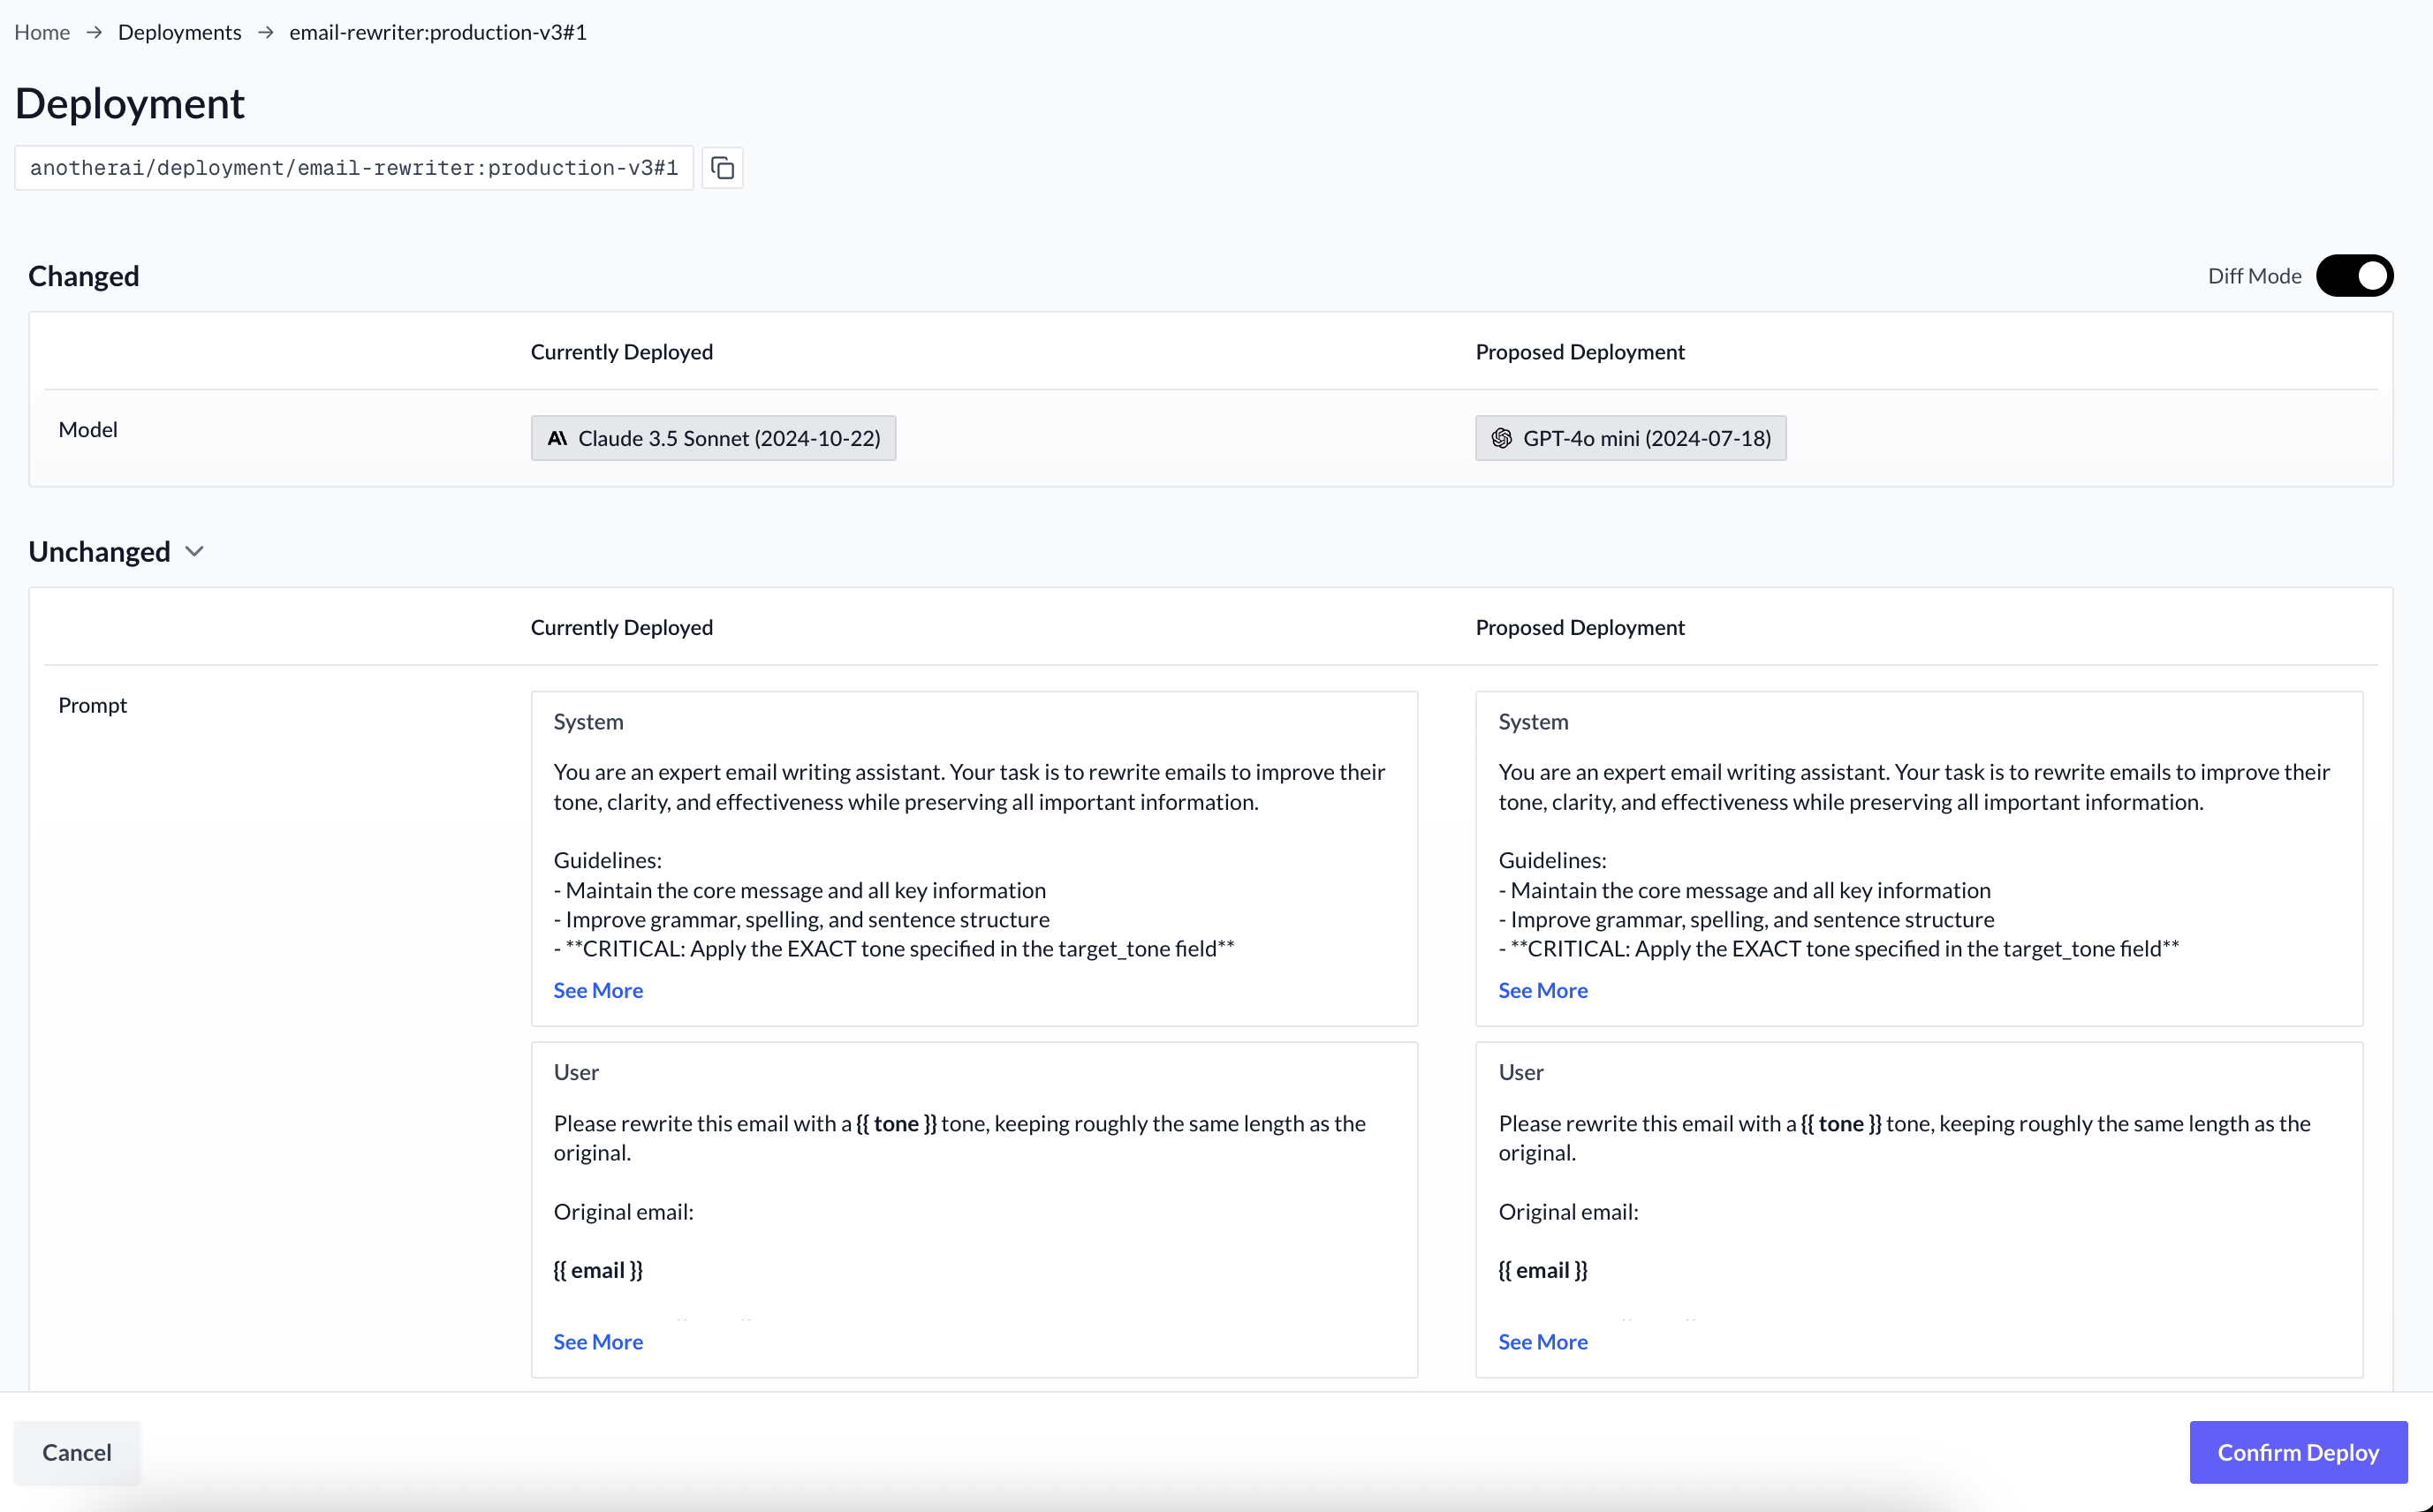
**That's it!** **No code changes needed** - your application automatically uses the updated version.
# Image Agents
URL: /use-cases/image-agents
undefined
***
## title: Image Agents
TODO
# Lowering Costs for an Agent
URL: /use-cases/lowering-costs
How to reduce agent costs while maintaining quality
***
title: Lowering Costs for an Agent
summary: Use case for optimizing agent costs by testing different models
description: How to reduce agent costs while maintaining quality
----------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
Suppose you have an agent that is working well, but is used in your product very often and racking up costs. With AnotherAI your AI assistant gets instant access to 100+ different models, so it can help you find a cheaper model that can deliver the same quality at a fraction of the cost.
## Identifying Cost Issues
Before optimizing costs, you need to understand your current spending. To get an overview of your current spending, you can view your [organization's metrics](https://anotherai.dev/metrics).
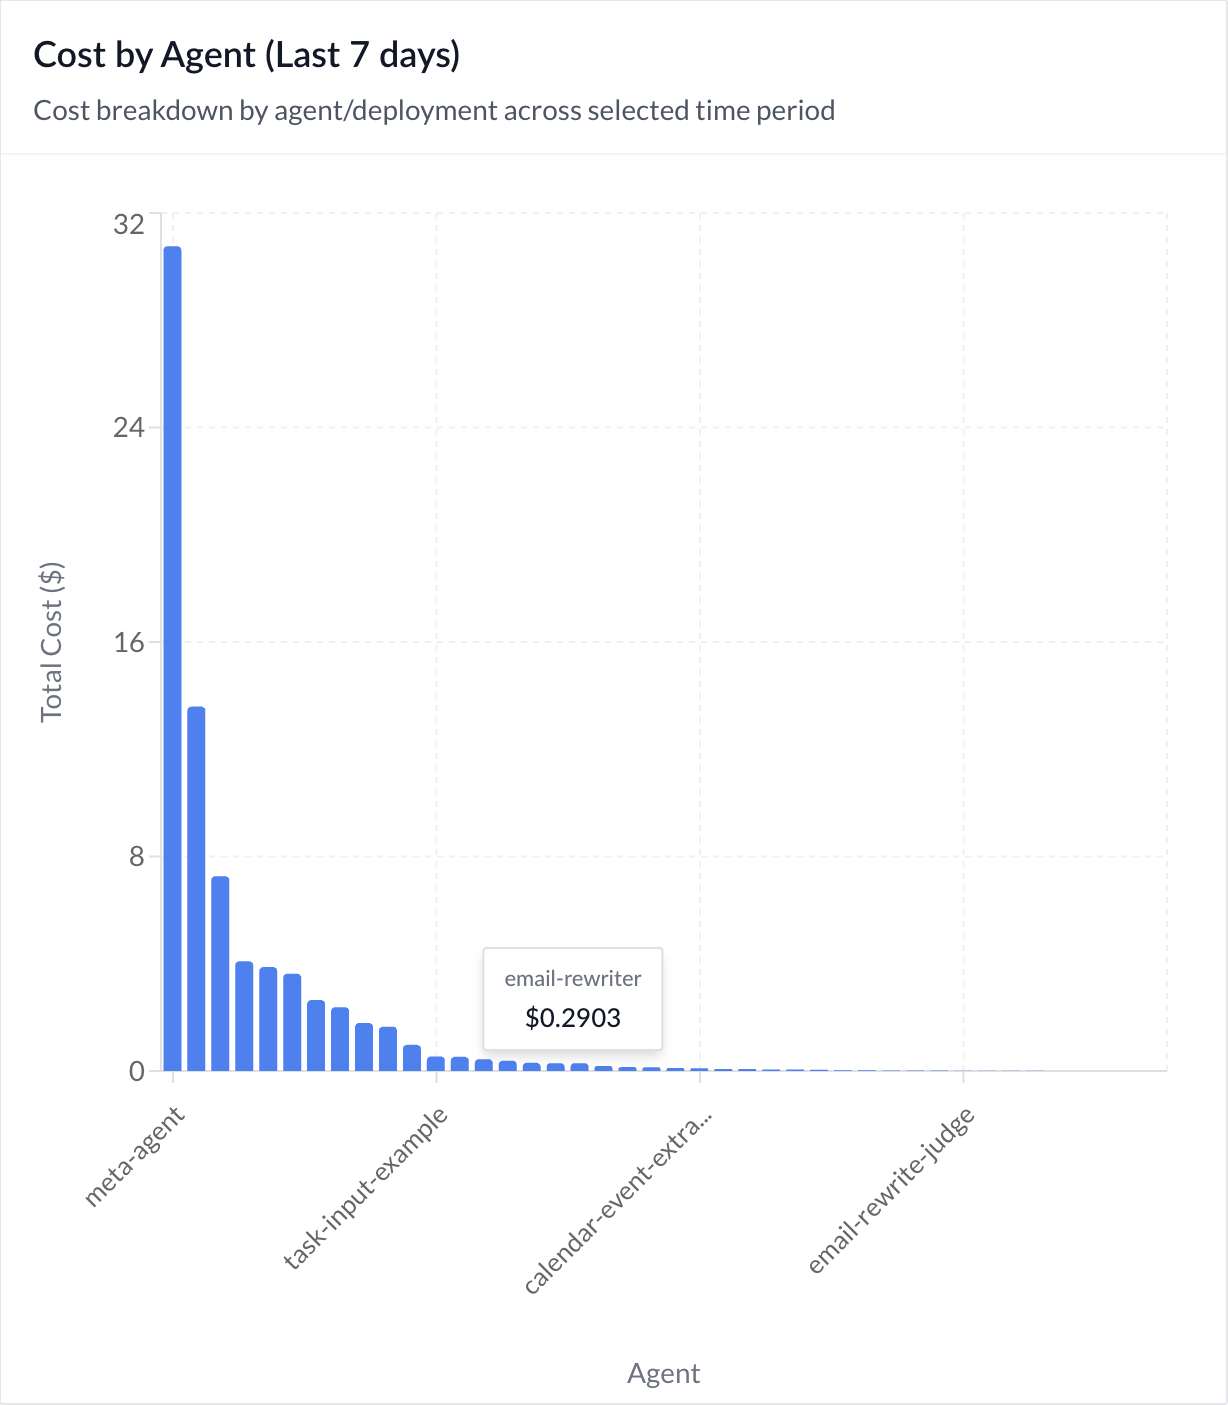
Your AI assistant can also help identify cost trends and anomalies:
```
Compare the costs of my agents and identify which ones are the most expensive to run.
Show me any agents where costs have increased significantly recently.
```
⏺ Cost Analysis Summary
**Most Expensive Agents (Total Cost)**
Top 5 by Total Spend:
1. email-subject-generator - $314.60 (241K runs)
2. task-extractor - $240.41 (329K runs)
3. daily-summary-writer - $229.95 (324K runs)
4. content-summarizer - $120.80 (168K runs)
5. document-analyzer - $72.78 (168K runs)
Top 5 by Cost Per Run:
1. research-assistant - $0.0095/run
2. customer-chat-bot - $0.0093/run
3. data-extractor - $0.0054/run
4. draft-generator - $0.0044/run
5. report-builder - $0.0043/run
**Agents with Significant Recent Cost Increases**
Massive Increases (>1000% daily average):
* contact-finder: +5,343% increase (from $0.33 to $13.57 in last 3 days)
* data-extractor: +2,038% increase (from $0.22 to $3.56)
* query-parser: +2,018% increase (from $0.16 to $2.52)
* customer-chat-bot: +1,822% increase (from $1.76 to $25.40)
* entity-extractor: +1,712% increase (from $0.35 to $4.76)
High-volume agents with large increases (>500%):
* daily-summary-writer: +1,228% increase (294K runs in last 3 days)
* task-extractor: +560% increase (274K runs in last 3 days)
* email-subject-generator: +527% increase (198K runs in last 3 days)
* content-summarizer: +570% increase (140K runs in last 3 days)
The cost increases appear to be primarily driven by increased usage volume rather than per-run cost changes, as most agents show stable or only slightly increased average costs per run.
AnotherAI automatically tracks costs for every completion, making it easy to identify which agents and models are driving your expenses. Learn more about [metrics and tracking](/use-cases/fundamentals/metrics).
## Finding a Cost-Effective Model
Ask your AI assistant to create an experiment comparing your current model against cheaper alternatives
```
Help me find the most cost effective model to use on anotherai/agent/calendar-event-extractor.
Compare the cheaper models with my current model to assess the cost difference and
quality drop.
```
If you want to be sure to test with real data, you can modify your prompt to include that instruction
```
Help me find the most cost effective model to use on anotherai/agent/calendar-event-extractor.
Compare the cheaper models with my current model to assess the cost difference and
quality drop. Use the inputs from the last 50 production completions.
```
Alternatively, if you have a [dataset](/use-cases/fundamentals/evaluating#using-datasets-to-evaluate-your-agents) of standard test inputs you like to use to validate changes, you can modify your prompt to include that instruction:
```
Help me find the most cost effective model to use on anotherai/agent/calendar-event-extractor.
Compare the cheaper models with my current model to assess the cost difference and
quality drop. Use the inputs from @email_test_cases.txt
```
Your AI assistant will create the experiment and give you an initial analysis of the results and well as a URL to view the results in the AnotherAI web app.
You can use the provided URL to view the results in the AnotherAI web app to perform manual analysis of the results.
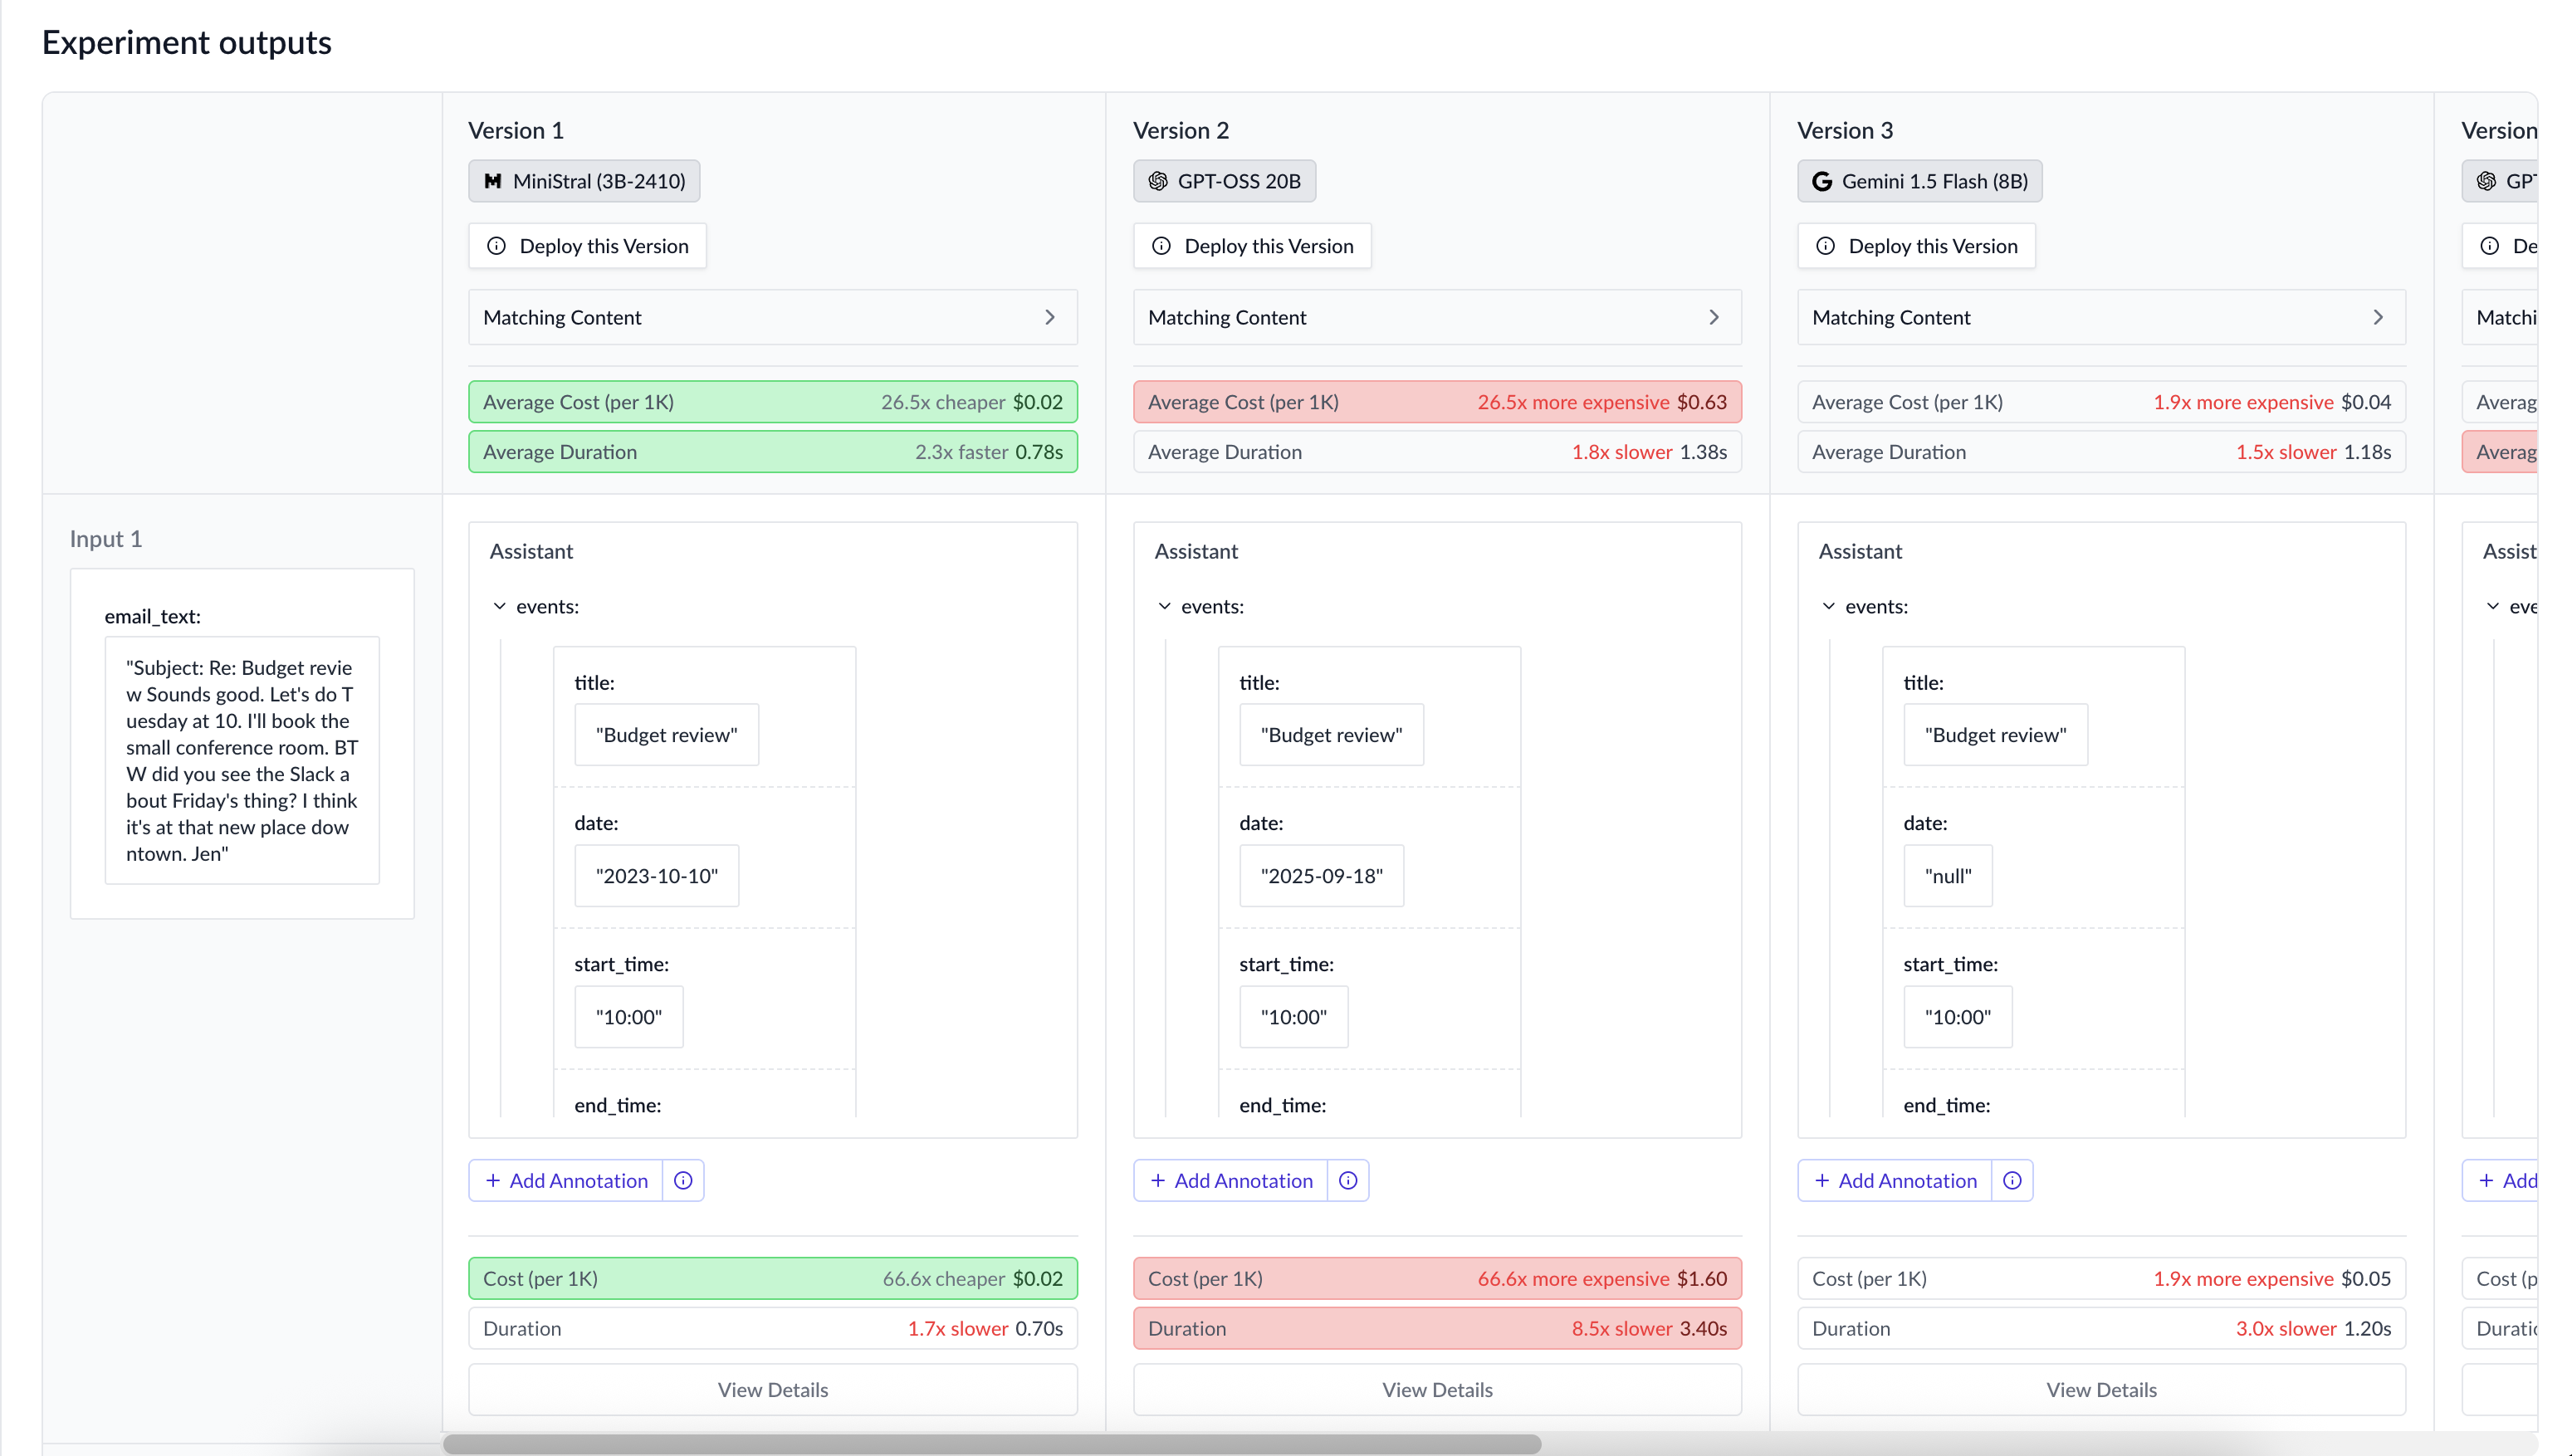
# Model Context Protocol (MCP)
URL: /use-cases/mcp.private
Learn how to use MCP servers with AnotherAI
***
title: Model Context Protocol (MCP)
summary: Documentation on using the Model Context Protocol (MCP) to connect AI agents to external data and tools. Covers MCP concepts, provider comparisons, and implementation with AnotherAI.
description: Learn how to use MCP servers with AnotherAI
--------------------------------------------------------
This guide is a work in progress and is not ready to be published.
The Model Context Protocol (MCP) is an open standard that enables AI models to securely connect to external data sources and tools. Think of MCP like a USB-C port for AI applications - it provides a standardized way to connect AI models to different systems, databases, and services.
AnotherAI supports MCP integration through the OpenAI-compatible chat/completions endpoint, allowing you to leverage the growing ecosystem of MCP servers with any model supported by AnotherAI.
## What is MCP?
MCP allows AI models to access:
* **External data sources** (databases, file systems, APIs)
* **Live information** (real-time data, current state)
* **Specialized tools** (code execution, analysis tools)
* **Business systems** (CRM, documentation, internal tools)
Unlike static data or pre-trained knowledge, MCP enables models to access up-to-date, contextual information during the conversation.
## MCP vs Traditional Tools
| Feature | **Traditional Tools** | **MCP Servers** |
| --------------- | ------------------------------ | --------------------------------- |
| **Setup** | Define individual functions | Connect to pre-built servers |
| **Scope** | Single function per tool | Multiple related tools per server |
| **Maintenance** | Custom code required | Server maintained by community |
| **Discovery** | Manual tool definition | Automatic tool discovery |
| **Context** | Limited to function parameters | Rich contextual data access |
## Provider Implementation Comparison
Before diving into AnotherAI's approach, let's compare how OpenAI, Anthropic, and Mistral implement MCP:
### OpenAI Implementation (Responses API)
**Approach**: Tool-centric configuration via Responses API
```bash
curl https://api.openai.com/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $OPENAI_API_KEY" \
-d '{
"model": "gpt-4.1",
"tools": [
{
"type": "mcp",
"server_label": "github",
"server_url": "https://mcp.github.com/sse",
"allowed_tools": ["search_repositories", "create_issue"],
"require_approval": "never"
}
],
"input": "Check my repositories for security issues"
}'
```
**Key Characteristics:**
* **Endpoint**: Uses `/v1/responses` (not chat/completions)
* **Configuration**: MCP servers configured in `tools` array with `type: "mcp"`
* **Tool Filtering**: `allowed_tools` parameter to limit available tools
* **Approval Control**: `require_approval` parameter for security
* **Server Identification**: `server_label` for naming servers
### Anthropic Implementation (Messages API)
**Approach**: Parameter-centric configuration via Messages API
```bash
curl https://api.anthropic.com/v1/messages \
-H "Content-Type: application/json" \
-H "X-API-Key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: mcp-client-2025-04-04" \
-d '{
"model": "claude-sonnet-4-20250514",
"max_tokens": 1000,
"messages": [{"role": "user", "content": "Check my repositories for security issues"}],
"mcp_servers": [
{
"type": "url",
"url": "https://mcp.github.com/sse",
"name": "github",
"authorization_token": "ghp_xxxxxxxxxxxx",
"tool_configuration": {
"enabled": true,
"allowed_tools": ["search_repositories", "create_issue"]
}
}
]
}'
```
**Key Characteristics:**
* **Endpoint**: Uses standard `/v1/messages` API
* **Configuration**: Dedicated `mcp_servers` parameter
* **Beta Feature**: Requires `anthropic-beta: mcp-client-2025-04-04` header
* **Tool Control**: `tool_configuration` object for fine-grained control
* **Authentication**: Direct `authorization_token` in server config
### Mistral Implementation
**Approach**: Agent-centric configuration with Python SDK
**Note**: Mistral provides CURL examples for their general `/v1/agents/completions` API, but their MCP documentation only shows Python SDK examples, not raw API calls.
```python
# Python SDK example from Mistral docs
from mistralai import Mistral
from mistralai.extra.run.context import RunContext
from mistralai.extra.mcp.sse import MCPClientSSE, SSEServerParams
client = Mistral(api_key=api_key)
server_url = "https://mcp.github.com/sse"
mcp_client = MCPClientSSE(sse_params=SSEServerParams(url=server_url))
async with RunContext(model="mistral-medium-latest") as run_ctx:
await run_ctx.register_mcp_client(mcp_client=mcp_client)
run_result = await client.beta.conversations.run_async(
run_ctx=run_ctx,
inputs="Check my repositories for security issues"
)
```
**Key Characteristics:**
* **Endpoint**: Uses `/v1/agents/completions` via Python SDK
* **Configuration**: MCP servers registered via `RunContext` and `register_mcp_client()`
* **Agent Management**: Agents created with `/v1/agents` endpoint
* **Python-Only**: No raw CURL examples for MCP integration
* **Conversation-Based**: Uses `conversations.run_async()` for execution
### AnotherAI Hybrid Approach
**Best of Both Worlds**: Maintains OpenAI compatibility while offering flexible configuration
```bash
# Option 1: Extended tools parameter (OpenAI-style)
curl https://run.anotherai.com/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer aai-xxx" \
-d '{
"model": "claude-3-7-sonnet-latest",
"messages": [{"role": "user", "content": "Check my repositories for security issues"}],
"metadata": {"agent_id": "security-analyst"},
"tools": [
{
"type": "mcp_server",
"mcp_server": {
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {"type": "bearer", "token": "ghp_xxx"},
"allowed_tools": ["search_repositories", "create_issue"]
}
}
]
}'
# Option 2: Dedicated mcp_servers parameter (Anthropic-style)
curl https://run.anotherai.com/v1/chat/completions \
-H "Content-Type: application/json" \
-H "Authorization: Bearer aai-xxx" \
-d '{
"model": "claude-3-7-sonnet-latest",
"messages": [{"role": "user", "content": "Check my repositories for security issues"}],
"metadata": {"agent_id": "security-analyst"},
"extra_body": {
"mcp_servers": [
{
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {"type": "bearer", "token": "ghp_xxx"},
"allowed_tools": ["search_repositories", "create_issue"]
}
]
}
}'
```
**Key Advantages:**
* **Full OpenAI Compatibility**: Uses standard `/v1/chat/completions` endpoint
* **Flexible Configuration**: Both tools-based and parameter-based approaches
* **Agent Integration**: Works with AnotherAI's agent/version/deployment system
* **No Beta Headers**: Production-ready without experimental flags
### API Specification Comparison
| Feature | **OpenAI** | **Anthropic** | **Mistral** | **AnotherAI** |
| --------------------- | --------------------- | ---------------------------------- | -------------------------------------- | ---------------------- |
| **MCP Documentation** | CURL examples | CURL examples | Python SDK only | Both options |
| **Endpoint** | `/v1/responses` | `/v1/messages` | `/v1/agents/completions` | `/v1/chat/completions` |
| **Beta Required** | No | Yes (`mcp-client-2025-04-04`) | No | No |
| **MCP Location** | `tools` array | `mcp_servers` parameter | `RunContext.register_mcp_client()` | Both options |
| **Tool Filtering** | `allowed_tools` | `tool_configuration.allowed_tools` | Not documented | `allowed_tools` |
| **Authentication** | Headers/URL params | `authorization_token` | SDK OAuth flows | `auth` object |
| **Multi-server** | Multiple tool entries | Array of servers | Multiple `register_mcp_client()` calls | Both patterns |
| **OpenAI Compat** | Different endpoint | Different API | Different paradigm | Full compatibility |
## Supported MCP Server Types
AnotherAI focuses exclusively on remote MCP servers:
### SSE Servers (Server-Sent Events)
Remote servers using Server-Sent Events. Perfect for real-time data and cloud services.
```python
client.chat.completions.create(
model="claude-3-7-sonnet-latest",
messages=[{"role": "user", "content": "Check this code for vulnerabilities"}],
metadata={"agent_id": "security-analyst"},
extra_body={
"mcp_servers": [{
"type": "sse",
"name": "semgrep",
"url": "https://mcp.semgrep.ai/sse"
}]
}
)
```
### HTTP Servers (Streamable)
Servers using streamable HTTP transport for high-performance scenarios.
```python
client.chat.completions.create(
model="gemini-2.5-pro-preview",
messages=[{"role": "user", "content": "Analyze sales data from Q4"}],
metadata={"agent_id": "data-analyst"},
extra_body={
"mcp_servers": [{
"type": "http",
"name": "analytics",
"url": "https://api.example.com/mcp",
"headers": {"Authorization": "Bearer token"}
}]
}
)
```
## Authentication Strategies
AnotherAI supports two authentication approaches for MCP servers:
### Strategy 1: UI-Configured Authentication
Configure authentication credentials in the AnotherAI web application for reusable, secure access:
**TODO**: Setting API keys from the UI might not work properly - this behavior needs to be determined
**In AnotherAI UI:**
1. Navigate to Agent Settings → MCP Servers
2. Add server with authentication details
3. Configure OAuth flows or store API keys securely
### Strategy 2: Dynamic Authentication
Pass authentication details directly in API requests for dynamic or temporary access:
```python
# Dynamic authentication in request
client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Search GitHub repositories"}],
metadata={"agent_id": "research-assistant"},
extra_body={
"mcp_servers": [{
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {
"type": "bearer",
"token": os.getenv("GITHUB_TOKEN")
}
}]
}
)
```
## Authentication Configuration
### Bearer Token Authentication
```python
{
"mcp_servers": [{
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {
"type": "bearer",
"token": "ghp_xxxxxxxxxxxx"
}
}]
}
```
### API Key Authentication
```python
{
"mcp_servers": [{
"type": "http",
"name": "database",
"url": "https://api.example.com/mcp",
"auth": {
"type": "api_key",
"header": "X-API-Key",
"value": "your-api-key"
}
}]
}
```
## Advanced Features
### Error Handling
...
## Combining with Existing Features
### MCP + Caching
**Important Consideration**: How should MCP tool calls interact with AnotherAI's existing caching system? This behavior needs to be defined:
* Should MCP tool calls disable caching (like current `tools` behavior)?
* Should caching work with special considerations for MCP servers?
* Should different MCP servers have different caching behaviors?
*This is an open design question that requires further specification.*
Current implementation assumption:
```python
# MCP tool calls respect AnotherAI's caching behavior
response = client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "What's the latest on quantum computing?"}],
temperature=0, # Enable caching
metadata={"agent_id": "research-assistant"},
extra_body={
"use_cache": "always", # Force cache check
"mcp_servers": [{
"type": "sse",
"name": "arxiv",
"url": "https://mcp.arxiv.org/sse"
}]
}
)
```
### MCP + Deployments + Conversations
```python
# Initial request with MCP server
initial_response = client.chat.completions.create(
model="code-reviewer/#1/production",
messages=[{"role": "user", "content": "Review my latest commit"}],
extra_body={
"mcp_servers": [{
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {"type": "bearer", "token": "ghp-token"}
}]
}
)
# Follow-up using conversation state
followup_response = client.chat.completions.create(
model="code-reviewer/#1/production",
messages=[{"role": "user", "content": "Apply the suggested changes"}],
extra_body={
"reply_to_run_id": initial_response.id,
# MCP servers from initial request are automatically available
}
)
```
## Security Considerations
### Authentication Best Practices
1. **Use Environment Variables**: Store sensitive tokens in environment variables, not in code
2. **Scope Permissions**: Use tokens with minimal required permissions
3. **Rotate Credentials**: Regularly rotate API keys and access tokens
4. **Monitor Usage**: Track MCP server usage for unusual patterns
### Safe Server Configuration
```python
# Good: Minimal permissions, specific scopes
{
"type": "sse",
"name": "github",
"url": "https://mcp.github.com/sse",
"auth": {
"type": "bearer",
"token": os.getenv("GITHUB_TOKEN") # Read-only token with repo scope
}
}
```
### Data Privacy
* **User Consent**: Ensure users understand what data MCP servers can access
* **Data Boundaries**: Configure MCP servers with appropriate scope limitations
* **Audit Logging**: Enable logging for MCP server interactions in production
## Troubleshooting
**TODO**: Comprehensive error handling and troubleshooting documentation will be added in a future release. This will include detailed error codes, common issues, and resolution strategies for MCP server integration.
## API Reference
### MCP Server Configuration Schema
```python
{
"mcp_servers": [
{
"type": "sse|http", # Required: Server type
"name": "server-name", # Required: Unique identifier
"url": "https://...", # Required: Server URL
"headers": {...}, # Optional: HTTP headers
"auth": {...} # Optional: Authentication config
}
]
}
```
### Request Format Options
**Option 1: Extended Tools Parameter**
```python
tools = [
# Traditional tools
{"type": "function", "function": {...}},
# MCP servers
{"type": "mcp_server", "mcp_server": MCPServerConfig}
]
```
**Option 2: Separate MCP Servers Parameter**
```python
extra_body = {
"mcp_servers": [MCPServerConfig, ...],
"mcp_options": {
"parallel_execution": True,
"max_tools_per_server": 50,
"error_handling": "graceful"
}
}
```
### Response Format
MCP tool calls appear in the response like standard tool calls:
```json
{
"choices": [{
"message": {
"role": "assistant",
"content": null,
"tool_calls": [{
"id": "call_abc123",
"type": "function",
"function": {
"name": "search_papers",
"arguments": "{\"query\": \"quantum computing\"}"
},
"mcp_server": "arxiv" # Additional field indicating MCP server
}]
}
}],
"usage": {
"prompt_tokens": 100,
"completion_tokens": 50,
"total_tokens": 150,
"mcp_servers_used": ["arxiv", "database"] # Additional field
}
}
```
## Provider Documentation References
For additional context and implementation details, refer to the official MCP documentation from other providers:
* **OpenAI MCP Documentation**: [OpenAI Agents SDK - Model Context Protocol](https://openai.github.io/openai-agents-python/mcp/)
* **Mistral MCP Documentation**: [Mistral AI - MCP Integration](https://docs.mistral.ai/agents/mcp/#how-to-use-a-remote-mcp-server-with-authentication)
* **Anthropic MCP Documentation**: [Anthropic - MCP Connector](https://docs.anthropic.com/en/docs/agents-and-tools/mcp-connector)
* **MCP Specification**: [Model Context Protocol Official Specification](https://modelcontextprotocol.io/specification/2025-03-26/index)
# Memory
URL: /use-cases/memory.private
...
***
title: Memory
summary: Explains how to manage conversational memory using `reply_to_run_id`. This feature maintains chat history for stateful, multi-turn interactions.
description: ...
----------------
## Chat history
When building a chatbot agent with multiple back and forths, you previously needed to keep track of the conversation history, since LLM requires the full context of the conversation to generate a response.
To make it easier to manage the chat history, AnotherAI provides a managed storage for all chat agents, so you can only pass the last message to AnotherAI along with a `reply_to_run_id` parameter, and the previous messages of the conversation will be added by AnotherAI automatically.
### How it Works
When AnotherAI receives a request containing `reply_to_run_id`, it performs these steps before calling the underlying LLM:
1. Looks up the run associated with the provided `reply_to_run_id`.
2. Retrieves the complete `messages` array (including system, user, and assistant turns) from that historical run.
3. Prepends these historical messages to the `messages` array sent in the current request.
4. Sends the combined message list to the target language model.
### Benefits
* **Simplified State Management:** Offloads the burden of storing and transmitting potentially long conversation histories from your client application.
* **Reduced Payload Size:** Your client only needs to send the latest user message(s), significantly reducing the size of the API request payload for long conversations.
* **Seamless Agent/Chatbot Development:** Makes building multi-turn conversational agents much easier, as AnotherAI handles the context continuity.
This feature effectively turns the stateless chat completion endpoint into a stateful one, managed by AnotherAI based on the run history.
### Example
#### Simple example
```python
response = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "Hello, how are you?"},
]
)
# get the conversation id
conversation_id = response.id
# send a new message to the conversation
response = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "user", "content": "My name is John."}
],
extra_body={
"reply_to_run_id": conversation_id
}
)
```
#### Using deployments
You can combine the Deployments feature with the stateful conversation feature (`reply_to_run_id`) to easily manage conversational context while using server-managed model configurations.
**Mechanism:**
Make an API call specifying:
1. The target deployment in the `model` parameter: `model="/#/"`
2. The previous run ID in the `extra_body`: `extra_body={"reply_to_run_id": "chatcmpl-xxxx"}`
3. Typically, only the *new* user message(s) in the `messages` array.
**How it Works:**
When both are provided, AnotherAI performs the following:
1. Retrieves the full message history from the run specified by `reply_to_run_id`.
2. Identifies the **model** associated with the `/#/` from your Deployment configurations.
3. Prepends the retrieved history to the new message(s) provided in the current request's `messages` array.
4. Sends the combined message list to the **model specified by the Deployment**.
**Important Interaction Note:** In this specific scenario (using both `reply_to_run_id` and a Deployment ID), the prompt template defined within the Deployment configuration is **not applied**. The message history fetched via `reply_to_run_id` provides the necessary context, and the Deployment ID primarily serves to select the correct model for the next turn in the conversation. Any `input` variables in `extra_body` will apply to templates within the *new* message(s) provided in the current call.
**Benefit:** This allows you to maintain conversation state effortlessly using `reply_to_run_id` while ensuring that the appropriate, environment-specific model (managed via Deployments) is used for generating the next response.
# Increasing Agent Reliability
URL: /use-cases/private.increasing-agent-reliability
How AnotherAI is designed to provide 100% uptime for your agents.
***
title: Increasing Agent Reliability
summary: Documentation on reliability features. Covers how to configure provider and model fallbacks.
description: How AnotherAI is designed to provide 100% uptime for your agents.
------------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
import StatusMonitor from '@/components/status-monitor';
## Goal
We are committed to delivering 100% uptime for your agents. To achieve this, we've implemented model and provider fallback systems that automatically handle failures. When individual AI providers or models fail, your tasks continue running seamlessly without interruption.
## Intelligent fallback systems
AnotherAI implements multiple layers of fallback mechanisms to ensure your agents continue running even when individual components fail. These systems work together to provide seamless operation across different failure scenarios.
### Provider fallback (automatic)
AnotherAI continuously monitors the health and performance of all integrated AI providers. When a provider experiences downtime or degraded performance, our system automatically switches to a healthy alternative provider without any manual intervention.
For example, all OpenAI models are also available through Azure OpenAI Service. If the OpenAI API becomes unavailable, AnotherAI will automatically failover to Azure OpenAI within one second. This seamless transition ensures your agent runs continue without interruption, and you don't need to make any changes to your code.
n
This intelligent routing between providers happens behind the scenes, maintaining consistent response times and reliability for your applications even during provider outages.
### Model fallback (configurable)
Sometimes using the exact same model on a different provider won't ensure 100% uptime. Common scenarios include:
* The model doesn't have provider redundancy and the unique provider is having issues
* All providers for a given model are down, or rate limits are exceeded on all providers
* The completion failed due to model limitations (content moderation errors, failed structured outputs)
In these cases, falling back to a different AI model can ensure the completion succeeds.
#### Configuration options
Configure model fallback using the `use_fallback` argument in the completion endpoint:
| Option | Value | Behavior |
| ----------------------- | ------------------------ | ---------------------------------------------------------------------------------------------------------------- |
| **Automatic** (default) | `"auto"` | Uses a different model based on the error type. See [automatic fallback logic](#automatic-fallback-logic) below. |
| **Disable** | `"never"` | Disables fallback entirely. Useful when consistency matters more than success. |
| **Custom** | `["model-1", "model-2"]` | Allows passing a list of models to try in order when the initial model fails. |
#### Automatic fallback logic
The default fallback algorithm (i.e. when `use_fallback` is not provided or when `use_fallback="auto"`) assigns each model a fallback model based on the type of error that occurred:
* for rate limit errors, we use a model of the same category (similar price and speed) that is supported by a different provider
* structured generation errors can occur for models without native structured output. In this case, we use a model at the same price point that supports native structured output. For example, `GPT 4.1 Nano` would be used as a fallback for models like `Llama 4 Scout` and `Gemini 2.0 Flash`.
* for content moderation errors, we use a model that has been historically more permissive. For example, Llama 4 Maveric on Groq seems to be on the stricter side whereas non preview Gemini models on Vertex are often more permissive.
#### Code examples
##### OpenAI SDK
```python
completion = client.chat.completions.create(
model="gpt-4o",
messages=[{"role": "user", "content": "Extract the name and email from: John Doe "}],
model_fallback=["gpt-4o-mini", "claude-3-5-haiku-20241022"]
)
```
```typescript
const completion = await openai.chat.completions.create({
model: "gpt-4o",
messages: [{"role": "user", "content": "Extract the name and email from: John Doe "}],
model_fallback: ["gpt-4o-mini", "claude-3-5-haiku-20241022"]
});
```
```sh
curl -X POST {{API_URL}}/v1/chat/completions \
-H "Authorization: Bearer $ANOTHERAI_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o",
"messages": [{"role": "user", "content": "Extract the name and email from: John Doe "}],
"model_fallback": ["gpt-4o-mini", "claude-3-5-haiku-20241022"]
}'
```
## Infrastructure resilience
Our infrastructure is designed with multiple layers of redundancy to ensure continuous operation even during various failure scenarios.
### Application layer
We've designed our application architecture for maximum resilience:
* **Isolated inference endpoints**: Our inference API runs in separate containers, isolated from other API endpoints. This allows independent scaling and deployment of the inference API.
* **Canary deployments**: New API versions are deployed to a small subset of users first, then gradually rolled out. This allows us to catch issues early and roll back if needed.
* **Health monitoring**: Continuous monitoring of service health enables automatic failover and issue detection.
### Database layer
We use MongoDB Atlas for our primary database infrastructure, ensuring high availability through a distributed architecture with a [99.995% SLA](https://www.mongodb.com/cloud/atlas/reliability). Our database deployment includes 7 replicas across 3 Azure regions:
* 3 replicas in East US2
* 2 replicas in Iowa
* 2 replicas in California
These replicas automatically synchronize data, ensuring that if one database instance or even an entire region fails, others can immediately take over without data loss. MongoDB Atlas offers automatic failover capabilities, where if the primary node becomes unavailable, a secondary replica is automatically promoted to primary, typically within seconds.
For storing run history and analytics data, we use Clickhouse, which excels at handling large volumes of data efficiently. While Clickhouse powers our analytics and observability features, it's not required for core agent execution. The process that stores run history is completely isolated from the critical run path, ensuring agents continue running normally even if Clickhouse experiences temporary unavailability.
### Network & datacenter layer
We use [Azure Front Door](https://azure.microsoft.com/en-us/products/frontdoor) as our global load balancer to ensure high availability across multiple regions. Our infrastructure is deployed in both East US and Central US datacenters, providing geographic redundancy.
Azure Front Door continuously monitors the health of our backend services in each region. If one datacenter experiences an outage or performance degradation, Azure Front Door automatically redirects traffic to the healthy region within approximately 30 seconds. This intelligent routing happens without manual intervention, ensuring minimal disruption to your API calls.
This multi-region architecture allows us to maintain high availability even during regional cloud provider outages, helping us achieve our goal of 100% uptime for the AnotherAI API.
If you have any questions about our architecture, please reach out to us on [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA) or [email](mailto:team@workflowai.support).
# Migrating from WorkflowAI to AnotherAI
URL: /use-cases/private.migrate-from-workflowai
undefined
***
title: Migrating from WorkflowAI to AnotherAI
summary: Guide for migrating agents from WorkflowAI to AnotherAI
----------------------------------------------------------------
## Context
WorkflowAI is a layer of abstraction on top of LLM providers, that similarly to AnotherAI allows hitting many providers in the same manner.
The main difference is that in most cases WorkflowAI has a "structured data in structured data out" approach and does not use the message primitive in its basic API.
While not the most common usage, WorkflowAI also offers an OpenAI completion API compatible endpoint.
WorkflowAI and AnotherAI share the same authorization servers. So users of WorkflowAI can use the same account on AnotherAI. API Keys are however not transferable. WorkflowAI API keys start with `wai-` and AnotherAI API keys start with `aai-`.
## Migration Steps
Very important: Most WorkflowAI agents use deployments on WorkflowAI, meaning that the code does not contain the prompt. The prompt is stored and managed by the WorkflowAI backend. It is possible to setup a bridge that forwards data from WorkflowAI to AnotherAI which makes the prompt and/or deployment available in AnotherAI.
### Step 1: Identify the agent id and deployment environment
You will first need to identify:
* the agent id, which will be the same in AnotherAI as in WorkflowAI
* the deployment environment ("production", "staging", "dev")
They both can be extracted from the code.
```typescript
// WorkflowAI client setup
// This should be replaced with the OpenAI client setup pointing to AnotherAI
const workflowAI = new WorkflowAI({
key: process.env["WORKFLOWAI_API_KEY"],
});
// Set up types
// Input type can likely be re-used in a function
export interface AnalyzeBookCharactersTaskInput {
book_title?: string;
}
// Output type will have to converted to a Zod schema to be compatible with the OpenAI beta SDK
export interface AnalyzeBookCharactersTaskOutput {
characters?: {
name?: string;
goals?: string[];
weaknesses?: string[];
outcome?: string;
}[];
}
// Set up the agent
const analyzeBookCharacters: Agent<
AnalyzeBookCharactersTaskInput,
AnalyzeBookCharactersTaskOutput
> = workflowAI.agent({
id: "analyze-book-characters", // agent id, will be the same in AnotherAI
schemaId: 1, // schema id, can be ignored, will no longer be used in AnotherAI
version: "production", // deployment envoronment, in WorkflowAI deployments are unique per agent schema
});
```
WorkflowAI exposes a `run` endpoint per agent and schema. The full url will look like `https://run.workflowai.com/v1/agents//schemas//run` or `https://run.workflowai.com/v1/tasks//schemas//run` where:
* `` is a slug that is the id of the agent
* `` is an integer that identifies a schema (not used in AnotherAI)
The payload will look like:
```
POST https://run.workflowai.com/v1/agents/analyze-book-characters/schemas/1/run
Authorization: Bearer aai-***
Content-Type: application/json
{
"version": "production", // deployment_id, in WorkflowAI deployments are unique per agent schema
"task_input": {
"book_title": "The Shadow of the Wind"
},
"metadata": {
// metadata is optional
}
}
```
### Step 2: Check if a deployment has already been migrated
In WorkflowAI, deployments are unique per agent schema. In AnotherAI, deployments are unique accross all agents and the concept of schema is removed. Instead, it is a good practice to include the agent\_id into the deployment id and add a deployment number.
You can fetch all existing deployments for a given agent using the `list_deployments` tool with the agent\_id parameter.
A migrated deployment will likely have the shape: `:#`
In the example above, the migrated deployment will look like: `analyze-book-characters:production#1`.
> It is possible that a deployment was created with a slightly different format. Check the available deployments using the `list_deployments` tool and make sure to adjust the deployment id accordingly.
If the deployment has not been migrated, tell the user to contact the WorkflowAI support.
### Step 3: Convert the WorkflowAI code to point to AnotherAI when a deployment has already been migrated for a standard WorkflowAI agent
AnotherAI is compatible with the OpenAI completion API, so it should be configured just like any other OpenAI client. You can use the `create_api_key` tool to create an API key if needed. Be mindful of any existing frameworks that are used to make completion calls and follow the appropriate documentation. In some cases, you might have to adapt the response format (aka `output_schema`) which is a property of the version in AnotherAI.
To use a deployment, simply use the deployment id in the model parameter in the completion call.
```typescript
import OpenAI from "openai";
import { zodTextFormat } from "openai/helpers/zod";
import { z } from "zod";
const client = new OpenAI({
baseURL: "{{API_URL}}/v1",
apiKey: process.env["ANOTHERAI_API_KEY"],
});
// Typescript here is sufficient
export interface AnalyzeBookCharactersTaskInput {
book_title?: string;
}
// ----------------------------------------------------------------
// Without using Zod
export interface AnalyzeBookCharactersTaskOutput {
characters?: {
name?: string;
goals?: string[];
weaknesses?: string[];
outcome?: string;
}[];
}
export async function analyzeBookCharacters(input: AnalyzeBookCharactersTaskInput): Promise {
const completion = await client.chat.completions.create({
model: "anotherai/deployment/analyze-book-characters:production#1", // use the "anotherai/deployment/" id here
messages: [], // messages should remain empty since the prompt is stored in AnotherAI
// response_format is not needed here since it is handled by the deployment
input: input, // input is AnotherAI specific. You may have to silence a TS error
});
return JSON.parse(completion.choices[0].message.content)
}
// ----------------------------------------------------------------
// Or if using Zod and the beta OpenAI client
// Output needs to be converted to a Zod schema to be compatible with the OpenAI beta SDK
// OutputSchema is available in `version.output_schema.json_schema`
const AnalyzeBookCharactersTaskOutputSchema = z.object({
characters: z.array(z.object({
name: z.string(),
goals: z.array(z.string()),
weaknesses: z.array(z.string()),
outcome: z.string(),
})),
});
export type AnalyzeBookCharactersTaskOutput = z.infer;
export async function analyzeBookCharacters(input: AnalyzeBookCharactersTaskInput): Promise {
// Use .parse() instead of .create() when using the beta client
// `client.beta.chat` in older versions of the SDK
const completion = await client.chat.completions.parse({
model: "anotherai/deployment/analyze-book-characters:production#1", // use the "anotherai/deployment/" id here
messages: [], // messages should remain empty since the prompt is stored in AnotherAI
response_format: zodTextFormat(AnalyzeBookCharactersTaskOutputSchema, "AnalyzeBookCharactersTaskOutput"),
input: input, // input is AnotherAI specific. You may have to silence a TS error
});
return completion.output_parsed
}
```
```go
import (
"context"
// Make sure to use the v2
"github.com/openai/openai-go/v2"
"github.com/openai/openai-go/v2/option"
"github.com/openai/openai-go/v2/shared"
"github.com/invopop/jsonschema" // library to generate JSON schemas if needed
)
// setup AnotherAI client
var client = openai.NewClient(
option.WithBaseURL("{{API_URL}}/v1"),
option.WithAPIKey(os.Getenv("ANOTHERAI_API_KEY")),
)
// types are likely already present in the users' code
type AnalyzeBookCharactersTaskInput struct {
BookTitle string `json:"book_title"`
}
type AnalyzeBookCharactersTaskOutput struct {
Characters []struct {
Name string `json:"name"`
Goals []string `json:"goals"`
Weaknesses []string `json:"weaknesses"`
Outcome string `json:"outcome"`
} `json:"characters"`
}
// Generate the JSON schema for the output
var AnalyzeBookCharactersTaskOutput = jsonschema.Reflect(&AnalyzeBookCharactersTaskOutput{})
func AnalyzeBookCharacters(input AnalyzeBookCharactersTaskInput) (AnalyzeBookCharactersTaskOutput, error) {
params := openai.ChatCompletionNewParams{
// Pass a plain string here
Model: "anotherai/deployment/analyze-book-characters:production#1",
// No need to pass messages
Metadata: shared.Metadata{
//...any user provided metadata. No need to pass agent_id here since it will be passed by the deployment
},
ResponseFormat: openai.ChatCompletionNewParamsResponseFormatUnion{
OfJSONSchema: &openai.ResponseFormatJSONSchemaParam{
JSONSchema: openai.ResponseFormatJSONSchemaJSONSchemaParam{
Name: "analyze-book-characters-task-output",
Schema: AnalyzeBookCharactersTaskOutput,
},
},
},
}
// input is AnotherAI specific
params.SetExtraFields(map[string]any{
"input": input, // will be serialized as JSON
})
chatCompletion, err := client.Chat.Completions.New(
context.TODO(),
params,
)
out := AnalyzeBookCharactersTaskOutput{}
if err != nil {
// handle error if needed
return out, err
}
content := chatCompletion.choices[0].message.content
if err := json.Unmarshal([]byte(content), &out); err != nil {
// handle error if needed
return out, err
}
return out, nil
}
```
It is likely that an OpenAI SDK exists for the requested language. The OpenAI SDKs are usually more convenient to use, providing out of the box:
* retries / error management
* structured output parsing
* tool calling handling
It is also possible that the user already has an Agent framework setup that is compatible with the completion API. If re-using an existing Agent framework, it is a good idea to create a separate client as to avoid forcing the user to migrate the entirety of its completion calls.
If hitting the API directly is needed, the payload will look like:
```json
{
"model": "anotherai/deployment/analyze-book-characters:production#1", // use the "anotherai/deployment/" id here
"messages": [],
// no need to pass the response_format here, it is handle by the deployment
"input": ..., // corresponds to task_input in WorkflowAI,
"metadata": {
// metadata is optional
}
}
```
The code is now migrated to AnotherAI.
### Step 3 bis: Migrating a WorkflowAI agent that uses the OpenAI completion API compatible endpoint
A WorkflowAI agent that uses the completion API will also have a configured OpenAI client. This client should be updated to point to AnotherAI's base URL and API key.
Example code to be converted:
```typescript
import OpenAI from 'openai';
client = OpenAI(
base_url="https://run.workflowai.com/v1/",
api_key=os.environ["WORKFLOWAI_API_KEY"],
)
```
When hitting the API directly, an http client is usually configured with the base URL and API key.
The exact client depends on the language and libraries that are used.
Simply make sure that:
* the base URL points to `{{API_URL}}`. The full completion URL should look like `{{API_URL}}/v1/chat/completions`
* the Authorization header looks like `Authorization: Bearer aai-***` where `aai-***` is the AnotherAI API key
You can tell whether or not the agent uses a deployment by checking the model in the OpenAI completion call.
Any model with the format `/#/` is a WorkflowAI deployment.
```typescript
// This is a WorkflowAI deployment
const completion = await client.chat.completions.create({
model: "travel-assistant/#1/production",
});
// This is not a WorkflowAI deployment
const completion = await client.chat.completions.create({
model: "gpt-4o",
});
```
Uses deployments:
```sh
POST {{API_URL}}/v1/chat/completions
Authorization: Bearer aai-***
Content-Type: application/json
{
"model": "travel-assistant/#1/production",
# messages are optional here
...
}
```
Does not use deployments, calls a model directly
```sh
POST {{API_URL}}/v1/chat/completions
Authorization: Bearer aai-***
Content-Type: application/json
{
"model": "gpt-4o",
# messages are required here
...
}
```
If the agent uses a model directly, there is nothing to do. Changing the OpenAI client config will be enough.
If the agent uses a deployment, you will need to adjust the `deployment_id` to match the imported one, don't forget to prefix it with `anotherai/deployment/`.
# Tools
URL: /use-cases/tools.private
undefined
***
title: Tools
summary: Documentation for using tools with AI agents. Covers hosted tools like web search and defining custom tools for specific use cases.
--------------------------------------------------------------------------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
## What are tools?
Tools are a way to extend the capabilities of your AI agent.
Real-life use cases for tools:
* Search the web to gather the latest news about a company or topic.
* Browse a specific web page to extract information for a report.
* Execute a SQL query to fetch monthly sales data from a company database.
* Search in a vector database to find similar documents or images based on content.
* Send an email to a prospect after identifying information about their company online.
Tools have two forms:
| Type | Description |
| ---------------- | -------------------------------------------------------------------------------------------------------- |
| **Hosted Tools** | AnotherAI-built tools (web search, browser). Hosted tools do not require any code or engineering effort. |
| **Custom Tools** | Developer-defined tools. Custom tools will require you to write code to handle the tool calls. |
Here is a comparison of hosted tools and custom tools to help you decide which is best for your use case:
| **Hosted Tools** | **Custom Tools** |
| ------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| ✅ Works out of the box with no setup or code required.
✅ Billing is integrated.
❌ Limited to the tools available.
❌ No customization possible. | ✅ Fully customizable to your needs.
✅ Can integrate with any system.
✅ Billing can be integrated for your custom tool.
❌ Need to manage API keys and billing for each tool (when relevant).
❌ Requires engineering effort. |
## What hosted tools are available?
AnotherAI currently supports tools for:
* Web search: using Google and Perplexity
* Browser: using a text-based browser
## How to use hosted tools?
### From code
To add a hosted tool to your agent, find the tool name (`@tool`) and add it to your agent prompt.
For example, to use the `@google-search` tool, you can add the following to your agent prompt:
```python
messages = [
{
"role": "system",
"content": "Use @google-search to find the weather in {{location}}."
},
]
```
AnotherAI will automatically add the tool mentioned in the `tools` parameter sent to the LLM.
### From the Playground
\[TODO: adjust when the proxy playground is available with tools]
Tools can be added in the Playground by either:
1. Describing the use case to the playground chat agent
2. Under "Version" tap on the tools you want to enable.
\[TODO: video how to add a tool from the playground]
### Web search
AnotherAI supports two web search tools:
* `@google-search` makes a web search using Google
* `@perplexity-sonar-pro` makes a web search using Perplexity's Sonar Pro model
```python
messages = [
{
"role": "system",
"content": "Use @google-search to find the weather in {{location}}."
}
]
```
```python
messages = [
{
"role": "system",
"content": "Use @perplexity-sonar-pro to summarize the latest news about {{topic}}."
}
]
```
TODO: clarify that tools are used for web search
> Looking into prompt details for a run it seems there is some observability on the google search
> Do you have some doc about it ? What is generating the sweb search query ?
### Browser (text-only)
Use the tool `@browser-text` to extract text from a web page.
```python
messages = [
{
"role": "system",
"content": "Use @browser-text to extract the company name, number of employees, and email address from {{company_url}}."
}
]
```
### All tools
TODO: make a table with all the tools using the `/v1/tools/hosted` endpoint
### List hosted tools programmatically
You can list all the hosted tools programmatically:
* by calling the `list_hosted_tools` tool from the MCP server
* by calling the `/v1/tools/hosted` endpoint (no authentication required)
```bash
curl -X GET "https://api.anotherai.com/v1/tools/hosted" \
-H "accept: application/json" \
```
We're working on adding more tools, if you need any specfic tool, please open a discussion on [GitHub](https://github.com/anotherai/anotherai/discussions/categories/ideas) or [Discord](https://discord.com/invite/auuf8DREZh)
## Custom tools
### From code
AnotherAI is fully compatible with the `tools` parameter from the OpenAI `chat.completions` API, so you can use your existing code without modification.
For more details, refer to OpenAI's documentation on [tools and function calling](https://platform.openai.com/docs/guides/function-calling).
```python
tools = [{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get current temperature for a given location.",
"parameters": {
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "City and country e.g. Bogotá, Colombia"
}
},
"required": [
"location"
],
"additionalProperties": False
},
"strict": True
}
}]
completion = client.chat.completions.create(
model="gpt-4.1",
messages=[{"role": "user", "content": "What is the weather like in Paris today?"}],
tools=tools
)
print(completion.choices[0].message.tool_calls)
```
#### Supported parameters
\[TODO: @guillaq]
* `strict`
# Using End-User Feedback to Improve Agents
URL: /use-cases/user-feedback
Collect and integrate end-user feedback to improve your agents
***
title: Using End-User Feedback to Improve Agents
summary: Guide for incorporating end-user feedback into agent development through annotations and feedback collection.
description: Collect and integrate end-user feedback to improve your agents
---------------------------------------------------------------------------
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Card, Cards } from 'fumadocs-ui/components/card';
import { Callout } from 'fumadocs-ui/components/callout';
import { FlaskRound, MessageSquare } from 'lucide-react';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
# End-User Feedback
Incorporating end-user feedback into your agent's development process can be invaluable when creating effective agents. We recommend setting up user feedback in your product to be added directly to completions via annotations.
Below is an example of the process you might implement for collecting and incorporating end-user feedback:
### Set up user feedback collection in your product
This will look different for each product. Generally we recommend allowing the user to provide a comment, so that they can provide nuanced feedback. You may also want to allow your user to leave a score - for example 1-5 stars, or a thumbs up/down - in these cases the feedback would be added as a metric in the annotations.
Example of a user feedback component:
### Send user feedback to AnotherAI via the annotations endpoint
Ask your AI coding assistant to help integrate user feedback with AnotherAI:
```
Create a function that sends user feedback to AnotherAI via the annotations API.
The function should accept:
- completion_id from the AnotherAI response
- a numeric rating (e.g., 1-5 stars)
- a text comment from the user
- user identifier for tracking who submitted the feedback
Use the AnotherAI annotations endpoint to store this feedback so it appears
alongside the completion in the AnotherAI dashboard.
```
```python
# Example: Send user feedback as annotations via API
import requests
from datetime import datetime
# Configure your AnotherAI API endpoint and key
API_BASE_URL = "{{API_URL}}"
API_KEY = "your-api-key"
def submit_user_feedback(completion_id: str, rating: int, comment: str, user_id: str = "end_user"):
"""Submit user feedback as an annotation to AnotherAI"""
annotation = {
"id": f"feedback_{completion_id}_{datetime.now().timestamp()}",
"target": {
"completion_id": completion_id,
# key_path can be used to annotate specific fields
"key_path": None # Annotating the entire completion
},
"author_name": user_id,
"text": comment,
"metric": {
"name": "accuracy",
"value": rating # e.g., 1-5 star rating
},
"metadata": {
"source": "feedback_widget",
"additionalProp1": {}
}
}
response = requests.post(
f"{API_BASE_URL}/v1/annotations",
json=[annotation],
headers={
"Authorization": f"Bearer {API_KEY}",
"Content-Type": "application/json"
}
)
if response.status_code == 200:
print(f"Feedback submitted successfully for completion {completion_id}")
else:
print(f"Error submitting feedback: {response.text}")
return response
# Example usage after getting a completion
completion_id = "anotherai/completion/0198cd7c-2b1a-73b1-ce14-53da0b268569"
accuracy = 4
user_comment = "The response was helpful but could be more concise"
submit_user_feedback(completion_id, accuracy, user_comment)
```
### Create a custom view to easily review the feedback sent
Ask your AI assistant to create a view for you in AnotherAI to see all the feedback in one place.
```
Create a view that shows all completions of anotherai/agent/[your-agent-name] with annotations.
The view should display the completion ID, input, outputs, and the annotation
left on the completion.
```
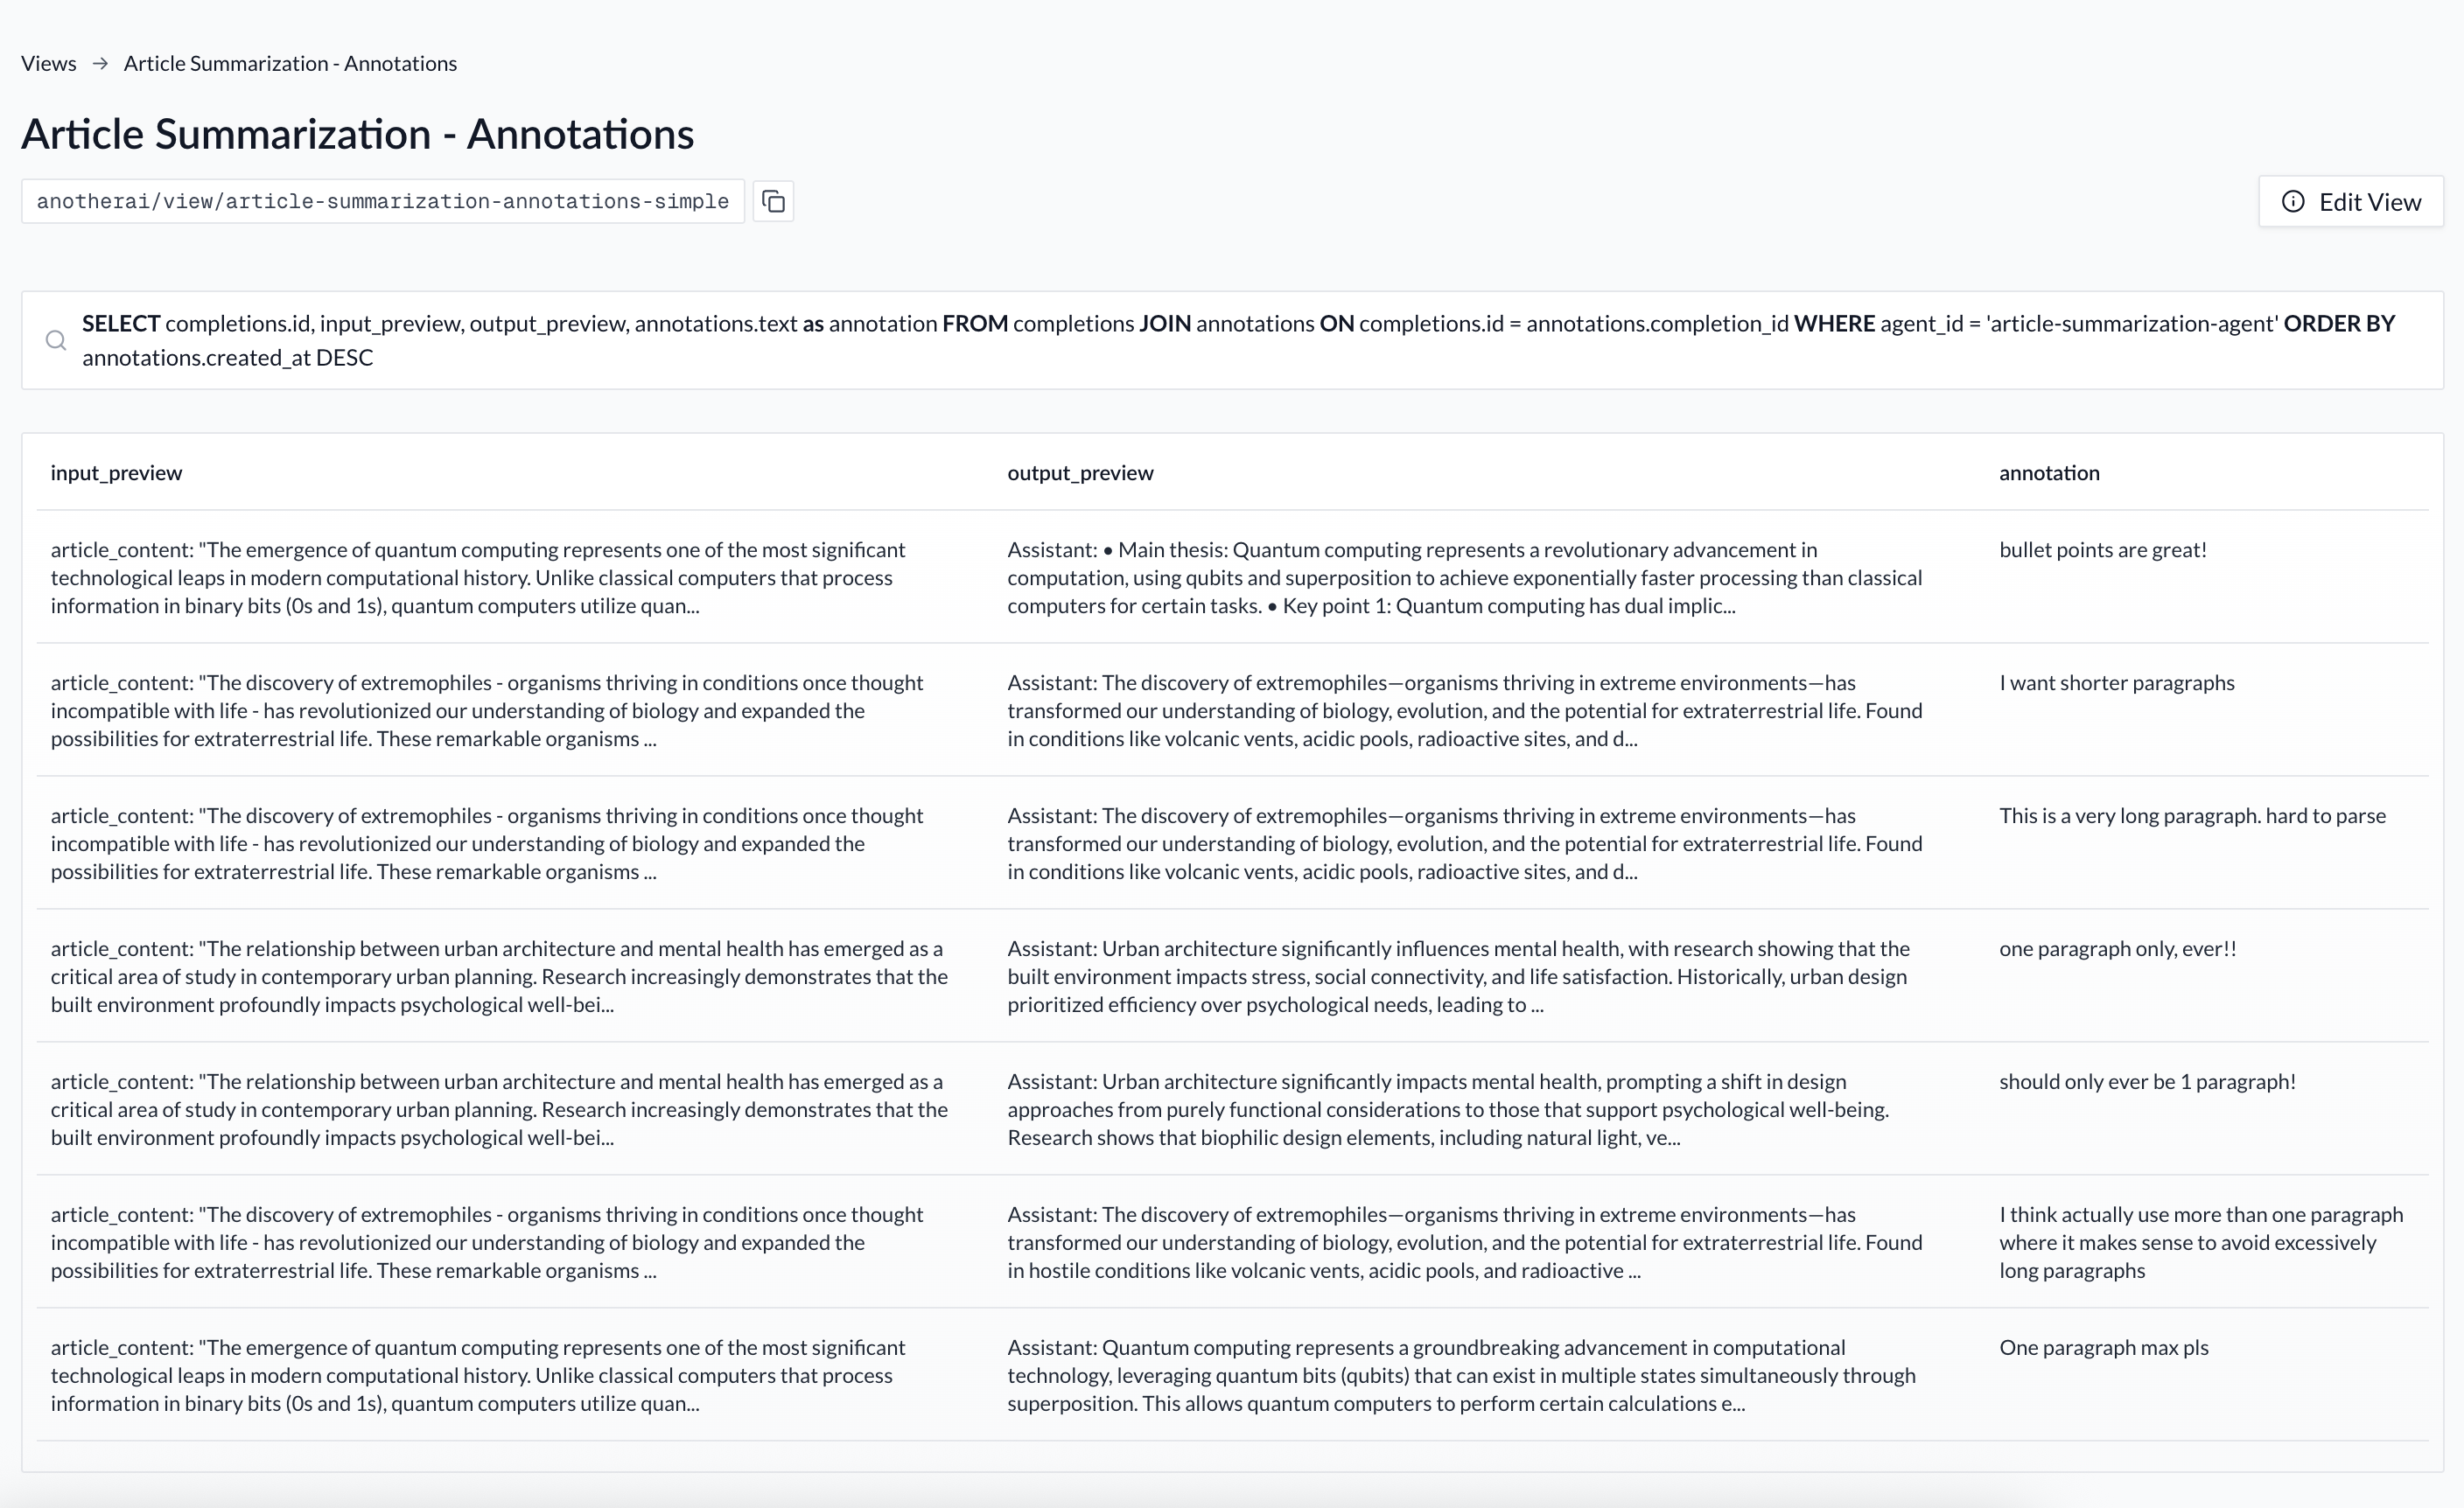
### Using Feedback for Improvements
Ask your AI assistant to analyze user feedback and suggest improvements:
```
Review the user feedback annotations for agent/email-rewriter from the last week
and suggest prompt improvements based on common complaints
```
Your AI assistant will query the annotations, identify patterns, and propose specific changes to improve user satisfaction.
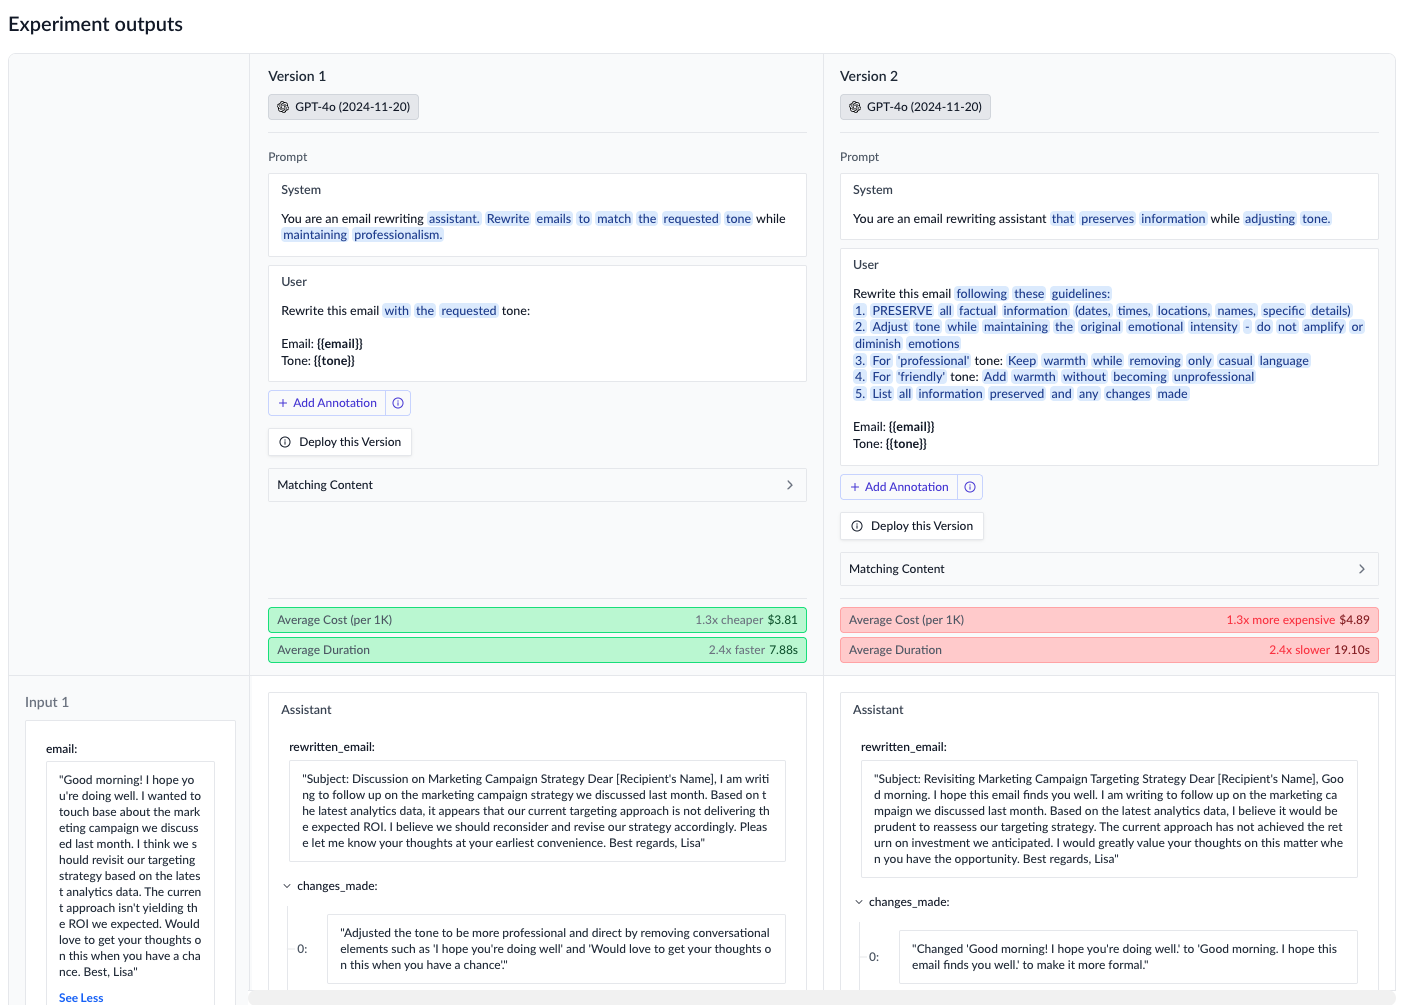
Once you've validated improvements through experiments, you can deploy them instantly without code changes using [deployments](/use-cases/fundamentals/deployments). This allows your team to rapidly iterate on agent improvements based on user feedback - no engineering bottlenecks, no deployment delays.
## Other Ways to Improve your Agents
}>
Systematically compare prompts, models, and parameters to find the optimal agent configuration
}>
Add specific feedback to completions and experiments to guide agent improvements
# Using Annotations to Improve Agents
URL: /use-cases/fundamentals/annotations
Learn how to use annotations to provide specific feedback on completions and experiments, enabling your AI coding agent to improve your agents based on real-world performance
***
title: Using Annotations to Improve Agents
summary: Use annotations to provide feedback and improve your AI agents
description: Learn how to use annotations to provide specific feedback on completions and experiments, enabling your AI coding agent to improve your agents based on real-world performance
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Callout } from 'fumadocs-ui/components/callout';
import { Card, Cards } from 'fumadocs-ui/components/card';
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { FlaskRound, MessageSquarePlus } from 'lucide-react';
## Annotations
When building and running AI agents in production, we wanted to build a way for you to leave clear feedback for your AI assistant to use to improve your agent. This is where annotations come in.
## When to Use Annotations: Manually Reviewing Production Completions
All completions from your agents are saved in the AnotherAI. You can access them at any time:
1. Open [https://anotherai.dev/](https://anotherai.dev/)
2. Select `Agents` from the left sidebar
3. Select the name of the agent you want to review completions for
4. Scroll down the page and select `View all Completions`
**Identifying completions that need improvements**
While not always the case, generally the review of production completions are triggered by:
* a feedback system set up to flag completions that need review (learn more about utilizing end-user feedback to improve your agents with [user feedback](/use-cases/user-feedback))
* a user or team member reporting an issue with a completion
You have a few options on how to locate the specific completion that is being referred to:
* **Describe the completion you're looking for to your AI assistant**: You can ask your AI assistant to locate the specific completion that match the description of the feedback you received.
* For example: `Find the completions with outputs that contain HTML opening an closing tags <> and `
* **Search using metadata**: If you have structured [metadata](/observability#metadata) like `customer_id` or `user_email`, you can ask your AI assistant to locate the specific completion that match the metadata.
* For example: `List all completions with customer_email = john@example.com`
* **Manually search on the web app**: If all else fails, all completions are visible on the web app, so you can manually search for the specific completion you're looking for. To review all completions for a given agent:
* Open [https://anotherai.dev/](https://anotherai.dev/)
* Select `Agents` from the left sidebar
* Select the name of the agent you want to review completions for
* Scroll down the page and select `View all Completions`
**Annotate individual completions with your feedback**
* To annotate entire completions: there is a text box on the top right of the screen where you can add your feedback about the content of the completion.
* To annotate individual fields within the output, hover over the field you want to annotate and select the "Add Annotation" button.
You can learn more about the type of content you may want to add in annotations [here](#what-sort-of-content-can-be-added-in-annotations)
**Using your AI coding agent to improve your agent based on annotations**
After you've added annotations to agent completions or an experiment, all you tell your AI coding agent that you've added annotations and ask it to use your feedback to improve your agent. Just specify the agent - and optionally the specific completions - that you added the annotations to, and your agent will take care of the rest. For example:
```
Adjust anotherai/agent/calendar-event-extractor based on the annotations
that have been added in anotherai/completion/01994ea5-59d3-7396-8b8f-5531355cf151,
anotherai/completion/01994e86-5861-715c-7078-1b1d4e6440b1, and
anotherai/completion/01994e86-2bef-7227-cea5-5b82f56f7bc7.
```
Your AI coding assistant will use the annotations to improve the agent.
**Gain insights about your agent's performance with annotations (optional)**
You can also leverage annotations to provide you with insights about your agent's performance. For example you can ask your AI coding agent to do the following based on the annotations you've added:
**Create Performance Reports**
```
Provide a report summarizing main themes in annotations left on completions of calendar-event-extraction
that used GPT-5.
```
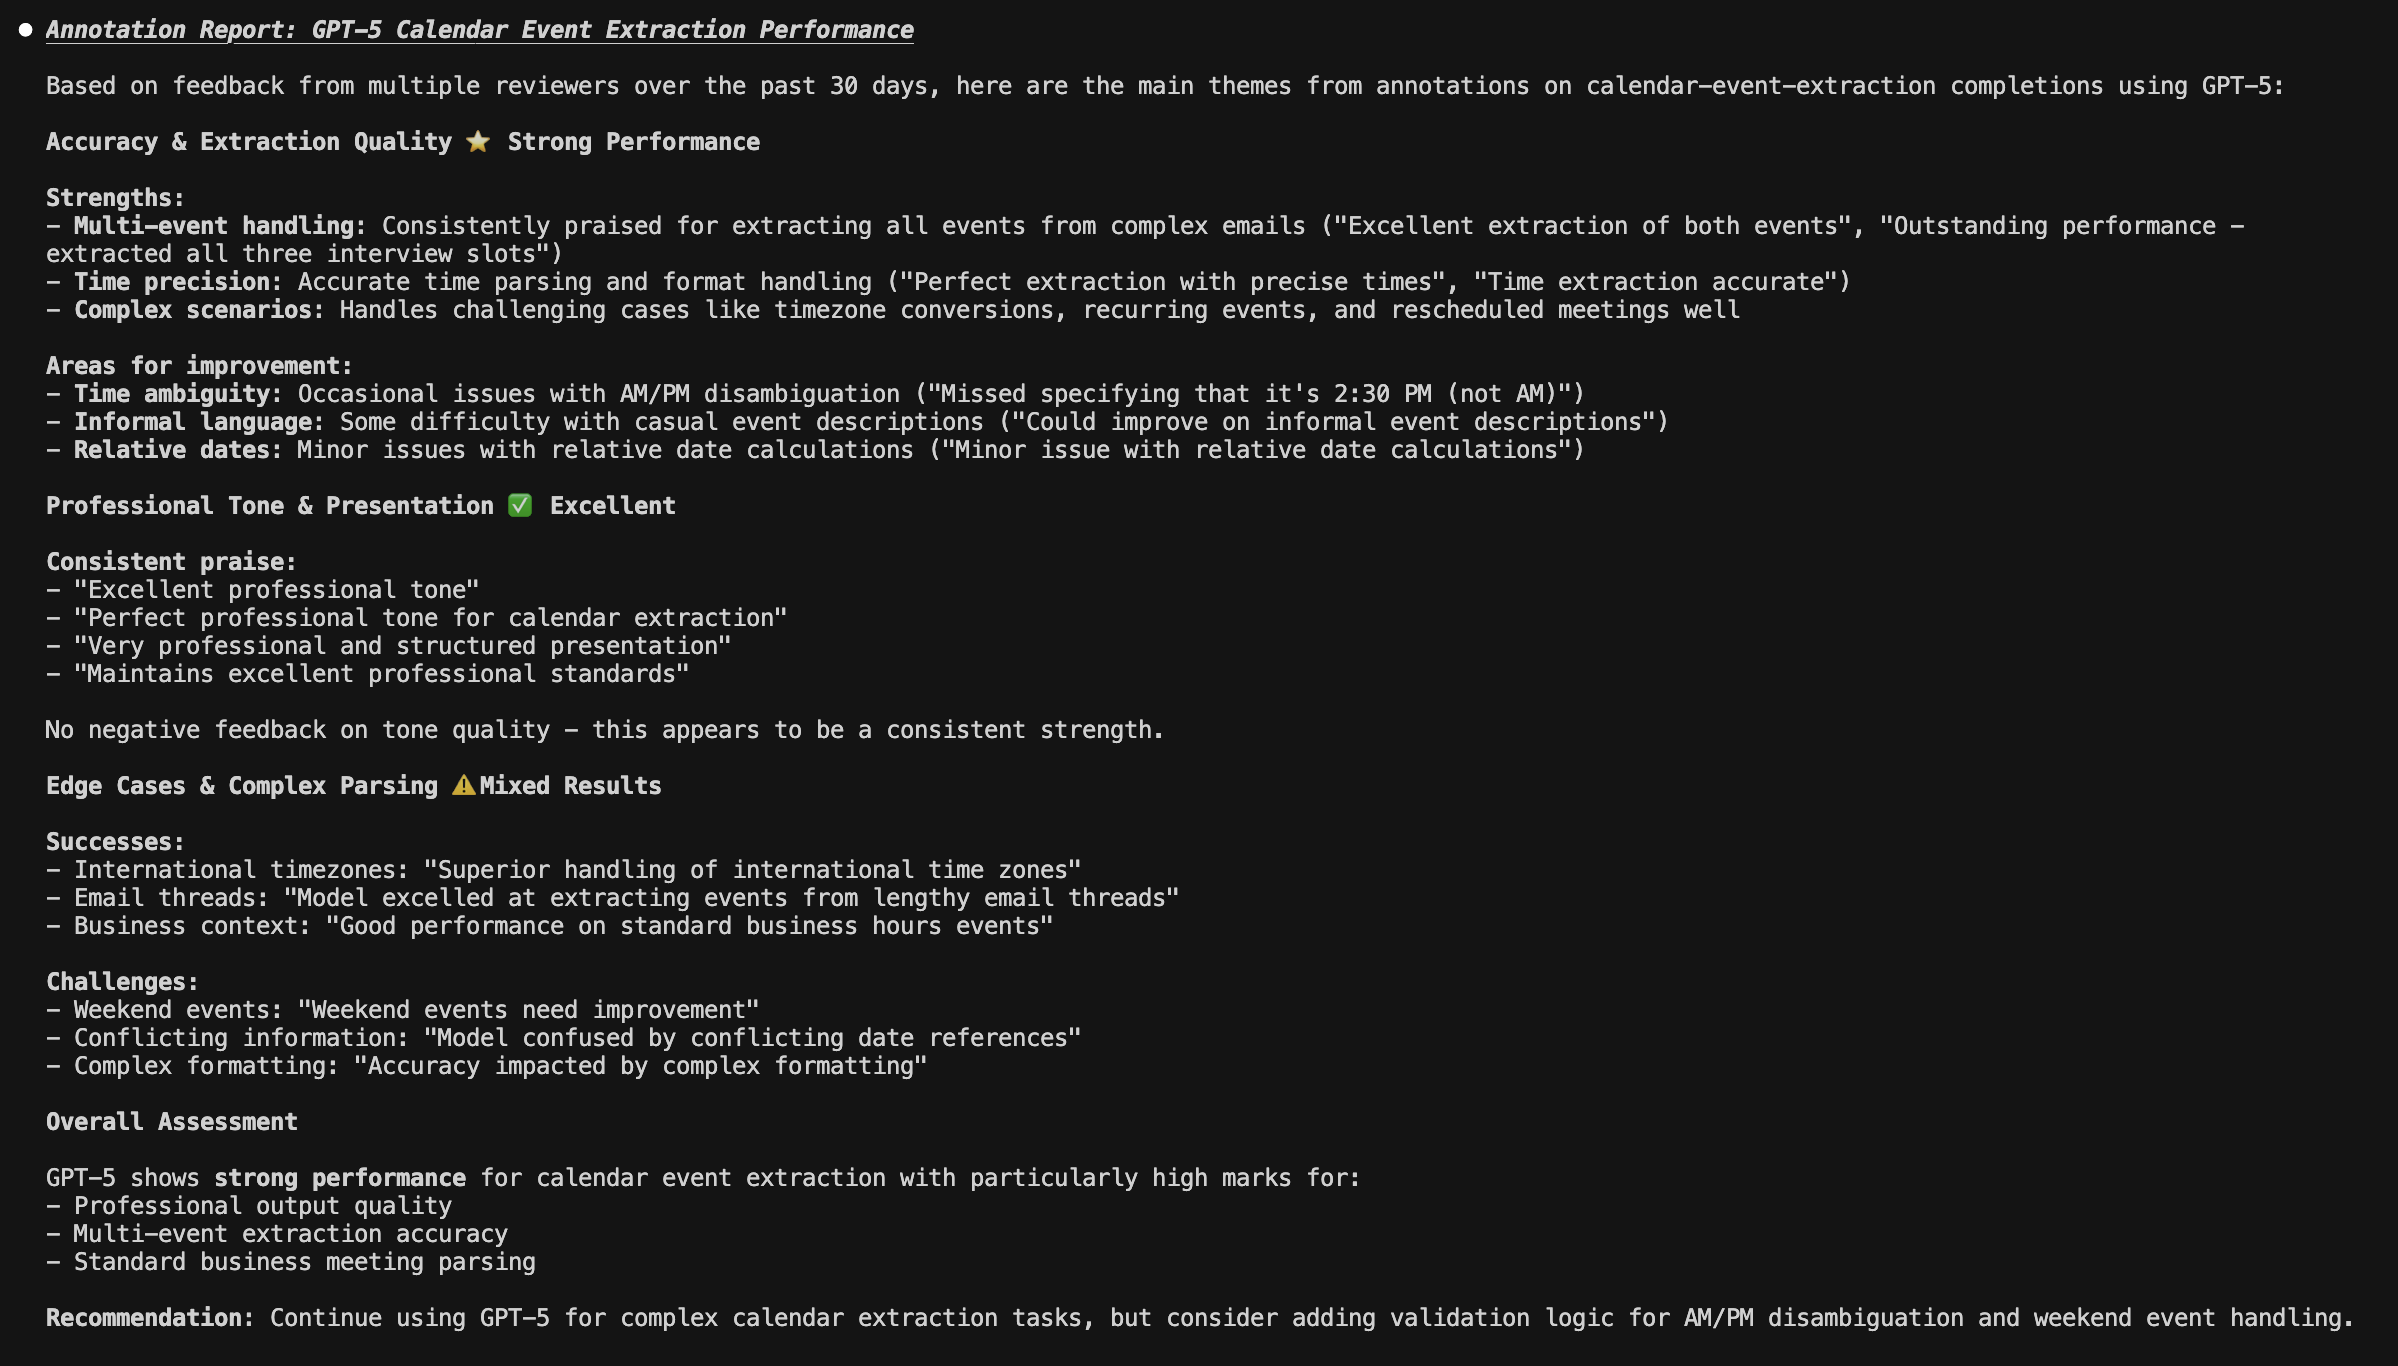
**Compare Model Performance**
```
Which model has the best tone overall, based on annotations?
```
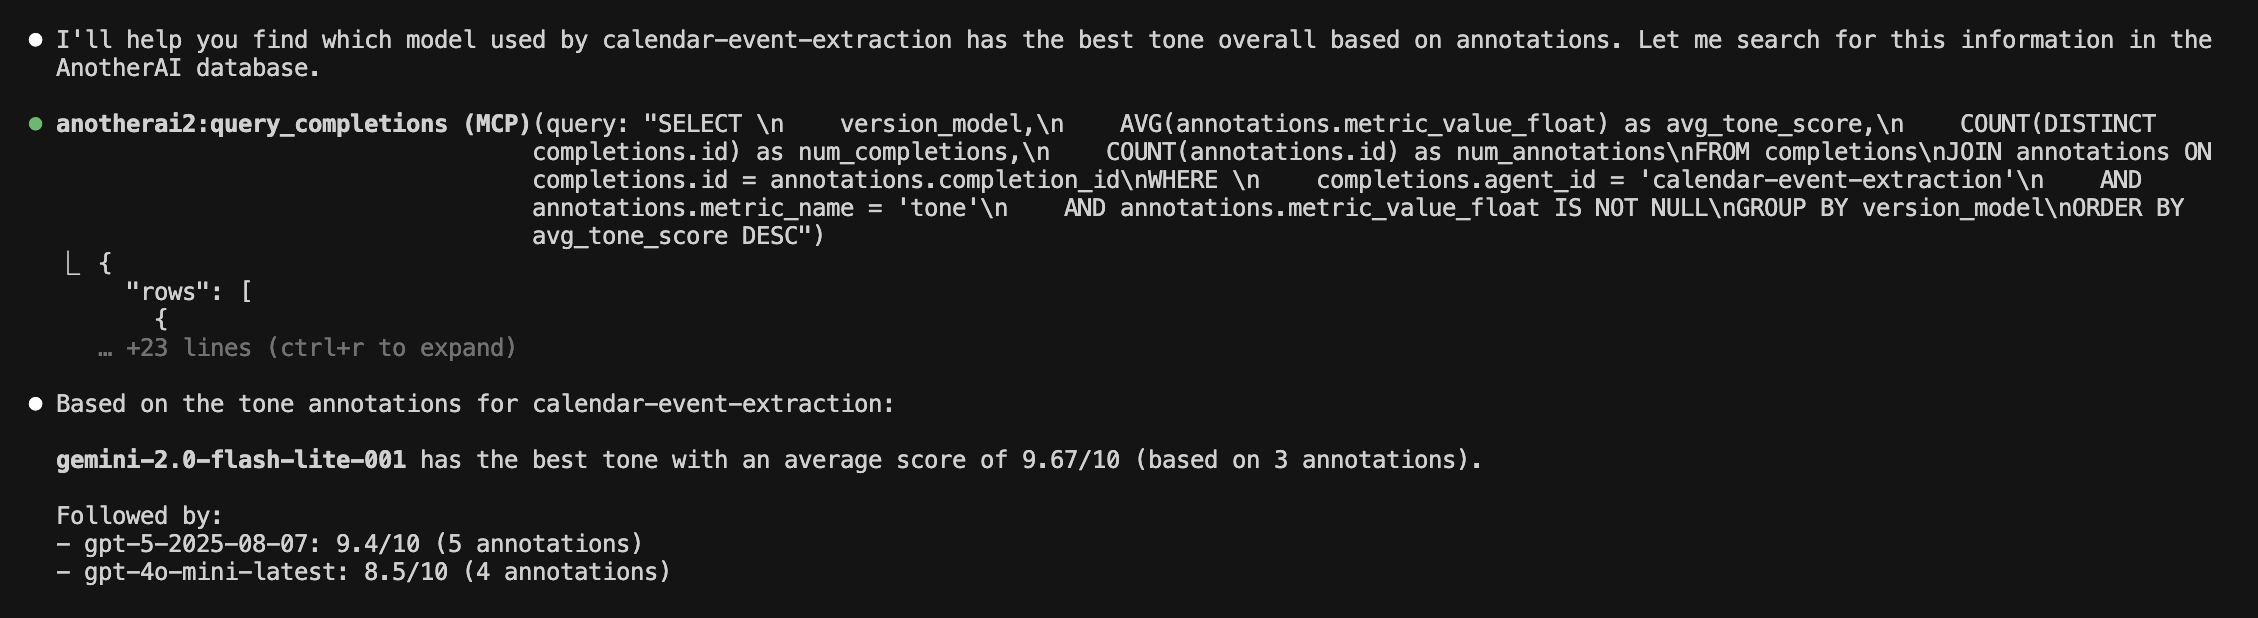
## What sort of content can be added in annotations?
Annotations can contain feedback about:
* What is working (e.g. "The event descriptions are clear and the ideal length")
* What is not working (e.g. "The description of the events are too verbose, and this model missed out on extracting the updated time of the team sync")
Using text-based annotations allow you to provide thorough, nuanced feedback in cases where a completion's quality isn't straightforward. For example:
1. If you don't consider a completion as all good or all bad, you can highlight parts of a completion that are working well and parts that are not.
2. You can add specific thoughts and context to a completion so your coding agent will have an in-depth understanding of the completion's quality.
However if you would like to incorporate more quantitative ratings, you can do that by using scores, which are described below!
Here is what it looks like when annotations are present on a completion:
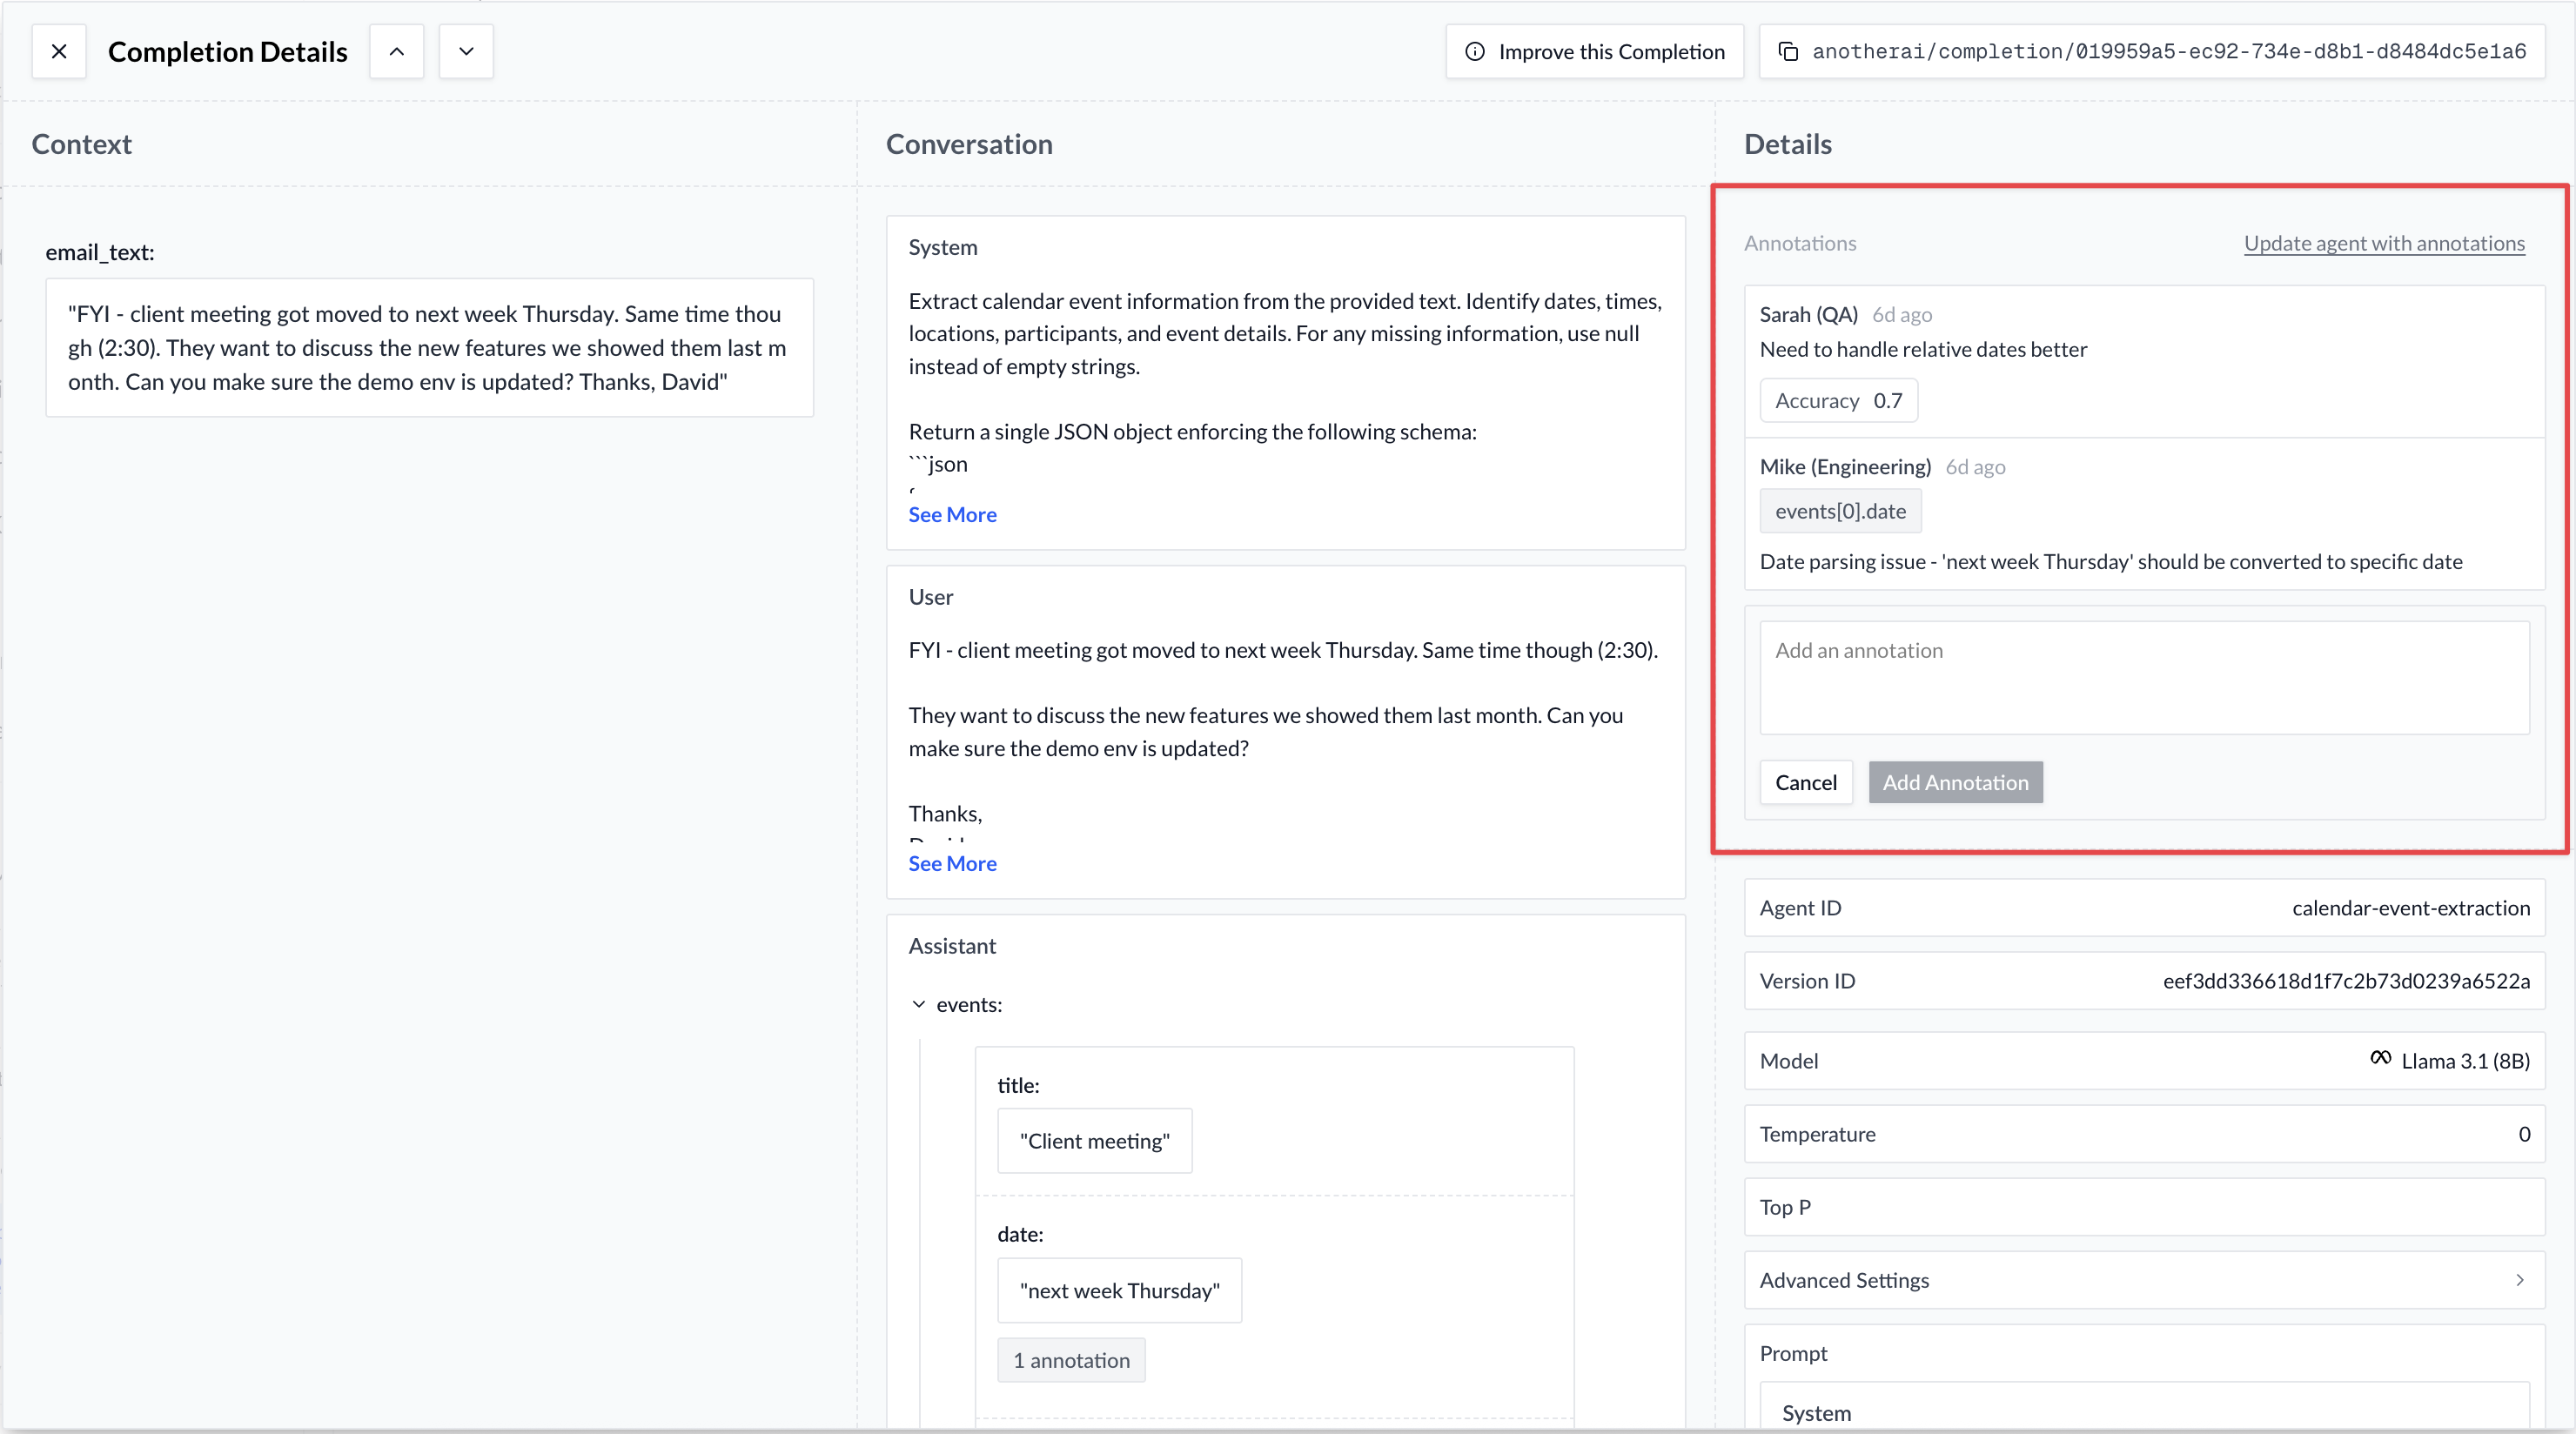
## Other Methods for Improving Agents with Annotations
While using annotations when manually reviewing production completions is the most common use case, we would be remiss if we didn't mention some other methods for improving your agents with annotations:
### Manually Annotating Experiment Results
* To annotate entire completions: locate the "Add Annotation" button under each completion's output. Select the button to open a text box where you can add your feedback about the content of that specific completion.
* To annotate individual fields within the output, hover over the field you want to annotate and select the "Add Annotation" button.
* You can also add annotations to the model, prompt, output schema (if structured output is enabled for the agent), and other parameters like temperature, top\_p, etc.
### Using AI Agents to Add Annotations
You can also ask your preferred AI coding agent to review completions and add text-based, scores, or both types of annotations on your behalf. To ensure that your agent is evaluating the completions in the way you want, it's best to provide some guidance. For example:
```
Review the completions in anotherai/experiment/019885bb-24ea-70f8-c41b-0cbb22cc3c00
and leave scores about the completion's accuracy and tone. Evaluate accuracy based on
whether the agent correctly extracted all todos from the transcript and evaluate tone
based on whether the agent used an appropriately professional tone.
```
Your agent will analyze the completions and add appropriate annotations. In the example above, your agent will add an annotation with the scores "accuracy" and "tone" and assigned appropriate values for each, based on the content of the completion.
## Other Ways to Improve your Agents
}>
Systematically compare prompts, models, and parameters to find the optimal agent configuration
}>
Collect and integrate feedback from your end users to continuously improve your agents
# Building a New Agent
URL: /use-cases/fundamentals/building
Step-by-step guide to creating, configuring, and deploying AI agents using AnotherAI
***
title: Building a New Agent
summary: Learn how to build AI agents with AnotherAI's unified API and observability features
description: Step-by-step guide to creating, configuring, and deploying AI agents using AnotherAI
-------------------------------------------------------------------------------------------------
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
**Our goal with building with AnotherAI is to turn your AI coding assistant into your AI engineer.** Instead of manually testing different models and prompts, AnotherAI gives your AI coding agent the tools to automatically find the optimal configuration for your specific use case. Here is how to get started building a new agent with AnotherAI.
Before you begin, make sure you have the AnotherAI MCP server configured with your AI assistant. Your AI assistant needs this connection to create agents, run experiments, and manage deployments. See the [Getting Started guide](/getting-started) for setup instructions.
Need an extra hand with building agents? We're happy to help. Reach us at [team@workflowai.support](mailto:team@workflowai.support) or on [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
## Specifying Agent Behavior and Requirements
The easiest way to create a new agent is to ask your preferred AI assistant to build it for you.
#### Basic Agent Creation
Start by describing what your agent should do:
```
Create a new AnotherAI agent that can summarize emails
```
#### Adding Performance Requirements
If you have other criteria or constraints for your agent, you can include them in your prompt and your AI assistant will use AnotherAI to help you optimize for them.
**For customer-facing agents that need fast responses:**
```
Create a new AnotherAI agent that summarizes emails where at least half of the responses complete in under 1 second
```
**For high-volume agents that need to be cost-effective:**
```
Create a new AnotherAI agent that summarizes emails that costs less than $5 for 1000 requests
```
Your AI assistant will be able to construct the agent's code, and will be able to use AnotherAI to access 100+ different models to find the best configuration to help you achieve your goals.
#### Adding Metadata
You can also add custom metadata to your agents to help organize and track them. Common use cases include:
* **Workflow tracking**: include a trace\_id and workflow\_name key. (Learn more about workflows [here](/use-cases/connecting-agents))
* **User identication**: include a user\_id customer\_email key.
```
Create a new AnotherAI agent that summarizes emails and include a customer_id metadata key.
```
**Agent IDs in Metadata**
When your AI assistant creates an agent, it automatically assigns an `agent_id` in the metadata. In code it would look something like `"agent_id": "email-summarizer"`, and in the AnotherAI web app it would look like `anotherai/agent/email-summarizer`. The agent ID helps AnotherAI organize completions by agent and enables you to reference specific agents when chatting with your AI assistant.
You might ask your AI assistant a question about a specific agent, like:
```
How much is anotherai/agent/email-summarizer costing me this month?
```
(if you're curious about costs of agents, see our [metrics](/use-cases/fundamentals/metrics) page!)
If you prefer to build manually or want to understand the configuration details, see our [OpenAI SDK Integration](/integrations/openai) guide.
## Testing your Agent
As part of the process of creating your agent with AnotherAI, your AI assistant will automatically create an initial experiment to test your agent's performance. Experiments allow you to systematically compare each of these different parameters of your agent to find the optimal setup for your use case across one or more inputs. You can use experiments to:
* Compare performance across different models (GPT-4, Claude, Gemini, etc.)
* Test multiple prompt variations to find the most effective approach
* Optimize for specific metrics like cost, speed, and accuracy.
In the cases above where certain constraints were specified, your AI assistant will automatically create several versions of your agent to assess which one matches your requirements best.
For the prompt requesting a fast agent:

For the prompt requesting a cost-effective agent:

If you find there is additional criteria you want to test, you can always ask your AI assistant to create additional experiments. The most common parameters to experiment with are prompts and models, however you can also experiment with changes to other parameters like temperature.
### Prompts
Comparing different prompts is one of the most effective ways to improve your agent's performance. Small changes in wording, structure, or examples can lead to significant improvements. If you notice an issue with an existing prompt, you can even ask your AI assistant to generate prompt variations to use in the experiment.
Example:
```
Look at the prompt of anotherai/agent/email-rewriter and create an experiment in AnotherAI
that compares the current prompt with a new prompt that better emphasizes adopting
the tone lists in the input
```
Your AI assistant will create the experiment and give you an initial analysis of the results and well as a URL to view the results in the AnotherAI web app.
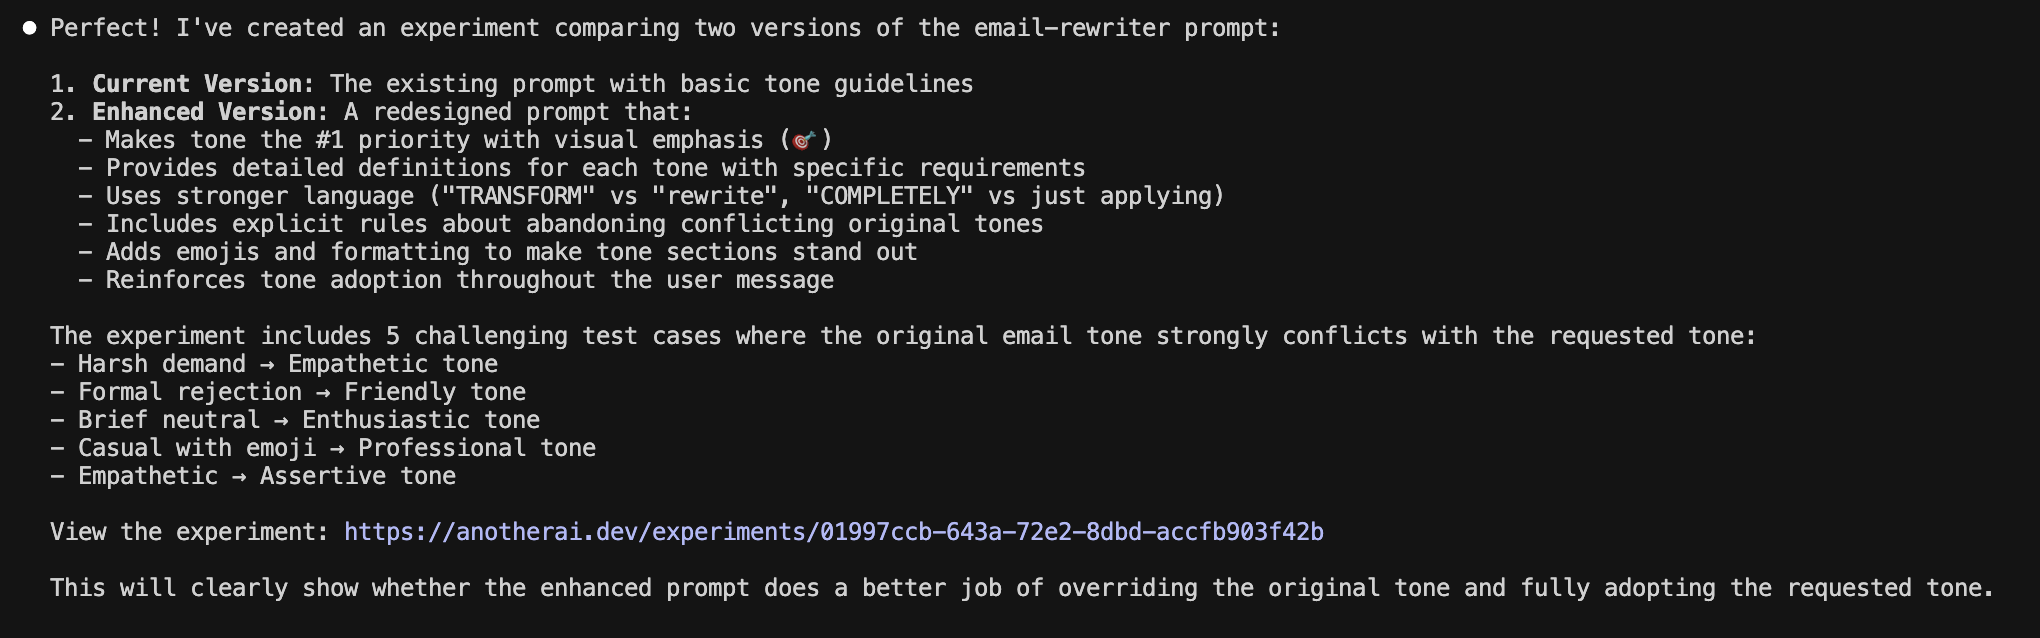
You can use the provided URL to view the results in the AnotherAI web app to perform manual analysis of the results.

### Models
Different models excel at different tasks. AnotherAI supports over 100 different models, and experiments can help you choose the right model for your agent, depending on its needs.
Example:
```
Create an AnotherAI experiment to help me find a faster model for anotherai/agent/email-rewriter,
but still maintains the same tone and verbosity considerations as my current model.
```
If you have a specific model in mind that you want to try - **for example, a newly released model** - you can ask your AI assistant to help you test that model against your existing agent version. You can always request that your AI assistant uses inputs from existing completions, to ensure that you're testing with real, production data.
Example:
```
Can you retry the last 5 completions of anotherai/agent/email-rewriter and compare the outputs with
GPT 5 mini?
```
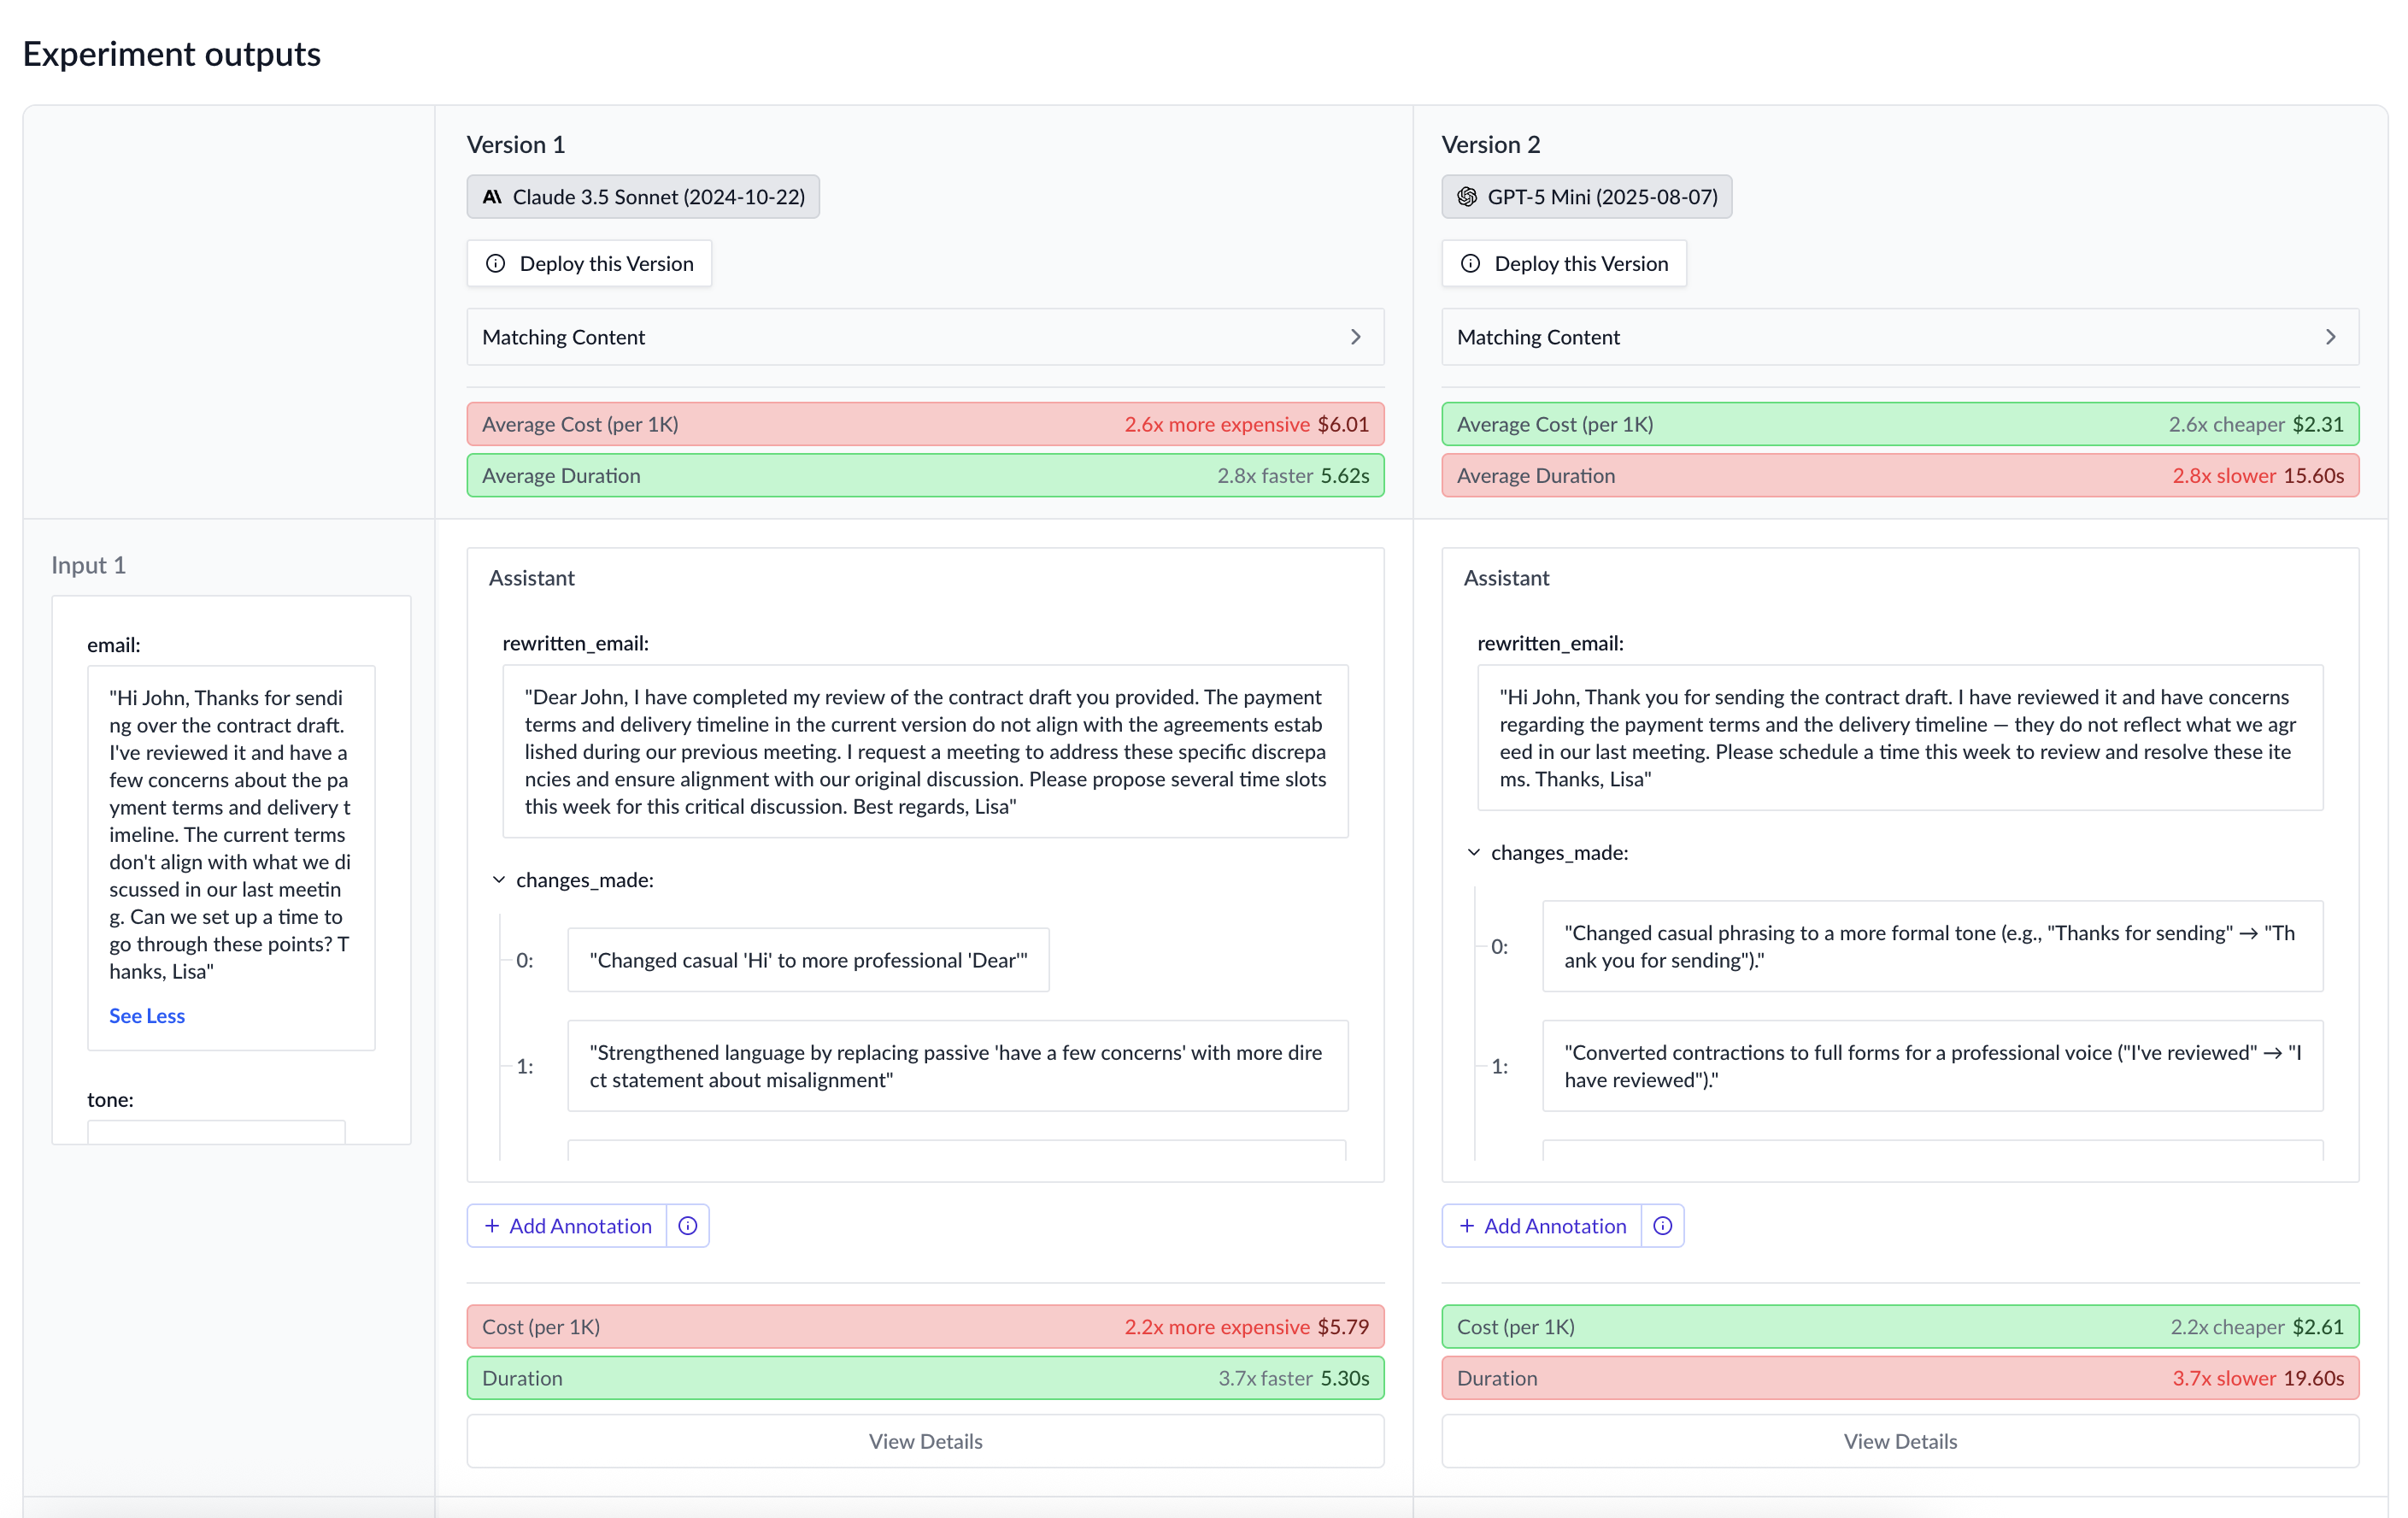
### Other Parameters
Beyond prompts and models, fine-tuning other parameters can impact your agent's behavior and output quality. Temperature in particular can have a significant impact on the quality of the output.
Temperature is the most important parameter to experiment with after prompts and models. It controls the randomness of the model's output:
* **Low temperature (0.0 - 0.3)**: More deterministic, consistent outputs. Best for:
* Data extraction tasks
* Classification
* Structured output generation
* Tasks requiring high accuracy and repeatability
* **Medium temperature (0.4 - 0.7)**: Balanced creativity and consistency. Best for:
* General purpose assistants
* Question answering
* Summary generation
* **High temperature (0.8 - 1.0)**: More creative, varied outputs. Best for:
* Creative writing
* Brainstorming
* Generating diverse options
Example:
```
Test my email-rewriter agent with temperatures 0.2, 0.5, and 0.8 to find
the right balance between creativity and professionalism
```
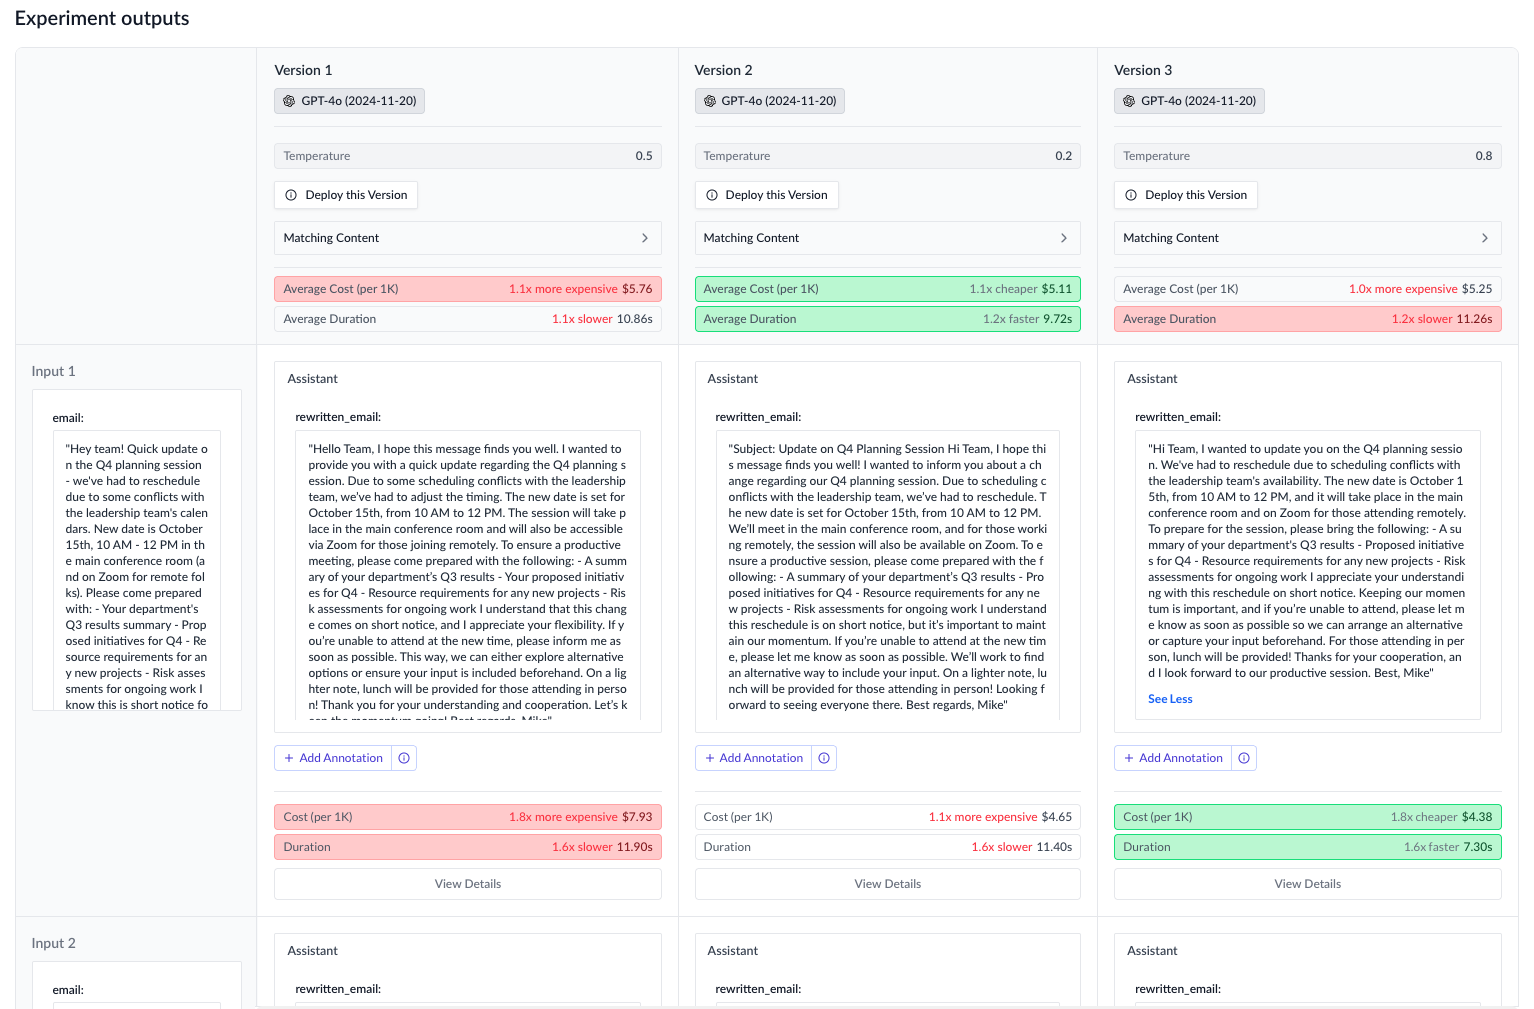
### Managing Large Experiments with Claude Code
If you're testing an agent that has a large system prompt and/or very long inputs, you may encounter token limit issues with the `get_experiment` MCP tool that impacts Claude Code's ability to provide accurate insights on your agent.

In this case, you can manually increase Claude Code's output token limit.
**To set up permanently for all terminal sessions:**
For zsh (default on macOS):
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.zshrc && source ~/.zshrc
```
For bash:
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.bashrc && source ~/.bashrc
```
**For temporary use in current session only:**
```bash
export MAX_MCP_OUTPUT_TOKENS=150000
```
Notes:
* If you forget or don't realize you need to set a higher limit, you can quit your existing session, run the command to increase the limit, and then use `claude --resume` to continue your previous session with the increased limit applied.
You can learn more about tool output limits for Claude Code in their [documentation](https://docs.claude.com/en/docs/claude-code/mcp#mcp-output-limits-and-warnings).
## Adding Feedback to your Experiments
When reviewing the results of experiments, you can add feedback (annotations) to help your AI coding agent understand what is working and what is not. Your AI coding agent can then use this feedback to create additional experiments with improved versions of your agent.
You can add annotations to completions from experiments directly in AnotherAI web app. Annotations can be added for both entire completions and individual fields within the output (when the output is structured).
To add annotations:
When your coding agent creates an experiment for you, it will automatically send you a URL to the experiment. Use that URL to open the page for the experiments.
Or if adding annotations to an experiment later:
* Go to [anotherai.dev/experiments](https://anotherai.dev/experiments)
* Select the experiment you want to add annotations to
Locate the "Add Annotation" button under each completion's output. Select the button to open a text box where you can add your feedback about the content of that specific completion.
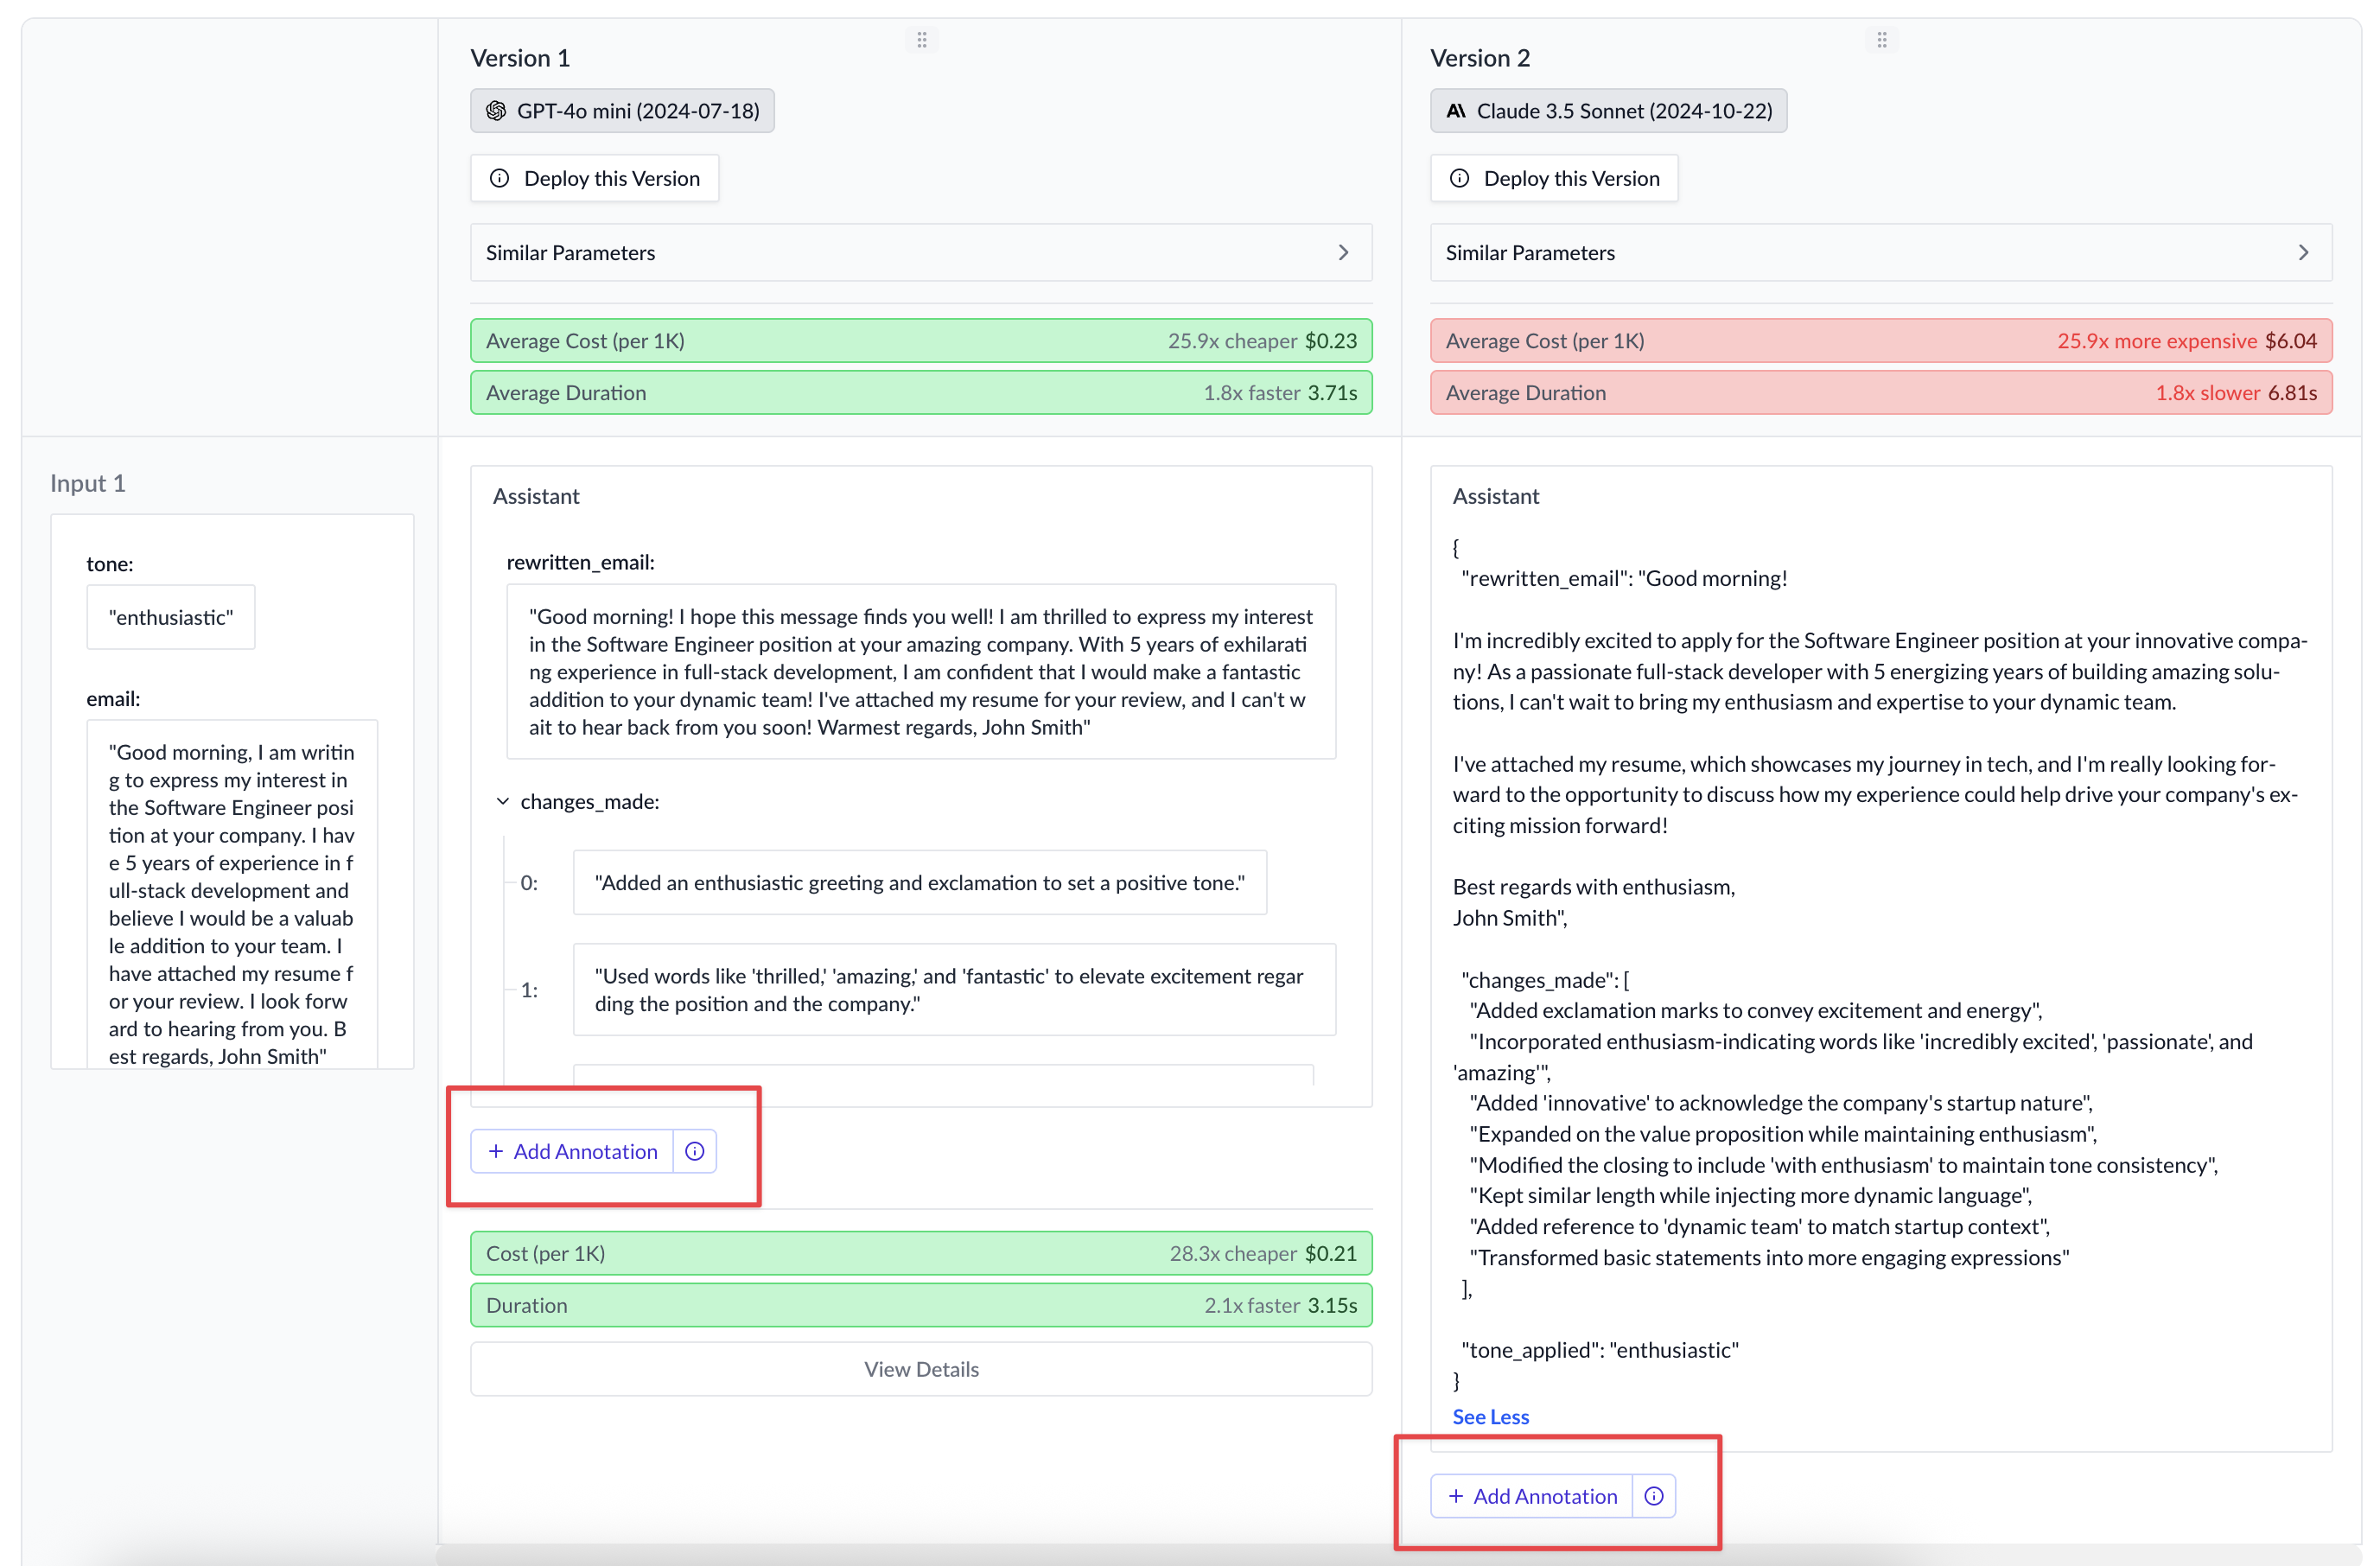
To annotate individual fields within the output, hover over the field you want to annotate and select the "Add Annotation" button.
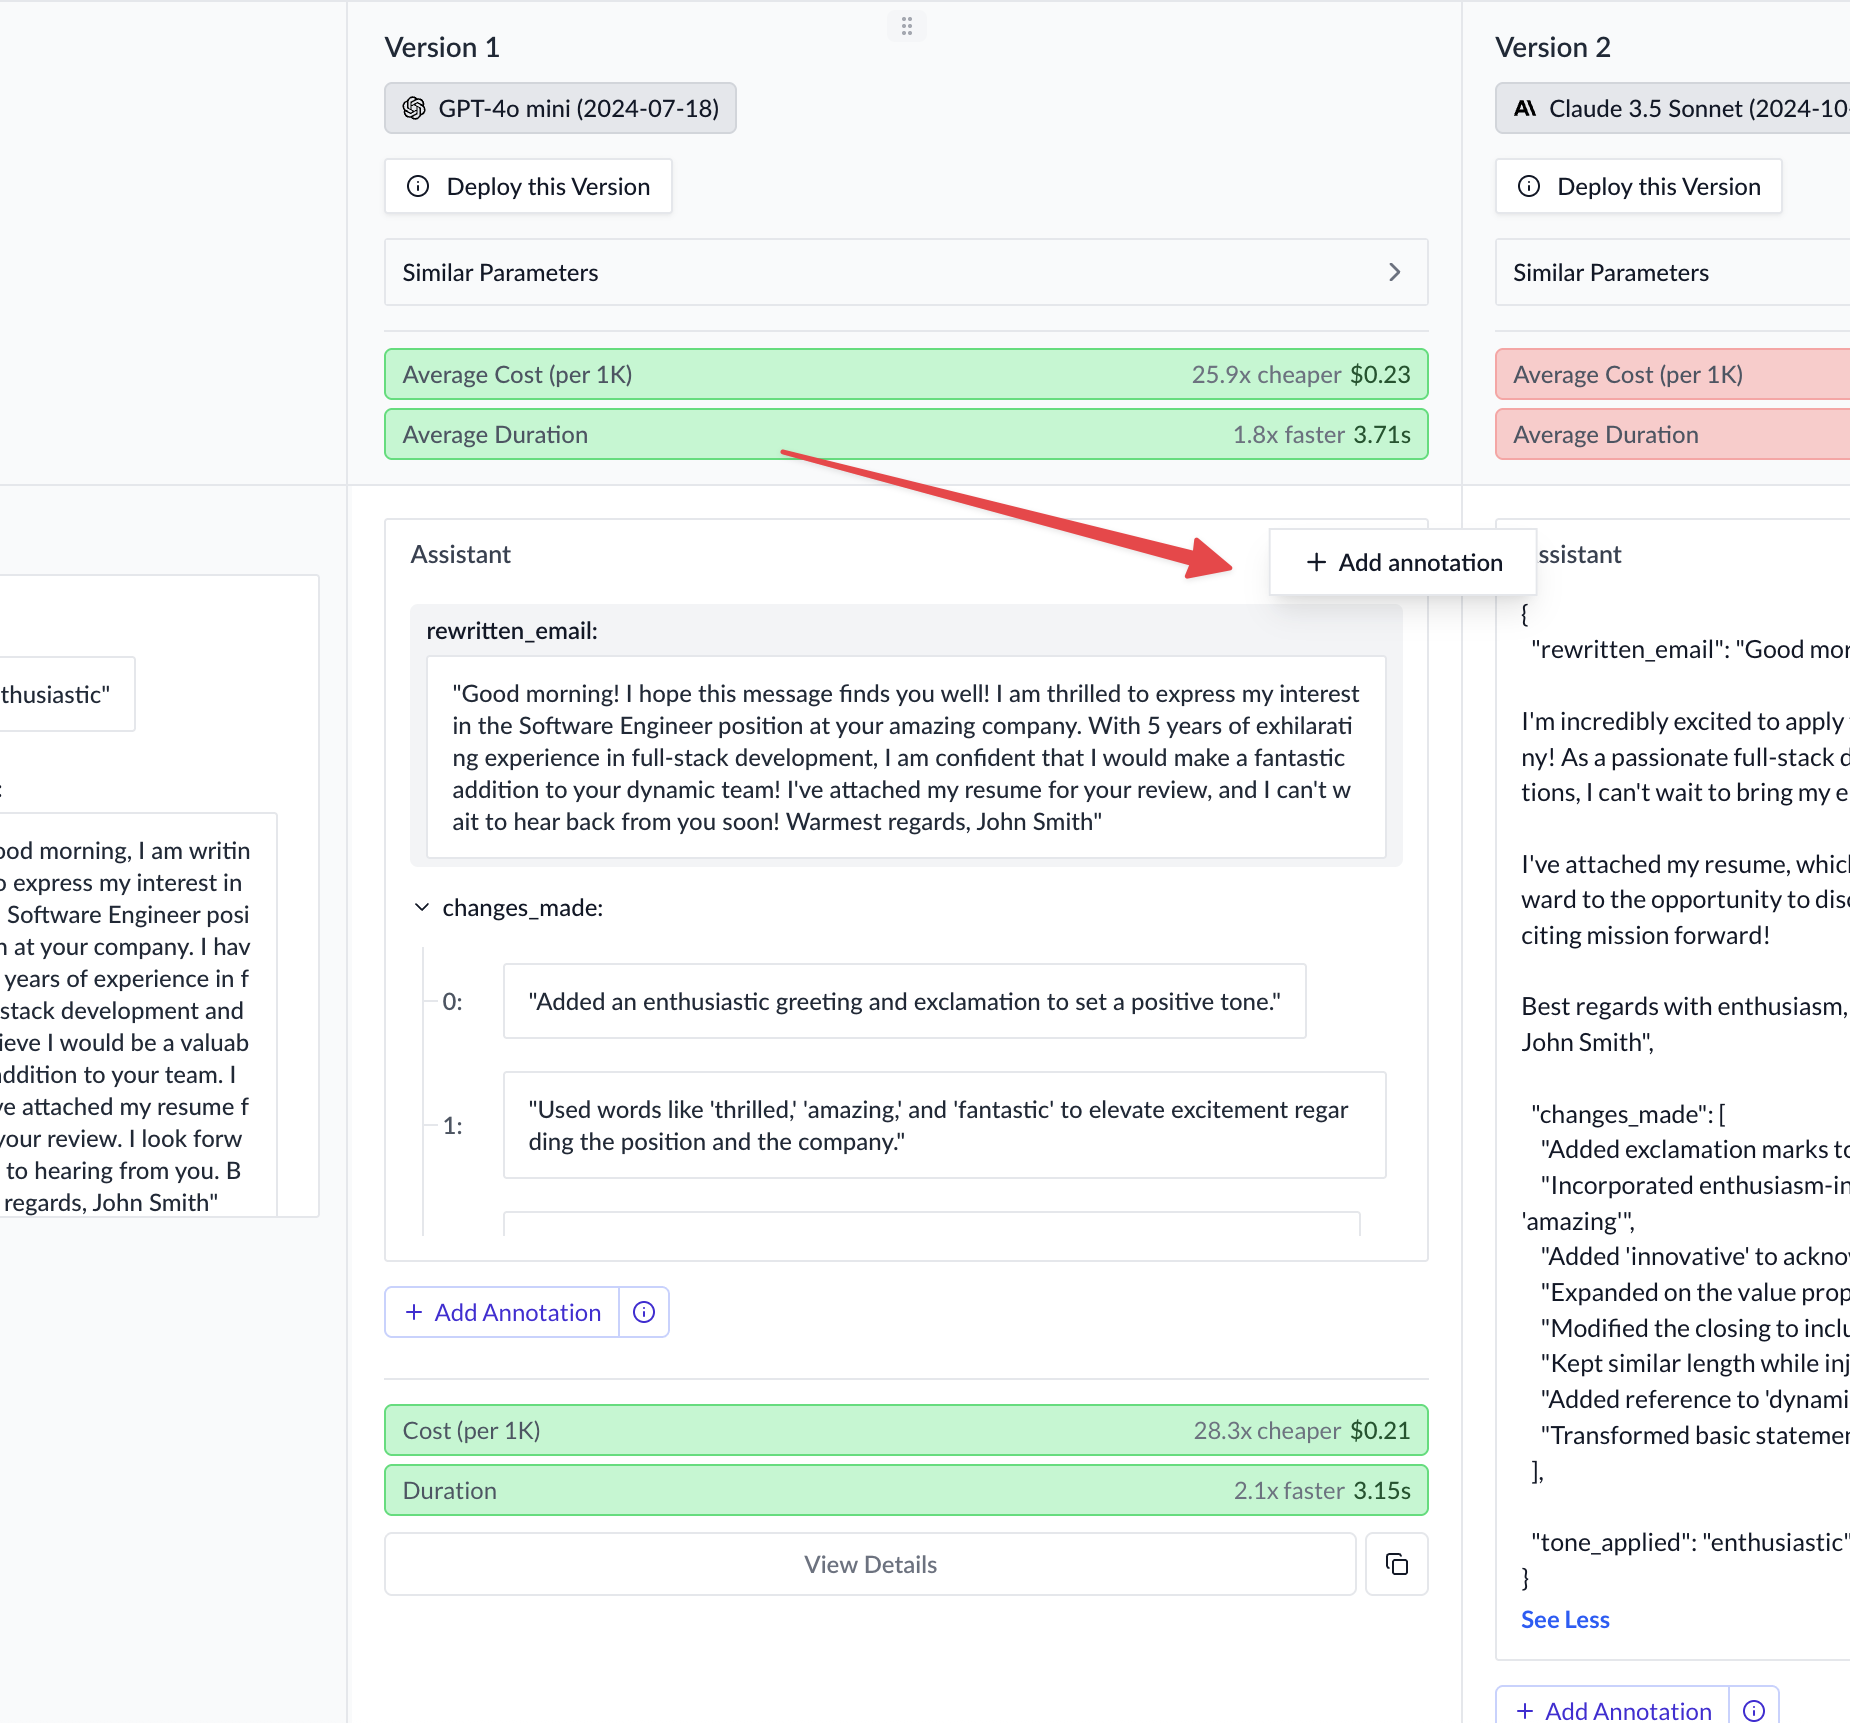
You can also add annotations to the model, prompt, output schema (if structured output is enabled for the agent), and other parameters like temperature, top\_p, etc.
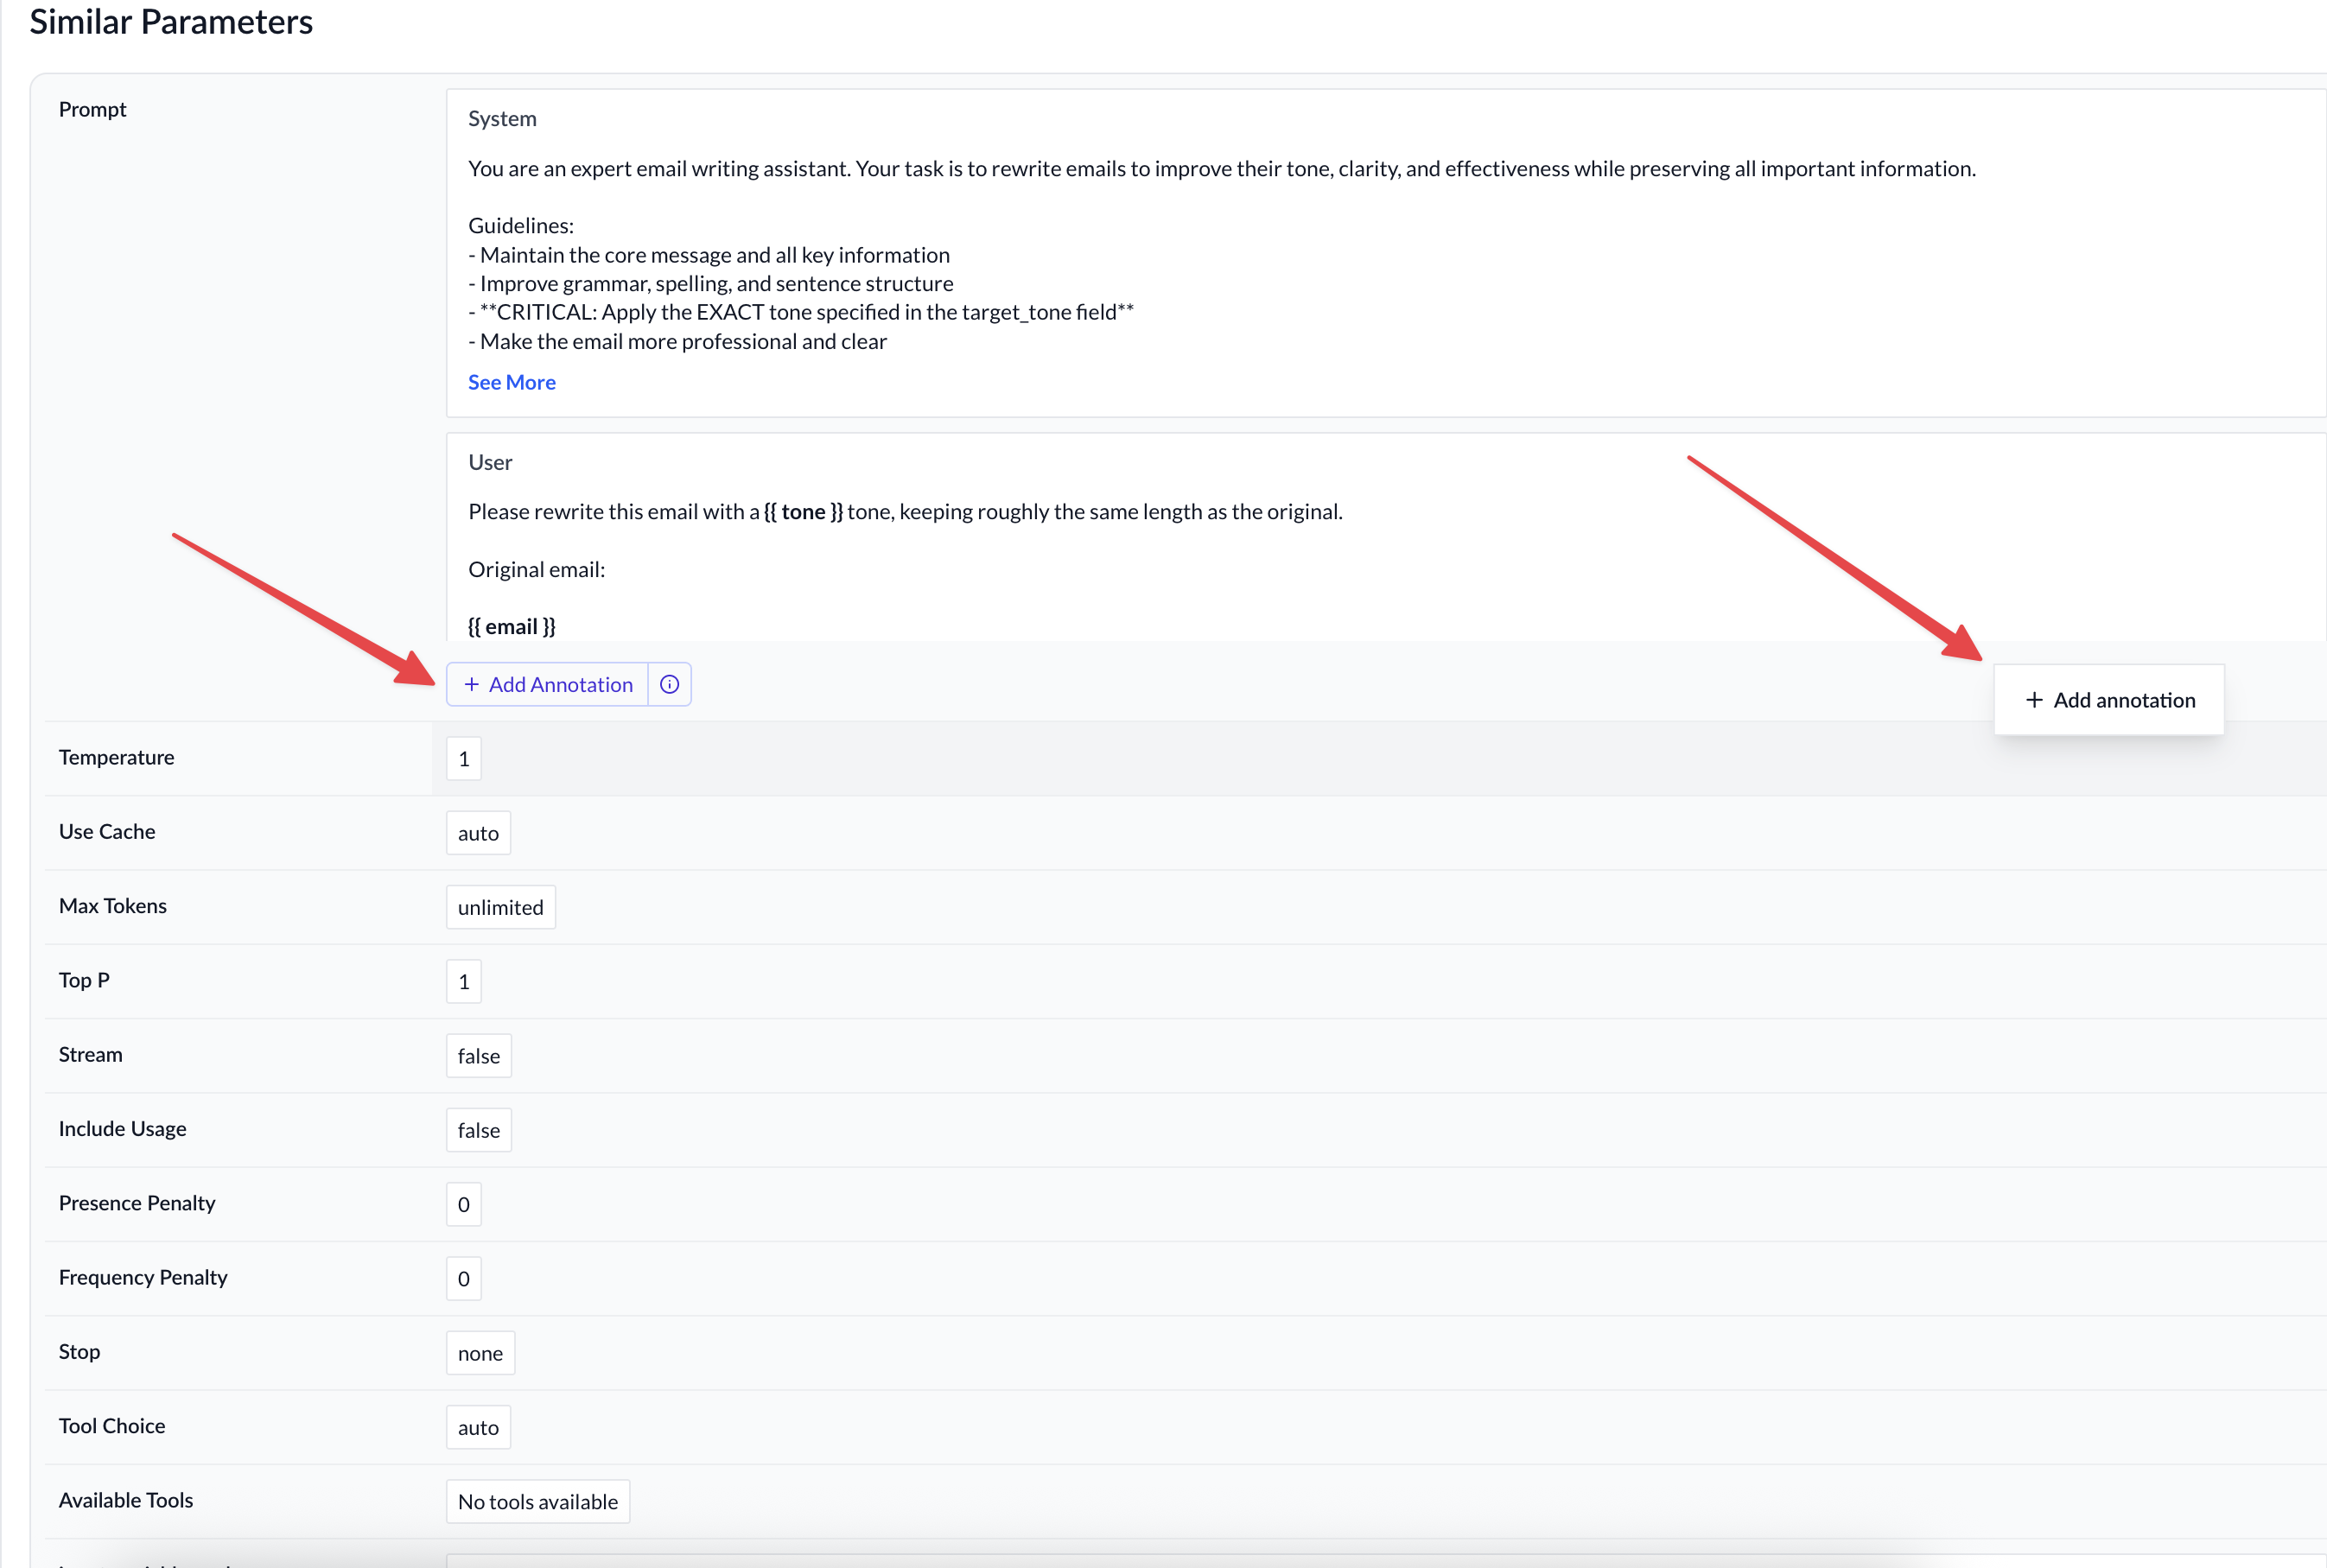
Add specific feedback about what's working and what isn't. For example:
* "Perfect tone match - captured the enthusiastic style requested. All responses should be this high quality."
* "Too formal - should be more conversational for this email type"
* "The rewrite is too long - original was concise and this adds unnecessary words"
Once you've added annotations, ask your AI assistant to review them and improve your agent:
```
Review the annotations I added in anotherai/experiment/01997ccb-643a-72e2-8dbd-accfb903f42b
and update the prompt to address the issues I identified.
```
Your AI assistant will analyze your feedback and create an improved version of your agent based on your specific guidance.
To learn more about how annotations can be used to improve your agent, see our [Improving an Agent with Annotations](/use-cases/fundamentals/annotations) page.
## Next Steps
* [Learn more about different types of experiments](/use-cases/fundamentals/experiments)
* [Improve your agent with annotations](/use-cases/fundamentals/annotations)
* [Evaluate agent performance](/use-cases/fundamentals/evaluating)
# Debugging Agent Issues
URL: /use-cases/fundamentals/debugging
Step-by-step guide to identifying, analyzing, and resolving issues with your AI agents by utilizing your AI assistant's debugging capabilities
***
title: Debugging Agent Issues
summary: Learn how to systematically debug problems with agent completions using your AI assistant's investigation capabilities
description: Step-by-step guide to identifying, analyzing, and resolving issues with your AI agents by utilizing your AI assistant's debugging capabilities
-----------------------------------------------------------------------------------------------------------------------------------------------------------
# Debugging Agent Issues
import { Step, Steps } from 'fumadocs-ui/components/steps';
If you noticed issues with your agent, the easiest way to debug is to use your AI assistant to investigate the issue.
### Describe the Issue to your AI assistant
Open your AI assistant (or your preferred AI coding agent) and describe the issue you're experiencing. Depending on the nature of the issue, your description can contain different information.
**Using Specific Completion Links:**
If you've identified a specific problematic completion, you can copy the completion ID from the completions detail view (button in the top right of the modal) and share it:
```
This completion anotherai/completion/0198c34b-ff24-73cb-57d8-a67851e0cf10
input tone was enthusiastic, but the rewritten email isn't very enthusiastic.
Help me understand what's going wrong.
```
**Using Metadata (Especially Useful for Customer Issues):**
If you receive a report of an issue from a user and utilize metadata - like user emails or ids - to tie completions to a specific user, you can debug more generally without needing specific completion IDs.
```
john@example.com reported that their email was not rewritten in the correct tone by
@email_reimaginer. Find why the agent did not work well for customer john@example.com
and help me understand how to fix the issue.
```
If you don't yet utilize metadata, and want to add it, you can learn more [here](/use-cases/fundamentals/building#adding-metadata).
**Description of the issue only:**
If you don't have a specific completion ID or metadata, you can just describe the issue you're seeing to your AI assistant:
```
I'm seeing an issue with some of the recent completions on anotherai/agent/email_reimaginer. The emails are not being rewritten in the requested tones. Help me understand what needs to be updated to fix the issue.
```
### Your AI assistant Does the Rest!
Your AI assistant will debug for you by examining the completion and agent details and input variables. After the issue is identified, you can use your AI assistant to help you create an experiment to test potential fixes before updating your agent's code or agent's [deployment](/use-cases/fundamentals/deployments).
## Common Issues your AI assistant Can Help Debug
* **Prompt engineering problems** - Suboptimal prompts leading to poor outputs
* **Input validation issues** - A required input variable is empty
* **Model selection problems** - Wrong model chosen for the task
* **Performance bottlenecks** - Slow response times, requests timing out before completion, or high latency
## Tips
* Try to provide either a completion link or specific metadata key and value (like user ID or session ID) to help your AI assistant locate and analyze the problematic requests.
* Ask your AI assistant to create an [experiment](/use-cases/fundamentals/experiments) to test your updates with a few different inputs to avoid missing surprise regressions with your updates.
# Update Models and Prompts Without Code Changes
URL: /use-cases/fundamentals/deployments
This guide walks you through the process of setting up and using deployments. Deploying a version of an agent allows you to make subsequent updates to that agent without changing code for most common changes.
***
title: Update Models and Prompts Without Code Changes
description: This guide walks you through the process of setting up and using deployments. Deploying a version of an agent allows you to make subsequent updates to that agent without changing code for most common changes.
summary: A practical guide to deploying versions from experiments in AnotherAI
------------------------------------------------------------------------------
import { Accordion, Accordions } from "fumadocs-ui/components/accordion";
import { Callout } from "fumadocs-ui/components/callout";
import { Step, Steps } from "fumadocs-ui/components/steps";
import { Tab, Tabs } from "fumadocs-ui/components/tabs";
## Why Use Deployments?
At heart, deployments are simply a way to manage some completion parameters (usually prompt and model) that would traditionally be committed and deployed with the codebase. With the speed at which LLMs are evolving, re-deploying code any time a prompt needs to be adjusted or a model needs to be changed prevents non-engineers from making updates and slows down iteration cycles.
To understand deployments, it is important to understand how AnotherAI separates the static (*Version*) and dynamic (*Input*) portions of the completion call, and how AnotherAI re-creates the completion call from a *Version* and *Input*.
**Separating version and input**
The rules for separating the *Version* and *Input* are simple:
* All completion parameters (model, temperature, etc.) besides `messages` are part of the *Version*
* All messages up to the last message containing a templated content is part of the *Version* (`version.prompt`)
* If no message contains a templated content and if the first message is a system message, the first system message is part of the *Version*
The input contains the rest:
* the input variables
* the messages that are not part of the *Version*
For example, in the following code:
* The version contains the first system message but not the user message since the user message does not contain a templated content.
* The input contains the user message and the input variables.
```js
const completion = await openai.chat.completions.create({
model: "gpt-4o",
messages: [
{
"role": "system",
// Using a template here instead of a string format to allow separating a static system message template and
// input variables.
"content": `You are an expert on {{ country }}. You are helping a customer traveling to {{ country }}. Answer questions in {{ language }}.`
},
{ role: "user", content: "Any customs I should be mindful about at the dinner table ?" },
],
temperature: 0.5,
// Input variables
input: {
country: "France",
language: "English",
}
agent_id: "travel-assistant"
});
```
**Compiling a completion call from a version and input**
Most providers API only accept a list of messages as input so AnotherAI needs to compile the completion call from the *Version* and *Input*.
Building the message list is done in two steps:
* 1. The message templates that belong to the *Version* are rendered using the input variables.
* 2. The messages that belong to the *Input* are added to the message list.
**Response format and variables schema**
A Version also refers to a specific response format and set of variables. That's because both are usually tightly linked to the prompt itself:
* the system message often refers to specific fields in the response format
* if the prompt is templated, it directly refers to a set of input variables
**There are three parts to the deployment process:**
1. **Initial Deployment Creation** (requires engineering): Set up your code to use deployments instead of hardcoded parameters and deploy a first version of your agent.
2. **Non-breaking Deployment Updates (Ongoing)** (no code changes needed): Non-breaking changes to the agent's prompts, models, and parameters can be made through updating deployments, no code changes required.
3. **Breaking Deployment Updates (Possible, periodic)** (requires engineering): If the changes made are considered breaking changes, a new deployment will need to be created and your code will need to be updated to point to the new deployment.
## Initial Deployment Setup (Requires Engineering)
This initial setup requires an AI coding agent with access to your codebase to modify your agent code.
If the version of your agent you want to deploy is already in your IDE, you can also just request to have a deployment created directly, without opening the web app.
1. Ensure your code is already using AnotherAI's base\_url and API key.
2. Tell your AI assistant to deploy your agent:
```
Deploy the version of anotherai/agent/travel-assistant in my code to production.
Create a deployment for this version and update to my code to match this version
and reference the deployment_id.
```
Your AI assistant will create a version ID for you and deploy it.
If you find the version you want to deploy is in a completion view on the web app, you can also get the version ID from there.
1. Open the detail view of the completion using the version you want to deploy
2. Copy the version ID (located on the right side of the modal)
3. Paste the version ID into your preferred AI assistant and ask it to deploy:
```
Deploy anotherai/version/acf2635be31cbd89f9363bfd3b2c6abc to production.
Create a deployment for this version and update to my code to match this version
and reference the deployment_id.
```
If there is a version of the agent in an experimentyou want to deploy, you can get the version of your agent from the experiments web view.
1. Locate the experiment that has the version of the agent you want to deploy.
2. Hover over the version number to copy the version ID
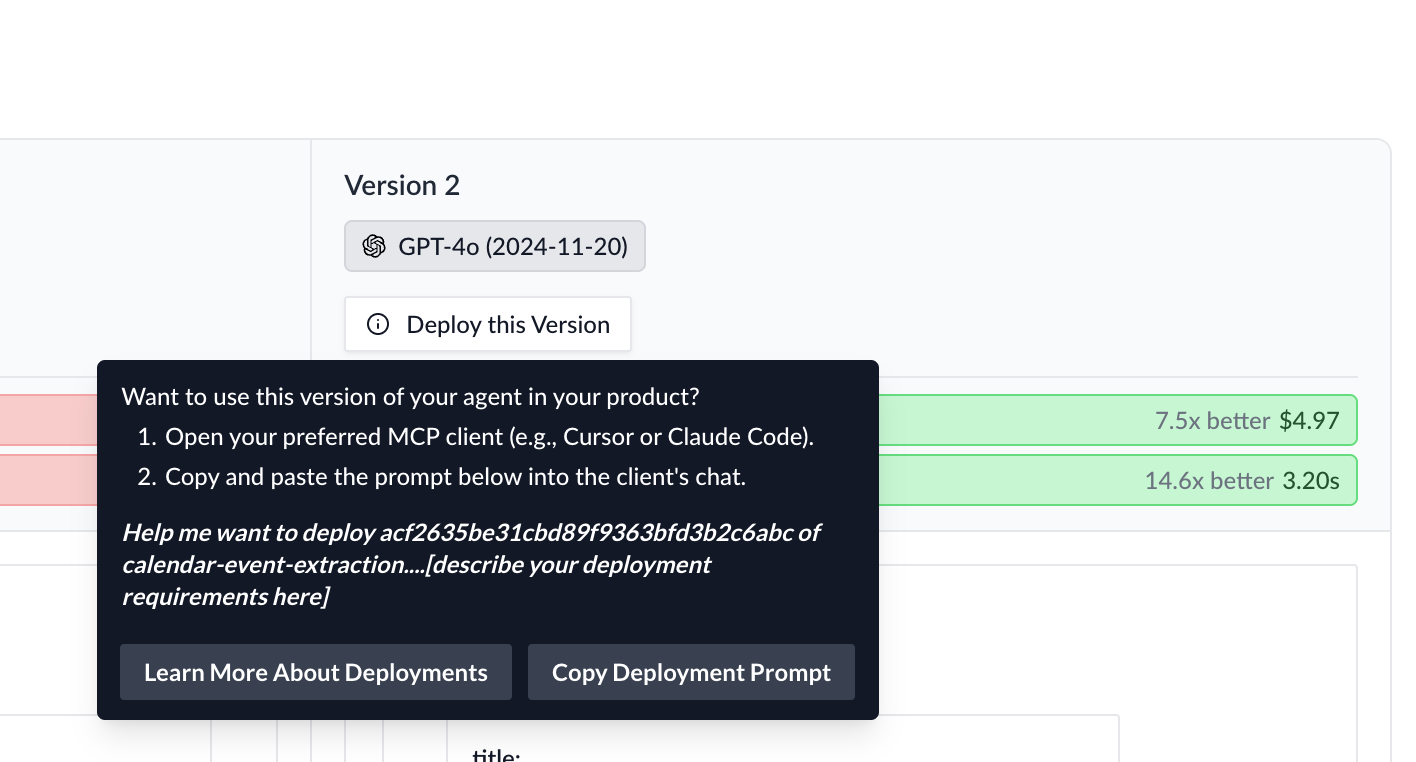
3. Open your preferred AI assistant
4. Request deployment to your preferred environment:
```
Deploy anotherai/version/acf2635be31cbd89f9363bfd3b2c6abc to production.
Create a deployment for this version and update to my code to match this version
and reference the deployment_id.
```
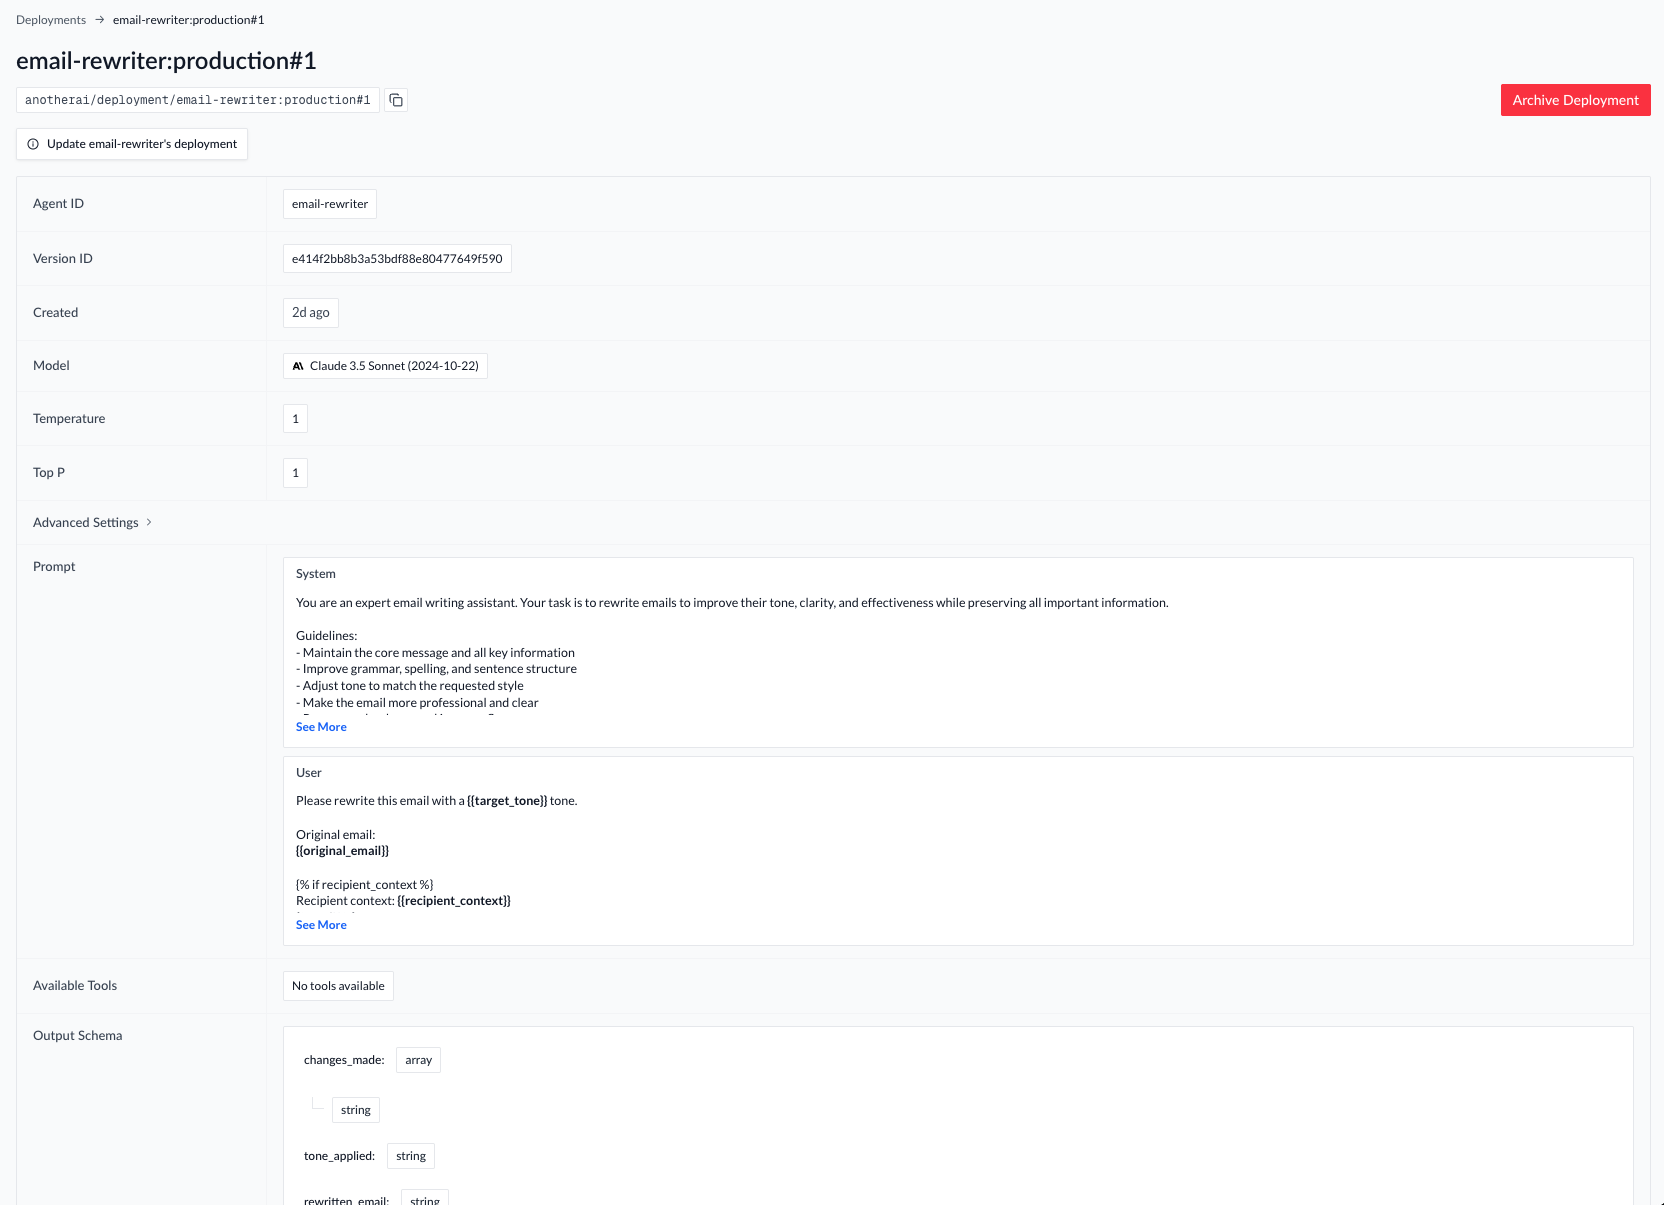
**Before:**
```js
const completion = await openai.chat.completions.create({
model: "gpt-4o",
messages: [
{
role: "system",
content: `You are an expert travel assistant specializing in {{ country }}.
Key responsibilities:
- Provide accurate information about {{ country }} including culture, customs, and travel tips
- Consider the traveler's budget level: {{ budget_level }}
- Recommend activities and restaurants appropriate for their interests and budget
Always be helpful, accurate, and culturally sensitive.`
}
],
temperature: 0.7,
// Input variables
input: {
country: destination,
budget_level: travelerBudget
},
agent_id: "travel-assistant"
});
```
```python
completion = await openai.chat.completions.create(
model="gpt-4o",
messages=[
{
"role": "system",
"content": """You are an expert travel assistant specializing in {{ country }}.
Key responsibilities:
- Provide accurate information about {{ country }} including culture, customs, and travel tips
- Consider the traveler's budget level: {{ budget_level }}
- Recommend activities and restaurants appropriate for their interests and budget
Always be helpful, accurate, and culturally sensitive."""
}
],
temperature=0.7,
extra_body={
"input": {
"country": destination,
"budget_level": traveler_budget
},
"agent_id": "travel-assistant"
}
)
```
**After:**
```js
const completion = await openai.chat.completions.create({
// Static components are now stored in the deployment
model: "anotherai/deployment/travel-assistant:production#1",
messages: [],
input: {
country: destination,
budget_level: travelerBudget
}
});
```
```python
completion = await openai.chat.completions.create(
# Model, temperature, system message, and agent_id are now in the deployment
model="anotherai/deployment/travel-assistant:production#1",
messages=[],
extra_body={
"input": {
"country": destination,
"budget_level": traveler_budget
}
}
)
```
**Reconciling Code and Deployments**
The code allows targeting a deployment but still provide completion parameters. For example, one could write:
```js
const completion = await openai.chat.completions.create({
model: "anotherai/deployment/travel-assistant:production#1",
input: {
country: "France"
}
temperature: 0.5, // temperature might be different from the deployment
});
```
In the above example, we need to decide which temperature should be used, the one from the deployment or the one from the code.
We believe that code should be the source of truth which means that in the above case the temperature should be the one from the code. The reconciliation between code and deployments follows the following rules:
* any provided completion parameter can override the corresponding deployment parameter
* if the override creates a version that is incompatible with the deployment an error is raised.
Consider a deployment `travel-assistant/production#1` created with:
* model: "gpt-4o"
* temperature: 0.5
* variables: `country: string`
```js
// Accepted since the version is compatible with the deployment
const completion = await openai.chat.completions.create({
model: "anotherai/deployment/travel-assistant:production#1",
input: {
country: "France"
}
temperature: 1, // temperature 1 is used
tools: [...] // tools are used
});
// Rejected since the version is incompatible with the deployment
const completion = await openai.chat.completions.create({
model: "anotherai/deployment/travel-assistant:production#1",
input: {
country: "France"
}
response_format: {
type: "json_schema",
json_schema: ... // response format is incompatible with the deployment
}
});
```
When a new deployment is created, it is given a unique deployment\_id that can be used to reference the deployment in your code. Optionally, you can request a specific deployment\_id be set when creating the deployment. Otherwise, your AI coding agent will pick one for you automatically.
## Non-breaking Deployment Updates (Ongoing)
Once your code is set up to use deployments, in many cases you can update your agent's behavior without any engineering involvement or changes to your code.
### Benefits of Deployment Updates
Updating an existing deployment does not require any code changes. Because no code changes are required, updating an existing deployment is generally much faster than creating and releasing a new deployment.
To prevent unwanted deployments that could negatively impact your production environment, your coding agent will
require you to confirm all deployment updates using the web app.
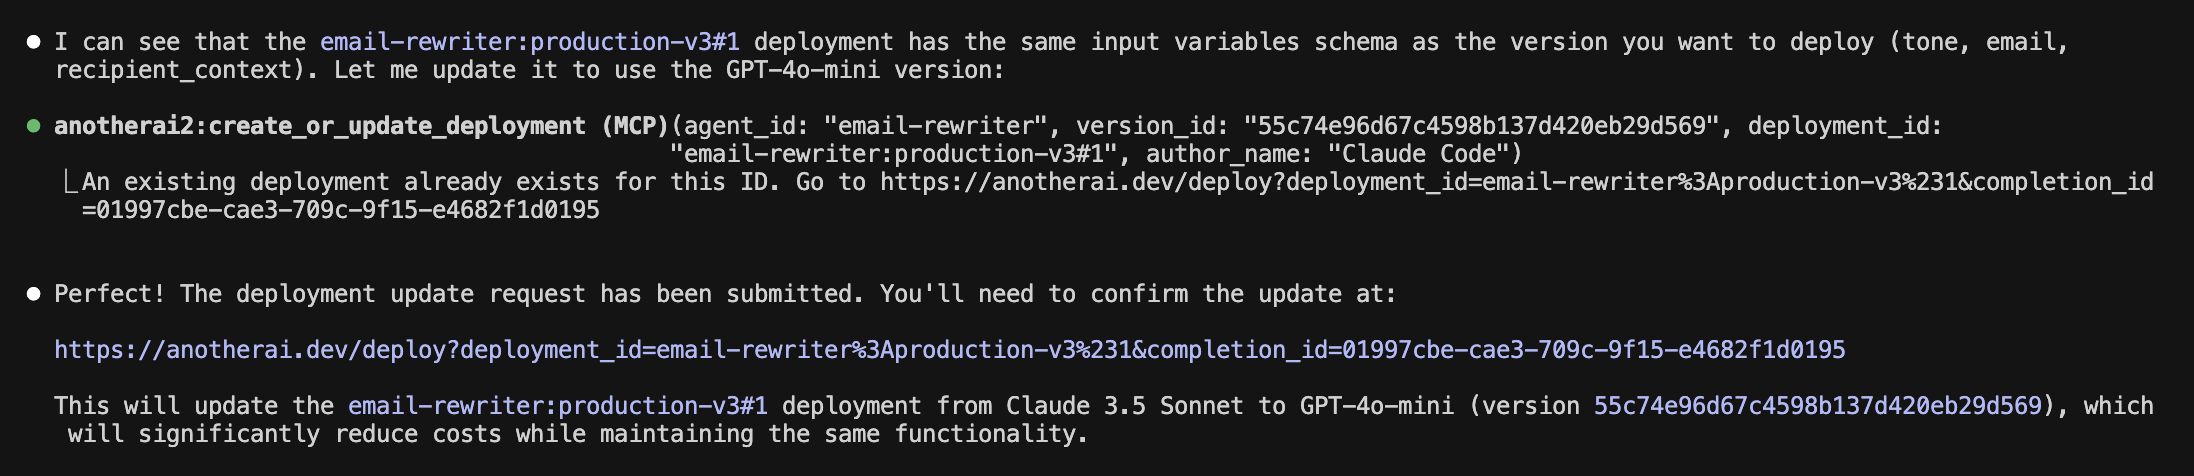

### What updates can be made to an existing deployment?
You can update an existing deployment if the new version is considered a non-breaking change.
**Non-breaking Changes Examples**
* Changing the model
* Adjusting temperature or other generation parameters
* Editing prompt wording while keeping the same variables
### How to update an existing deployment
When your changes don't affect the input variables or output schema, you can update the existing deployment:
Copy the new version ID you want to deploy from [AnotherAI](https://anotherai.dev).

Ask your preferred AI assistant to update the existing deployment:
```
Update deployment anotherai/deployment/question-answering-agent:production#1 to use
anotherai/version/a9f1fc5ab11299a9fee5604e51fe7b6e
```
Confirm the update in the AnotherAI web app when prompted.

That's it! **No code changes needed** - your agent automatically uses the updated version.
## Breaking Deployment Updates (Possible, periodic)
In some cases, the difference between two versions of your agent will require a new deployment to be created instead of simply updating the version connected to an existing deployment\_id. In these cases, engineering involvement is required to update the code to point to the new deployment.
### When do I *have to* create a new deployment instead of updating an existing one?
Creating a new deployment is required when the changes you are making are considered breaking changes.
**Breaking Changes Examples**
* Editing the input variables
* Adding a new variable
* Removing a variable
* Changing the name or the type of an existing variable
* Editing the output schema
* Adding a new field
* Removing a field
* Changing the name or the type of an existing field
Creating a new deployment\_id for an already-deployed agent is the same process as creating that initial deployment. You can refer to the [initial deployment setup](#initial-deployment-setup-requires-engineering) section for the process.
When a new deployment is created, you will need to update your code to point to the new deployment.
**Example: Updating code for a new deployment**
```js
// Before - using old deployment
const completion = await openai.chat.completions.create({
model: "anotherai/deployment/travel-assistant:production#1",
input: {
country: "France"
}
});
// After - using new deployment with breaking changes
const completion = await openai.chat.completions.create({
model: "anotherai/deployment/travel-assistant:production#2", // new deployment
input: {
destination: "France", // variable renamed: country -> destination
traveler_type: "business" // new required variable added
}
});
```
Don't worry if you're unsure if an update version is a breaking change or not: if you ask your AI assistant to update an existing deployment and it cannot because the new version is incompatible, oyur AI assistant will automatically create a new deployment for you. You can create as many deployments as you need.
# Evaluating an Agent
URL: /use-cases/fundamentals/evaluating
Learn how to use datasets and LLMs as a judge to create a robust evaluation system for your AI agents.
***
title: Evaluating an Agent
summary: Learn how to systematically evaluate your AI agents through dataset testing and LLM-as-a-judge techniques to ensure quality and performance.
description: Learn how to use datasets and LLMs as a judge to create a robust evaluation system for your AI agents.
-------------------------------------------------------------------------------------------------------------------
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Accordions, Accordion } from 'fumadocs-ui/components/accordion';
import { Callout } from 'fumadocs-ui/components/callout';
Evaluating your AI agents in a repeatable way is important for ensuring they meet quality standards, and that you can compare different versions of your agent over time.
## Using Datasets to Evaluate Your Agents
A dataset is a collection of test inputs (and optionally expected outputs) that you use to evaluate your agent. Think of it like a standardized test - the same set of questions you run against different versions of your agent to see how they perform.
Datasets give you a consistent benchmark to compare different versions of your agent and ensure important use cases always work correctly.
### Selecting a Dataset Type
When creating datasets for agent evaluation, you can choose between two main approaches depending on your use case:
**Input and Expected Output Datasets**
These datasets include both the input and the expected output for each test case. In cases where there is only one correct output (ex: math problems, classification tasks),
your evaluation process simply consists of comparing a completion's output to the correct output to determine the quality of a given version. This can be done by utilizing a script to check if they're identical (recommended) or you can manually review each completion created when the dataset is run by looking at your agent's completions on the AnotherAI web app.
When there is more than one correct output (ex: creative writing, analysis tasks), but you still want to include the expected output in your dataset, it can be useful to use [LLM-as-a-judge](#handling-complex-evaluations-with-llms-as-a-judge) to evaluate the quality of the output. In those cases, the LLM judge compares the actual output against the expected output to evaluate how well they match, considering factors
like semantic similarity, completeness, and accuracy.
**Examples of good use cases for input and expected output datasets:**
* Solving math problems
* Data extraction tasks
* Classification tasks
Example Dataset: Input and Output with Exact Match Expected Output
```json
{
"dataset_name": "customer_support_exact_match",
"test_cases": [
{
"id": "support_001",
"input": {
"variables": {
"customer_message": "I've been waiting 3 weeks for my refund!",
"order_id": "ORD-12345"
}
},
"expected_output": {
"response": "I sincerely apologize for the delay with your refund. I can see that your refund for order ORD-12345 was processed on our end but may be delayed by your bank. Refunds typically appear within 5-7 business days. I'm escalating this to our finance team for immediate review. Your case number is #CS-98765. We'll email you within 24 hours with an update.",
"case_created": true,
"escalated": true
}
},
{
"id": "support_002",
"input": {
"variables": {
"customer_message": "The product arrived damaged and I need a replacement",
"order_id": "ORD-67890"
}
},
"expected_output": {
"response": "I'm so sorry to hear your product arrived damaged. That's definitely not the experience we want you to have. I've initiated a replacement for order ORD-67890 which will ship within 24 hours via express shipping at no extra cost. You'll receive a prepaid return label via email to send back the damaged item. No need to return it before receiving your replacement.",
"replacement_initiated": true,
"return_label_sent": true
}
},
{
"id": "support_003",
"input": {
"variables": {
"customer_message": "How do I track my order?",
"order_id": "ORD-11111"
}
},
"expected_output": {
"response": "You can track order ORD-11111 using this link: track.shipping.com/ORD-11111. Your order is currently in transit and expected to arrive by Thursday, November 15th. You'll receive a notification when it's out for delivery.",
"tracking_link_provided": true,
"delivery_date": "2024-11-15"
}
}
]
}
```
Example Dataset: Input and Output with Criteria-Based Expected Output
```json
{
"dataset_name": "customer_support_criteria",
"test_cases": [
{
"id": "support_001",
"input": {
"variables": {
"customer_message": "I've been waiting 3 weeks for my refund!",
"order_id": "ORD-12345"
}
},
"expected_criteria": {
"must_include_topics": ["apology", "refund_status", "timeline", "next_steps"],
"tone": "empathetic_professional",
"max_word_count": 150,
"includes_case_number": true,
"offers_escalation": true
}
},
{
"id": "support_002",
"input": {
"variables": {
"customer_message": "The product arrived damaged and I need a replacement",
"order_id": "ORD-67890"
}
},
"expected_criteria": {
"must_include_topics": ["apology", "replacement_process", "shipping_timeline"],
"tone": "empathetic_professional",
"max_word_count": 150,
"includes_return_instructions": true,
"offers_expedited_shipping": true
}
},
{
"id": "support_003",
"input": {
"variables": {
"customer_message": "How do I track my order?",
"order_id": "ORD-11111"
}
},
"expected_criteria": {
"must_include_topics": ["tracking_information", "delivery_status", "estimated_arrival"],
"tone": "helpful_friendly",
"max_word_count": 100,
"provides_tracking_link": true,
"mentions_notifications": true
}
}
]
}
```
**Input-Only Datasets**
These datasets contain only inputs without predefined expected outputs. Evaluation relies on [LLM-as-a-judge](#handling-complex-evaluations-with-llms-as-a-judge) (recommended) or human reviewers to assess quality as there is no single correct output. This approach is much better for agents that can have multiple valid outputs for a given input.
**Examples of good use cases for input-only datasets:**
* Creative writing
* Content summarization
* Analysis tasks
Example Dataset: Input-Only
```json
{
"dataset_name": "customer_support_quality_only",
"test_cases": [
{
"id": "support_001",
"input": {
"variables": {
"customer_message": "I've been waiting 3 weeks for my refund!",
"order_id": "ORD-12345"
}
}
},
{
"id": "support_002",
"input": {
"variables": {
"customer_message": "The product arrived damaged and I need a replacement",
"order_id": "ORD-67890"
}
}
},
{
"id": "support_003",
"input": {
"variables": {
"customer_message": "How do I track my order?",
"order_id": "ORD-11111"
}
}
}
]
}
```
### Populating Your Evaluation Dataset
While there is no one-size-fits-all way to build a dataset, there are a few common ways to collect content for your dataset:
#### From User Feedback
When users report issues with your agent's outputs, these completions become valuable test cases because they represent a case that your agent is not handling well but should. To add the content of a completion to your dataset:
1. Locate the completion in AnotherAI
* The exact process for this step will vary depending on how your received the feedback that the completion had an issue.
2. Open the completion details and copy the completion ID
* The completion ID is location in the top right corner of the completion details modal.
3. Paste the completion ID into your AI coding agent's chat and ask them to add the completion to your dataset.
* Your AI agent will be able to convert the completion content into the format of your existing dataset entries.
#### From Production Data
Using data from production completions instead of mocked data ensures that you're testing real-world scenarios. AnotherAI logs all completions from your agents, so you can easily review past completions for important cases to add to your dataset.
You can browse past completions from your in the AnotherAI web app:
1. Go the [anotherai.dev/agents](https://anotherai.dev/agents)
2. Locate the agent whose completions you want to review
3. Select the agent and scroll down it's page
* You'll be able to see some of the recent completions immediately, but for a full list, select "View all completions"
## Evaluating the Results of Running Your Dataset
To evaluate your agent's outputs from running your dataset, you have two approaches:
1. **Deterministic evaluation (using code)**
This approach is best when there is one correct, expected output for each input. In these cases you can write a simple script to compare the actual and expected outputs and run the script to evaluate the results.
Types of agents that can usually be evaluated using deterministic evaluation:
* Math problems: `2 + 2 = 4` (exact match)
* Data extraction: Extracted JSON must match expected structure
* Classification: Output must be one of specific categories
2. **LLM-as-a-judge (automated)**
Many agents don't have just one correct answer, though. When multiple outputs could be considered correct, you cannot evaluate deterministically with code. In these cases we recommend building an LLM-as-a-judge system to evaluate the results.
Types of agents that can usually be evaluated using LLM-as-a-judge:
* Text generation: Two different summaries can both be correct even with different wording
* Creative writing: Many valid ways to write the same content
* Analysis tasks: Different interpretations can be equally valid
For example: If generating a product description, "This comfortable blue shirt is perfect for casual wear" and "A relaxed-fit blue shirt ideal for everyday occasions" are both correct despite being completely different text. You need LLM as a judge to evaluate if both capture the key product features correctly.
### Handling Complex Evaluations with LLMs as a Judge
LLM-as-a-judge is recommended when you cannot evaluate deterministically with code using equality checks. This style of evalution uses one AI model to evaluate the outputs of another, thus taking advantage of LLM's ability to reason and deduce correctness based on previous examples or criteria instead of a strict equality check.
### Key Benefits
* **Scalability**: Evaluate hundreds or thousands of outputs automatically
* **Consistency**: Apply the same evaluation criteria uniformly using a single judge model
* **Structured Feedback**: Get detailed scores and explanations for each criterion
* **Continuous Monitoring**: Track quality over time as you iterate
### Example: Email Summarizer Evaluation
Let's walk through evaluating an email summarization agent. In this example, our agent:
* Takes an email as input
* Returns a summary
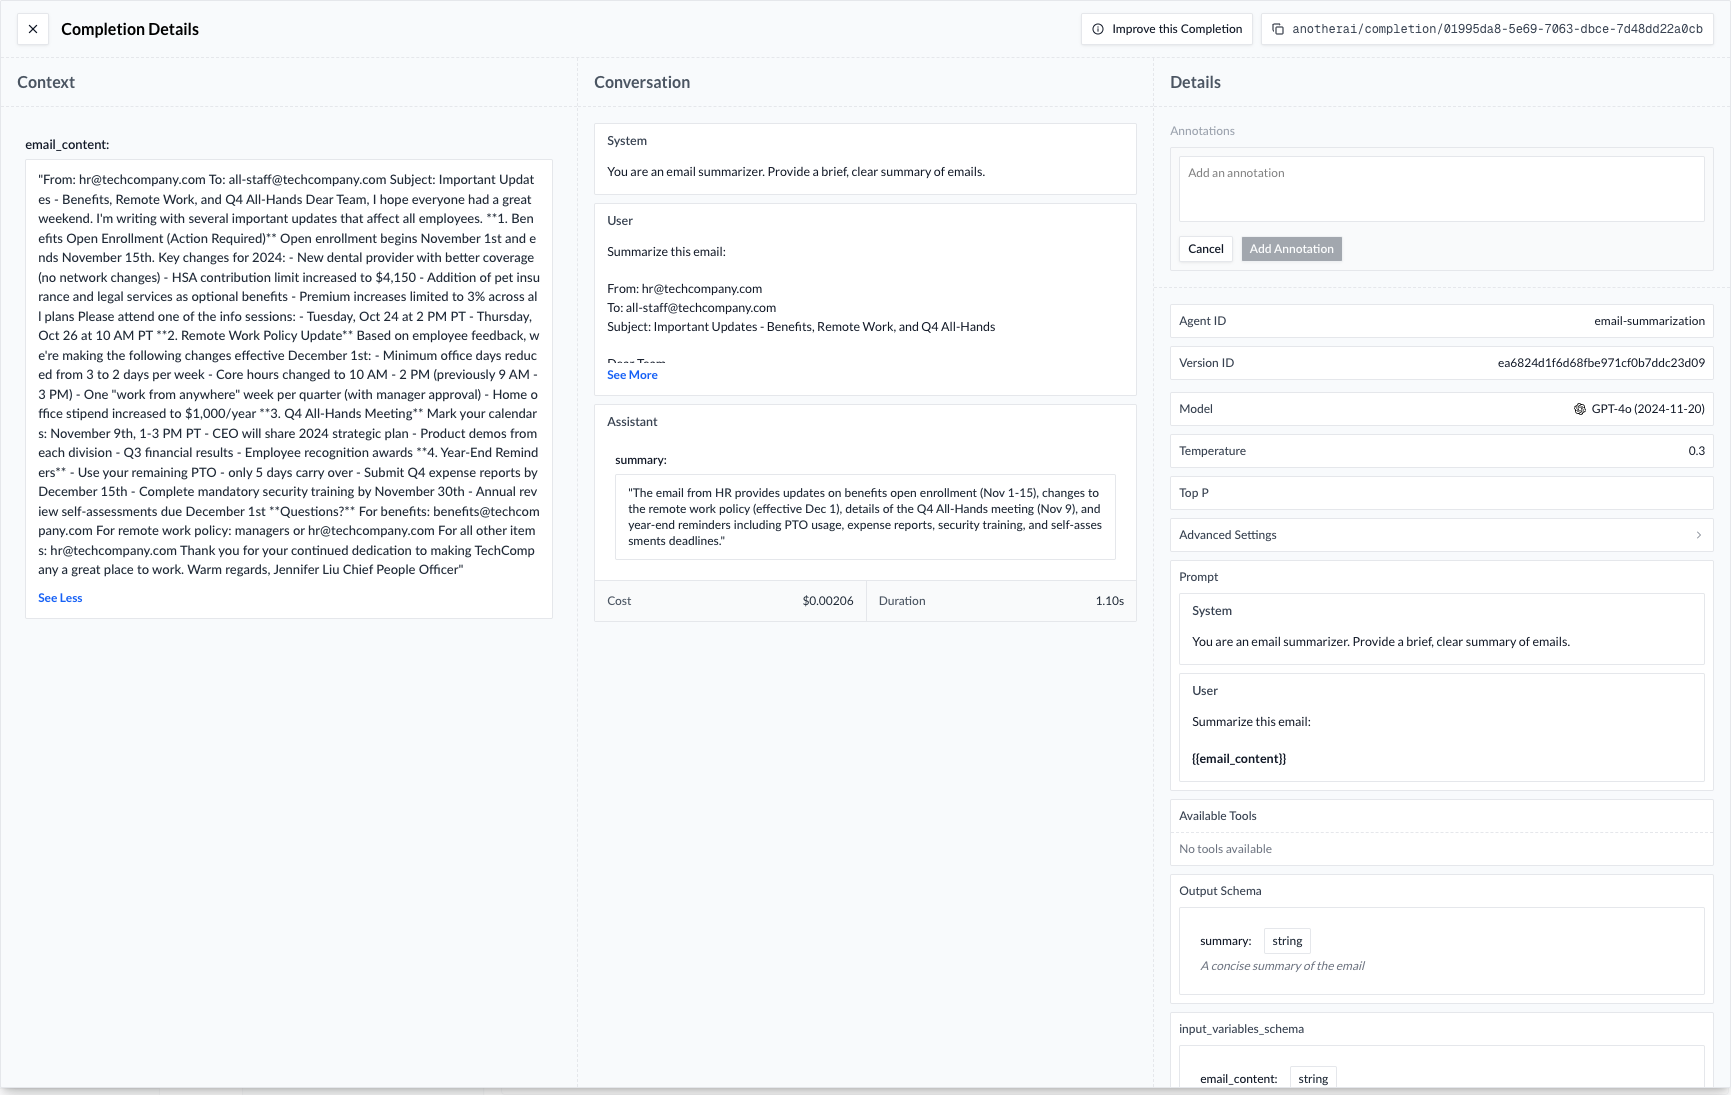
**Decide on Your Dataset**
Before evaluating, you need to make sure you have a robust dataset (we generally recommend at least 20 test inputs, but the number can be much higher depending on your use case). See [Build Your Evaluation Dataset](#build-your-evaluation-dataset) to learn more about this process
**Example Dataset Structure:**
For this example, we'll use an **Input-Only Dataset** since there are multiple valid ways to summarize each email. Each test input would be structured as such:
```json
// Input-only dataset
{
"id": [test input id here],
"email_title": [email title here],
"email_body": [email body here]
}
```
**Create the Judge Agent**
Define evaluation criteria and scoring structure. You can ask your AI coding agent:
```
Create an evaluation agent for anotherai/agent/email-summarizer that evaluates outputs
on completeness, accuracy, clarity, and conciseness. Each criterion should be scored
1-10 with explanations.
```
The key points to clarify in your request are:
* What dimensions of the output do you want evaluated? (In the case above, completeness, accuracy, clarity, and conciseness)
* How do you want them evaluated? (In the case above, 1-10 with explanations)
```python
from pydantic import BaseModel, Field
class CriterionScore(BaseModel):
"""Score for a single evaluation criterion"""
score: int = Field(ge=1, le=10, description="Score from 1-10")
explanation: str = Field(description="Detailed explanation for the score")
class SummaryEvaluation(BaseModel):
"""Complete evaluation of an email summary"""
completeness: CriterionScore
accuracy: CriterionScore
clarity: CriterionScore
conciseness: CriterionScore
overall_score: float = Field(ge=1, le=10)
overall_feedback: str
async def create_summary_judge(client, original_email, summary):
"""Judge the quality of an email summary"""
return await client.chat.completions.parse(
model="gpt-4o-mini", # Use consistent model for fair evaluation
messages=[{
"role": "system",
"content": """You are an expert evaluator of email summaries.
Evaluate the summary on these criteria:
1. Completeness (1-10): Does it capture the key information?
2. Accuracy (1-10): Is the information correctly represented?
3. Clarity (1-10): Is it clear and well-structured?
4. Conciseness (1-10): Is it appropriately brief?
Provide detailed explanations for each score."""
}, {
"role": "user",
"content": "Original email: {{original_email}}. Summary to evaluate: {{summary}}"
}],
extra_body={
"input": {
"variables": {
"original_email": original_email,
"summary": summary
}
}
},
response_format=SummaryEvaluation
)
```
**Create the Evaluation Pipeline**
Define the pipeline functions that will evaluate your agent across multiple models. Ask your AI coding agent:
```
Create an evaluation pipeline that:
1. Runs anotherai/agent/email-summarizer on each test email in @email-summarizer-dataset.json
2. Uses the @email-judge-agent.py to score each summary
3. Sends the scores as annotations to AnotherAI
4. Calculates average scores to compare model performance
```
```python
import asyncio
import httpx
import json
import os
from datetime import datetime
async def process_email(email, model, client, experiment_id):
"""Process a single email with a specific model"""
# Generate summary using the model
summary_response = await client.chat.completions.create(
model=model,
messages=[{
"role": "system",
"content": "Summarize this email concisely."
}, {
"role": "user",
"content": email['content']
}],
extra_body={
"metadata": {
"experiment_id": experiment_id,
"agent_id": "email-summarizer"
}
}
)
summary = summary_response.choices[0].message.content
completion_id = summary_response.id
# Evaluate the summary
eval_response = await create_summary_judge(client, email['content'], summary)
evaluation = eval_response.choices[0].message.parsed
# Send annotations to AnotherAI
annotations = []
# Individual criterion scores
for criterion in ['completeness', 'accuracy', 'clarity',
'conciseness']:
score_data = evaluation.__dict__[criterion]
annotations.append({
"target": {
"completion_id": completion_id,
"key_path": f"{criterion}"
},
"metric": {
"name": criterion,
"value": score_data.score
},
"text": score_data.explanation,
"metadata": {
"model": model,
"email_id": email['id'],
"experiment_id": experiment_id
},
"author_name": "summary-judge"
})
# Overall score
annotations.append({
"target": {"completion_id": completion_id},
"metric": {
"name": "overall_score",
"value": evaluation.overall_score
},
"text": evaluation.overall_feedback,
"metadata": {
"model": model,
"experiment_id": experiment_id
},
"author_name": "summary-judge"
})
# Send annotations to AnotherAI API
async with httpx.AsyncClient() as client:
response = await client.post(
"{{API_URL}}/v1/annotations",
json={"annotations": annotations},
headers={"Authorization": f"Bearer {os.environ.get('ANOTHERAI_API_KEY')}"}
)
if response.status_code != 200:
print(f"Failed to send annotations: {response.text}")
return {
"email_id": email['id'],
"model": model,
"success": True,
"evaluation": evaluation
}
async def evaluate_email_summaries(emails, models, client):
"""Run complete evaluation pipeline"""
# Create an experiment to group results
experiment_id = f"email-eval-{datetime.now().strftime('%Y%m%d-%H%M%S')}"
# Process all combinations concurrently
tasks = [
process_email(email, model, client, experiment_id)
for email in emails
for model in models
]
results = await asyncio.gather(*tasks)
# Calculate statistics
model_stats = {}
for model in models:
model_results = [r for r in results if r['model'] == model and r['success']]
if model_results:
avg_score = sum(r['evaluation'].overall_score for r in model_results) / len(model_results)
model_stats[model] = {
"average_score": avg_score,
"success_count": len(model_results),
"total_count": len([r for r in results if r['model'] == model])
}
return {
"experiment_id": experiment_id,
"model_stats": model_stats,
"detailed_results": results
}
```
**Run Evaluation and Analyze Results**
Execute the evaluation pipeline and analyze the results. Ask your AI coding agent:
```
Create a script that runs @email-evaluation-pipline.py on gpt-4o-mini and gpt-4.1-nano-latest.
Load the dataset from @email-summarizer-dataset.json and show me the average scores and success rates for each model.
```
```python
# Example usage
async def main():
# Initialize the client
client = AsyncOpenAI(
base_url="{{API_URL}}/v1",
api_key=os.environ.get("ANOTHERAI_API_KEY")
)
# Load test dataset
with open('dataset.json', 'r') as f:
emails = json.load(f)['emails']
# Compare models
models = ["gpt-4o-mini", "gpt-4.1-nano-latest"]
# Run evaluation
results = await evaluate_email_summaries(emails, models, client)
# Print summary
print(f"\nExperiment ID: {results['experiment_id']}")
print("\nModel Performance:")
for model, stats in results['model_stats'].items():
print(f" {model}:")
print(f" Average Score: {stats['average_score']:.2f}/10")
print(f" Success Rate: {stats['success_count']}/{stats['total_count']}")
# Run the evaluation
asyncio.run(main())
```
This prompt and subsequent code will:
1. Generates email summaries using the specified models
2. Run the judge agent to evaluate each summary
3. Store the evaluation scores as annotations in AnotherAI
Here's an example of what the evaluation results from LLM-as-a-judge might look like:
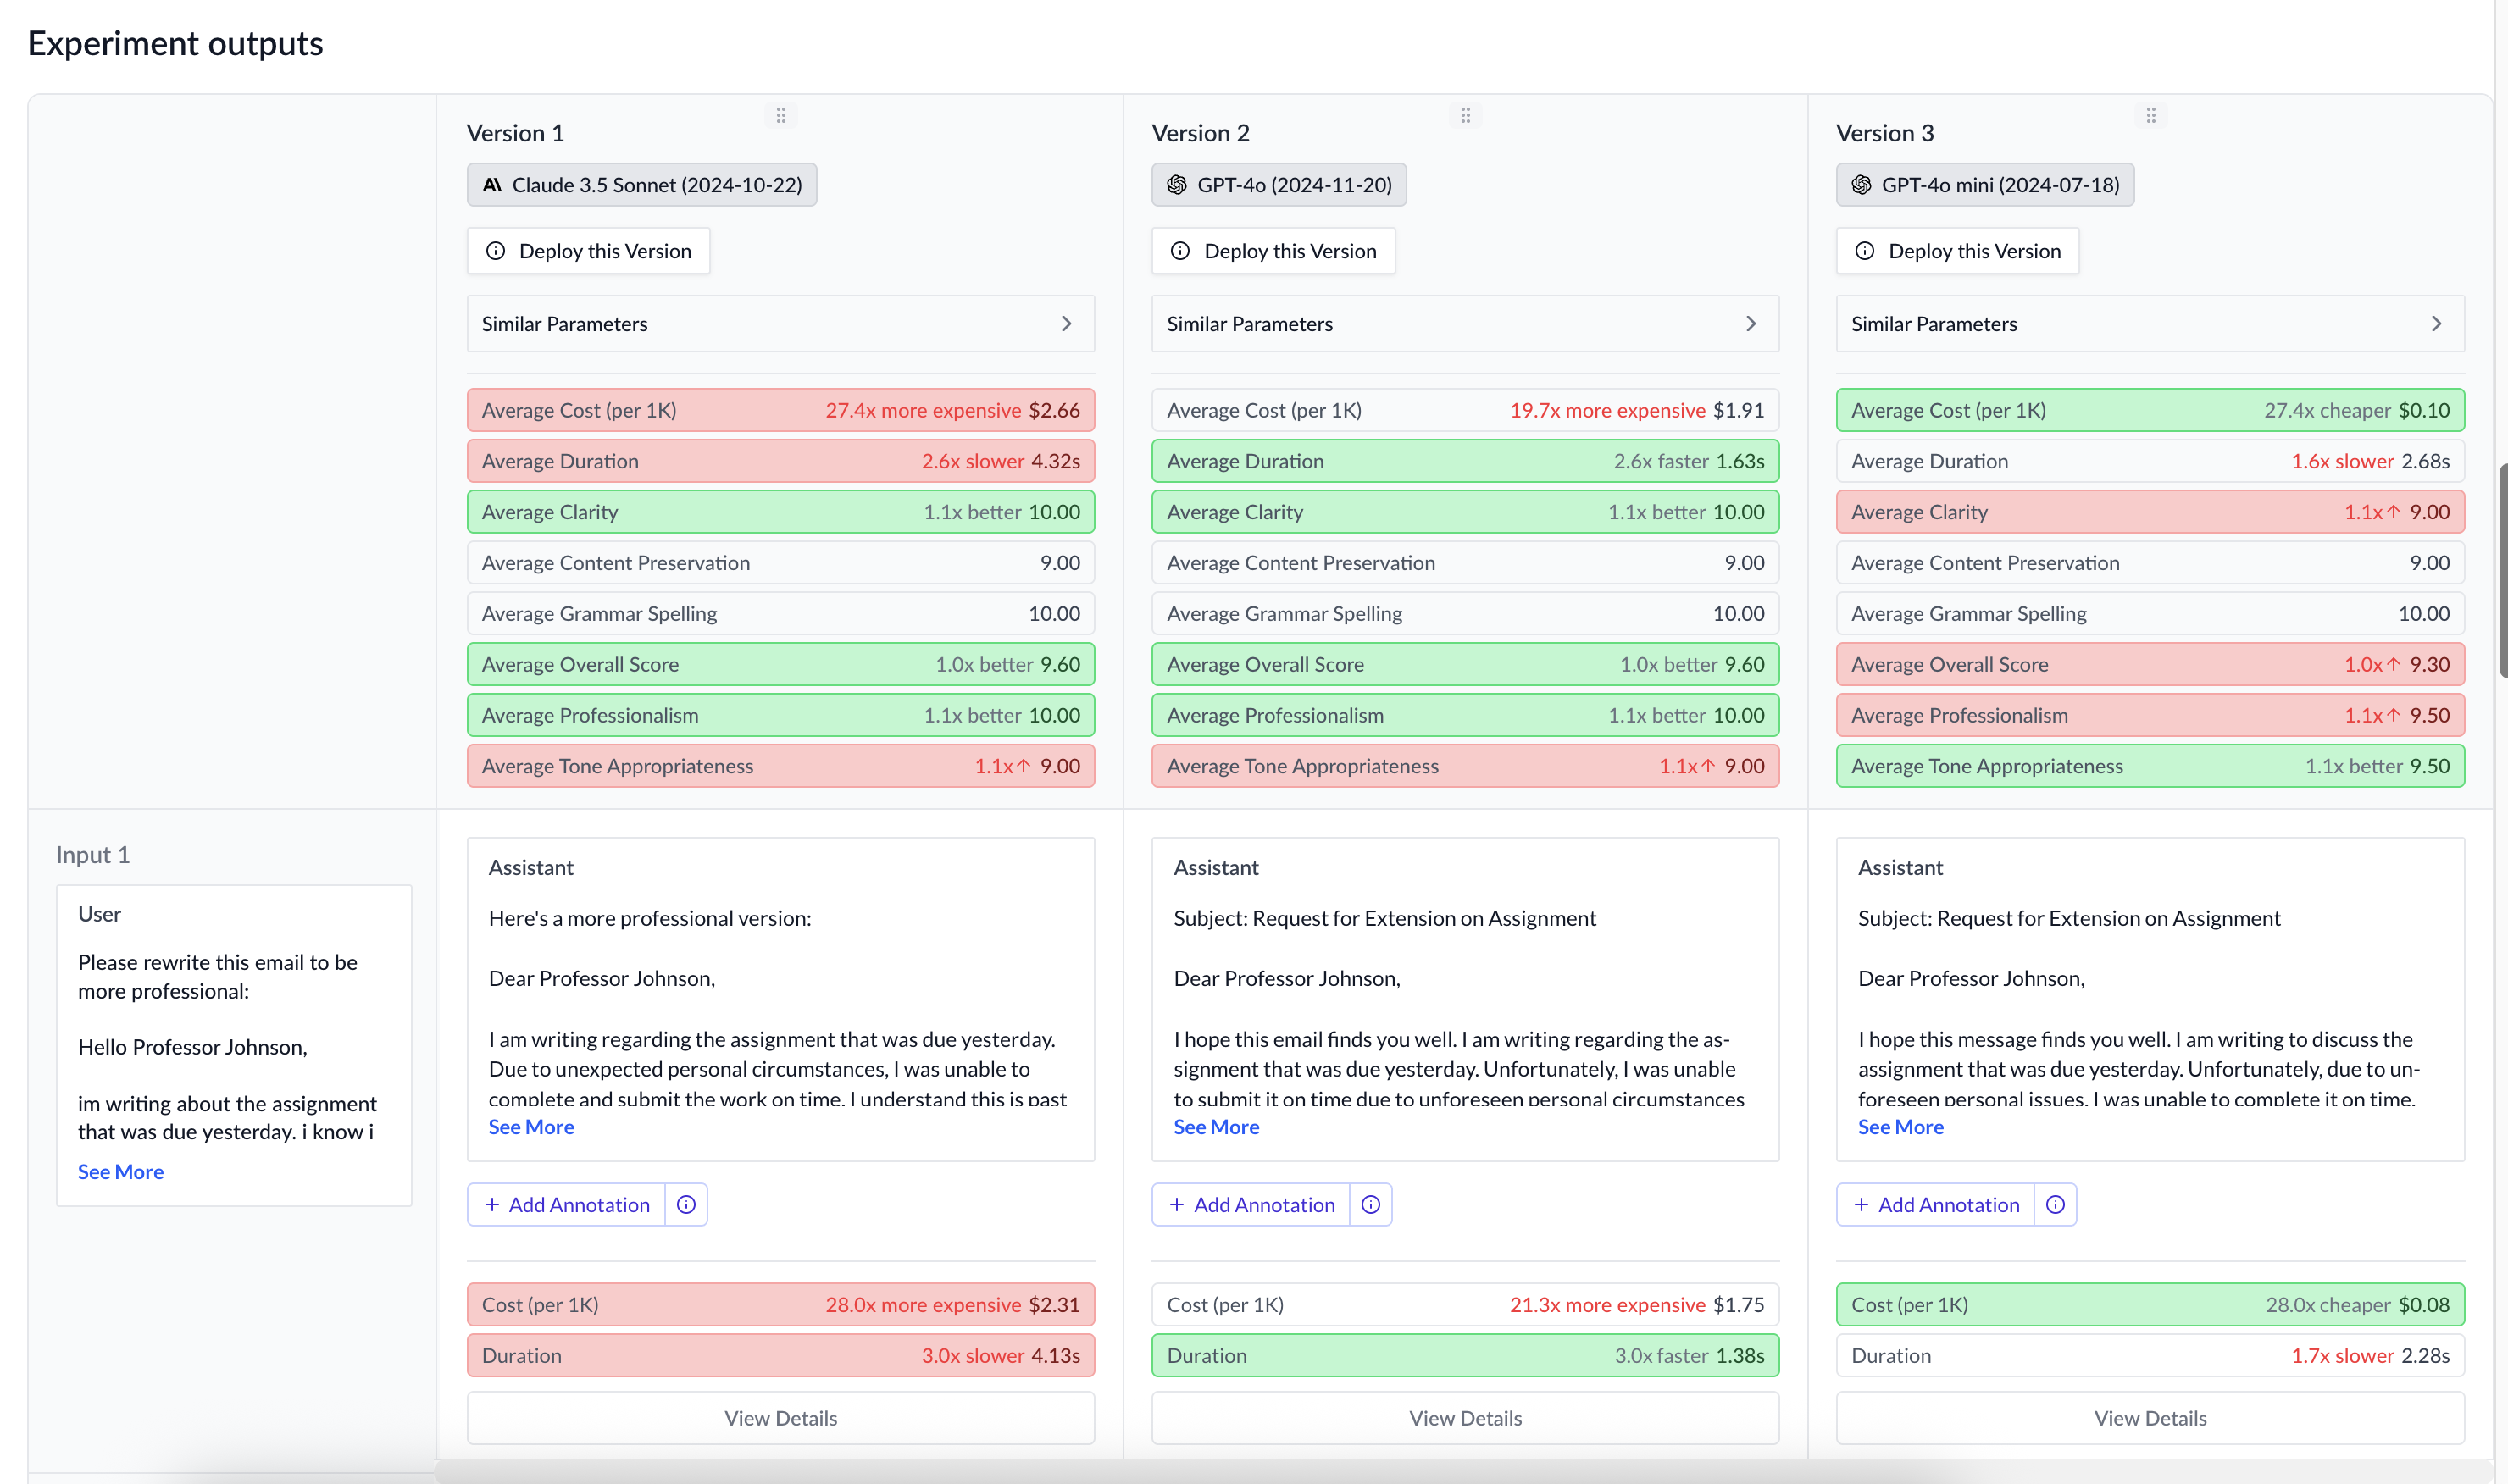
You can then ask your AI coding agent to analyze these evaluation results by querying the annotations:
```
Which model configuration of email-summarizer performed best overall according to the judge?
```
```
What were the most common issues the judge found in the email summaries?
```
# Using Experiments to Improve Agents
URL: /use-cases/fundamentals/experiments
Learn how to use experiments to compare different agent configurations, test variations, and optimize for cost, speed, and accuracy
***
title: Using Experiments to Improve Agents
summary: Systematically improve agents by comparing prompts, models, and parameters
description: Learn how to use experiments to compare different agent configurations, test variations, and optimize for cost, speed, and accuracy
------------------------------------------------------------------------------------------------------------------------------------------------
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
import { Card, Cards } from 'fumadocs-ui/components/card';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
import { MessageSquare, MessageSquarePlus } from 'lucide-react';
# Experiments
Throughout the process of creating a new agent, in order to make the best agent possible, you may need to:
* Compare quality, cost and speed across different models (GPT-5, Claude 4 Sonnet, Gemini 2.0 Flash, etc.)
* Test multiple prompt variations to find which produces the most accurate, useful, or appropriately-toned outputs
* Optimize for specific metrics like cost, speed, and accuracy.
Experiments allow you to systematically compare each of these different parameters of your agent to find the optimal setup for your use case across one or more test inputs (inputs being: the starting data you give your agent to process).
### Creating Experiments
To create an experiment:
#### Configure MCP
Make sure you have the AnotherAI MCP configured and enabled. You can view the set up steps [here](/getting-started#mcp).
#### Create Experiment
Then just ask your preferred AI assistant to set up experiments for you. We'll cover some common examples and sample messages you can use below.
The most common parameters to experiment with are prompts and models, however you can also experiment with changes to other parameters like temperature.
### Prompts
Comparing different prompts is one of the most effective ways to improve your agent's performance. Small changes in wording, structure, or examples can lead to significant improvements. If you notice an issue with an existing prompt, you can even ask your AI assistant to generate prompt variations to use in the experiment.
Example:
```
Look at the prompt of anotherai/agent/email-rewriter and create an experiment in AnotherAI
that compares the current prompt with a new prompt that better emphasizes adopting
the tone lists in the input
```
Your AI assistant will create the experiment and give you an initial analysis of the results and well as a URL to view the results in the AnotherAI web app.

You can use the provided URL to view the results in the AnotherAI web app to perform manual analysis of the results.

### Models
Different models excel at different tasks. AnotherAI supports over 100 different models, and experiments can help you choose the right model for your agent, depending on its needs.
Example:
```
Create an AnotherAI experiment to help me find a faster model for anotherai/agent/email-rewriter,
but still maintains the same tone and verbosity considerations as my current model.
```
If you have a specific model in mind that you want to try - **for example, a newly released model** - you can ask your AI assistant to help you test that model against your existing agent version. You can always request that your AI assistant use inputs from existing completions, to ensure that you're testing with real, production data.
Example:
```
Can you retry the last 5 completions of anotherai/agent/email-rewriter and compare the outputs with
GPT 5 mini?
```

### Other Parameters
Beyond prompts and models, fine-tuning other parameters can impact your agent's behavior and output quality. Temperature in particular can have a significant impact on the quality of the output.
Temperature is the most important parameter to experiment with after prompts and models. It controls the randomness of the model's output:
* **Low temperature (0.0 - 0.3)**: More deterministic, consistent outputs. Best for:
* Data extraction tasks
* Classification
* Structured output generation
* Tasks requiring high accuracy and repeatability
* **Medium temperature (0.4 - 0.7)**: Balanced creativity and consistency. Best for:
* General purpose assistants
* Question answering
* Summary generation
* **High temperature (0.8 - 1.0)**: More creative, varied outputs. Best for:
* Creative writing
* Brainstorming
* Generating diverse options
Example:
```
Test my email-rewriter agent with temperatures 0.2, 0.5, and 0.8 to find
the right balance between creativity and professionalism
```

### Managing Large Experiments with Claude Code
If you're testing an agent that has a large system prompt and/or very long inputs, you may encounter token limit issues with the `get_experiment` MCP tool that impacts Claude Code's ability to provide accurate insights on your agent.

In this case, you can manually increase Claude Code's output token limit.
**To set up permanently for all terminal sessions:**
For zsh (default on macOS):
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.zshrc && source ~/.zshrc
```
For bash:
```bash
echo 'export MAX_MCP_OUTPUT_TOKENS=150000' >> ~/.bashrc && source ~/.bashrc
```
**For temporary use in current session only:**
```bash
export MAX_MCP_OUTPUT_TOKENS=150000
```
Notes:
* If you forget or don't realize you need to set a higher limit, you can quit your existing session, run the command to increase the limit, and then use `claude --resume` to continue your previous session with the increased limit applied.
You can learn more about tool output limits for Claude Code in their [documentation](https://docs.claude.com/en/docs/claude-code/mcp#mcp-output-limits-and-warnings).
### Tips:
* When creating experiments from your codebase, always reference the specific files of your agent when requesting experiments to avoid any ambiguity about what should be tested
* When not in your codebase (for example, when using ChatGPT), you can reference the agent by the agent\_id found in AnotherAI (ex. anotherai/agent/email-rewriter) to avoid any ambiguity about what should be tested
* Pick one variable to test with at a time (ex. models, prompts) to make sure that you can easily attribute a given variable on the agent's changes in performance.
### Analyzing Experiment Results
Once your experiment has been created, you can:
1. **Review your AI assistant's analysis** of the results (and ask follow up questions if needed)
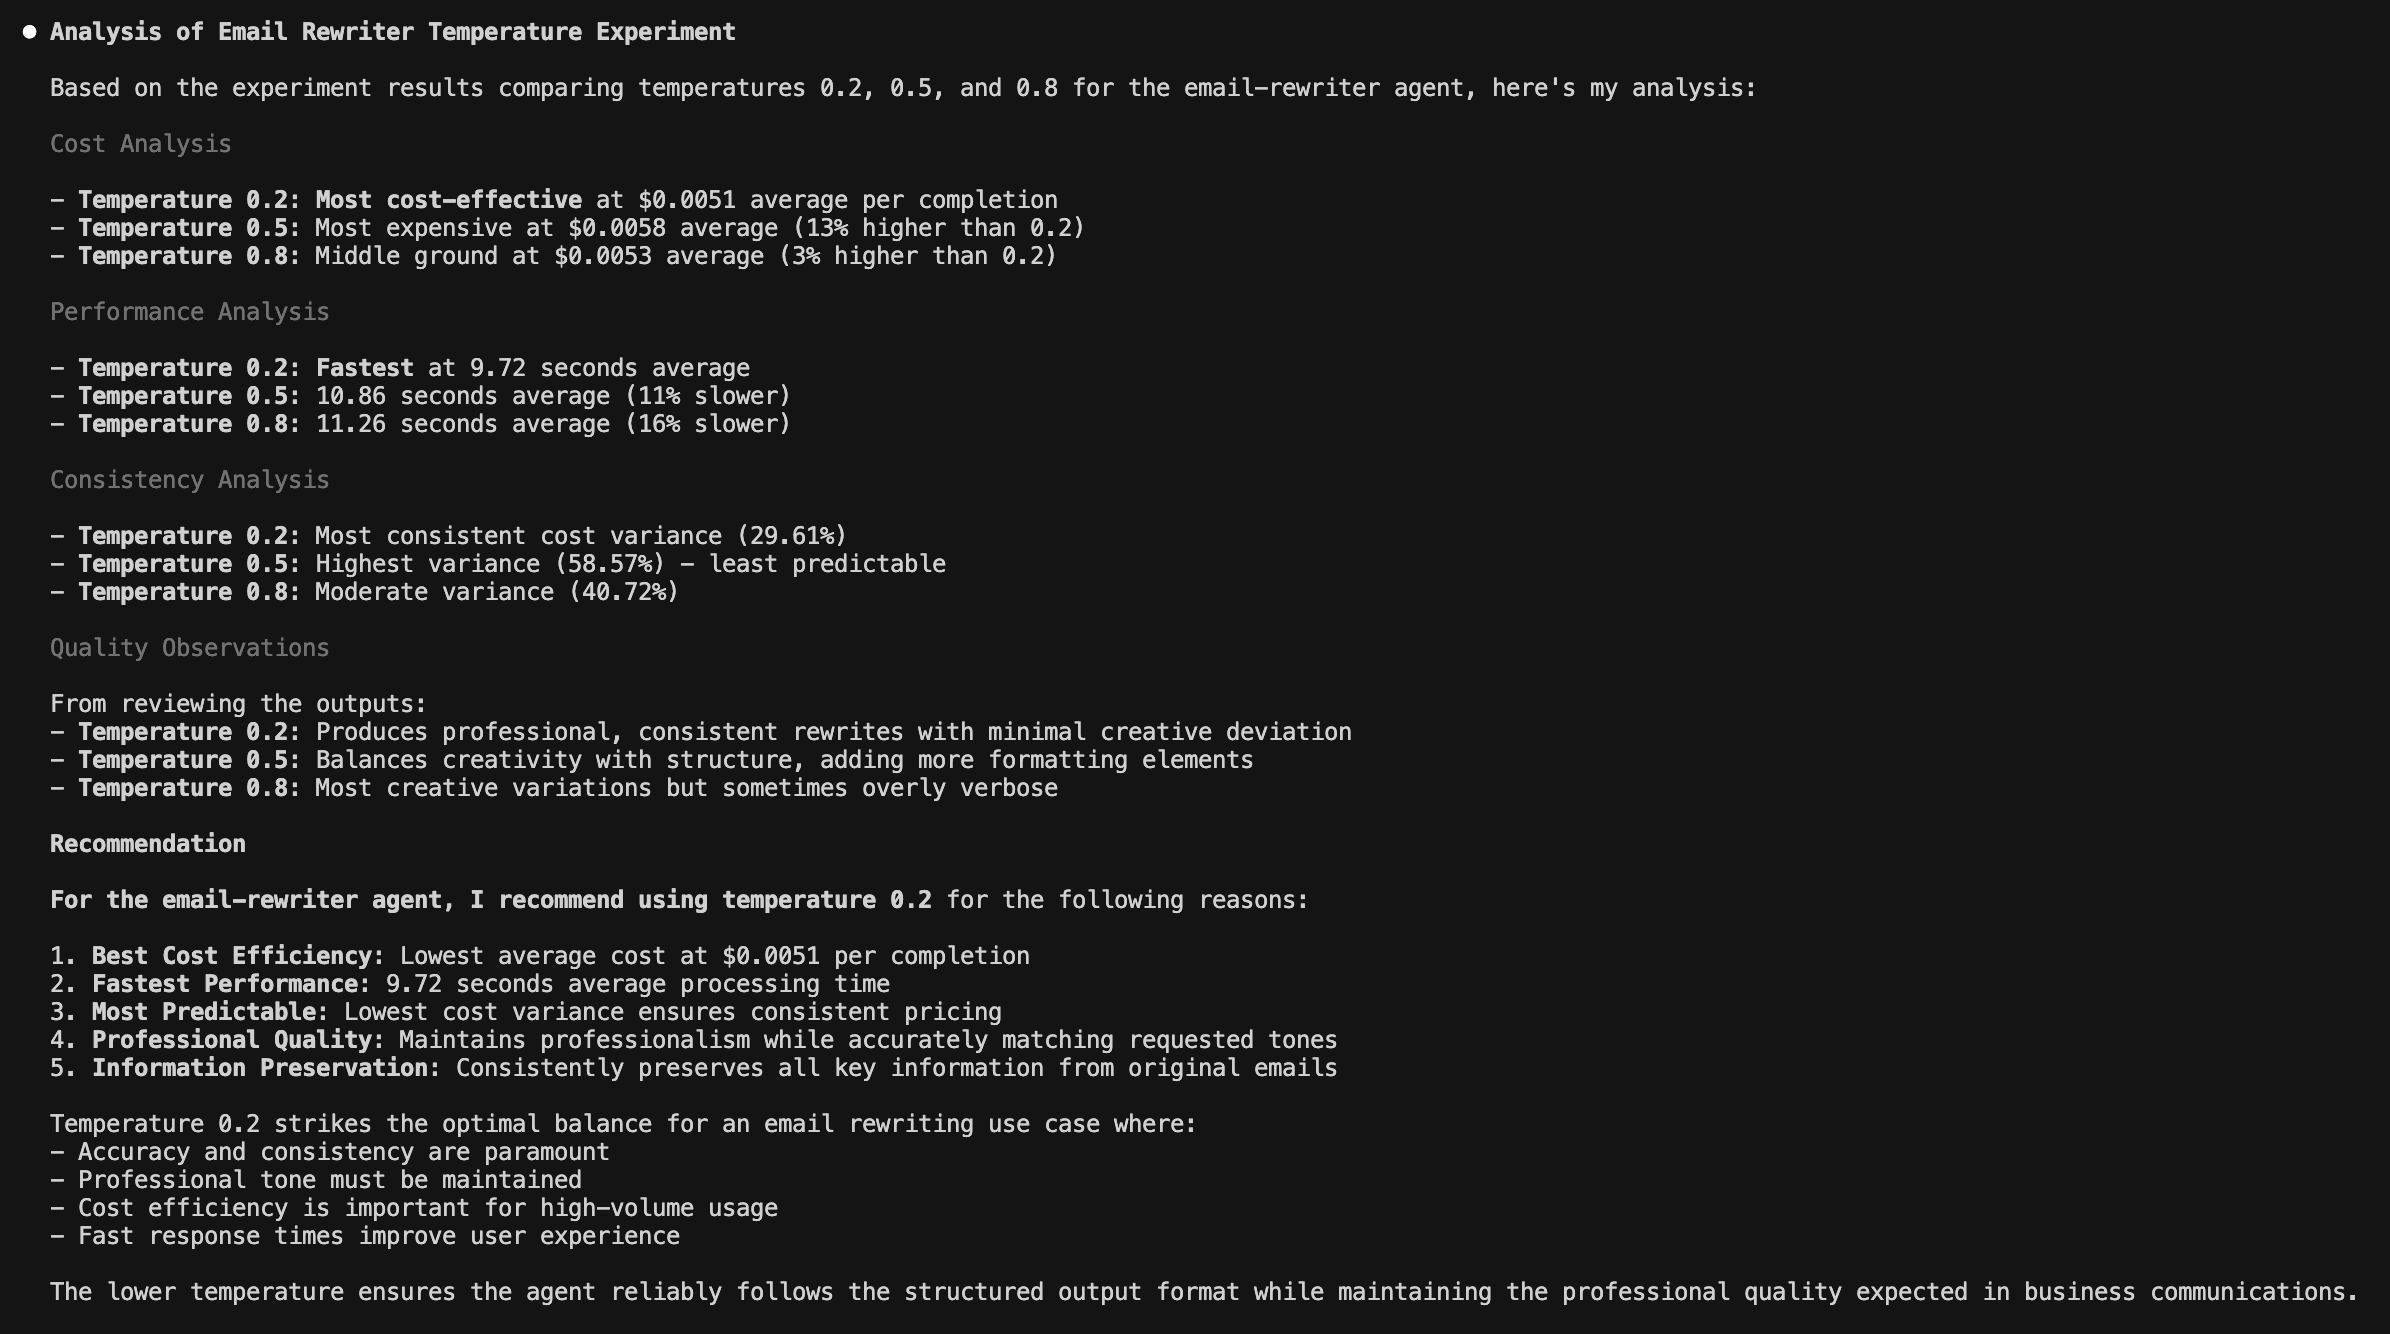
2. **Review side-by-side comparisons** in the AnotherAI experiments view
3. **Use annotations** to mark which outputs are better and why (keep reading to learn more about annotations!)
## Other Ways to Improve your Agents
}>
Add specific feedback to completions and experiments to guide agent improvements
}>
Collect and integrate feedback from your end users to continuously improve your agents
# Metrics and Views
URL: /use-cases/fundamentals/metrics
Query your AI agents' data with natural language, create persistent dashboards, and integrate with your tools via API for advanced use cases
***
title: Metrics and Views
summary: Ask questions in natural language, build custom views, and access your AI agent data to monitor performance, costs, and usage patterns
description: Query your AI agents' data with natural language, create persistent dashboards, and integrate with your tools via API for advanced use cases
---------------------------------------------------------------------------------------------------------------------------------------------------------
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Steps, Step } from 'fumadocs-ui/components/steps';
import { Callout } from 'fumadocs-ui/components/callout';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
One of the core features we wanted to unlock with AnotherAI was to allow users to access all their agent data in a way that would allow them to see the information that was important to *them*.
You can start by asking questions directly in natural language through your AI assistant, build persistent views in the web app for metrics you want to monitor regularly, and for more advanced use cases, access the data directly via REST API to integrate with your existing tools or build your own customizable dashboards.
## Types of Data You Can Query
**Organization-wide data, including:**
* Total spending across all agents
* Most used agents and models
* Agents with the highest failure rates
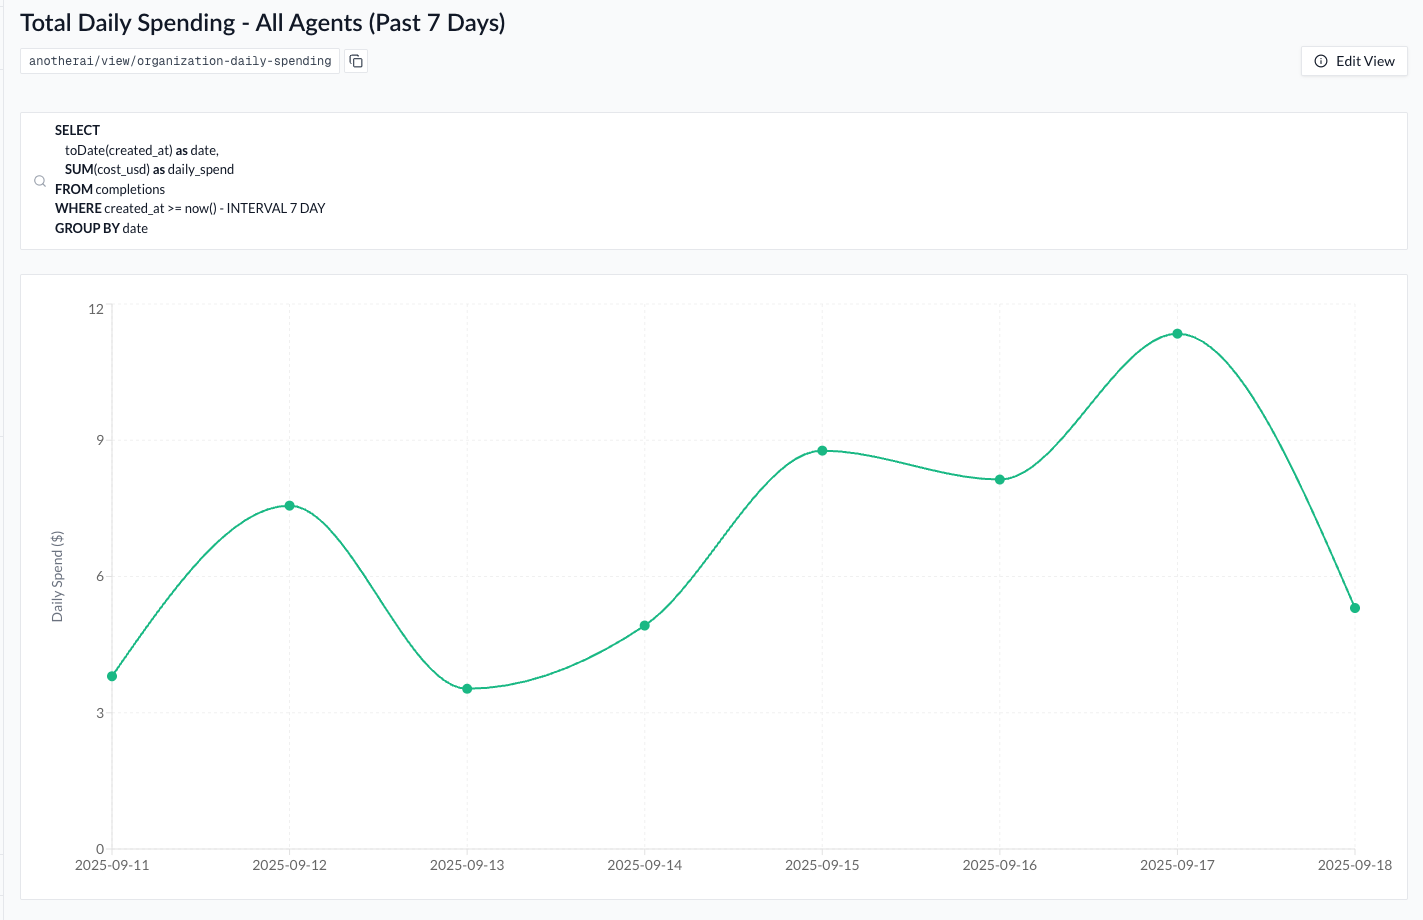
**Agent-level data, including:**
* Individual agent costs and usage
* Latency and performance metrics
* User feedback and annotations left my team members
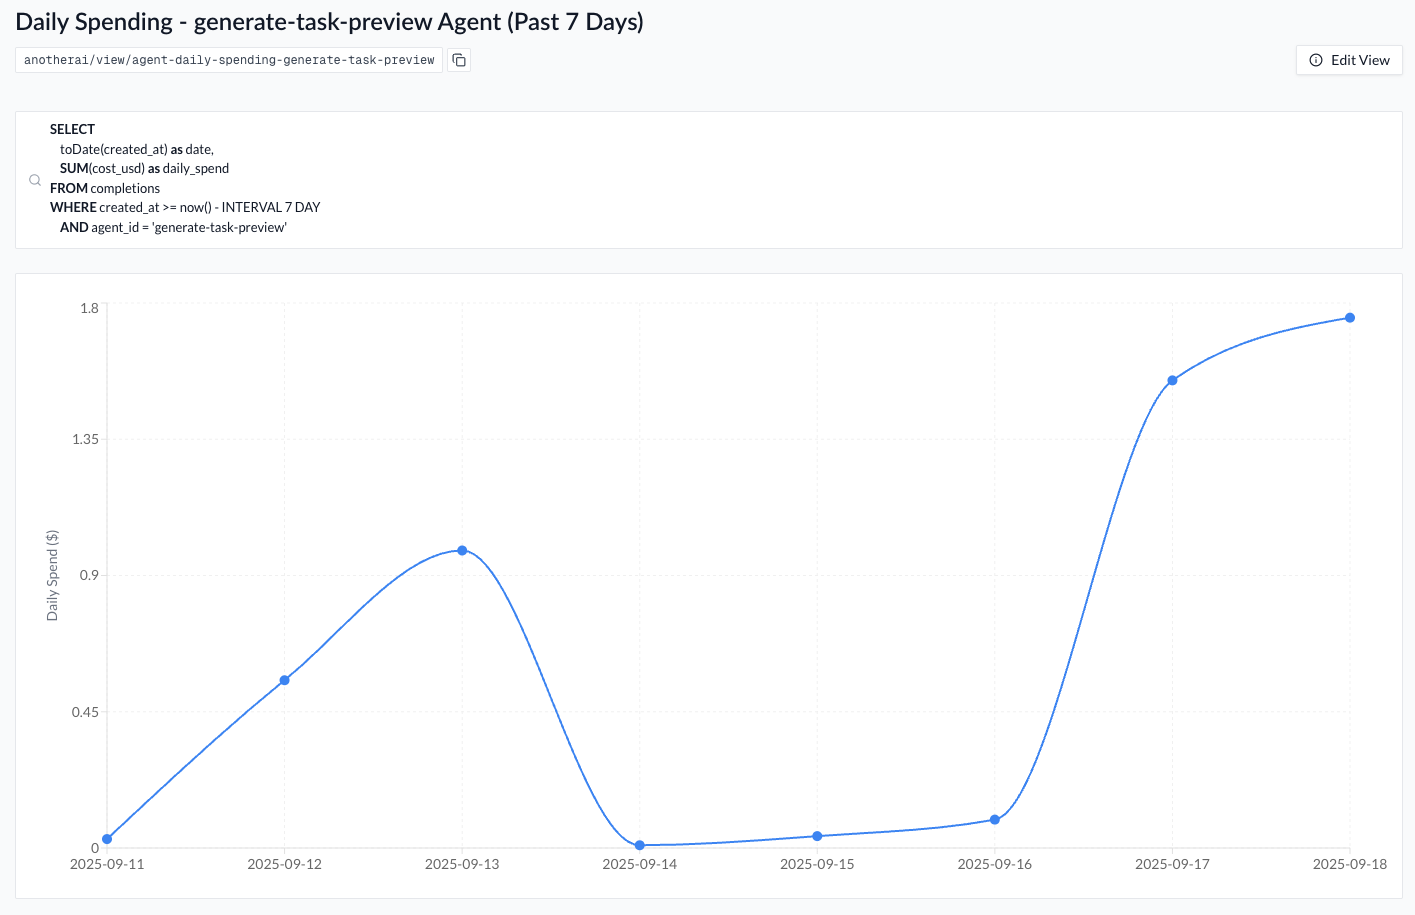
## Type of Views You Can Create
There are two main types of views in AnotherAI:
**1. Table Views**
* Display tabular data with rows and columns
* Best for individual completions, detailed records, or spreadsheet-style data
* Example uses: Recent completions, error logs, cost breakdowns
Example of a table view:
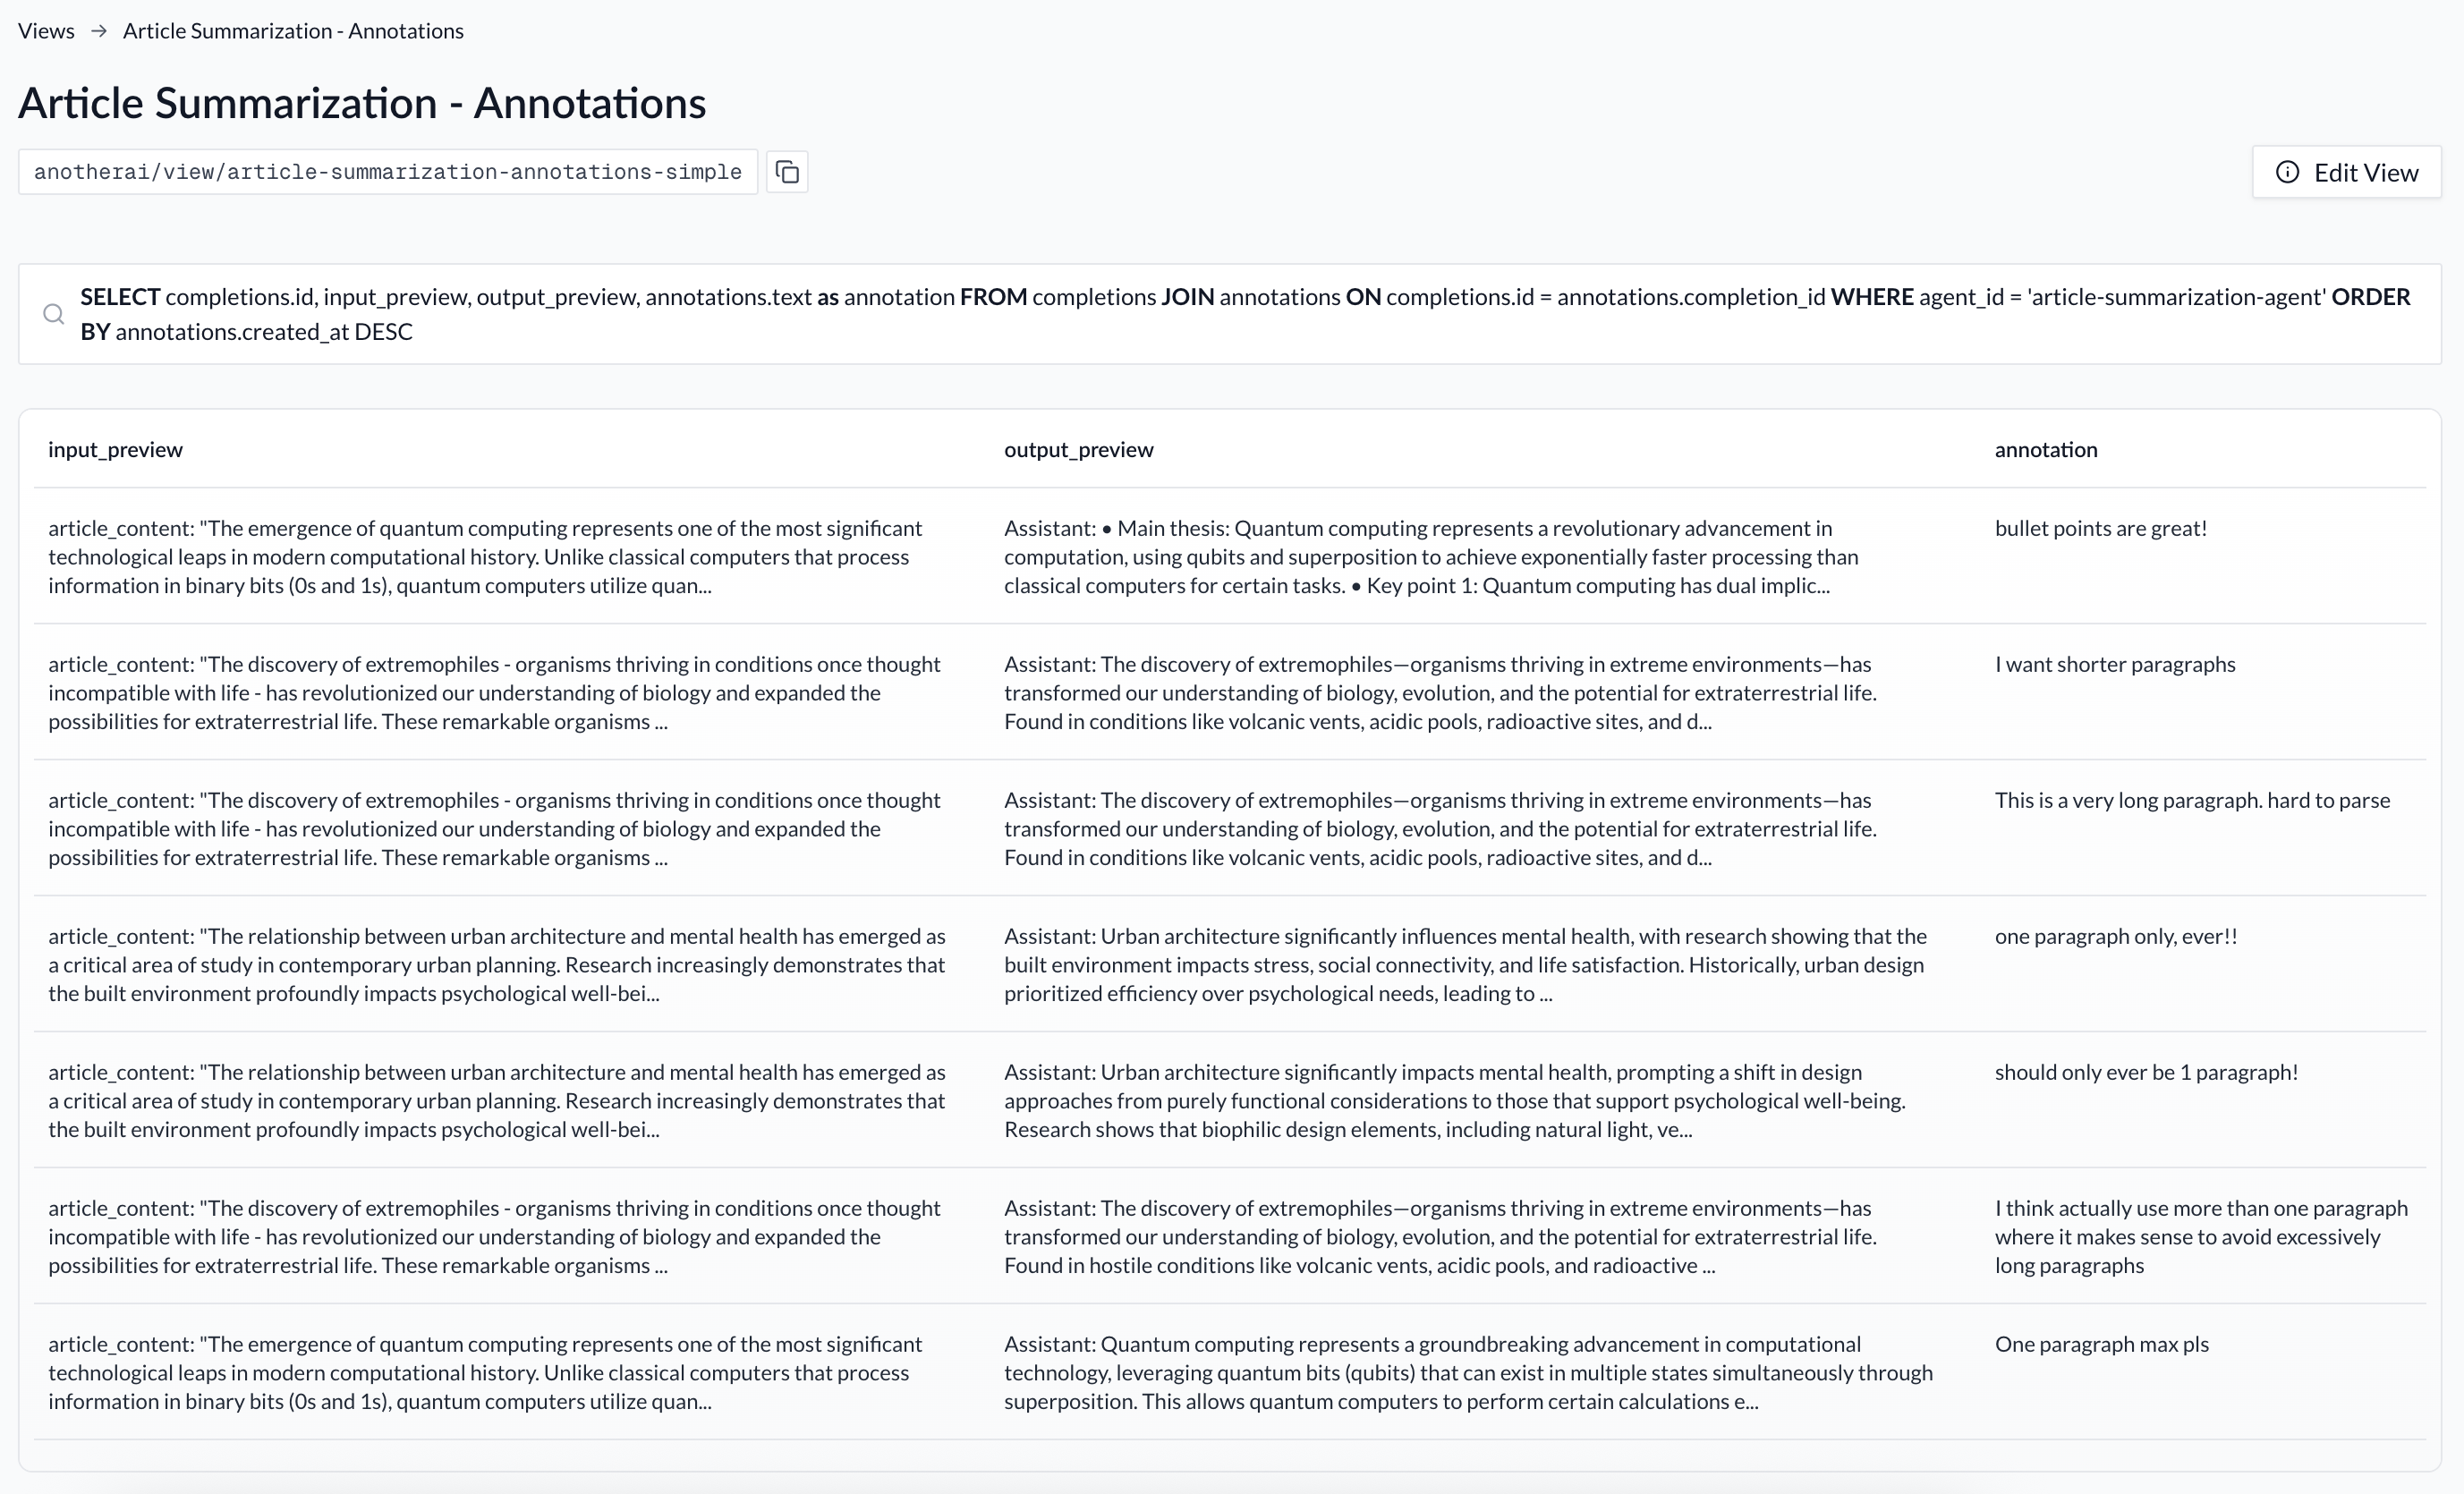
**2. Chart/Graph Views**
* Multiple visualization types for aggregated data:
* **Line graphs**: Time-series data and trends
* **Bar charts**: Compare values across categories (can be stacked)
* **Pie charts**: Show proportional data as segments
* **Scatter plots**: Plot relationships between two numeric variables
* Best for aggregated metrics, trends, and visual analysis
-Example uses: Cost trends over time, agent performance comparisons, model usage distribution
Example of a chart view:

**Key difference**: Tables show individual records while charts show aggregated data with visual representations.
## Query methods
### Using Natural Language via AI Assistant
The AnotherAI MCP allows you to ask questions about your completions data in plain English. Your AI assistant will automatically translate your request into the appropriate SQL query and retrieve the results. This means you don't need to know SQL to analyze your data.
For example, you can ask questions like:
* "What's my total spend this week?"
This Week's Total Spend: $1,123.18
Daily Breakdown:
* Monday 9/8: $164.87
* Tuesday 9/9: $232.25
* Wednesday 9/10: $249.97
* Thursday 9/11: $240.29
* Friday 9/12: $235.78 (today, partial day)
You've run 1.45 million completions this week at an average cost of $0.00078 per run.
* "Which agents are failing most often?"
**Agents with Highest Failure Rates (Last 7 Days):**
1. extract-company-info-from-domain - 58.82% failure rate (10 failures / 17 total runs)
2. extract-meeting-notes - 33.33% failure rate (10 failures / 30 total runs)
3. task-input-migration - 5.26% failure rate (2 failures / 38 total runs)
4. generate-task-preview - 3.55% failure rate (41 failures / 1,155 total runs)
5. task-input-example - 0.75% failure rate (2 failures / 265 total runs)
* "Show me the average latency for each model"
**Average Model Latencies (Last 24 Hours):**
| Model | Avg Latency | P50 | P95 | P99 | Total Requests |
| -------------------------- | ----------- | ------- | -------- | -------- | -------------- |
| gemini-1.5-pro-002 | 1,662ms | 1,500ms | 2,580ms | 4,124ms | 245 |
| gemini-2.0-flash-001 | 1,877ms | 1,150ms | 11,575ms | 15,860ms | 106 |
| gemini-2.0-flash-latest | 2,638ms | 1,700ms | 9,075ms | 13,470ms | 166 |
| gpt-4o-mini-latest | 4,683ms | 4,300ms | 6,300ms | 6,540ms | 6 |
| gemini-2.5-flash | 4,756ms | 3,800ms | 10,160ms | 13,516ms | 27 |
| claude-3-7-sonnet-20250219 | 7,061ms | 6,000ms | 12,100ms | 22,680ms | 161 |
* "How many completions did we process yesterday?"
**Yesterday's Completions (September 14):**
Total: 376 completions
Total Cost: $4.92
Average Cost per Completion: $0.0131
Success Rate: 99.2% (3 failures)
Unique Agents Used: 29
**Completions by Hour:**
* 12 AM: 1
* 1 AM: 5
* 2 AM: 13
* 3 AM: 1
* 4 AM: 87
* 5 AM: 69
* 6 AM: 13
* 7 AM: 1
* 8 AM: 2
* 9 AM: 18
* 10 AM: 12
* 11 AM: 9
* 12 PM: 18
* 1 PM: 3
* 2 PM: 37
* 3 PM: 17
* 4 PM: 11
* 5 PM: 1
* 6 PM: 1
* 7 PM: 18
* 8 PM: 1
* 9 PM: 25
* 10 PM: 13
Your AI assistant will handle the query and present the results in a clear format.
### Creating Views in AnotherAI
You can also create persistent views in the web app to monitor important metrics over time. Simply describe what you want to see visualized.
For example: suppose you have an agent is becoming increasingly popular in your product. You want to keep an eye on the overall spend on that agent to ensure you don't go over budget. You also want to keep an eye on the speed of the models you're using, so that your customers aren't left with long wait times. You may ask your AI assistant to create the following views as such:
Describe the view or goal you want to your preferred AI assistant
```
Create a view in AnotherAI that shows me the daily cost of
anotherai/agent/calendar-event-extraction
```
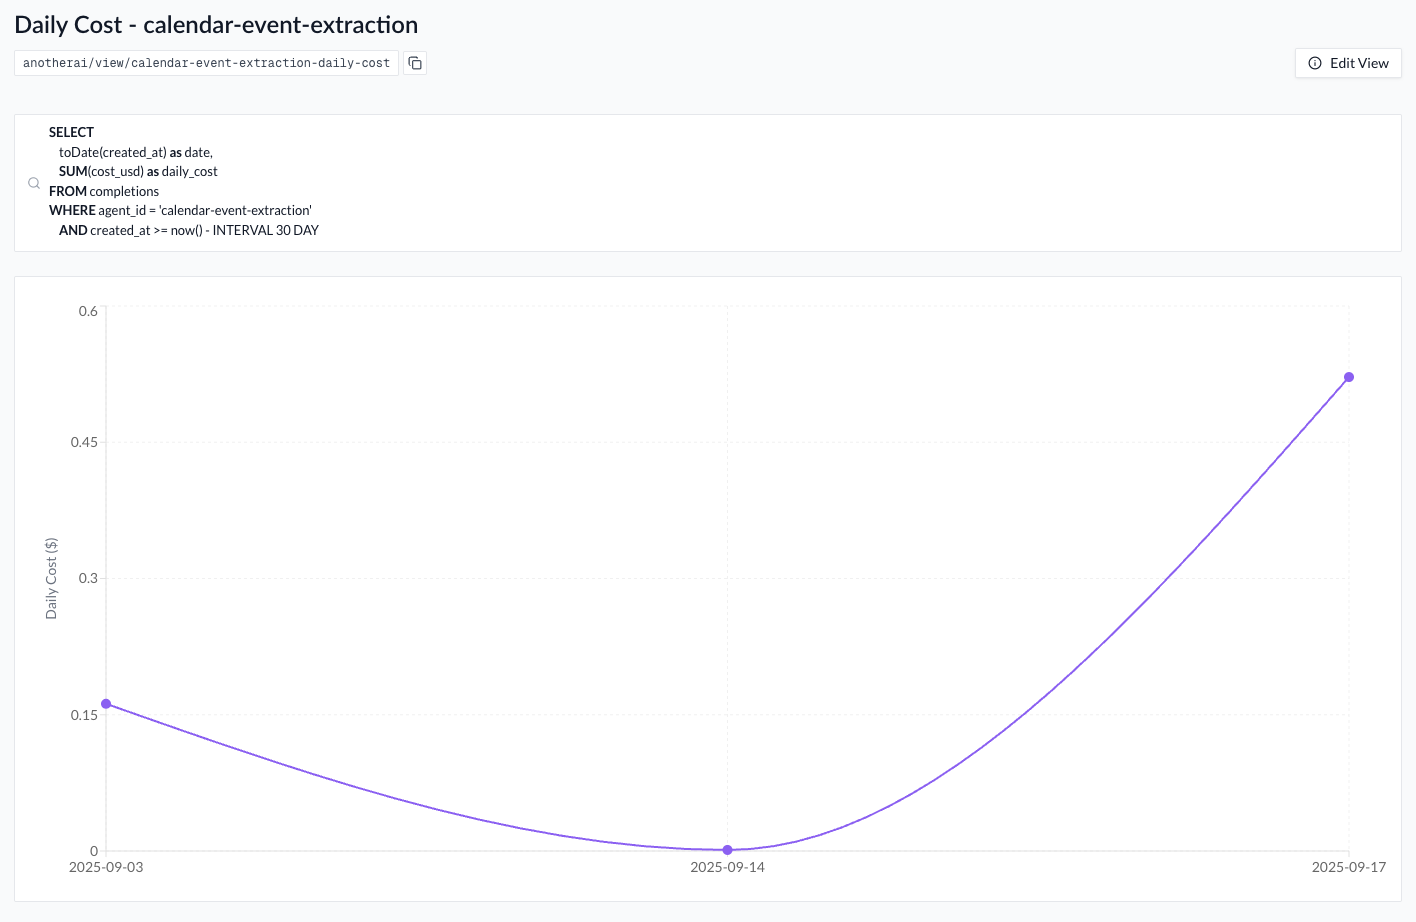
or
```
Create a view in AnotherAI that shows me the total number of completions per day
across all agents for the last week
```
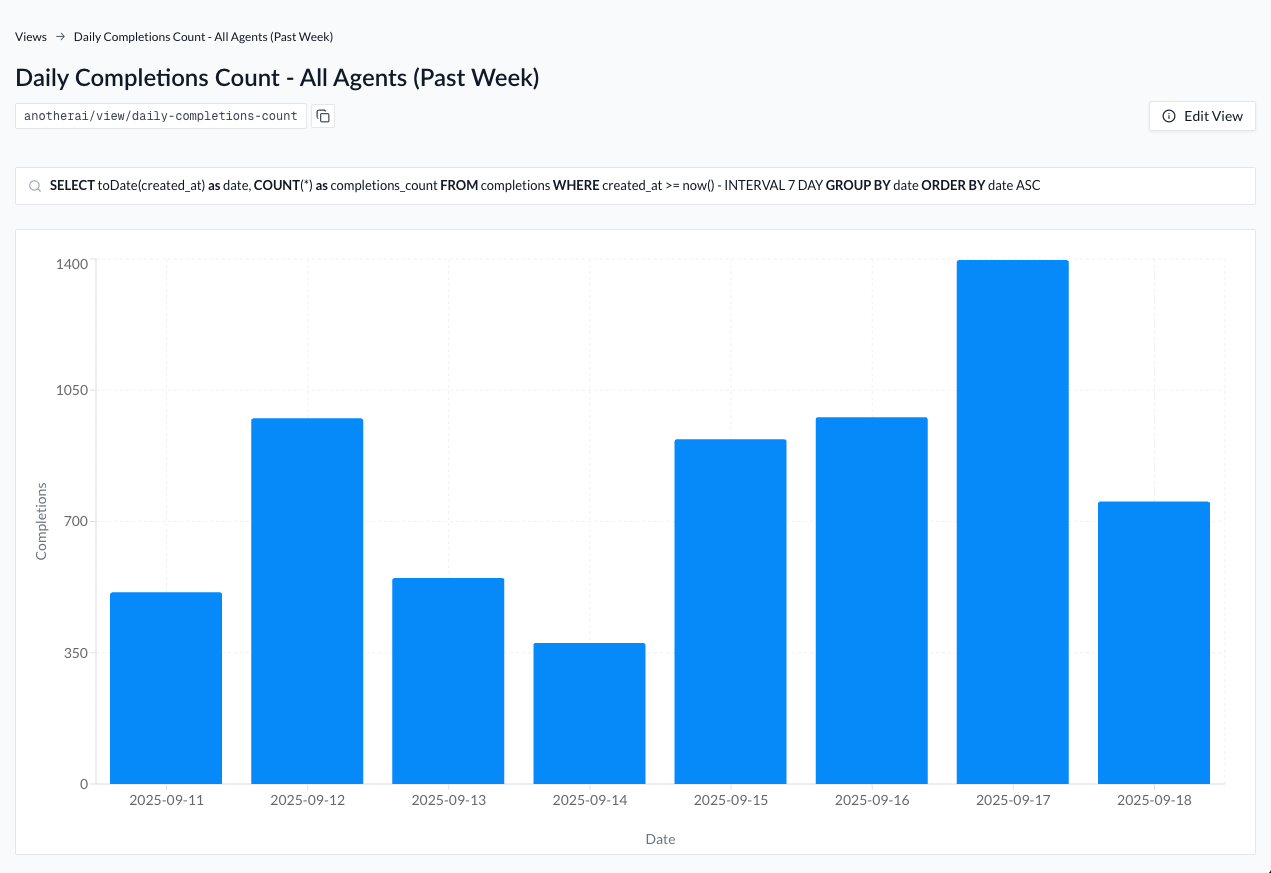
or
```
Create a view in AnotherAI that shows all the completion outputs and annotations
for anotherai/agent/calendar-event-extraction
```
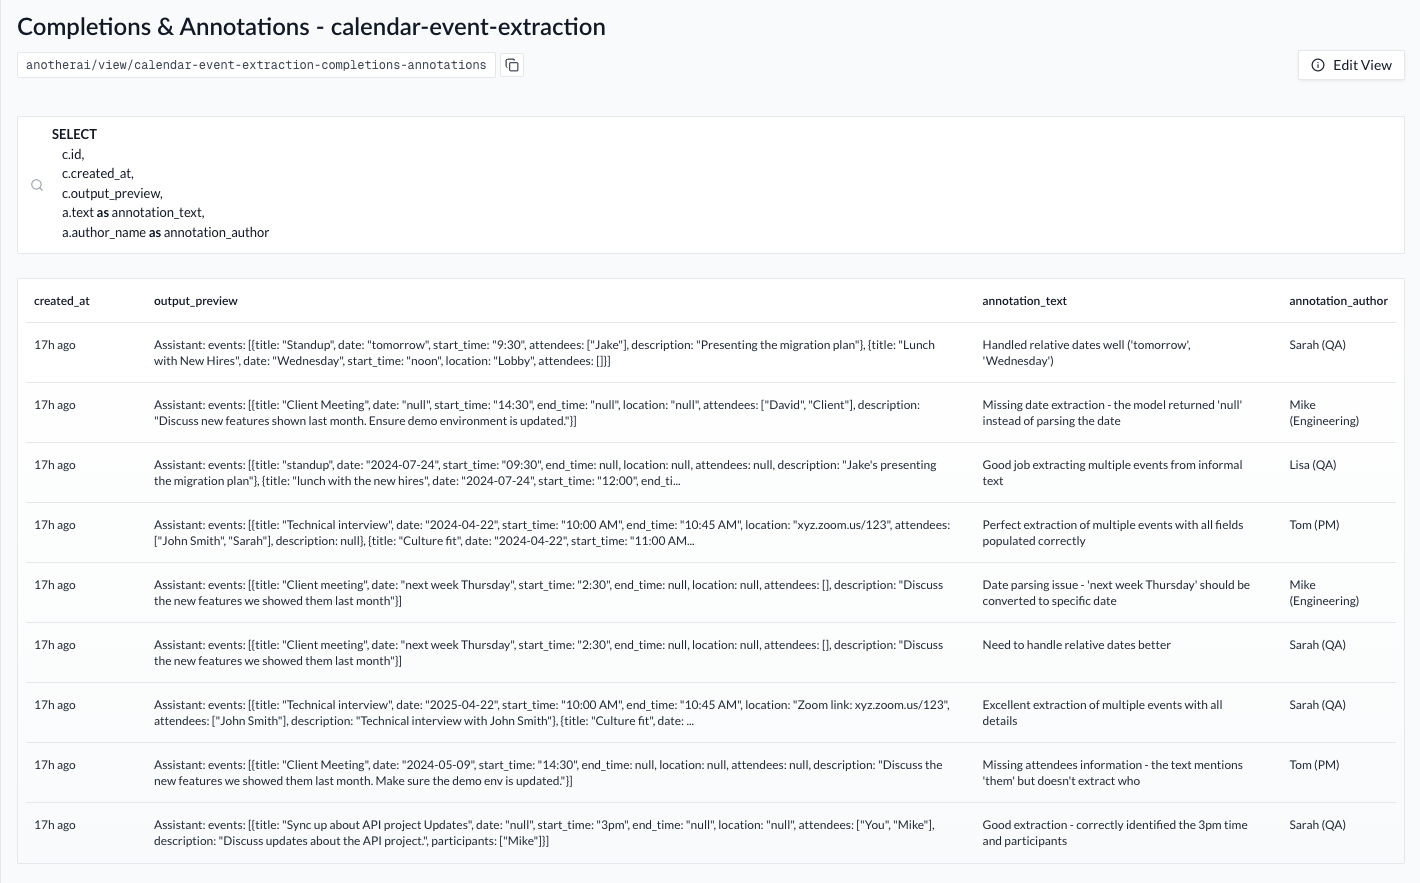
After creating a view, you can always make adjustments to it
```
Update anotherai/views/calendar-event-extraction-completions-annotations to include
the completion inputs as well
```
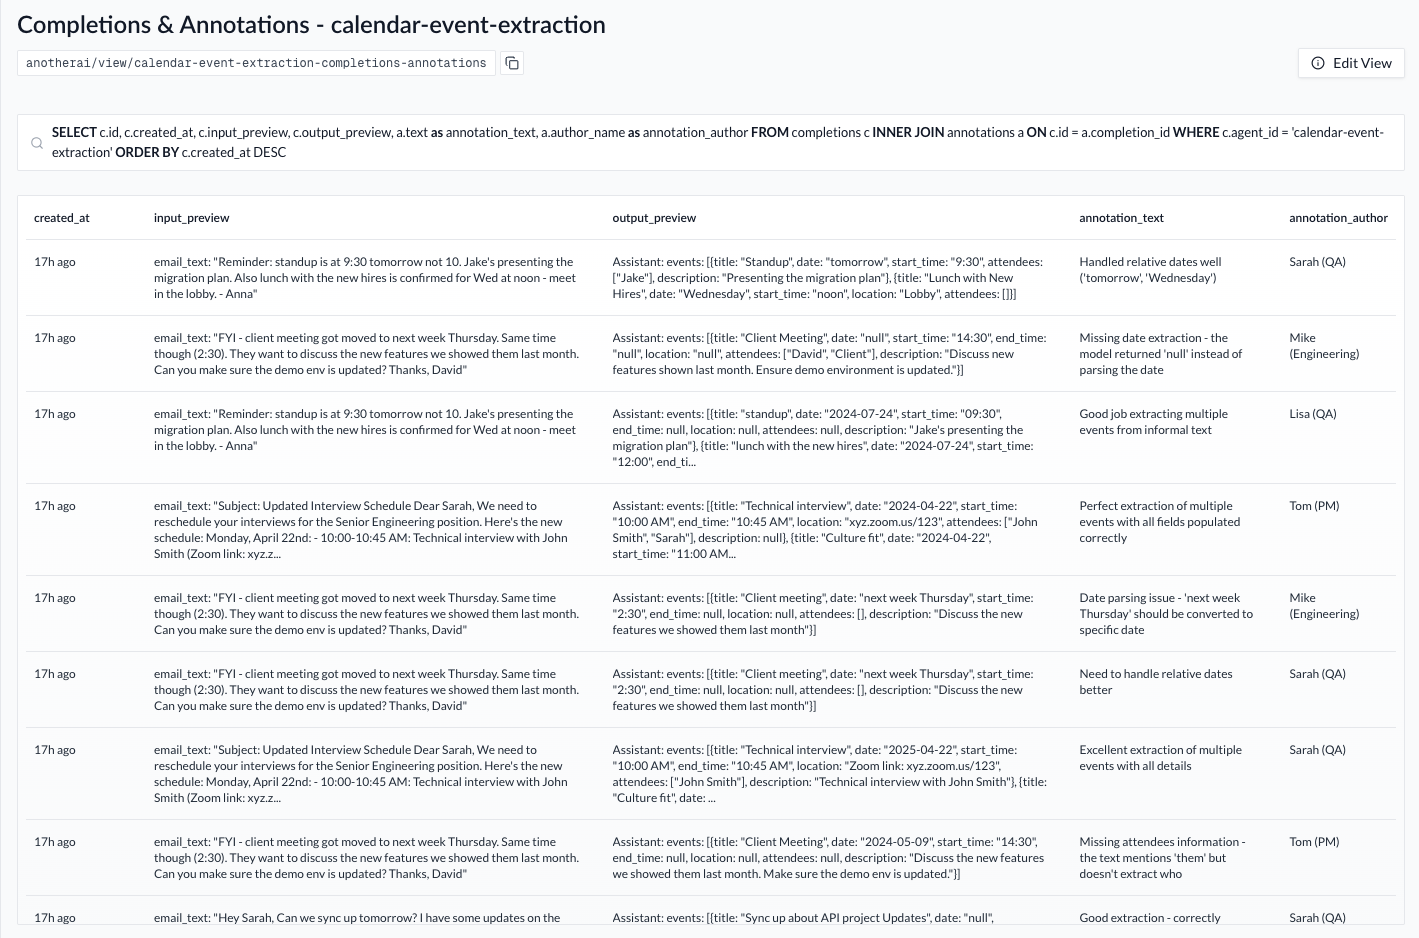
## Can I access metrics via an API?
Yes! If you want to integrate AnotherAI data into your existing business intelligence tools, you can also access the data via the `/v1/completions/query` endpoint. This provides the same functionality as the `query_completions` MCP tool but through HTTP requests, enabling you to further customize how you utilize the data available to you.
**Recommended approach:** For building integrations with the AnotherAI API, we recommend using an AI coding assistant with the AnotherAI MCP connected. The MCP gives your AI assistant direct access to:
* Complete API documentation
* The ability to explore the SQL schema using `query_completions` with DESCRIBE statements
* Real-time testing of queries before implementing them in code
This approach significantly speeds up development and ensures your integration uses the API correctly. See the [Getting Started guide](/getting-started) for MCP setup instructions.
### Endpoint
```http
GET {{API_URL}}/v1/completions/query
```
### Authentication
Include your AnotherAI API key in the Authorization header:
```http
Authorization: Bearer aai-your-api-key
```
### Parameters
| Parameter | Type | Required | Description |
| --------- | ------ | -------- | ----------------------------------------------- |
| `query` | string | Yes | SQL query to execute on the `completions` table |
### Response
Returns an array of objects representing the query results:
```json
[
{
"completion_id": "comp_123",
"agent_id": "email-classifier",
"model": "gpt-4o",
"created_at": "2024-01-15T10:30:00Z",
"total_tokens": 150,
"cost_usd": 0.002
}
]
```
### Example usage
```bash
curl -X GET "{{API_URL}}/v1/completions/query?query=SELECT%20*%20FROM%20completions%20WHERE%20agent_id%20%3D%20%27email-classifier%27%20LIMIT%2010" \
-H "Authorization: Bearer aai-your-api-key" \
-H "Content-Type: application/json"
```
```python
import requests
url = "{{API_URL}}/v1/completions/query"
headers = {
"Authorization": "Bearer aai-your-api-key",
"Content-Type": "application/json"
}
params = {
"query": "SELECT * FROM completions WHERE agent_id = 'email-classifier' LIMIT 10"
}
response = requests.get(url, headers=headers, params=params)
data = response.json()
```
```javascript
const url = new URL("{{API_URL}}/v1/completions/query");
url.searchParams.append("query", "SELECT * FROM completions WHERE agent_id = 'email-classifier' LIMIT 10");
const response = await fetch(url, {
headers: {
"Authorization": "Bearer aai-your-api-key",
"Content-Type": "application/json"
}
});
const data = await response.json();
```
### Common queries
Here are some useful SQL queries for analyzing your completion data:
```sql
-- Get completions for a specific agent in the last 24 hours
SELECT * FROM completions
WHERE agent_id = 'my-agent'
AND created_at >= NOW() - INTERVAL 1 DAY
ORDER BY created_at DESC;
-- Analyze cost and token usage by model
SELECT model, COUNT(*) as completion_count,
SUM(total_tokens) as total_tokens,
SUM(cost_usd) as total_cost
FROM completions
GROUP BY model
ORDER BY total_cost DESC;
-- Find slow completions (over 5 seconds)
SELECT completion_id, agent_id, model, duration_ms
FROM completions
WHERE duration_ms > 5000
ORDER BY duration_ms DESC;
```
# Migrating an Existing Agent
URL: /use-cases/fundamentals/migrating
Learn how to migrate agents currently using the OpenAI SDK, WorkflowAI, or other LLM SDKs to AnotherAI, and add features like input variables and structured outputs
***
title: Migrating an Existing Agent
summary: Guide for migrating agents using OpenAI SDK, WorkflowAI, or other LLM SDKs to AnotherAI
description: Learn how to migrate agents currently using the OpenAI SDK, WorkflowAI, or other LLM SDKs to AnotherAI, and add features like input variables and structured outputs
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
import { Step, Steps } from 'fumadocs-ui/components/steps';
import { Tabs, Tab } from 'fumadocs-ui/components/tabs';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
import { Callout } from 'fumadocs-ui/components/callout';
import { BarChart3, UploadCloud, Eye, PlugZap, ListChecks, Globe, ShieldCheck } from 'lucide-react';
## Migrating From the OpenAI SDK to AnotherAI
The easiest way to migrate your agent is to ask your preferred AI assistant to handle it for you.
Looking for help with migrating your agent? We're happy to help. Reach us at [team@workflowai.support](mailto:team@workflowai.support) or on [Slack](https://join.slack.com/t/anotherai-dev/shared_invite/zt-3av2prezr-Lz10~8o~rSRQE72m_PyIJA).
If you want to keep your agent as is in code with minimal changes, you can ask your AI assistant to do the following:
```
Migrate my agent at @[your-agent-file-path] to use AnotherAI.
I want to keep my agent as is in code, but just add access to
AnotherAI's features
```
If your agent isn't currently using [input variables](/integrations/openai#1-input-variables) or [structured output](/integrations/openai#2-structured-outputs), it's highly recommended to add them during migration.
* **Enable experiments**: Without input variables, AnotherAI can't distinguish between the static data of your prompt template and the dynamic data that changes between completions, making it impossible to run experiments with different inputs
* **Better observability**: Separates your prompt logic from your data, making it easier to debug issues and understand what data caused specific outputs
* **Reliability**: Guarantees valid JSON output every time, eliminating parsing errors and retry loops
* **Consistency**: Ensures all responses follow the exact same schema, making downstream processing predictable
```
Migrate my agent at @[your-agent-file-path] to use AnotherAI.
I want to keep the same prompt, but update the code to use input variables and structured output.
```
If you prefer to migrate manually or want to understand what changes are needed, follow the steps below.
1. Update your configuration
There are three main steps to migrating your agent to AnotherAI:
1. Update your OpenAI client configuration to point to AnotherAI's base URL. (Required)
2. Add an `agent_id` in the agent's metadata. This ensures that each agent can be distinguished in AnotherAI's webview. (Recommended)
3. (For cloud-hosted AnotherAI only) Replace your provider API keys with an AnotherAI API key to gain easy access to 100+ different models. (Recommended)
```python
from openai import OpenAI
client = OpenAI(
base_url="{{API_URL}}/v1", # Or http://localhost:8000/v1 for self-hosted
api_key="aai-***",
)
# Your existing code works as-is
response = client.chat.completions.create(
model="gpt-4o",
messages=[
{"role": "user", "content": "Hello, world!"}
],
metadata={
"agent_id": "your-agent-name", # Recommended for observability
}
)
```
```javascript
import OpenAI from 'openai';
const client = new OpenAI({
baseURL: '{{API_URL}}/v1', // Or http://localhost:8000/v1 for self-hosted
apiKey: 'aai-***',
});
// Your existing code works as-is
const response = await client.chat.completions.create({
model: 'gpt-4o',
messages: [
{ role: 'user', content: 'Hello, world!' }
],
metadata: {
agent_id: 'your-agent-name', // Recommended for observability
}
});
```
2. Verify your agent is working
Test your agent by running it once. If everything is set up correctly, you should see the completion appear at [https://anotherai.dev/completions](https://anotherai.dev/completions).
3. You're done!
Your agent is now integrated with AnotherAI, giving you access to:
* **100+ AI Models**: Access models from OpenAI, Anthropic, Google, and more
* **Observability**: Track completions, costs, and performance metrics
* **Experiments**: Test different models and prompts
* **Deployments**: Update prompts and models without changing code
## Migrating from WorkflowAI to AnotherAI
If you're a previous WorkflowAI user, any completions created after \[insert date] on WorkflowAI will be automatically available in the AnotherAI web app. The completions can be used by your AI coding agent to recreate an identical agent in your codebase to use in AnotherAI.
Go to [https://anotherai.dev/agents](https://anotherai.dev/agents)
Select the agent that you want to migrate
Scroll down the agent's page to view the recent completions and select a completion that uses the version of your agent that you want to migrate
Copy the completion ID
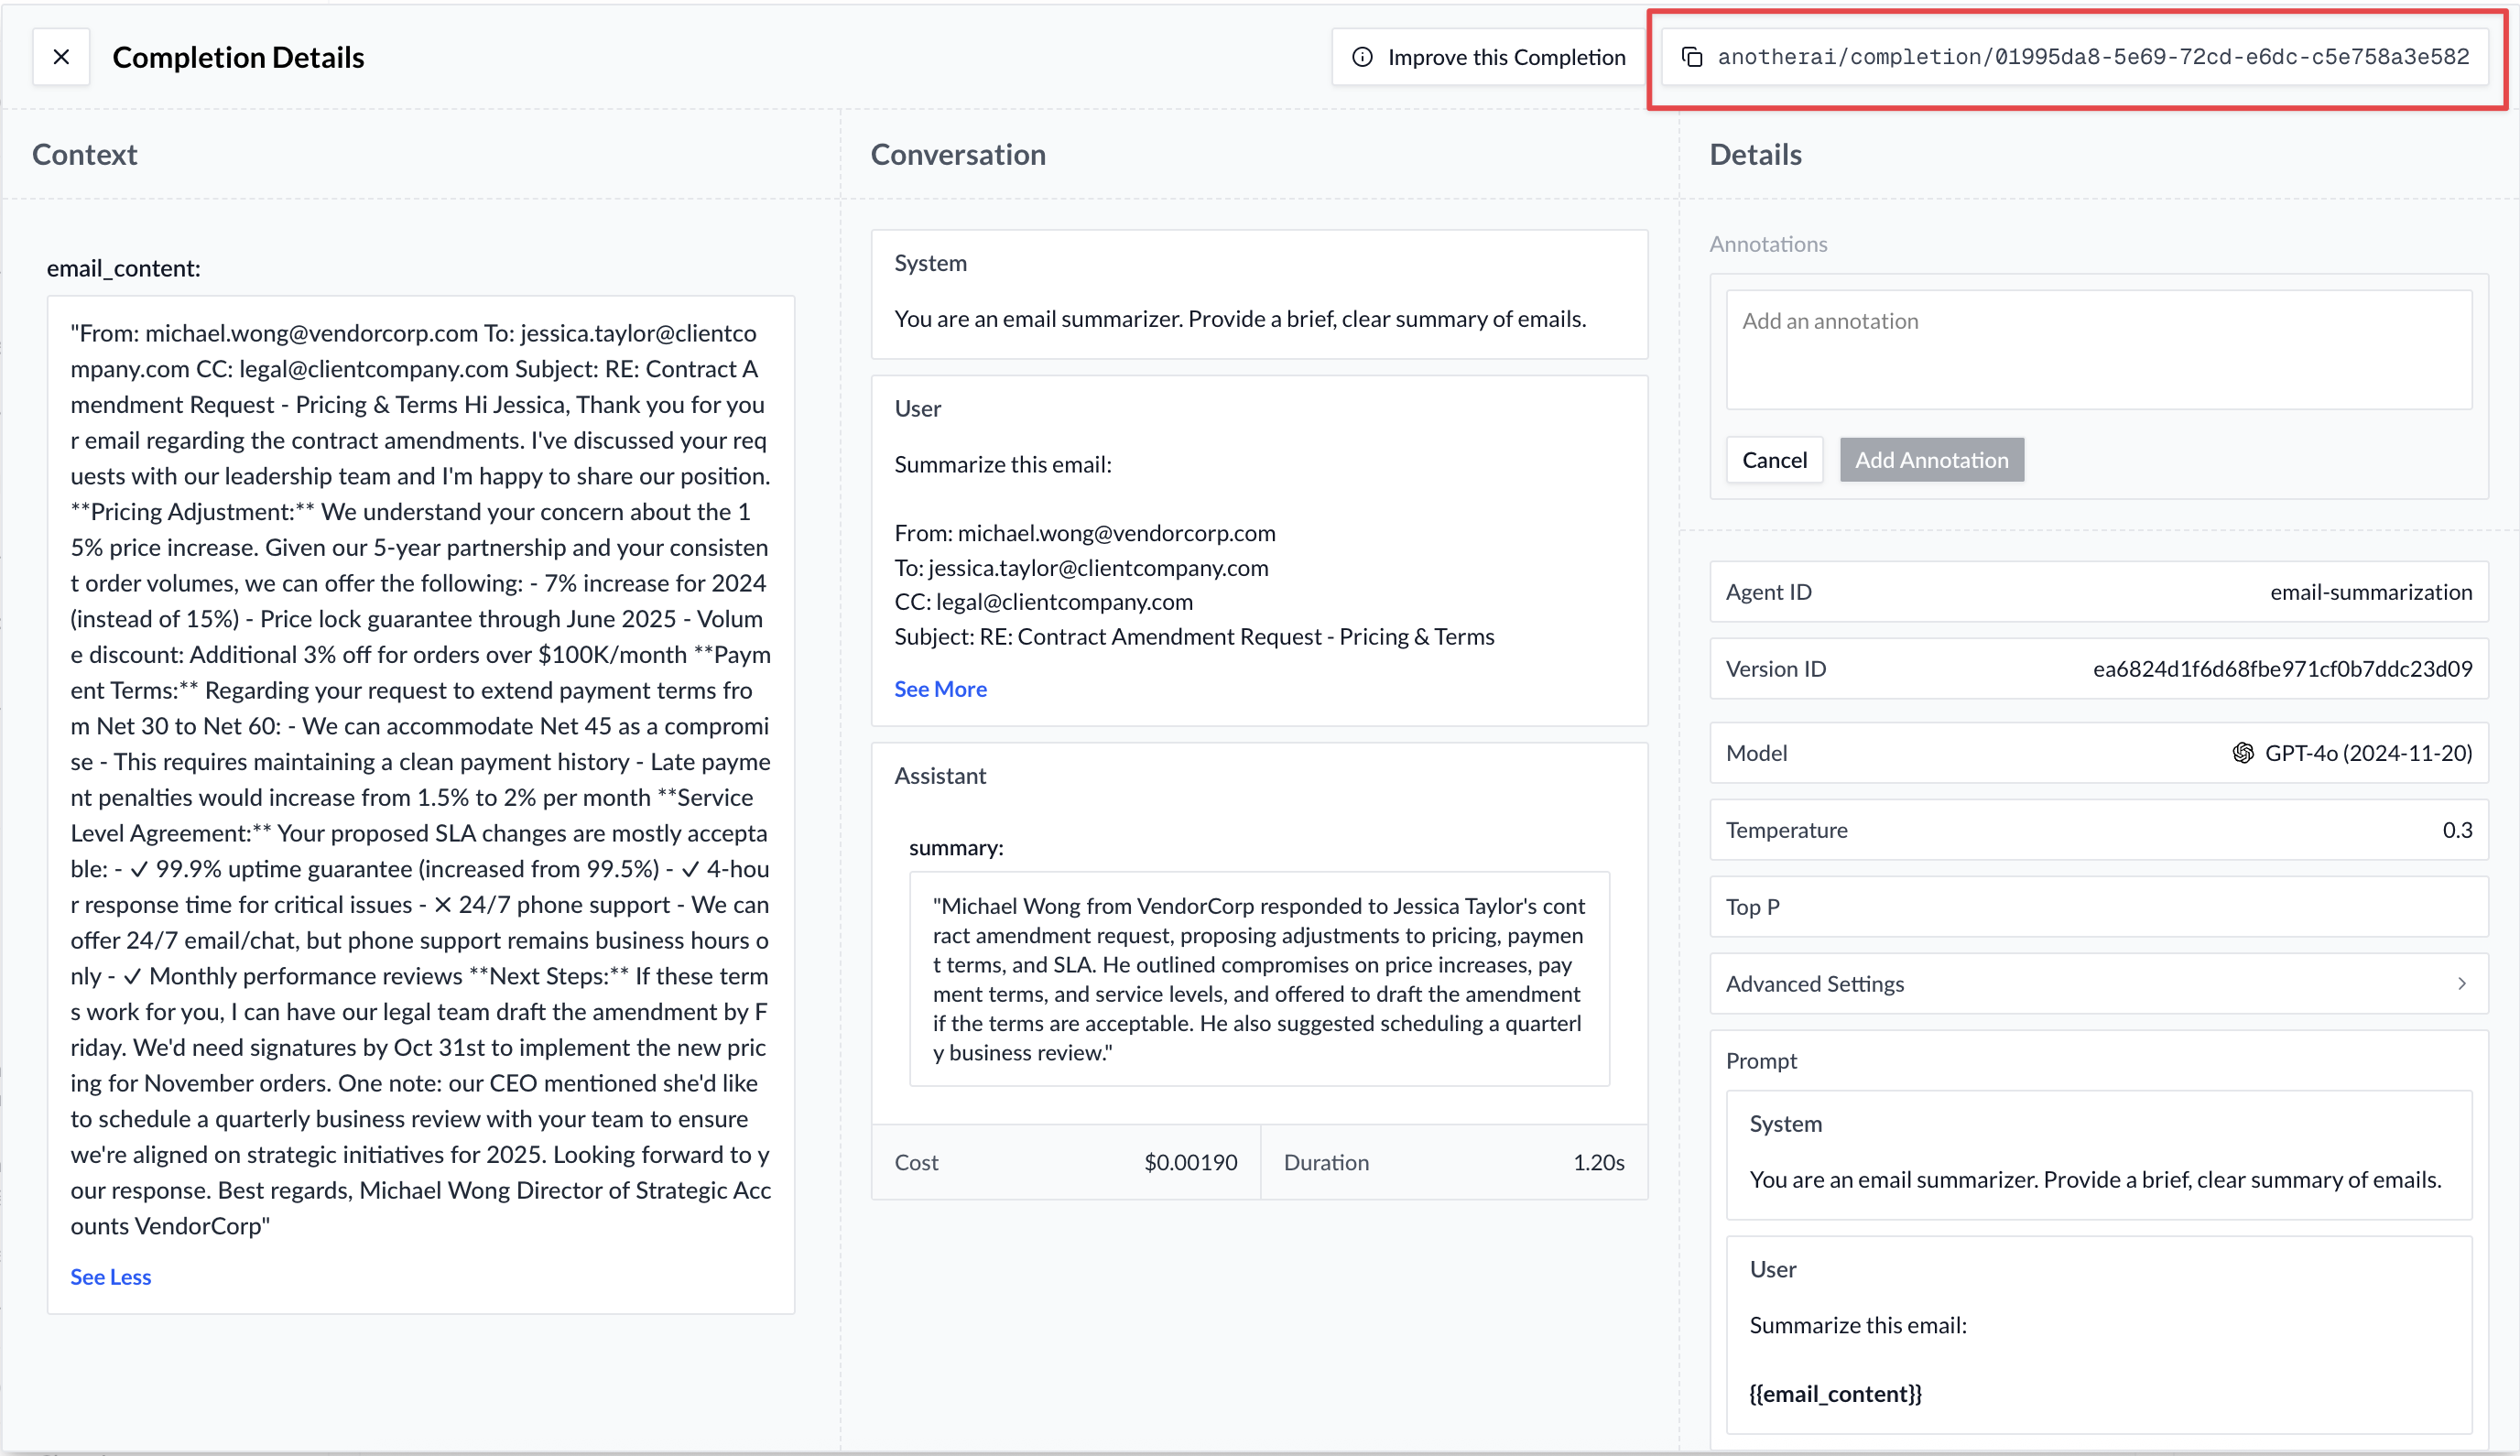
Send the following prompt to your preferred AI assistant:
```
Migrate this version of my agent to AnotherAI:
[paste the completion ID here]
```
Your AI assistant will take care of the steps to migrate the agent to AnotherAI including:
* Fetching prompts from WorkflowAI deployments
* Converting WorkflowAI SDK calls to OpenAI completion calls
* Setting up API keys and client configuration
* Handling structured outputs and metadata
The migration process ensures your existing WorkflowAI agents work seamlessly with AnotherAI while gaining access to additional features.
## Migrating Away from AnotherAI
We have a zero lock-in promise, so you can try AnotherAI risk-free. If it doesn't provide value, switching back takes minutes, not months.
To switch away from AnotherAI:
* Remove `base_url="{{API_URL}}/v1"`
* If you're not using deployments: your code stays identical
* If you are using deployments: simply ask your AI assistant to fetch your deployment configuration to recreate the equivalent configuration in your code.
If you have any questions or encounter any issues with switching away from AnotherAI, please reach out to [us](mailto:team@workflowai.support).
## Next Steps
* [Evaluating Agents](/use-cases/fundamentals/evaluating) - Test and compare agent performance
* [Improving Agents](/use-cases/fundamentals/annotations) - Optimize prompts and model selection
* [Deployments](/use-cases/fundamentals/deployments) - Update prompts and models without changing code